Databricks-Certified-Professional-Data-Engineer Visual Cert Exam - New Databricks-Certified-Professional-Data-Engineer Test Simulator

2026 Latest Dumpleader Databricks-Certified-Professional-Data-Engineer PDF Dumps and Databricks-Certified-Professional-Data-Engineer Exam Engine Free Share: https://drive.google.com/open?id=11pfEZS88vSPOs1ut_qE-VB05B5CHH-1j
Have similar features to the desktop-based exam simulator contains actual Databricks Databricks-Certified-Professional-Data-Engineer Practice Test that will help you grasp every topic Compatible with every operating system such as Mac, Linus, iOS, Windows, and Android Works properly on Google chrome, Internet explorer, Microsoft Edge, Opera, etc. Does not require any special plugins to operate creates an exam atmosphere making candidates more confident. Keep track of your progress with self-analysis Points out mistakes at the end of every attempt.
| Section | Weight | Objectives |
|---|
| Pipeline Development and Orchestration | 10-15% | - Databricks workflows
- 1. Monitoring and alerting
- 2. Jobs and job scheduling
- 3. Task dependencies and orchestration
|
| Data Ingestion | 15-20% | - Batch ingestion methods
- 1. Spark APIs for ingestion
- 2. DBR autoloader
- 3. Integration with external systems
- Streaming ingestion
- 1. Kafka integration
- 2. Structured streaming fundamentals
|
| Delta Lake | 20-25% | - Delta Lake fundamentals
- 1. Time travel and data versioning
- 2. Optimize and Z-order
- 3. ACID transactions
- Delta Lake operations
- 1. Schema evolution and enforcement
- 2. Merge, update, delete operations
- 3. Delta Live Tables
|
| Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
- 1. Differences between data lake, data warehouse, and lakehouse
- 2. Bronze, silver, gold data layers
- 3. Data governance fundamentals
|
| Data Processing with Spark | 25-30% | - Spark DataFrames and Spark SQL
- 1. Spark SQL queries and functions
- 2. DataFrame operations and transformations
- 3. Window functions
- Python and SQL for data engineering
- 1. Performance optimization techniques
- 2. Spark APIs in Python
- 3. Built-in and user-defined functions
|
>> Databricks-Certified-Professional-Data-Engineer Visual Cert Exam <<
New Databricks-Certified-Professional-Data-Engineer Test Simulator, Databricks-Certified-Professional-Data-Engineer Key Concepts
Knowledge makes prominent contributions to human civilization and progress. In the 21st century, the rate of unemployment is increasing greatly. Many jobs are replaced by intelligent machines. You must learn practical knowledge such as our Databricks-Certified-Professional-Data-Engineer actual test guide, which cannot be substituted by artificial intelligence. Now, our Databricks-Certified-Professional-Data-Engineer learning prep can meet your demands. You will absorb the most useful knowledge with the assistance of our study materials. The Databricks-Certified-Professional-Data-Engineer certificate is valuable in the job market. But you need professional guidance to pass the exam. For instance, our Databricks-Certified-Professional-Data-Engineer exam questions fully accords with your requirements.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q215-Q220):
NEW QUESTION # 215
A data engineer has a Job with multiple tasks that runs nightly. One of the tasks unexpectedly fails during 10
percent of the runs.
Which of the following actions can the data engineer perform to ensure the Job completes each night while
minimizing compute costs?
- A. They can institute a retry policy for the entire Job
- B. They can set up the Job to run multiple times ensuring that at least one will complete
- C. They can institute a retry policy for the task that periodically fails
- D. They can observe the task as it runs to try and determine why it is failing
- E. They can utilize a Jobs cluster for each of the tasks in the Job
Answer: C
NEW QUESTION # 216
An upstream source writes Parquet data as hourly batches to directories named with the current date. A nightly batch job runs the following code to ingest all data from the previous day as indicated by the date variable:
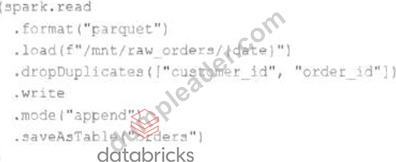
Assume that the fields customer_id and order_id serve as a composite key to uniquely identify each order.
If the upstream system is known to occasionally produce duplicate entries for a single order hours apart, which statement is correct?
- A. Each write to the orders table will only contain unique records; if existing records with the same key are present in the target table, these records will be overwritten.
- B. Each write to the orders table will run deduplication over the union of new and existing records, ensuring no duplicate records are present.
- C. Each write to the orders table will only contain unique records, but newly written records may have duplicates already present in the target table.
- D. Each write to the orders table will only contain unique records, and only those records without duplicates in the target table will be written.
- E. Each write to the orders table will only contain unique records; if existing records with the same key are present in the target table, the operation will tail.
Answer: C
Explanation:
This is the correct answer because the code uses the dropDuplicates method to remove any duplicate records within each batch of data before writing to the orders table. However, this method does not check for duplicates across different batches or in the target table, so it is possible that newly written records may have duplicates already present in the target table. To avoid this, a better approach would be to use Delta Lake and perform an upsert operation using mergeInto. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "DROP DUPLICATES" section.
NEW QUESTION # 217
Which statement regarding stream-static joins and static Delta tables is correct?
- A. Stream-static joins cannot use static Delta tables because of consistency issues.
- B. The checkpoint directory will be used to track updates to the static Delta table.
- C. Each microbatch of a stream-static join will use the most recent version of the static Delta table as of each microbatch.
- D. The checkpoint directory will be used to track state information for the unique keys present in the join.
- E. Each microbatch of a stream-static join will use the most recent version of the static Delta table as of the job's initialization.
Answer: C
Explanation:
Explanation
This is the correct answer because stream-static joins are supported by Structured Streaming when one of the tables is a static Delta table. A static Delta table is a Delta table that is not updated by any concurrent writes, such as appends or merges, during the execution of a streaming query. In this case, each microbatch of a stream-static join will use the most recent version of the static Delta table as of each microbatch, which means it will reflect any changes made to the static Delta table before the start of each microbatch. Verified References:[Databricks Certified Data Engineer Professional], under "Structured Streaming" section; Databricks Documentation, under "Stream and static joins" section.
NEW QUESTION # 218
A data ingestion task requires a one-TB JSON dataset to be written out to Parquet with a target part-file size of 512 MB. Because Parquet is being used instead of Delta Lake, built-in file-sizing features such as Auto- Optimize and Auto-Compaction cannot be used.
Which strategy will yield the best performance without shuffling data?
- A. Ingest the data, execute the narrow transformations, repartition to 2,048 partitions (1TB* 1024*1024
/512), and then write to parquet. - B. Set spark.sql.shuffle.partitions to 2,048 partitions (1TB*1024*1024/512), ingest the data, execute the narrow transformations, optimize the data by sorting it (which automatically repartitions the data), and then write to parquet.
- C. Set spark.sql.shuffle.partitions to 512, ingest the data, execute the narrow transformations, and then write to parquet.
- D. Set spark.sql.adaptive.advisoryPartitionSizeInBytes to 512 MB bytes, ingest the data, execute the narrow transformations, coalesce to 2,048 partitions (1TB*1024*1024/512), and then write to parquet.
- E. Set spark.sql.files.maxPartitionBytes to 512 MB, ingest the data, execute the narrow transformations, and then write to parquet.
Answer: E
Explanation:
For this scenario where a one-TB JSON dataset needs to be converted into Parquet format without employing Delta Lake ' s auto-sizing features, the goal is to avoid unnecessary data shuffles and yet ensure optimal file sizes for the output Parquet files. Here's a breakdown of why option A is most suitable:
* Setting maxPartitionBytes: The spark.sql.files.maxPartitionBytes configuration controls the size of blocks that Spark reads from the data source (in this case, the JSON files) but also influences the output size of files when data is written without repartition or coalesce operations. Setting this parameter to
512 MB directly addresses the requirement to manage the output file size effectively.
* Data Ingestion and Processing:
* Ingesting Data: Load the JSON dataset into a DataFrame.
* Applying Transformations: Perform any required narrow transformations that do not involve shuffling data (like filtering or adding new columns).
* Writing to Parquet: Directly write the transformed DataFrame to Parquet files. The setting for maxPartitionBytes ensures that each part-file is approximately 512 MB, meeting the requirement for part-file size without additional steps to repartition or coalesce the data.
* Performance Consideration: This approach is optimal because:
* It avoids the overhead of shuffling data, which can be significant, especially with large datasets.
* It directly ties the read/write operations to a configuration that matches the target output size, making it efficient in terms of both computation and I/O operations.
* Alternative Options Analysis:
* Option B and D: Involves repartitioning, which would trigger a shuffle of the data, contradicting the requirement to avoid shuffling for performance reasons.
* Option C: Uses coalesce, which is less intensive than repartition but can still lead to uneven partition sizes and does not directly control the output file size as effectively as setting maxPartitionBytes.
* Option E: Setting shuffle partitions to 512 doesn't directly control the output file size for writing to Parquet and could lead to smaller files depending on the dataset ' s partitioning post- transformations.
References
* Apache Spark Configuration
* Writing to Parquet Files in Spark
NEW QUESTION # 219
A data engineering manager has noticed that each of the queries in a Databricks SQL dashboard takes a few
minutes to update when they manually click the "Refresh" button. They are curious why this might be
occurring, so a team member provides a variety of reasons on why the delay might be occurring.
Which of the following reasons fails to explain why the dashboard might be taking a few minutes to update?
- A. The SQL endpoint being used by each of the queries might need a few minutes to start up
- B. The queries attached to the dashboard might all be connected to their own, unstarted Databricks clusters
- C. The Job associated with updating the dashboard might be using a non-pooled endpoint
- D. The queries attached to the dashboard might take a few minutes to run under normal circumstances
- E. The queries attached to the dashboard might first be checking to determine if new data is available
Answer: C
NEW QUESTION # 220
......
Never say you can not do it. This is my advice to everyone. Even if you think that you can not pass the demanding Databricks Databricks-Certified-Professional-Data-Engineer exam. You can find a quick and convenient training tool to help you. Dumpleader's Databricks Databricks-Certified-Professional-Data-Engineer exam training materials is a very good training materials. It can help you to pass the exam successfully. And its price is very reasonable, you will benefit from it. So do not say you can't. If you do not give up, the next second is hope. Quickly grab your hope, itis in the Dumpleader's Databricks Databricks-Certified-Professional-Data-Engineer Exam Training materials.
New Databricks-Certified-Professional-Data-Engineer Test Simulator: https://www.dumpleader.com/Databricks-Certified-Professional-Data-Engineer_exam.html
- 100% Pass Quiz Fantastic Databricks-Certified-Professional-Data-Engineer - Databricks Certified Professional Data Engineer Exam Visual Cert Exam 🪓 Download ⇛ Databricks-Certified-Professional-Data-Engineer ⇚ for free by simply searching on ▶ www.exam4labs.com ◀ 🔚Databricks-Certified-Professional-Data-Engineer Top Exam Dumps
- First-hand Databricks Databricks-Certified-Professional-Data-Engineer Visual Cert Exam: Databricks Certified Professional Data Engineer Exam - New Databricks-Certified-Professional-Data-Engineer Test Simulator 🚼 Open website ( www.pdfvce.com ) and search for ➽ Databricks-Certified-Professional-Data-Engineer 🢪 for free download ◀New Databricks-Certified-Professional-Data-Engineer Exam Price
- Databricks-Certified-Professional-Data-Engineer Latest Exam Pdf 😸 Databricks-Certified-Professional-Data-Engineer Detailed Answers 🍒 Valid Test Databricks-Certified-Professional-Data-Engineer Tutorial 🪐 “ www.easy4engine.com ” is best website to obtain 【 Databricks-Certified-Professional-Data-Engineer 】 for free download ⏹Exam Sample Databricks-Certified-Professional-Data-Engineer Questions
- Latest Databricks Databricks-Certified-Professional-Data-Engineer Questions - Get Essential Exam Knowledge [2026] 👾 Search for ➽ Databricks-Certified-Professional-Data-Engineer 🢪 and download it for free on ⇛ www.pdfvce.com ⇚ website 🐵Free Databricks-Certified-Professional-Data-Engineer Test Questions
- Reliable Databricks-Certified-Professional-Data-Engineer Real Exam 🥎 Databricks-Certified-Professional-Data-Engineer Top Exam Dumps 👵 Exam Databricks-Certified-Professional-Data-Engineer Sample 🕗 Download ▶ Databricks-Certified-Professional-Data-Engineer ◀ for free by simply searching on ➤ www.troytecdumps.com ⮘ 🔐New Databricks-Certified-Professional-Data-Engineer Exam Price
- New Databricks-Certified-Professional-Data-Engineer Exam Price 🅰 Latest Databricks-Certified-Professional-Data-Engineer Examprep 🎻 Reliable Databricks-Certified-Professional-Data-Engineer Real Exam 🗣 Easily obtain ➥ Databricks-Certified-Professional-Data-Engineer 🡄 for free download through ⇛ www.pdfvce.com ⇚ 🧐Exam Databricks-Certified-Professional-Data-Engineer Sample
- Databricks-Certified-Professional-Data-Engineer Practice Guide 😎 Databricks-Certified-Professional-Data-Engineer High Quality 🔚 Valid Test Databricks-Certified-Professional-Data-Engineer Tutorial 😮 Search for ⇛ Databricks-Certified-Professional-Data-Engineer ⇚ and download it for free on ( www.troytecdumps.com ) website 🐖Valid Test Databricks-Certified-Professional-Data-Engineer Tutorial
- First-hand Databricks Databricks-Certified-Professional-Data-Engineer Visual Cert Exam: Databricks Certified Professional Data Engineer Exam - New Databricks-Certified-Professional-Data-Engineer Test Simulator 📇 Open 「 www.pdfvce.com 」 and search for ▷ Databricks-Certified-Professional-Data-Engineer ◁ to download exam materials for free 💮New Soft Databricks-Certified-Professional-Data-Engineer Simulations
- Databricks-Certified-Professional-Data-Engineer Top Exam Dumps 🍜 Test Databricks-Certified-Professional-Data-Engineer Online ⭕ Examcollection Databricks-Certified-Professional-Data-Engineer Free Dumps 🙁 The page for free download of 「 Databricks-Certified-Professional-Data-Engineer 」 on ➡ www.verifieddumps.com ️⬅️ will open immediately 👣Databricks-Certified-Professional-Data-Engineer Latest Exam Pdf
- Free PDF Quiz 2026 Pass-Sure Databricks Databricks-Certified-Professional-Data-Engineer Visual Cert Exam ☃ Search for { Databricks-Certified-Professional-Data-Engineer } and obtain a free download on “ www.pdfvce.com ” 🔴Valid Test Databricks-Certified-Professional-Data-Engineer Tutorial
- Databricks-Certified-Professional-Data-Engineer Visual Cert Exam - Pass Guaranteed Quiz 2026 Databricks-Certified-Professional-Data-Engineer: Databricks Certified Professional Data Engineer Exam First-grade New Test Simulator 🧙 Open ✔ www.examdiscuss.com ️✔️ enter ⏩ Databricks-Certified-Professional-Data-Engineer ⏪ and obtain a free download 🔢New Databricks-Certified-Professional-Data-Engineer Exam Price
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
P.S. Free & New Databricks-Certified-Professional-Data-Engineer dumps are available on Google Drive shared by Dumpleader: https://drive.google.com/open?id=11pfEZS88vSPOs1ut_qE-VB05B5CHH-1j