DOWNLOAD the newest Prep4King AI-300 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1fJk4KbTO2i2464lBoiSvROaf2kj6nk3A
The Microsoft sector is an ever-evolving and rapidly growing industry that is crucial in shaping our lives today. With the growing demand for skilled Microsoft professionals, obtaining Operationalizing Machine Learning and Generative AI Solutions (AI-300) certification exam has become increasingly important for those who are looking to advance their careers and stay competitive in the job market. Individuals who hold Operationalizing Machine Learning and Generative AI Solutions (AI-300) certification exam demonstrate to their employers and clients that they have the knowledge and skills necessary to succeed in the AI-300 exam.
| Section | Objectives |
|---|---|
| Topic 1: Design and implement a GenAIOps infrastructure | - Manage API keys, rate limits, and responsible AI guardrails - Set up Microsoft Foundry and Azure AI services for generative AI workloads - Configure prompt orchestration, prompt flows, and agent frameworks - Implement RAG (Retrieval-Augmented Generation) pipelines and vector search |
| Topic 2: Implement machine learning model lifecycle and operations | - Monitor model performance, data drift, and operational health - Train, register, and version models using Azure Machine Learning - Retrain, update, and manage model versions in production - Deploy models to real-time and batch endpoints |
| Topic 3: Implement generative AI quality assurance and observability | - Implement logging, tracing, and telemetry for GenAI applications - Monitor latency, token usage, cost, and error rates - Evaluate generative AI outputs for quality, safety, and grounding - Conduct red teaming, adversarial testing, and content filtering |
| Topic 4: Design and implement an MLOps infrastructure | - Configure source control, CI/CD pipelines, and automation for ML workflows - Set up Azure Machine Learning workspace and compute targets - Manage environments, data stores, and model registries - Implement security, governance, and compliance for MLOps |
| Topic 5: Optimize generative AI systems and model performance | - Tune prompts, system messages, and grounding strategies - Optimize inference performance, caching, and throughput - Implement cost management and scaling strategies for GenAI workloads - Fine-tune and distill models for specific use cases |
About your blurry memorization of the knowledge, our AI-300 learning materials can help them turn to very clear ones. We have been abiding the intention of providing the most convenient services for you all the time on AI-300 study guide, which is also the objection of us. We also have high staff turnover with high morale after-sales staff offer help 24/7. So our customer loyalty derives from advantages of our AI-300 Preparation quiz.
NEW QUESTION # 170
You have an Azure Machine Learning workspace named Workspace 1 Workspace! has a registered Mlflow model named model 1 with PyFunc flavor You plan to deploy model1 to an online endpoint named endpoint1 without egress connectivity by using Azure Machine learning Python SDK vl You have the following code: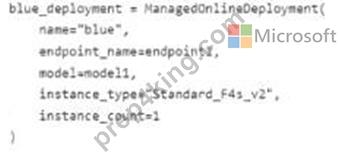
You need to add a parameter to the ManagedOnllneDeployment object to ensure the model deploys successfully Solution: Add the scoring_script parameter.
Does the solution meet the goal?
Answer: B
NEW QUESTION # 171
A team deploys a classification model to production and scores incoming customer data daily.
After several weeks, business stakeholders report unexpected changes in prediction behavior, even though the endpoint remains healthy.
You need to determine whether data drift is occurring and if it is, identify the appropriate actions.
Which action should you perform for each observed signal? To answer, move the appropriate actions to the correct observed signals. You may use each action once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.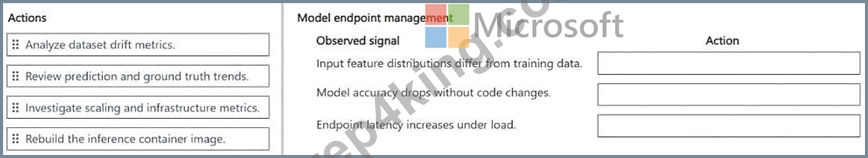
Answer:
Explanation: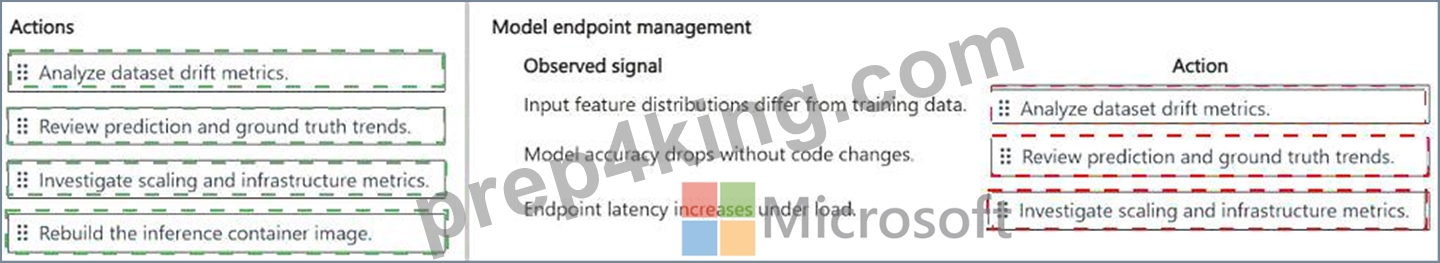
Explanation:
Input feature distributions differ from training data: Analyze dataset drift metrics Model accuracy drops without code changes: Review prediction and ground truth trends Endpoint latency increases under load: Investigate scaling and infrastructure metrics When input feature distributions differ from training data , the correct action is to analyze dataset drift metrics . Azure Machine Learning model monitoring detects data drift by comparing the statistical distributions of production model inputs against reference data, commonly the original training dataset.
Supported measures include Population Stability Index, Jensen-Shannon distance, normalized Wasserstein distance, and statistical tests such as Kolmogorov-Smirnov.
When model accuracy drops without code changes , the next investigation should focus on prediction and ground-truth trends . Azure Machine Learning model-performance monitoring compares production predictions with collected actual outcomes and can calculate classification metrics such as accuracy, precision, and recall. A declining score without deployment changes may indicate concept drift, prediction drift, or changing relationships between input features and target outcomes.
When endpoint latency increases under load , the issue is operational rather than primarily statistical. The team should investigate scaling and infrastructure metrics , including request latency, requests per minute, CPU/memory utilization, throttling, and replica capacity. Microsoft recommends using endpoint metrics to determine whether compute must scale up or out.
Rebuild the inference container image is not indicated by any of the observed signals.
Study Guide Reference: Implement machine learning model lifecycle and operations - production monitoring, data drift, model-performance monitoring, endpoint observability, and scaling.
NEW QUESTION # 172
During training, pipelines occasionally fail due to schema mismatch caused by upstream data changes. You need a robust and automated solution that prevents invalid data from reaching training steps. What is the BEST approach?
Answer: A
Explanation:
A data validation component ensures that incoming data matches the expected schema before training begins. This prevents pipeline failures and avoids training on corrupted or incomplete data. Ignoring schema mismatches can introduce silent errors, making debugging difficult and compromising model quality.
NEW QUESTION # 173
Drag and Drop Question
You manage an Azure Machine Learning workspace named workspace1 with a compute instance named compute1. You connect to compute1 by using a terminal window from workspace1.
You create a file named "requirements.txt" containing Python dependencies to include Jupyter.
You need to add a new Jupyter kernel to compute1.
Which four commands should you use? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.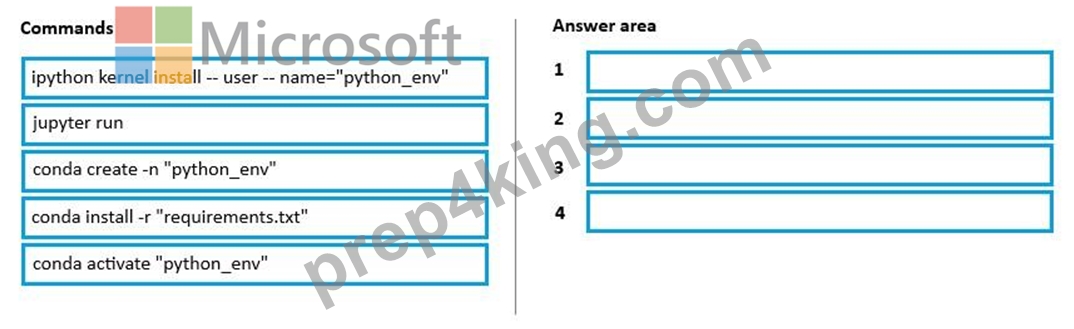
Answer:
Explanation: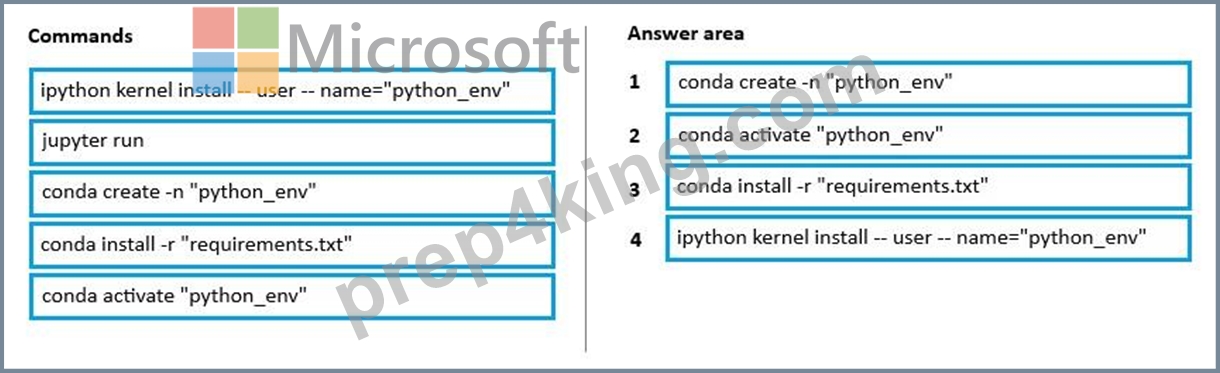
Explanation:
Step 1: conda create -n "python_env"
1. Create the environment
conda create -n python_env python=3.10 -y
Step 2: conda activate "python_env"
2. Activate it
conda activate python_env
Step 3: pip install -r "requirements.txt"
3. Install your dependencies (including ipykernel)
pip install -r requirements.txt
Step 4: ipython kernel install --user --name="python_env"
4. Register the environment as a Jupyter kernel
ipython kernel install --user --name="python_env"
NEW QUESTION # 174
Hotspot Question
A team is building a generative AI agent by using Retrieval-Augmented Generation (RAG) in Microsoft Foundry.
The team frequently updates prompt content. The team must be able to track changes across contributors while avoiding full application redeployments.
You need to enable rapid prompt iteration with traceability. Applications consuming the agent must be able to use updated prompts without requiring redeployment.
What should you configure for each requirement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.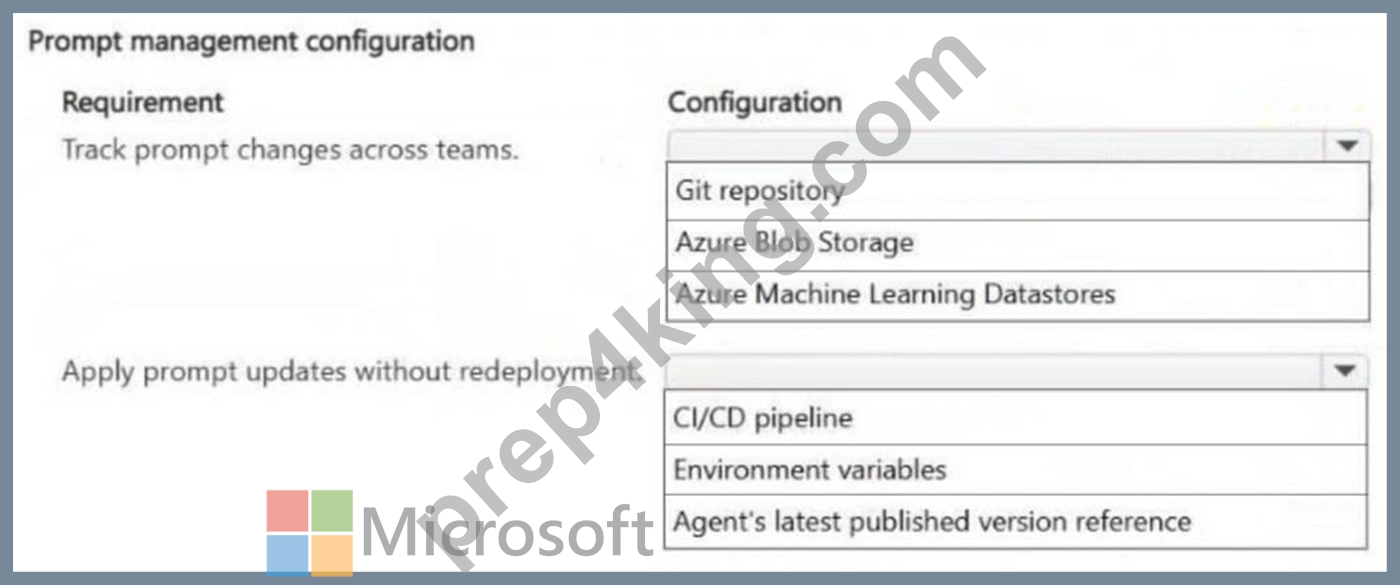
Answer:
Explanation: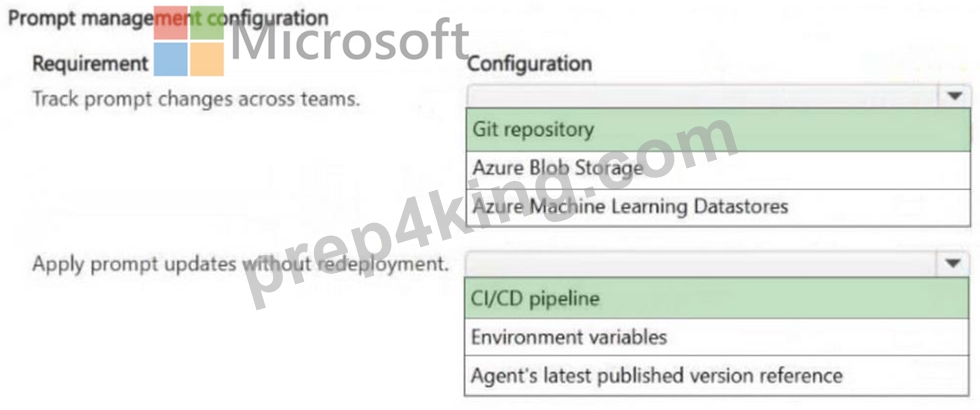
NEW QUESTION # 175
......
The AI-300 test prep mainly help our clients pass the AI-300 exam and gain the certification. The certification can bring great benefits to the clients. The clients can enter in the big companies and earn the high salary. You may double the salary after you pass the AI-300 Exam. If you own the certification it proves you master the AI-300 quiz torrent well and you own excellent competences and you will be respected in your company or your factory. If you want to change your job it is also good for you.
AI-300 Preparation: https://www.prep4king.com/AI-300-exam-prep-material.html
P.S. Free & New AI-300 dumps are available on Google Drive shared by Prep4King: https://drive.google.com/open?id=1fJk4KbTO2i2464lBoiSvROaf2kj6nk3A