Außerdem sind jetzt einige Teile dieser ExamFragen Data-Engineer-Associate Prüfungsfragen kostenlos erhältlich: https://drive.google.com/open?id=1Du34p9D75Tl3swOf6smrNz1z4CSTUpzf
Wie wir alle wissen, genießen die Dumps zur Amazon Data-Engineer-Associate Zertifizierungsprüfung von ExamFragen einen guten Ruf und sind international berühmt. Wieso kann ExamFragen so große Resonanz finden? Weil die Fragenkataloge zur Amazon Data-Engineer-Associate Zertifizierng von ExamFragen wirklich praktisch sind und Ihnen helfen können, gute Noten in der Data-Engineer-Associate Prüfung zu erzielen.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Ingestion and Transformation | 34% | - Orchestrate data pipelines
|
| Topic 2: Data Security and Governance | 18% | - Apply authentication and authorization
|
| Topic 3: Data Operations and Support | 22% | - Manage and troubleshoot data processes
|
| Topic 4: Data Store Management | 26% | - Manage data lifecycle
|
>> Data-Engineer-Associate PDF <<
Haben Sie an der Amazon Data-Engineer-Associate Zertifizierungsprüfung teilgenommen? Was kann ich machen, wenn ich die Prüfung ablege, daran ich nicht selbstbewusst bin? Gibt es Abkürzung für die Data-Engineer-Associate Prüfung? Es gibt nicht genug Zeit, die Bücher auswendig zu lernen. Sind Sie der ähnlichen Meinungen? Wenn ja, kümmern Sie sich nicht darum, weil Sie immer noch die Chance haben diese Data-Engineer-Associate Prüfung gut vorzubereiten, obwohl die Prüfungszeit vor Ihnen schnell auftaucht? Wie kann ich diese Chance finden? Das ist die Amazon Data-Engineer-Associate Dumps von ExamFragen. Es gibt hocheffektive Prüfungsunterlagen zur Zertifizierung. Es kann Ihnen helfen, in kurzer Zeit die Prüfungsfragen vorzubereiten. Die Hitz-Rate dieser dumps sind sehr hoch. Deshalb können Sie Amazon Data-Engineer-Associate Zertifizierungsprüfung bestehen, wenn Sie die Prüfungsfragen und -antworten gut lernen.
242. Frage
A company stores employee data in Amazon Redshift A table named Employee uses columns named Region ID, Department ID, and Role ID as a compound sort key. Which queries will MOST increase the speed of a query by using a compound sort key of the table? (Select TWO.)
Antwort: A,C
Begründung:
In Amazon Redshift, a compound sort key is designed to optimize the performance of queries that use filtering and join conditions on the columns in the sort key. A compound sort key orders the data based on the first column, followed by the second, and so on. In the scenario given, the compound sort key consists of Region ID, Department ID, and Role ID. Therefore, queries that filter on the leading columns of the sort key are more likely to benefit from this order.
* Option B: "Select * from Employee where Region ID='North America' and Department ID=20;" This query will perform well because it uses both the Region ID and Department ID, which are the first two columns of the compound sort key. The order of the columns in the WHERE clause matches the order in the sort key, thus allowing the query to scan fewer rows and improve performance.
* Option C: "Select * from Employee where Department ID=20 and Region ID='North America';" This query also benefits from the compound sort key because it includes both Region ID and Department ID, which are the first two columns in the sort key. Although the order in the WHERE clause does not match exactly, Amazon Redshift will still leverage the sort key to reduce the amount of data scanned, improving query speed.
* Options A, D, and E are less optimal because they do not utilize the sort key as effectively:
* Option A only filters by the Region ID, which may still use the sort key but does not take full advantage of the compound nature.
* Option D uses only Role ID, the last column in the compound sort key, which will not benefit much from sorting since it is the third key in the sort order.
* Option E filters on Region ID and Role ID but skips the Department ID column, making it less efficient for the compound sort key.
References:
* Amazon Redshift Documentation - Sorting Data
* AWS Certified Data Analytics Study Guide
* AWS Certification - Data Engineer Associate Exam Guide
243. Frage
A company is building an inventory management system and an inventory reordering system to automatically reorder products. Both systems use Amazon Kinesis Data Streams. The inventory management system uses the Amazon Kinesis Producer Library (KPL) to publish data to a stream. The inventory reordering system uses the Amazon Kinesis Client Library (KCL) to consume data from the stream. The company configures the stream to scale up and down as needed.
Before the company deploys the systems to production, the company discovers that the inventory reordering system received duplicated data.
Which factors could have caused the reordering system to receive duplicated data? (Select TWO.)
Antwort: A,C
Begründung:
Problem Analysis:
The company uses Kinesis Data Streams for both inventory management and reordering.
The Kinesis Producer Library (KPL) publishes data, and the Kinesis Client Library (KCL) consumes data.
Duplicate records were observed in the inventory reordering system.
Key Considerations:
Kinesis streams are designed for durability but may produce duplicates under certain conditions.
Factors such as network timeouts, shard splits, or changes in record processors can cause duplication.
Solution Analysis:
Option A: Network-Related Timeouts
If the producer (KPL) experiences network timeouts, it retries data submission, potentially causing duplicates.
Option B: High IteratorAgeMilliseconds
High iterator age suggests delays in processing but does not directly cause duplication.
Option C: Changes in Shards or Processors
Changes in the number of shards or record processors can lead to re-processing of records, causing duplication.
Option D: AggregationEnabled Set to True
AggregationEnabled controls the aggregation of multiple records into one, but it does not cause duplication.
Option E: High max_records Value
A high max_records value increases batch size but does not lead to duplication.
Final Recommendation:
Network-related timeouts and changes in shards or processors are the most likely causes of duplicate data in this scenario.
Amazon Kinesis Data Streams Best Practices
Kinesis Producer Library (KPL) Overview
Kinesis Client Library (KCL) Overview
244. Frage
A company maintains a data warehouse in an on-premises Oracle database. The company wants to build a data lake on AWS. The company wants to load data warehouse tables into Amazon S3 and synchronize the tables with incremental data that arrives from the data warehouse every day.
Each table has a column that contains monotonically increasing values. The size of each table is less than 50 GB. The data warehouse tables are refreshed every night between 1 AM and 2 AM. A business intelligence team queries the tables between 10 AM and 8 PM every day.
Which solution will meet these requirements in the MOST operationally efficient way?
Antwort: C
Begründung:
The company needs to load data warehouse tables into Amazon S3 and perform incremental synchronization with daily updates. The most efficient solution is to use AWS Database Migration Service (AWS DMS) with a combination of full load and change data capture (CDC) to handle the initial load and daily incremental updates.
Option A: Use an AWS Database Migration Service (AWS DMS) full load plus CDC job to load tables that contain monotonically increasing data columns from the on-premises data warehouse to Amazon S3. Use custom logic in AWS Glue to append the daily incremental data to a full-load copy that is in Amazon S3.
DMS is designed to migrate databases to AWS, and the combination of full load plus CDC is ideal for handling incremental data changes efficiently. AWS Glue can then be used to append the incremental data to the full data set in S3. This solution is highly operationally efficient because it automates both the full load and incremental updates.
Options B, C, and D are less operationally efficient because they either require writing custom logic to handle bookmarks manually or involve unnecessary daily full loads.
References:
AWS Database Migration Service Documentation
AWS Glue Documentation
245. Frage
A data engineer needs to create an Amazon Athena table based on a subset of data from an existing Athena table named cities_world. The cities_world table contains cities that are located around the world. The data engineer must create a new table named cities_us to contain only the cities from cities_world that are located in the US.
Which SQL statement should the data engineer use to meet this requirement?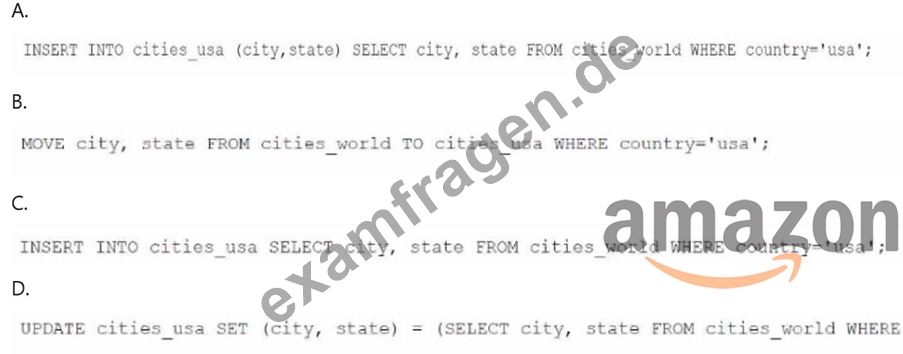
Antwort: A
Begründung:
To create a new table named cities_usa in Amazon Athena based on a subset of data from the existing cities_world table, you should use an INSERT INTO statement combined with a SELECT statement to filter only the records where the country is 'usa'. The correct SQL syntax would be:
Option A: INSERT INTO cities_usa (city, state) SELECT city, state FROM cities_world WHERE country='usa'; This statement inserts only the cities and states where the country column has a value of 'usa' from the cities_world table into the cities_usa table. This is a correct approach to create a new table with data filtered from an existing table in Athena.
Options B, C, and D are incorrect due to syntax errors or incorrect SQL usage (e.g., the MOVE command or the use of UPDATE in a non-relevant context).
Reference:
Amazon Athena SQL Reference
Creating Tables in Athena
246. Frage
A manufacturing company collects sensor data from its factory floor to monitor and enhance operational efficiency. The company uses Amazon Kinesis Data Streams to publish the data that the sensors collect to a data stream. Then Amazon Kinesis Data Firehose writes the data to an Amazon S3 bucket.
The company needs to display a real-time view of operational efficiency on a large screen in the manufacturing facility.
Which solution will meet these requirements with the LOWEST latency?
Antwort: D
Begründung:
This solution will meet the requirements with the lowest latency because it uses Amazon Managed Service for Apache Flink to process the sensor data in real time and write it to Amazon Timestream, a fast, scalable, and serverless time series database. Amazon Timestream is optimized for storing and analyzing time series data, such as sensor data, and can handle trillions of events per day with millisecond latency. By using AmazonTimestream as a source, you can create an Amazon QuickSight dashboard that displays a real-time view of operational efficiency on a large screen in the manufacturing facility. Amazon QuickSight is a fully managed business intelligence service that can connect to various data sources, including Amazon Timestream, and provide interactive visualizations and insights123.
The other options are not optimal for the following reasons:
A: Use Amazon Managed Service for Apache Flink (previously known as Amazon Kinesis Data Analytics) to process the sensor data. Use a connector for Apache Flink to write data to an Amazon Timestream database. Use the Timestream database as a source to create a Grafana dashboard. This option is similar to option C, but it uses Grafana instead of Amazon QuickSight to create the dashboard.
Grafana is an open source visualization tool that can also connect to Amazon Timestream, but it requires additional steps to set up and configure, such as deploying a Grafana server on Amazon EC2, installing the Amazon Timestream plugin, and creating an IAM role for Grafana to access Timestream. These steps can increase the latency and complexity of the solution.
B: Configure the S3 bucket to send a notification to an AWS Lambda function when any new object is created. Use the Lambda function to publish the data to Amazon Aurora. Use Aurora as a source to create an Amazon QuickSight dashboard. This option is not suitable for displaying a real-time view of operational efficiency, as it introduces unnecessary delays and costs in the data pipeline. First, the sensor data is written to an S3 bucket by Amazon Kinesis Data Firehose, which can have a buffering interval of up to 900 seconds. Then, the S3 bucket sends a notification to a Lambda function, which can incur additional invocation and execution time. Finally, the Lambda function publishes the data to Amazon Aurora, a relational database that is not optimized for time series data and can have higher storage and performance costs than Amazon Timestream .
D: Use AWS Glue bookmarks to read sensor data from the S3 bucket in real time. Publish the data to an Amazon Timestream database. Use the Timestream database as a source to create a Grafana dashboard.
This option is also not suitable for displaying a real-time view of operational efficiency, as it uses AWS Glue bookmarks to read sensor data from the S3 bucket. AWS Glue bookmarks are a feature that helps AWS Glue jobs and crawlers keep track of the data that has already been processed, so that they can resume from where they left off. However, AWS Glue jobs and crawlers are not designed for real-time data processing, as they can have a minimum frequency of 5 minutes and a variable start-up time.
Moreover, this option also uses Grafana instead of Amazon QuickSight to create the dashboard, which can increase the latency and complexity of the solution .
References:
1: Amazon Managed Streaming for Apache Flink
2: Amazon Timestream
3: Amazon QuickSight
4: Analyze data in Amazon Timestream using Grafana
5: Amazon Kinesis Data Firehose
6: Amazon Aurora
7: AWS Glue Bookmarks
8: AWS Glue Job and Crawler Scheduling
247. Frage
......
Eine breite Vielzahl von Amazon Data-Engineer-Associate Prüfungsfragen und Antworten aus ExamFragen sind logisch. Amazon Data-Engineer-Associate Zertifizierungsantworten aus ExamFragen sind gleich wie die in der realen Prüfung. Vor dem Kauf der Amazon Data-Engineer-Associate Echte Fragen können Sie kostenlose Demo zum Teil auf der Website www.ExamFragen.de herunterladen.
Data-Engineer-Associate Testing Engine: https://www.examfragen.de/Data-Engineer-Associate-pruefung-fragen.html
Übrigens, Sie können die vollständige Version der ExamFragen Data-Engineer-Associate Prüfungsfragen aus dem Cloud-Speicher herunterladen: https://drive.google.com/open?id=1Du34p9D75Tl3swOf6smrNz1z4CSTUpzf