Test Databricks Databricks-Certified-Data-Engineer-Associate Dumps & Databricks-Certified-Data-Engineer-Associate Reliable Dump
Our company attaches great importance on improving the Databricks-Certified-Data-Engineer-Associate study prep. In addition, we clearly know that constant improvement is of great significance to the survival of a company. The fierce competition in the market among the same industry has long existed. As for our Databricks-Certified-Data-Engineer-Associate exam braindump, our company masters the core technology, owns the independent intellectual property rights and strong market competitiveness. What is more, we have never satisfied our current accomplishments. The highest record is up to five seconds. There has no delay time of the grading process. Slow system response doesn’t exist. In addition, the calculation system of the Databricks-Certified-Data-Engineer-Associate Test Question is very powerful and stable. We promise that the results of your exercises are accurate.
| Topic | Details |
|---|
| Topic 1 | - Databricks Lakehouse Platform: This topic covers the relationship between the data lakehouse and the data warehouse, the improvement in data quality, comparing and contrasting silver and gold tables, elements of the Databricks Platform Architecture, and differentiating between all-purpose clusters and jobs clusters. Moreover, it identifies how cluster software is versioned, how clusters can be filtered, how to use multiple languages, how to run one notebook, how notebooks can be shared, Git operations, and limitations in Databricks Notebooks. Lastly, the topic describes how clusters are terminated, how to use multiple languages, and how Databricks Repos enables CI
- CD workflows.
|
| Topic 2 | - Production Pipelines: It focuses on identifying the advantages of using multiple tasks in Jobs, a suitable scenario where predecessor task should be set up, CRON as an opportunity for scheduling opportunity, and how an alert can be sent via email. The topic also discusses setting up a predecessor task in Jobs, reviewing a task's execution history, and debugging a failed task. Lastly, it delves into setting up a retry policy in case of failure and creating an alert in the case of a failed task.
|
| Topic 3 | - Incremental Data Processing: In this topic questions about identifying Delta Lake, benefits of ACID transactions, a scenario to use an external table, location of a table, the benefits of Zordering, the kind of files, CTAS as a solution, the impact of ON VIOLATION DROP ROW and ON VIOLATION FAIL UPDATE, and the necessary component to create a new DLT pipeline. Moreover, the topic also discusses directory structure of Delta Lake files, generated column, adding a table comment, and the benefits of the MERGE command.
|
| Topic 4 | - ELT with Apache Spark: It focuses on extracting data, identifying the prefix, creating a view, duplicating rows, creating a new table, utilizing the dot, parsing JSON, and defining a SQL UDF. Moreover, the topic delves into describing the security model, identifying the location of a function, and identifying the PIVOT.
|
| Topic 5 | - Data Governance: It identifies one of the four areas of data governance, Unity Catalog securables, and the cluster security modes. It also discusses how to create a UC-enabled all-purpose cluster and a DBSQL warehouse. The topic explains how to implement data object access control, create a DBSQL warehouse, and e a UC-enabled all-purpose cluster.
|
>> Test Databricks Databricks-Certified-Data-Engineer-Associate Dumps <<
2026 Databricks Realistic Test Databricks-Certified-Data-Engineer-Associate Dumps
We guarantee that if you study our Databricks-Certified-Data-Engineer-Associate guide materials with dedication and enthusiasm step by step, you will desperately pass the exam without doubt. As the authoritative provider of study materials, we are always in pursuit of high pass rate of Databricks-Certified-Data-Engineer-Associate practice test compared with our counterparts to gain more attention from potential customers. Otherwise if you fail to pass the exam unfortunately with our Databricks-Certified-Data-Engineer-Associate Study Materials, we will full refund the products cost to you soon. Our Databricks-Certified-Data-Engineer-Associate study torrent will be more attractive and marvelous with high pass rate.
Databricks-Certified-Data-Engineer-Associate exam is a comprehensive exam that tests the individual's knowledge of Databricks and its various features. Databricks-Certified-Data-Engineer-Associate exam includes multiple-choice questions that require the individual to select the best answer from a list of options. Databricks-Certified-Data-Engineer-Associate Exam also includes hands-on tasks that require the individual to demonstrate their ability to perform specific tasks using Databricks.
Databricks Certified Data Engineer Associate Exam Sample Questions (Q23-Q28):
NEW QUESTION # 23
A data organization leader is upset about the data analysis team's reports being different from the data engineering team's reports. The leader believes the siloed nature of their organization's data engineering and data analysis architectures is to blame.
Which of the following describes how a data lakehouse could alleviate this issue?
- A. Both teams would autoscale their work as data size evolves
- B. Both teams would use the same source of truth for their work
- C. Both teams would respond more quickly to ad-hoc requests
- D. Both teams would be able to collaborate on projects in real-time
- E. Both teams would reorganize to report to the same department
Answer: B
Explanation:
A data lakehouse is a data management architecture that combines the flexibility, cost-efficiency, and scale of data lakes with the data management and ACID transactions of data warehouses, enabling business intelligence (BI) and machine learning (ML) on all data12. By using a data lakehouse, both the data analysis and data engineering teams can access the same data sources and formats, ensuring data consistency and quality across their reports. A data lakehouse also supports schema enforcement and evolution, data validation, and time travel to old table versions, which can help resolve data conflicts and errors1. Reference: 1: What is a Data Lakehouse? - Databricks 2: What is a data lakehouse? | IBM
NEW QUESTION # 24
A data organization leader is upset about the data analysis team's reports being different from the data engineering team's reports. The leader believes the siloed nature of their organization's data engineering and data analysis architectures is to blame.
Which of the following describes how a data lakehouse could alleviate this issue?
- A. Both teams would autoscale their work as data size evolves
- B. Both teams would use the same source of truth for their work
- C. Both teams would respond more quickly to ad-hoc requests
- D. Both teams would be able to collaborate on projects in real-time
- E. Both teams would reorganize to report to the same department
Answer: B
NEW QUESTION # 25
A company uses Delta Sharing to collaborate with partners across different cloud providers and geographic regions. What will result in additional costs due to cross-region or egress fees?
- A. Sharing data within the same cloud provider and region
- B. Accessing Delta Sharing data using a VPN within the same data center
- C. Utilizing Delta Sharing for internal data analytics within a single cloud environment
- D. Transferring data via Delta Sharing across clouds and across different geographic regions
Answer: D
Explanation:
Databricks documents that Delta Sharing does not require data replication , but cloud providers can still charge data egress fees when data is shared across clouds or across geographic regions . Databricks specifically states that sharing within the same region incurs no egress cost , while cross-cloud or cross- region transfers can create additional charges from the underlying cloud provider. That means option A is correct. Options B and C describe same-cloud or same-region use cases that do not trigger the cross-region
/cross-cloud egress pattern Databricks calls out. Option D is unrelated to the main documented billing driver for Delta Sharing costs. The important principle is that Delta Sharing itself is designed to avoid replication overhead, but the physical movement of data between cloud boundaries or regions can still result in vendor networking charges. Therefore, when sharing data with external partners in other regions or clouds, engineers should plan for possible egress costs and monitor them accordingly.
=========
NEW QUESTION # 26
A data engineer has configured a Structured Streaming job to read from a table, manipulate the data, and then perform a streaming write into a new table.
The code block used by the data engineer is below:
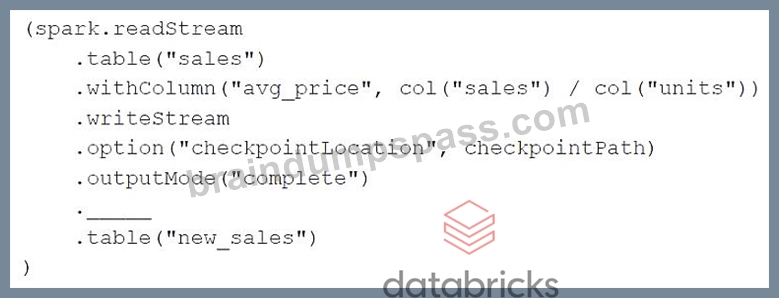
If the data engineer only wants the query to process all of the available data in as many batches as required, which of the following lines of code should the data engineer use to fill in the blank?
- A. processingTime(1)
- B. trigger(parallelBatch=True)
- C. trigger(continuous="once")
- D. trigger(availableNow=True)
- E. trigger(processingTime="once")
Answer: D
Explanation:
https://spark.apache.org/docs/latest/api/python/reference/pyspark.ss/api/pyspark.sql.streaming.DataStreamWriter.trigger.html
NEW QUESTION # 27
A data engineer wants to schedule their Databricks SQL dashboard to refresh every hour, but they only want the associated SQL endpoint to be running when it is necessary. The dashboard has multiple queries on multiple datasets associated with it. The data that feeds the dashboard is automatically processed using a Databricks Job.
Which of the following approaches can the data engineer use to minimize the total running time of the SQL endpoint used in the refresh schedule of their dashboard?
- A. They can reduce the cluster size of the SQL endpoint.
- B. They can turn on the Auto Stop feature for the SQL endpoint.
- C. They can ensure the dashboard's SQL endpoint is not one of the included query's SQL endpoint.
- D. They can set up the dashboard's SQL endpoint to be serverless.
- E. They can ensure the dashboard's SQL endpoint matches each of the queries' SQL endpoints.
Answer: B
NEW QUESTION # 28
......
Databricks-Certified-Data-Engineer-Associate Reliable Dump: https://www.braindumpspass.com/Databricks/Databricks-Certified-Data-Engineer-Associate-practice-exam-dumps.html
- Clearer Databricks-Certified-Data-Engineer-Associate Explanation 🚋 Valid Databricks-Certified-Data-Engineer-Associate Test Forum 🧿 Databricks-Certified-Data-Engineer-Associate Practice Exams Free 🔪 Simply search for ➡ Databricks-Certified-Data-Engineer-Associate ️⬅️ for free download on “ www.vce4dumps.com ” 🍗Valid Test Databricks-Certified-Data-Engineer-Associate Braindumps
- Databricks-Certified-Data-Engineer-Associate Reliable Exam Camp 🍅 Databricks-Certified-Data-Engineer-Associate Passed 🐌 Valid Test Databricks-Certified-Data-Engineer-Associate Braindumps 💇 《 www.pdfvce.com 》 is best website to obtain ▷ Databricks-Certified-Data-Engineer-Associate ◁ for free download 💃Best Databricks-Certified-Data-Engineer-Associate Practice
- Databricks-Certified-Data-Engineer-Associate Free Exam 🤮 Clearer Databricks-Certified-Data-Engineer-Associate Explanation 🦐 Databricks-Certified-Data-Engineer-Associate Reliable Test Question 🔏 Easily obtain free download of { Databricks-Certified-Data-Engineer-Associate } by searching on 《 www.prepawayete.com 》 🧇Databricks-Certified-Data-Engineer-Associate Passed
- Databricks-Certified-Data-Engineer-Associate Reliable Test Materials 🥠 Databricks-Certified-Data-Engineer-Associate Reliable Test Materials 🕺 Databricks-Certified-Data-Engineer-Associate Passed 🧄 Open ▛ www.pdfvce.com ▟ and search for ( Databricks-Certified-Data-Engineer-Associate ) to download exam materials for free 🦋Databricks-Certified-Data-Engineer-Associate Training Material
- Valid Test Databricks-Certified-Data-Engineer-Associate Dumps - Pass Databricks-Certified-Data-Engineer-Associate Once - Reliable Databricks-Certified-Data-Engineer-Associate Reliable Dump 🪒 Search for “ Databricks-Certified-Data-Engineer-Associate ” and download exam materials for free through 「 www.vceengine.com 」 🎣Reliable Databricks-Certified-Data-Engineer-Associate Test Blueprint
- Pass Your Databricks Databricks-Certified-Data-Engineer-Associate Exam with Complete Test Databricks-Certified-Data-Engineer-Associate Dumps: Databricks Certified Data Engineer Associate Exam Efficiently 🥻 ➥ www.pdfvce.com 🡄 is best website to obtain ➡ Databricks-Certified-Data-Engineer-Associate ️⬅️ for free download 📌Databricks-Certified-Data-Engineer-Associate Passed
- Databricks-Certified-Data-Engineer-Associate Training Material 🛢 Databricks-Certified-Data-Engineer-Associate Reliable Exam Camp 🦮 Databricks-Certified-Data-Engineer-Associate Practice Exams Free 🏵 Simply search for ➠ Databricks-Certified-Data-Engineer-Associate 🠰 for free download on ➡ www.verifieddumps.com ️⬅️ 😪Databricks-Certified-Data-Engineer-Associate Reliable Exam Camp
- Databricks-Certified-Data-Engineer-Associate Reliable Test Question 🍃 Databricks-Certified-Data-Engineer-Associate Reliable Practice Questions 🥜 Reliable Databricks-Certified-Data-Engineer-Associate Test Blueprint 🛀 Go to website { www.pdfvce.com } open and search for { Databricks-Certified-Data-Engineer-Associate } to download for free 🎮Latest Databricks-Certified-Data-Engineer-Associate Training
- Databricks-Certified-Data-Engineer-Associate Reliable Exam Camp 🎏 Databricks-Certified-Data-Engineer-Associate Passed ⚗ Best Databricks-Certified-Data-Engineer-Associate Practice 🌘 Go to website ▷ www.vce4dumps.com ◁ open and search for 「 Databricks-Certified-Data-Engineer-Associate 」 to download for free 🤿Databricks-Certified-Data-Engineer-Associate Free Exam
- Top Features of Databricks Databricks-Certified-Data-Engineer-Associate Exam Practice Questions 🔫 Go to website ▶ www.pdfvce.com ◀ open and search for 《 Databricks-Certified-Data-Engineer-Associate 》 to download for free 🏝Pdf Databricks-Certified-Data-Engineer-Associate Torrent
- Reliable Databricks-Certified-Data-Engineer-Associate Test Blueprint 🍼 Databricks-Certified-Data-Engineer-Associate Exam Objectives Pdf 🌒 Databricks-Certified-Data-Engineer-Associate Reliable Dumps Free 🥯 Search for ▛ Databricks-Certified-Data-Engineer-Associate ▟ and obtain a free download on ➤ www.practicevce.com ⮘ ♻Valid Test Databricks-Certified-Data-Engineer-Associate Braindumps
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes