真実的なNCA-GENM勉強方法一回合格-信頼的なNCA-GENM試験対策書

P.S. CertShikenがGoogle Driveで共有している無料かつ新しいNCA-GENMダンプ:https://drive.google.com/open?id=1RmuhrbxfjS5vy7-jBvOs3wBd2HGXq3Wo
NCA-GENMスタディガイドでは、無料の試用サービスを提供しているため、購入前にいくつかのトピックやソフトウェアを開く方法について学ぶことができます。 NCA-GENM学習教材の試用期間中、サンプルの質問のPDFバージョンは無料でダウンロードできます。また、PCバージョンとオンラインバージョンの両方を明確に示すことができます。 購入または試用プロセスでNCA-GENM試験の質問に問題がある場合は、いつでもご連絡いただけます。NVIDIA NCA-GENMトレーニングガイドで専門家をリモートで支援します。
NVIDIA NCA-GENM Exam Syllabus Topics:
| Section | Objectives |
|---|
| Topic 1: Responsible and Trustworthy AI | - Bias and safety considerations
- Ethical AI principles
|
| Topic 2: Multimodal AI Systems | - Multimodal model design
- Cross-modal learning
- 1. Audio-visual understanding
- 2. Text-image integration
|
| Topic 3: NVIDIA AI Ecosystem | - NVIDIA tools and frameworks
- 1. NeMo framework usage
- 2. GPU-accelerated AI workflows
|
| Topic 4: Generative AI Concepts | - Generative models
- 1. Transformers and LLM basics
- 2. Diffusion models
|
| Topic 5: Core AI and Machine Learning Fundamentals | - Machine learning basics
- 1. Neural networks fundamentals
- 2. Supervised and unsupervised learning
|
>> NCA-GENM勉強方法 <<
ユニーク-信頼的なNCA-GENM勉強方法試験-試験の準備方法NCA-GENM試験対策書
CertShikenのNVIDIAのNCA-GENM試験トレーニング資料を購入した後、君の受験のための知識をテストして、約束の時間での表現も評価します。CertShikenの NVIDIAのNCA-GENM試験トレーニング資料は高度に認証されたIT領域の専門家の経験と創造を含めているものです。そのけん異性は言うまでもありません。もし君はいささかな心配することがあるなら、あなたはうちの商品を購入する前に、CertShikenは無料でサンプルを提供することができます。
NVIDIA Generative AI Multimodal 認定 NCA-GENM 試験問題 (Q44-Q49):
質問 # 44
You're training a multimodal model for image and text retrieval. Given an image, the model should retrieve the most relevant text description from a database, and vice-vers a. You're using a dual-encoder architecture, where one encoder processes images and the other processes text, projecting them into a shared embedding space. What is the most effective way to train the model to ensure that semantically similar images and texts have close embeddings, while dissimilar ones have distant embeddings?
- A. Use a simple L1 loss between the image and text embeddings-
- B. Use a reconstruction loss that forces the model to reconstruct the input image from its text embedding and vice-versa.
- C. Use a contrastive loss function that minimizes the distance between embeddings of matching image-text pairs and maximizes the distance between embeddings of non-matching pairs. Example: Triplet Loss, InfoNCE.
- D. Train the encoders independently using separate supervised tasks for image and text classification.
- E. Apply adversarial training to make the embeddings indistinguishable between the two modalities.
正解:C
解説:
Contrastive loss functions are specifically designed for learning embeddings where similarity is defined by distance. They directly encourage similar items to be close and dissimilar items to be far apart. Independent training doesn't enforce the multimodal relationship. Reconstruction loss focuses on regenerating the input, not similarity. Adversarial training aims for indistinguishability, not meaningful embeddings. L1 Loss is a basic distance metric but less effective than contrastive losses for learning semantic similarity
質問 # 45
What does mixed-precision training refer to?
- A. Training a model using multiple precision levels, such as using both single-precision and double- precision floating-point numbers.
- B. Training a model using incomplete or missing information from different modalities.
- C. Training a model using different types of data, such as text, images, audio, time series, and geospatial information.
- D. Training a model using diverse data types while addressing challenges related to missing or incomplete information.
正解:A
解説:
Mixed-precision training performs the bulk of computation - matrix multiplications and convolutions - in a lower-precision floating-point format (typically FP16 or BF16 on NVIDIA Tensor Cores) while maintaining a master copy of weights and accumulating certain sensitive operations (like loss scaling and gradient accumulation) in FP32 to preserve numerical stability. The result is substantially faster training throughput and reduced memory footprint, since lower-precision arithmetic runs at higher effective FLOPS on hardware with dedicated Tensor Cores, without a meaningful loss of final model accuracy when combined with techniques like dynamic loss scaling to prevent gradient underflow.
Note that option A's specific mention of "double-precision" (FP64) is not how mixed precision is practiced in modern deep learning - production mixed-precision training combines FP16/BF16 with FP32, not FP64, since FP64 offers no throughput advantage on Tensor Core hardware and is rarely used in training pipelines.
Despite that imprecision in the option's wording, A is still the only choice capturing the correct underlying concept: combining multiple numeric precision levels within one training run. Options B, C, and D all misdescribe mixed precision as a *data-type* or *modality* strategy, confusing numerical precision (a performance/optimization concept) with data modality (a multimodal-data concept) - a distinction the exam tests directly.
Reference: Performance Optimization domain - mixed-precision training, Tensor Cores, loss scaling.
質問 # 46
Consider the following code snippet used for evaluating a Generative Adversarial Network (GAN):
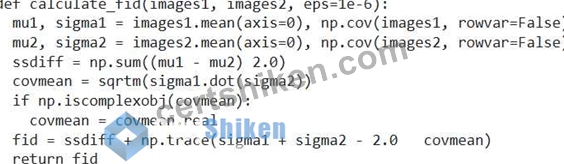
What does the code snippet calculate, and what do 'images1' and "images2 represent in the context of GAN evaluation?
- A. Calculates the Peak Signal-to-Noise Ratio (PSNR); 'images1 and 'images2 represent real and fake images respectively.
- B. Calculates the Structural Similarity Index (SSIM); 'images1 and 'images2 represent real and fake images respectively.
- C. Calculates the Kernel Inception Distance (KID); 'images1' and 'images2 represent real and fake images respectively.
- D. Calculates the Frechet Inception Distance (FID); 'images1' and 'images2 represent real and fake images respectively.
- E. Calculates the Inception Score; 'images1' and 'images2 represent real and fake images respectively.
正解:D
解説:
The code snippet calculates the Frechet Inception Distance (FID). FID measures the distance between the distributions of real and generated images, with lower FID scores indicating better image quality and diversity, and 'images1 represent feature vectors extracted from real and fake images using an Inception network (or a similar feature extractor). The code calculates the mean (mu) and covariance (sigma) of these feature vectors and uses them to compute the FID score. The other options represent different image quality metrics. The Inception Score assesses the quality and diversity of generated images but does not compare them to real images directly.
質問 # 47
When training a multimodal model with both text and image data, what is a common challenge related to the different characteristics and scales of these modalities, and what are some common strategies to address it? (Select TWO correct answers)
- A. Always training the image processing part first and freezing the weights before text processing
- B. Modalities often have different scales and distributions, leading to one modality dominating the learning process.
- C. Text data inherently contains more information than image data, making it difficult to balance their contributions.
- D. Images are always processed faster than text, requiring artificial delays in the text processing pipeline.
- E. Using modality-specific normalization techniques and carefully weighting the loss contributions from each modality.
正解:B、E
解説:
Different modalities often have different scales and distributions, leading to one modality dominating the learning process. To address this, modality-specific normalization techniques (e.g., batch normalization for images and layer normalization for text) and carefully weighting the loss contributions from each modality are often used.
質問 # 48
You are training a multimodal model that combines audio and video dat
a. You observe that the model performs well on the training data but generalizes poorly to unseen data. Which of the following regularization techniques is MOST likely to improve the generalization performance in this scenario?
- A. Dropout
- B. L1 Regularization (Lasso)
- C. Data Augmentation
- D. Early Stopping
- E. Weight Decay (L2 Regularization)
正解:C
解説:
Data augmentation is the most effective regularization technique in this scenario because it increases the diversity of the training data, making the model more robust to variations in unseen data L1 and L2 regularization can help prevent over fitting, but data augmentation directly addresses the issue of limited training data. Dropout also helps, but data augmentation is generally more impactful for multimodal data where variations are significant. Early stopping can also help, but it is not as effective as data augmentation.
質問 # 49
......
この分野には多くの専門家や教授がいます。すべての人々の要求を満たすために、当社のこれらの優秀な専門家および教授は昼夜を問わず働いています。彼らはすべての人々のために当社から最高のNCA-GENM認定トレーニング教材を設計するために最善を尽くしました。学習資料により、すべての人がより効率的な方法でNCA-GENM試験の準備をすることができます。 NCA-GENM学習教材がすべての人々に適し、学生、労働者、主婦などすべての人々の要求を満たすことを保証できます。
NCA-GENM試験対策書: https://www.certshiken.com/NCA-GENM-shiken.html
- 一生懸命にNCA-GENM勉強方法 - 合格スムーズNCA-GENM試験対策書 | 大人気NCA-GENM模擬問題 🥪 ▷ www.passtest.jp ◁から簡単に☀ NCA-GENM ️☀️を無料でダウンロードできますNCA-GENM最新試験情報
- ハイパスレート-有効的なNCA-GENM勉強方法試験-試験の準備方法NCA-GENM試験対策書 🍢 サイト➤ www.goshiken.com ⮘で➽ NCA-GENM 🢪問題集をダウンロードNCA-GENM関連受験参考書
- 試験の準備方法-完璧なNCA-GENM勉強方法試験-素晴らしいNCA-GENM試験対策書 🐗 【 www.it-passports.com 】の無料ダウンロード《 NCA-GENM 》ページが開きますNCA-GENM試験勉強攻略
- 初段のNVIDIA NCA-GENM: NVIDIA Generative AI Multimodal勉強方法 - パススルーGoShiken NCA-GENM試験対策書 ⚽ 時間限定無料で使える✔ NCA-GENM ️✔️の試験問題は「 www.goshiken.com 」サイトで検索NCA-GENM受験トレーリング
- NCA-GENM関連資格知識 🧰 NCA-GENM関連資格知識 🐆 NCA-GENM認定資格試験 🧐 今すぐ[ www.goshiken.com ]で➠ NCA-GENM 🠰を検索して、無料でダウンロードしてくださいNCA-GENM試験復習
- ハイパスレート-有効的なNCA-GENM勉強方法試験-試験の準備方法NCA-GENM試験対策書 ☸ 《 www.goshiken.com 》で☀ NCA-GENM ️☀️を検索して、無料で簡単にダウンロードできますNCA-GENM合格問題
- 素晴らしいNCA-GENM勉強方法一回合格-更新するNCA-GENM試験対策書 🌐 今すぐ▶ www.xhs1991.com ◀で( NCA-GENM )を検索し、無料でダウンロードしてくださいNCA-GENM合格問題
- NVIDIA NCA-GENM勉強方法 は主要材料 - NCA-GENM: NVIDIA Generative AI Multimodal 🐕 ウェブサイト⮆ www.goshiken.com ⮄を開き、➠ NCA-GENM 🠰を検索して無料でダウンロードしてくださいNCA-GENM関連受験参考書
- NVIDIA NCA-GENM勉強方法 は主要材料 - NCA-GENM: NVIDIA Generative AI Multimodal 🏙 { www.passtest.jp }サイトにて[ NCA-GENM ]問題集を無料で使おうNCA-GENM認定資格試験
- 試験の準備方法-権威のあるNCA-GENM勉強方法試験-一番優秀なNCA-GENM試験対策書 🖼 “ www.goshiken.com ”を開いて[ NCA-GENM ]を検索し、試験資料を無料でダウンロードしてくださいNCA-GENM合格率
- 素晴らしいNCA-GENM勉強方法一回合格-更新するNCA-GENM試験対策書 🥈 ➡ NCA-GENM ️⬅️を無料でダウンロード➥ www.passtest.jp 🡄ウェブサイトを入力するだけNCA-GENM最新知識
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, swipy.ru, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, scalar.usc.edu, Disposable vapes
P.S. CertShikenがGoogle Driveで共有している無料かつ新しいNCA-GENMダンプ:https://drive.google.com/open?id=1RmuhrbxfjS5vy7-jBvOs3wBd2HGXq3Wo