Certification DEA-C02 Book Torrent | DEA-C02 Free Test Questions

BONUS!!! Download part of Dumpkiller DEA-C02 dumps for free: https://drive.google.com/open?id=1m5KprpuyNHgb-hvDqhidYhFZZlP_xOZS
If you take a little snack, you will find that young people are now different. They made higher demands on themselves. This is a change in one's own mentality and it is also a requirement of the times! Whether you want it or not, you must start working hard! And our DEA-C02 exam materials may slightly reduce your stress. With our DEA-C02 study braidumps for 20 to 30 hours, we can proudly claim that you can pass the exam easily just as a piece of cake. And as long as you try our DEA-C02 practice questions, you will love it!
| Section | Weight | Objectives |
|---|
| Data Ingestion and Consumption | 20% | - Continuous Data Loading
- 1. Snowpipe configuration and usage
- 2. Real-time data ingestion patterns
- 3. Automating data loading with tasks
- Bulk Loading and Unloading
- 1. COPY INTO command options and best practices
- 2. Data loading performance optimization
- 3. Handling staged files
- 4. File format options (CSV, JSON, Parquet, AVRO)
- Data Unloading
- 1. Unloading to internal and external stages
- 2. Data export best practices
- 3. Partitioning unloading data
|
| Security and Governance | 15% | - Data Security
- 1. External tokenization
- 2. Data masking and tokenization
- 3. Row-level security policies
- 4. Column-level security
- Access Control
- 1. GRANT and REVOKE operations
- 2. Role hierarchy and ownership
- 3. Role-based access control (RBAC)
- Governance and Compliance
- 1. Object tagging
- 2. Access history and auditing
- 3. Data retention policies
- 4. Row access policies
|
| Data Transformation with Snowflake | 30% | - Snowflake Scripting
- 1. Dynamic SQL
- 2. Error handling
- 3. Procedures and control flow
- SQL Transformations
- 1. Complex JOINs and set operations
- 2. Window functions advanced usage
- 3. Working with semi-structured data (VARIANT)
- 4. Data type conversions and handling
- Data Processing Patterns
- 1. MERGE, UPDATE, DELETE operations
- 2. Time travel and change data capture
- 3. Zero-copy cloning for ETL
|
| Performance Optimization | 15% | - Query Optimization
- 1. Query profiling and analysis
- 2. Indexing strategies with clustering
- 3. Query result caching
- 4. Avoiding common performance pitfalls
- Warehouse Performance
- 1. Warehouse scaling policies
- 2. Multi-cluster warehouses
- 3. Resource monitors
- 4. Warehouse sizing and selection
- Data Optimization
- 1. Materialized views
- 2. Search optimization service
- 3. Data cache management
|
| Data Architecture and Processing | 20% | - Data Pipeline Design
- 1. Stream and task patterns
- 2. Data scheduling and orchestration
- 3. Pipeline monitoring and error handling
- Data Modeling for Performance
- 1. Dimension handling
- 2. Slowly changing dimensions (SCD)
- 3. Star and snowflake schemas
- Data Storage Architecture
- 1. Table types (Permanent, Transient, Temporary)
- 2. Micro-partitioning and clustering
- 3. Hybrid Tables concepts
|
>> Certification DEA-C02 Book Torrent <<
DEA-C02 Free Test Questions - DEA-C02 Test Discount Voucher
The DEA-C02 web-based practice questions carry the above-mentioned notable features of the desktop-based software. This version of Dumpkiller's DEA-C02 practice questions works on Mac, Linux, Android, iOS, and Windows. Our customer does not need troubling plugins or software installations to attempt the web-based DEA-C02 Practice Questions. Another benefit is that our DEA-C02 online mock test can be taken via all browsers, including Chrome, MS Edge, Internet Explorer, Safari, Opera, and Firefox.
Snowflake SnowPro Advanced: Data Engineer (DEA-C02) Sample Questions (Q195-Q200):
NEW QUESTION # 195
You have a Snowflake Stream named 'ORDERS STREAM' on an 'ORDERS' table, which is used to incrementally load data into a historical orders table named 'HISTORICAL ORDERS'. The data pipeline involves a series of tasks: 1) Consume changes from the 'ORDERS STREAM', 2) Apply transformations and data quality checks, and 3) Merge the changes into 'HISTORICAL ORDERS' using a MERGE statement. After a recent data load, you notice that the 'HISTORICAL ORDERS' table contains duplicate records for certain 'ORDER values. The MERGE statement uses 'ORDER ID' as the matching key. You have confirmed that the transformation logic is correct and idempotent. Examine the MERGE statement below. What could be causing the duplicates, given the context of Streams and incremental loading?
- A. The MERGE statement is not correctly handling updates and deletes from the stream. The 'WHEN NOT MATCHED' and 'WHEN MATCHED' clauses are not mutually exclusive, leading to potential insertions of duplicate rows.
- B. The 'ORDERS STREAM' is retaining historical data beyond the data retention period, causing older records to be re-processed.
- C. Multiple tasks are concurrently consuming from the same 'ORDERS STREAM' without proper coordination, causing records to be processed multiple times.
- D. The stream is not configured to capture DELETE operations from the ORDERS table, causing records that should have been removed in HISTORICAL ORDERS to remain.
- E. The stream's or 'BEFORE clause is being used incorrectly, potentially rewinding the stream to an earlier point in time.
Answer: C
Explanation:
The most likely cause of duplicate records, given the correct transformation logic and idempotent behavior, is D (Concurrent consumption from the stream) . If multiple tasks or processes are consuming from the same stream without proper coordination , they can both read the same changes and apply them to the 'HISTORICAL ORDERS' table. Option A (Retention Period) would cause data loss , not duplication, because older changes are simply lost. Option B is unlikely if you're not explicitly using or 'BEFORE' and even if you were, a simple stream consumption would advance the offset. If that clause was incorrectly configured, it would still not cause duplicates. Option C is possible but less likely if the transformation logic has been verified. If so many records are malformed that MERGE is broken, more evidence than duplication would be expected. Duplication alone with idempotent transformation suggests consumption error. Option E is a factor that could lead to 'HISTORICAL ORDERS' diverging from 'ORDERS but not a cause duplication.
NEW QUESTION # 196
You are tasked with migrating data from a legacy SQL Server database to Snowflake. One of the tables, 'ORDERS' , contains a column 'ORDER DETAILS that holds concatenated string data representing multiple order items. The data is formatted as 'iteml :qtyl ;item2:qty2;...'. You need to transform this string data into a JSON array of objects, where each object represents an item with 'name' and 'quantity' fields. Which of the following steps and functions would you use in Snowflake to achieve this transformation, in addition to loading the data?
- A. Use to split the string into rows, then use 'SPLIT to separate item name and quantity, and finally use 'OBJECT_CONSTRUCT and to create the JSON array.
- B. Use 'SPLIT with ';' as delimiter, then apply 'SPLIT again with ':' as delimiter. Finally, construct the JSON array using 'ARRAY_AGG' and 'OBJECT CONSTRUCT
- C. Utilize a Java UDF to parse the string and directly generate the JSON array.
- D. Use ' to extract item names and quantities, then use 'ARRAY_CONSTRUCT and 'OBJECT_CONSTRUCT to create the JSON array.
- E. Use ' STRTOK TO ARRAY' to split the string into an array, then iterate through the array using a JavaScript UDF to create the JSON objects.
Answer: A,B
Explanation:
Options A and D correctly outline the process. (A) and multiple 'SPLIT calls (D) are valid approaches to break down the concatenated string. Then, 'OBJECT_CONSTRUCT builds the individual JSON objects, and aggregates them into a JSON array. While Javascript or Java UDFs (C, E) could solve the problem, they are generally less efficient than Snowflake's built-in functions. (B) might work but is overkill for this simple splitting task, also you would still need to combine the extracted arrays for items and quantities.
NEW QUESTION # 197
You are designing a Snowpark Python application to process streaming data from a Kafka topic and land it into a Snowflake table 'STREAMED DATA. Due to the nature of streaming data, you want to achieve the following: 1. Minimize latency between data arrival and data availability in Snowflake. 2. Ensure exactly-once processing semantics to prevent data duplication. 3. Handle potential schema evolution in the Kafka topic without breaking the pipeline. Which combination of Snowpark and Snowflake features, applied with the correct configuration, would BEST satisfy these requirements? Select all that apply.
- A. Utilize Snowflake Streams on in conjunction with Snowpark to transform and cleanse the data after it has been ingested by Snowpipe. Apply a merge statement to update an external table of parquet files.
- B. Implement a Snowpark Python UDF that consumes data directly from the Kafka topic using a Kafka client library. Write data into 'STREAMED_DATX within a single transaction. Use a structured data type for the 'STREAMED DATA'.
- C. Use Snowflake's native Kafka connector to load data into a staging table. Then, use a Task and Stream combination, using a Snowpark Python UDF, to transform and load the data into 'STREAMED DATA' within a single transaction, handling schema evolution by casting columns to their new types or dropping missing column data.
- D. Use Snowpipe with auto-ingest and configure it to trigger on Kafka topic events. Define a VARIANT column in 'STREAMED_DATX to handle schema evolution.
- E. Use Snowflake Connector for Kafka to load data into a staging table. Then, use Snowpark Python to transform and load the data into 'STREAMED_DATR within a single transaction. Implement schema evolution logic in the Snowpark code to handle changes in the Kafka topic schema.
Answer: C,E
Explanation:
Options D and E represent the most reliable solutions to this problem statement. Option D: The combination of the Snowflake Connector for Kafka and Snowpark offers a balanced approach. The connector efficiently loads the raw data, and Snowpark Python provides the flexibility to transform the data within a transaction and implement schema evolution logic. Option E: Snowflake's Kafka connector, combined with tasks, streams, and a Snowpark IJDF, provides a pipeline that continuously transforms data and is only triggered by new events in the staging table created by the Kafka connector. Implementing schema evolution in the IJDF itself handles small changes effectively. Option A does not provide exactly-once semantics. While VARIANT columns handle schema evolution, Snowpipe itself might deliver messages more than once. Option B is less scalable and harder to manage compared to using the Snowflake Connector for Kafka or Streams/Tasks. Option C, using Streams on 'STREAMED_DATA' , can lead to data duplication if not managed correctly and updating an external table negates a central table stream for change control.
NEW QUESTION # 198
You have a Python UDF in Snowflake designed to enrich customer data by calling an external API to retrieve additional information based on the customer ID. Due to API rate limits, you need to implement a mechanism to cache API responses within the UDF to avoid exceeding the limits. The UDF is defined as follows:
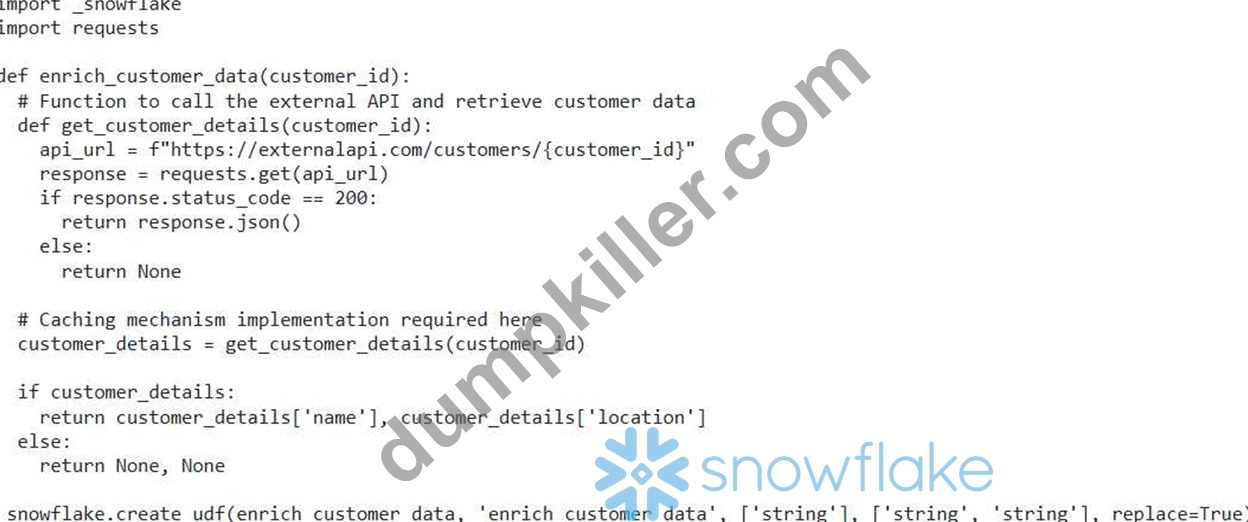
Which caching mechanism can be implemented MOST effectively WITHIN the Python UDF to minimize API calls while adhering to Snowflake's UDF limitations?
- A. Persist the API responses in a temporary table within Snowflake. The UDF will first query the temporary table for the customer ID; if found, return the cached data. Otherwise, call the API and store the response in the temporary table for future use.
- B. Use the 'functools.lru_cache' decorator to cache the results of the 'get_customer details' function within the UDF's scope. This will automatically cache the most recently used API responses.
- C. Utilize Snowflake's built-in caching mechanisms (result caching) by ensuring the UDF is deterministic and only depends on its input parameters. Snowflake will automatically cache the results of the UDF for subsequent calls with the same input.
- D. Leverage external caching services like Redis by making API calls to Redis from the UDF to store and retrieve cached API responses. This would require configuring Snowflake to connect with external systems.
- E. Create a global dictionary within the UDF to store the API responses, using the customer ID as the key. Before calling the API, check if the customer ID exists in the dictionary; if it does, return the cached response. This approach will keep cached values during the session.
Answer: B
Explanation:
Using 'functools.lru_cache' (Option A) is the most efficient and straightforward solution. It provides a built-in caching mechanism within the Python UDF's scope without requiring external dependencies or complex manual caching logic. Option B is not the best, as it will cause issues in multithreaded environment where this is not thread safe and could cause data inconsistency. Option C is related to Snowflake result cache which is independent of UDF cache needs and concerns. The temp table (option D) adds overhead by querying external tables within the UDF, making API execution slower rather than faster. And Option E needs external connections which increase infrastructure complexity.
NEW QUESTION # 199
You are developing a data pipeline in Snowflake that uses SQL UDFs for data transformation. You need to define a UDF that calculates the Haversine distance between two geographical points (latitude and longitude). Performance is critical. Which of the following approaches would result in the most efficient UDF implementation, considering Snowflake's execution model?
- A. Create an External Function (using AWS Lambda or Azure Functions) to calculate the Haversine distance. This allows for offloading the computation to a separate compute environment.
- B. Create a SQL UDF that pre-calculates the RADIANS for latitude and longitude only once and stores them in a temporary table, using those values for subsequent distance calculations within the same session.
- C. Create a Java UDF that calculates the Haversine distance, leveraging optimized mathematical libraries. This allows for potentially faster execution due to lower- level optimizations.
- D. Create a SQL UDF leveraging Snowflake's VECTORIZED keyword, hoping to automatically leverage SIMD instructions, without any code changes to mathematical calculation inside the UDF
- E. Create a SQL UDF that directly calculates the Haversine distance using Snowflake's built-in mathematical functions (SIN, COS, ACOS, RADIANS). This is straightforward and easy to implement.
Answer: E
Explanation:
SQL UDFs are generally the most efficient for simple calculations within Snowflake because they are executed within the Snowflake engine, minimizing data movement and overhead. While Java UDFs (option B) can offer optimizations, the overhead of invoking the Java environment often outweighs the benefits for this type of calculation. External Functions (option C) introduce significant latency due to network communication. Option D provides temporary performance improvements for the specific session, but is not the most efficient general solution. Vectorized keyword doesn't exists in snowflake to create UDFs, Hence it won't allow compilation. This questions emphasis on understanding the trade-offs between different UDF types and their performance implications within the Snowflake architecture.
NEW QUESTION # 200
......
We are popular not only because our outstanding DEA-C02 practice dumps, but also for our well-praised after-sales service. After purchasing our DEA-C02 practice materials, the free updates will be sent to your mailbox for one year long if our experts make any of our DEA-C02 Guide materials. They are also easily understood by exam candidates.Our DEA-C02 actual exam can secedes you from tremendous materials with least time and quickest pace based on your own drive and practice to win.
DEA-C02 Free Test Questions: https://www.dumpkiller.com/DEA-C02_braindumps.html
- New DEA-C02 Exam Simulator 🔖 Reliable DEA-C02 Exam Topics 💋 Valid DEA-C02 Exam Camp 🤿 Easily obtain 《 DEA-C02 》 for free download through ⏩ www.verifieddumps.com ⏪ 🌁Reliable DEA-C02 Exam Topics
- New DEA-C02 Mock Test 🦘 New DEA-C02 Mock Test 🍱 Valid DEA-C02 Exam Simulator Ⓜ ✔ www.pdfvce.com ️✔️ is best website to obtain ▛ DEA-C02 ▟ for free download 🍼Reliable DEA-C02 Exam Topics
- Braindumps DEA-C02 Torrent 😽 Valid DEA-C02 Exam Camp 💽 DEA-C02 Hot Questions 😊 ⮆ www.exam4labs.com ⮄ is best website to obtain ➠ DEA-C02 🠰 for free download 🌇DEA-C02 Real Dumps Free
- SnowPro Advanced: Data Engineer (DEA-C02) exam dumps, DEA-C02 dumps torrent 👌 Open ➡ www.pdfvce.com ️⬅️ enter ☀ DEA-C02 ️☀️ and obtain a free download 🗨DEA-C02 Real Dumps Free
- 2026 100% Free DEA-C02 –Useful 100% Free Certification Book Torrent | DEA-C02 Free Test Questions 🤑 Search for ▶ DEA-C02 ◀ and easily obtain a free download on ✔ www.practicevce.com ️✔️ ⚒DEA-C02 Real Dumps Free
- Valid DEA-C02 Exam Cram 🥇 Reliable DEA-C02 Braindumps Book 🎅 Braindumps DEA-C02 Torrent 📷 Search on “ www.pdfvce.com ” for [ DEA-C02 ] to obtain exam materials for free download 🐰DEA-C02 Download Free Dumps
- Pass-Sure Certification DEA-C02 Book Torrent Spend Your Little Time and Energy to Pass DEA-C02: SnowPro Advanced: Data Engineer (DEA-C02) exam 🥩 ( www.practicevce.com ) is best website to obtain ➽ DEA-C02 🢪 for free download 💼Exam DEA-C02 Simulator Online
- Valid DEA-C02 Exam Camp 🩳 Hot DEA-C02 Spot Questions ☝ DEA-C02 New Study Questions 🤹 Open website ➥ www.pdfvce.com 🡄 and search for ▶ DEA-C02 ◀ for free download 🪔Valid DEA-C02 Exam Simulator
- Brilliantly Updated Snowflake DEA-C02 Exam Dumps 🍼 Copy URL ➥ www.easy4engine.com 🡄 open and search for ➤ DEA-C02 ⮘ to download for free 🎹DEA-C02 Test Practice
- Free PDF Quiz Snowflake - DEA-C02 - Updated Certification SnowPro Advanced: Data Engineer (DEA-C02) Book Torrent 🔹 Search for ⮆ DEA-C02 ⮄ and easily obtain a free download on ➠ www.pdfvce.com 🠰 🤓DEA-C02 Test Dump
- Pass-Sure Certification DEA-C02 Book Torrent Spend Your Little Time and Energy to Pass DEA-C02: SnowPro Advanced: Data Engineer (DEA-C02) exam 🧧 Download ▶ DEA-C02 ◀ for free by simply entering ⮆ www.practicevce.com ⮄ website 🏋Latest DEA-C02 Dumps Sheet
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, wanderlog.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.scener.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
P.S. Free & New DEA-C02 dumps are available on Google Drive shared by Dumpkiller: https://drive.google.com/open?id=1m5KprpuyNHgb-hvDqhidYhFZZlP_xOZS