DOWNLOAD the newest PassTorrent DP-750 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1NaAIbnGKFqRpnuomZk24aPFmxW6OXual
If you are sure that you want to pass Microsoft certification DP-750 exam, then your selecting to purchase the training materials of PassTorrent is very cost-effective. Because this is a small investment in exchange for a great harvest. Using PassTorrent's test questions and exercises can ensure you pass Microsoft Certification DP-750 Exam. PassTorrent is a website which have very high reputation and specifically provide simulation questions, practice questions and answers for IT professionals to participate in the Microsoft certification DP-750 exam.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Deploy and manage data pipelines and workloads | 30-35% | - Operational reliability
|
| Topic 2: Secure and govern data using Unity Catalog | 15-20% | - Access control and policies
|
| Topic 3: Prepare and process data | 30-35% | - Data quality and validation
|
| Topic 4: Configure and manage Azure Databricks environments | 15-20% | - Security and authentication setup
|
>> Microsoft DP-750 Valid Braindumps Sheet <<
By concluding quintessential points into Implementing Data Engineering Solutions Using Azure Databricks practice materials, you can pass the exam with the least time while huge progress. Our experts are responsible to make in-depth research on the exams who contribute to growth of our DP-750 practice materials. Their highly accurate exam point can help you detect flaws on the review process and trigger your enthusiasm about the exam. What is more, DP-750 practice materials can fuel your speed and the professional backup can relieve you of stress of the challenge.
NEW QUESTION # 68
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named Catalog1. Catalog1 contains a schema named Schema1 and a table named Table1.
You need to ensure that access to the data in Table1 is controlled by using attribute-based access control (ABAC).
What should you apply to Table1, and how should you control access for users? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
NEW QUESTION # 69
Which component enforces table-level permissions in Databricks?
Answer: C
Explanation:
Unity Catalog provides fine-grained access control at table, schema, and column levels. It centralizes governance across workspaces. Cluster policies control compute settings. Spark configuration does not manage security. DBFS permissions are not sufficient for enterprise governance.
NEW QUESTION # 70
Which SCD type should you use to support the planned data modeling changes? To answer, drag the appropriate types to the correct issues. Each type may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Answer:
Explanation: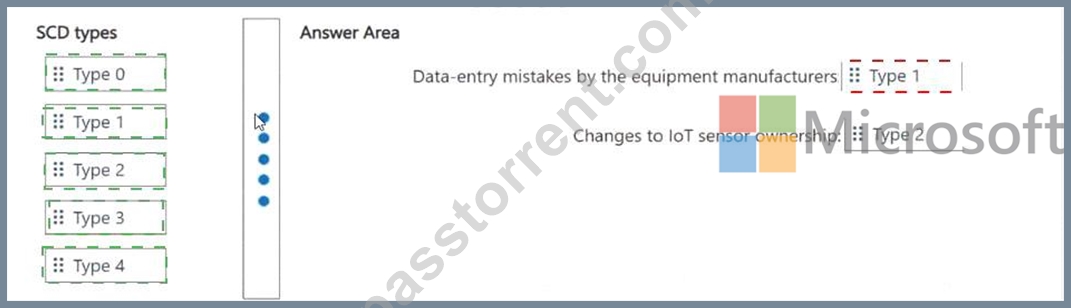
Explanation:
The correct mapping is SCD Type 1 for equipment metadata and SCD Type 2 for IoT sensor ownership history.
SCD Type 1 overwrites the existing record whenever an attribute changes - no history is kept. Contoso's requirement for equipment metadata (name, manufacturer, model, commissioning date) states 'historical values are NOT required,' which is the textbook definition of Type 1. A MERGE INTO with WHEN MATCHED THEN UPDATE handles this cleanly in Delta Lake.
SCD Type 2 creates a new row for each change, preserving the full history through effective-date or version columns. Contoso requires that 'analysts must track the full history of ownership' as sensors change hands over time - that full audit trail is only possible with Type 2. Type 3 (keeping just the previous value in an extra column) would lose earlier ownership records, so it doesn't satisfy the 'full history' requirement.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/merge
NEW QUESTION # 71
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job! contains three tasks named Task1, Task2. and Task3.
If Task1 fails, Task2 and Task3 must be prevented from running. Successfully completed tasks must NOT rerun during recovery.
You need to configure Job1 to support controlled failure handling and recovery What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.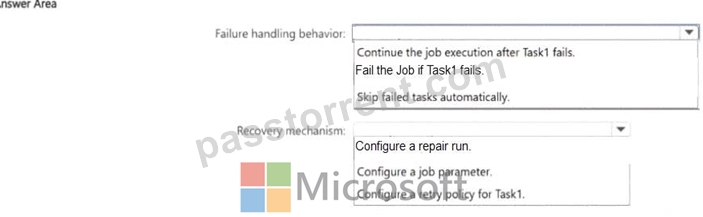
Answer:
Explanation: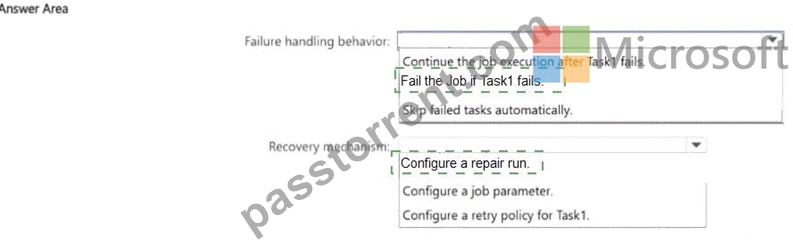
Explanation:
Two configurations are needed:
Task dependency with 'All succeeded' run condition: Set Task2 and Task3 to depend on Task1. Change the run condition on Task2 and Task3 to 'All succeeded' - this means they only execute when all their upstream dependencies (Task1) have succeeded. If Task1 fails, both downstream tasks are skipped automatically, not run with failed inputs.
Repair run for recovery: Lakeflow Jobs' Repair Run feature lets you re-execute only the tasks that failed (Task1 in this case) and their dependents (Task2 and Task3 if they were skipped), while skipping Task1 and any other tasks that already completed successfully. Successfully completed tasks are never re-executed during repair - their results are reused as-is.
Together these provide both controlled failure propagation (nothing runs downstream of a failure) and efficient recovery.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/repair-job-failures
NEW QUESTION # 72
You have an Azure Databricks workspace.
Users report that a Databricks notebook that runs each day takes longer than expected to run.
When reading the Directed Acyclic Graph (DAG), you discover the following issues concerning the Apache Spark stage:
* Most tasks in the stage finish quickly.
* A few tasks in the stage run more slowly.
* The CPU is underutilized at the end of the stage.
* The slow tasks process many more input records.
* The stage is blocked while it waits for the few slow tasks.
What is the root cause of the issues?
Answer: A
Explanation:
The symptoms indicate data skew. Spark partitions the stage's work into tasks, but a few partitions contain substantially more records than the others. Tasks processing the smaller partitions finish quickly, leaving the cluster underutilized while the stage waits for the oversized partitions. Caching would concern whether reused data is stored in memory and does not inherently explain an uneven distribution of input records. Shuffling transfers data between executors and can be expensive, but the decisive evidence is that only a few tasks process far more records. Spilling occurs when an executor cannot keep intermediate data in memory and writes it to disk; the scenario does not identify high spill volumes. Examining per-task input sizes in the Spark UI would confirm the skewed partition distribution.
NEW QUESTION # 73
......
Microsoft DP-750 exam dumps are important because they show you where you stand. After learning everything related to the Implementing Data Engineering Solutions Using Azure Databricks (DP-750)certification, it is the right time to take a self-test and check whether you can clear the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) certification exam or not. People who score well on the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) practice questions are ready to give the final Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam.
Practice DP-750 Test Online: https://www.passtorrent.com/DP-750-latest-torrent.html
DOWNLOAD the newest PassTorrent DP-750 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1NaAIbnGKFqRpnuomZk24aPFmxW6OXual