To go with the changing neighborhood, we need to improve our efficiency of solving problems, which reflects in many aspect as well as dealing with Databricks-Certified-Professional-Data-Engineer exams. Our Databricks-Certified-Professional-Data-Engineer practice materials can help you realize it. To those time-sensitive exam candidates, our high-efficient Databricks-Certified-Professional-Data-Engineer Actual Tests comprised of important news will be best help. Only by practicing them on a regular base, you will see clear progress happened on you. You can download Databricks-Certified-Professional-Data-Engineer exam questions immediately after paying for it, so just begin your journey toward success now
| Section | Weight | Objectives |
|---|---|---|
| Data Transformation, Cleansing, and Quality | 10% | - Handling missing or inconsistent data - Data validation and quality checks - Standardization and normalization |
| Debugging and Deploying | 10% | - CI/CD and DevOps practices - Deployment using bundles, CLI, and APIs - Troubleshooting pipelines and errors |
| Ensuring Data Security and Compliance | 10% | - Data encryption and masking - Access control and permissions - Compliance standards implementation |
| Data Governance | 7% | - Unity Catalog management - Data lineage and metadata tracking - Policy enforcement |
| Developing Code for Data Processing using Python and SQL | 22% | - Batch and incremental processing logic - Data transformation and aggregation - Integration with Databricks APIs and tools |
| Data Sharing and Federation | 5% | - Cross-workspace and cross-cloud access - Unity Catalog data sharing |
| Cost & Performance Optimisation | 13% | - Query optimization and caching - Cluster configuration and scaling - Storage optimization (partitioning, Z-order, indexing) |
| Monitoring and Alerting | 10% | - Setting up alerts and notifications - Pipeline observability and logging - Performance and health monitoring |
| Data Modelling | 6% | - Medallion Architecture implementation - Delta Lake table design - Schema design and management |
| Data Ingestion & Acquisition | 7% | - Auto Loader and streaming ingestion - Schema inference and evolution - Connecting to diverse data sources |
>> New Databricks-Certified-Professional-Data-Engineer Exam Pattern <<
Our products are officially certified, and Databricks-Certified-Professional-Data-Engineer exam materials are definitely the most authoritative product in the industry. In order to ensure the authority of our Databricks-Certified-Professional-Data-Engineer practice prep, our company has really taken many measures. First of all, we have a professional team of experts, each of whom has extensive experience. Secondly, before we write Databricks-Certified-Professional-Data-Engineer Guide quiz, we collect a large amount of information and we will never miss any information points.
NEW QUESTION # 144
A data engineer wants to reflector the following DLT code, which includes multiple definition with very similar code: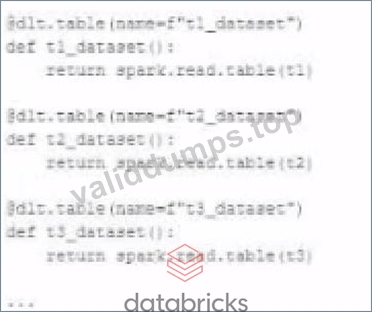
In an attempt to programmatically create these tables using a parameterized table definition, the data engineer writes the following code.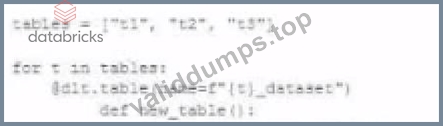
The pipeline runs an update with this refactored code, but generates a different DAG showing incorrect configuration values for tables.
How can the data engineer fix this?
Answer: D
Explanation:
The issue with the refactored code is that it tries to use string interpolation to dynamically create table names within the dlc.table decorator, which will not correctly interpret the table names. Instead, by using a dictionary with table names as keys and their configurations as values, the data engineer can iterate over the dictionary items and use the keys (table names) to properly configure the table settings. This way, the decorator can correctly recognize each table name, and the corresponding configuration settings can be applied appropriately.
NEW QUESTION # 145
Which of the following tool provides Data Access control, Access Audit, Data Lineage, and Data discovery?
Answer: B
NEW QUESTION # 146
A data engineer manages a production Lakeflow Declarative Pipeline that processes customer transaction data. The pipeline includes several data quality expectations such as transaction_amount > 0 and customer_id IS NOT NULL. These expectations are defined using the EXPECT clause in SQL.
The engineer aims to monitor the pipeline's data quality by analyzing the number of records that passed or failed each expectation during the latest pipeline update. The Lakeflow Declarative Pipelines event logs are stored in a Delta table named event_log_table.
For the most recent pipeline update, determine a programmatically appropriate approach to extract information like the name of each expectation, associated dataset, count of records that passed the expectation, and count of records that failed the expectation.
Which method retrieves the desired data quality metrics from the Lakeflow Declarative Pipelines event log?
Answer: B
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
The Databricks documentation specifies that for Lakeflow Declarative Pipelines, detailed data quality metrics are logged as events of type expectation_result within the event log. Each record of this type contains fields including expectation_name, dataset_name, passed_records, and failed_records. Filtering on event_type = 'expectation_result' and expanding the details field allows retrieving metrics for each expectation from the most recent pipeline update. While flow_progress provides summary statistics and data_quality events aggregate results, only expectation_result events provide granular, per-expectation metrics required for audit and monitoring automation.
NEW QUESTION # 147
A data governance team at a large enterprise is improving data discoverability across its organization. The team has hundreds of tables in their Databricks Lakehouse with thousands of columns that lack proper documentation. Many of these tables were created by different teams over several years, with missing context about column meanings and business logic. The data governance team needs to quickly generate comprehensive column descriptions for all existing tables to meet compliance requirements and improve data literacy across the organization. They want to leverage modern capabilities to automatically generate meaningful descriptions rather than manually documenting each column, which would take months to complete.
Which approach should the team use in Databricks to automatically generate column comments and descriptions for existing tables?
Answer: D
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
Databricks Catalog Explorer provides a feature called AI Generate that automatically produces intelligent comments for columns. This feature uses metadata such as column names, types, patterns, and sampled values to generate human-readable documentation. According to the documentation, this is the recommended method to rapidly enrich schema metadata and improve data discoverability, especially at enterprise scale. Unlike DESCRIBE HISTORY or DESCRIBE TABLE, which only surface technical schema details, AI Generate directly produces business-oriented descriptions. PySpark statistical functions (df.describe) only return numeric statistics and cannot generate descriptive metadata. Thus, AI Generate in Catalog Explorer is the correct approach.
NEW QUESTION # 148
A data architect is designing a Databricks solution to efficiently process data for different business requirements.
In which scenario should a data engineer use a materialized view compared to a streaming table ?
Answer: A
Explanation:
Materialized views in Databricks are optimized for precomputing and caching results of complex SQL queries, joins, and aggregations. They store query outputs physically and automatically refresh on a schedule or incremental change basis, drastically improving BI dashboard performance and reducing compute costs.
Conversely, streaming tables are designed for real-time data ingestion and processing , enabling event- driven analytics and low-latency use cases.
Databricks documentation explicitly recommends materialized views for analytical workloads with periodic updates and streaming tables for continuously updating sources. Therefore, the correct choice is C , where complex aggregations from large tables benefit most from materialized precomputation for fast reporting.
NEW QUESTION # 149
......
In order to pass Databricks certification Databricks-Certified-Professional-Data-Engineer exam, selecting the appropriate training tools is very necessary. And professional study materials about Databricks certification Databricks-Certified-Professional-Data-Engineer exam is a very important part. Our ValidDumps can have a good and quick provide of professional study materials about Databricks Certification Databricks-Certified-Professional-Data-Engineer Exam. Our ValidDumps IT experts are very experienced and their study materials are very close to the actual exam questions, almost the same. ValidDumps is a convenient website specifically for people who want to take the certification exams, which can effectively help the candidates to pass the exam.
Databricks-Certified-Professional-Data-Engineer Valid Test Materials: https://www.validdumps.top/Databricks-Certified-Professional-Data-Engineer-exam-torrent.html