BONUS!!! Download part of TestkingPDF DP-100 dumps for free: https://drive.google.com/open?id=1dB5ySJUswJwNve10apPy8ECAZAh3nxOI
You can find yourself sitting in your dream office and enjoying the new opportunity. So, don't wait, get the Microsoft DP-100 certification by preparing through TestkingPDF Microsoft DP-100 exam questions that will help you crack the Microsoft DP-100 Exam. TestkingPDF will provide you with all the Microsoft DP-100 exam dumps, practice exams, and other necessary documentation that will help you understand the Microsoft DP-100 exam questions and pass the Microsoft DP-100 exam.
| Section | Weight | Objectives |
|---|---|---|
| Explore data and run experiments | 20-25% | - Explore and visualize data
|
| Train and deploy models | 25-30% | - Manage models
|
| Optimize language models for AI applications | 25-30% | - Optimize with Retrieval Augmented Generation
|
| Design and prepare a machine learning solution | 20-25% | - Design a machine learning solution
|
>> Download DP-100 Free Dumps <<
Microsoft DP-100 certification exams are a great way to analyze and evaluate the skills of a candidate effectively. Big companies are always on the lookout for capable candidates. You need to pass the Microsoft DP-100 Certification Exam to become a certified professional. This task is considerably tough for unprepared candidates however with the right DP-100 prep material there remains no chance of failure.
NEW QUESTION # 438
You have an Azure Machine Learning workspace that contains a training cluster and an inference cluster.
You plan to create a classification model by using the Azure Machine Learning designer.
You need to ensure that client applications can submit data as HTTP requests and receive predictions as responses.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.
Answer:
Explanation:
1 - Create a pipeline that trains a classification model and run...
2 - Create a batch inference pipeline and run the pipeline on the compute cluster.
3 - Deploy a service to the inference cluster.
NEW QUESTION # 439
You are implementing hyperparameter tuning for a model training from a notebook. The notebook is in an Azure Machine Learning workspace. You add code that imports all relevant Python libraries.
You must configure Bayesian sampling over the search space for the num_hidden_layers and batch_size hyperparameters.
You need to complete the following Python code to configure Bayesian sampling.
Which code segments should you use? To answer, select the appropriate options in the answer area NOTE: Each correct selection is worth one point.
Answer:
Explanation: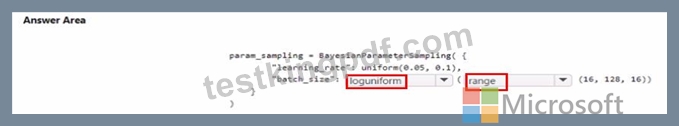
NEW QUESTION # 440
Hotspot Question
You create an Azure Machine Learning dataset. You use the Azure Machine Learning designer to transform the dataset by using an Execute Python Script component and custom code.
You must upload the script and associated libraries as a script bundle.
You need to configure the Execute Python Script component.
Which configurations should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
https://learn.microsoft.com/en-us/azure/machine-learning/component-reference/execute-python- script?view=azureml-api-2
NEW QUESTION # 441
You need to implement a new cost factor scenario for the ad response models as illustrated in the performance curve exhibit.
Which technique should you use?
Answer: D
Explanation:
Scenario:
Performance curves of current and proposed cost factor scenarios are shown in the following diagram:
The ad propensity model uses a cut threshold is 0.45 and retrains occur if weighted Kappa deviated from 0.1
+/- 5%.
Develop models
Testlet 2
Case study
Overview
You are a data scientist for Fabrikam Residences, a company specializing in quality private and commercial property in the United States. Fabrikam Residences is considering expanding into Europe and has asked you to investigate prices for private residences in major European cities. You use Azure Machine Learning Studio to measure the median value of properties. You produce a regression model to predict property prices by using the Linear Regression and Bayesian Linear Regression modules.
Datasets
There are two datasets in CSV format that contain property details for two cities, London and Paris, with the following columns:
The two datasets have been added to Azure Machine Learning Studio as separate datasets and included as the starting point of the experiment.
Dataset issues
The AccessibilityToHighway column in both datasets contains missing values. The missing data must be replaced with new data so that it is modeled conditionally using the other variables in the data before filling in the missing values.
Columns in each dataset contain missing and null values. The dataset also contain many outliers. The Age column has a high proportion of outliers. You need to remove the rows that have outliers in the Age column.
The MedianValue and AvgRoomsinHouse columns both hold data in numeric format. You need to select a feature selection algorithm to analyze the relationship between the two columns in more detail.
Model fit
The model shows signs of overfitting. You need to produce a more refined regression model that reduces the overfitting.
Experiment requirements
You must set up the experiment to cross-validate the Linear Regression and Bayesian Linear Regression modules to evaluate performance.
In each case, the predictor of the dataset is the column named MedianValue. An initial investigation showed that the datasets are identical in structure apart from the MedianValue column. The smaller Paris dataset contains the MedianValue in text format, whereas the larger London dataset contains the MedianValue in numerical format. You must ensure that the datatype of the MedianValue column of the Paris dataset matches the structure of the London dataset.
You must prioritize the columns of data for predicting the outcome. You must use non-parameters statistics to measure the relationships.
You must use a feature selection algorithm to analyze the relationship between the MedianValue and AvgRoomsinHouse columns.
Model training
Given a trained model and a test dataset, you need to compute the permutation feature importance scores of feature variables. You need to set up the Permutation Feature Importance module to select the correct metric to investigate the model's accuracy and replicate the findings.
You want to configure hyperparameters in the model learning process to speed the learning phase by using hyperparameters. In addition, this configuration should cancel the lowest performing runs at each evaluation interval, thereby directing effort and resources towards models that are more likely to be successful.
You are concerned that the model might not efficiently use compute resources in hyperparameter tuning. You also are concerned that the model might prevent an increase in the overall tuning time. Therefore, you need to implement an early stopping criterion on models that provides savings without terminating promising jobs.
Testing
You must produce multiple partitions of a dataset based on sampling using the Partition and Sample module in Azure Machine Learning Studio. You must create three equal partitions for cross-validation. You must also configure the cross-validation process so that the rows in the test and training datasets are divided evenly by properties that are near each city's main river. The data that identifies that a property is near a river is held in the column named NextToRiver. You want to complete this task before the data goes through the sampling process.
When you train a Linear Regression module using a property dataset that shows data for property prices for a large city, you need to determine the best features to use in a model. You can choose standard metrics provided to measure performance before and after the feature importance process completes. You must ensure that the distribution of the features across multiple training models is consistent.
Data visualization
You need to provide the test results to the Fabrikam Residences team. You create data visualizations to aid in presenting the results.
You must produce a Receiver Operating Characteristic (ROC) curve to conduct a diagnostic test evaluation of the model. You need to select appropriate methods for producing the ROC curve in Azure Machine Learning Studio to compare the Two-Class Decision Forest and the Two-Class Decision Jungle modules with one another.
Develop models
Question Set 3
NEW QUESTION # 442
You need to define a process for penalty event detection.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.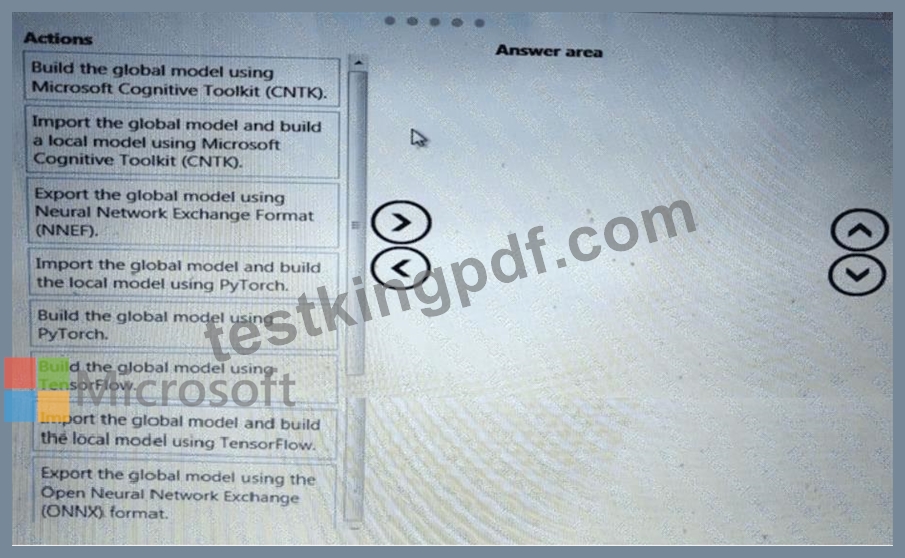
Answer:
Explanation:
NEW QUESTION # 443
......
DP-100 study materials are the product for global users. Standards in all aspects are also required by international standards. The system designed of DP-100 learning guide by our IT engineers is absolutely safe. Your personal information will never be revealed. And DP-100 actual exam will certainly not covet this small profit and sell your information. DP-100 Study Materials can come today. With so many loyal users, our good reputation is not for nothing. In us, you don't have to worry about information leakage. Selecting a brand like DP-100 learning guide is really the most secure.
Reliable DP-100 Test Questions: https://www.testkingpdf.com/DP-100-testking-pdf-torrent.html
P.S. Free & New DP-100 dumps are available on Google Drive shared by TestkingPDF: https://drive.google.com/open?id=1dB5ySJUswJwNve10apPy8ECAZAh3nxOI