Most experts agree that the best time to ask for more dough is after you feel your CCAR-P performance has really stood out. Our CCAR-P guide materials provide such a learning system where you can improve your study efficiency to a great extent. During the process of using our CCAR-P Study Materials, you focus yourself on the exam bank within the given time, and we will refer to the real exam time to set your CCAR-P practice time, which will make you feel the actual CCAR-P exam environment and build up confidence.
| Section | Weight | Objectives |
|---|---|---|
| Solution Design & Architecture | 17% | - Align solutions to business value pillars - Select architectural patterns: workflow, agentic, augmented LLM - Design multi-agent systems and orchestration strategies - Translate business problems into Claude-based AI solutions - Design end-to-end architectures and feedback loops |
| Governance, Safety & Risk Management | 14% | - Implement guardrails and safety controls - Manage data privacy and security compliance - Address ethical AI considerations and bias mitigation - Ensure regulatory compliance (GDPR, HIPAA, etc.) |
| Developer Productivity & Operational Enablement | 7% | - Configure Claude tools and environments for teams - Support debugging, monitoring, and operational resolution - Improve developer workflows with AI-assisted tooling |
| Evaluation, Testing & Optimization | 16% | - Implement iterative improvement pipelines - Test accuracy, reliability, latency, and cost - Define evaluation metrics and success criteria - Optimize performance, prompting, and model selection |
| Stakeholder Communication & Lifecycle Management | 14% | - Document architectures and support full lifecycle phases - Conduct structured discovery and requirement gathering - Communicate architectural decisions and trade-offs - Manage stakeholder feedback and expectation alignment |
| Claude Models, Prompting & Context Engineering | 13% | - Select appropriate Claude models based on trade-offs - Apply context engineering and context management techniques - Mitigate prompt injection, leaks, and jailbreak risks - Design system prompts, templates, and guardrails |
| Integration | 19% | - Integrate Claude with enterprise systems, APIs, and tools - Design authentication, authorization, and observability - Integrate with data pipelines and RAG systems - Implement Model Context Protocol (MCP) integrations |
For candidates who preparing for the exam, knowing the latest information for the exam is quite necessary. CCAR-P exam cram of us can offer free update for 365 days for you, and we have skilled professionals examine the update every day, once we have the update version, we will send you the first time. CCAR-P training materials is not only high-quality, but also contain certain quantity, therefore they will be enough for you to pass the exam. We have a professional service team, and the service staffs have professional knowledge for CCAR-P Exam Materials, if you have any questions, you can consult us.
NEW QUESTION # 85
You are a solution architect evaluating candidate use cases for a Claude-based program.
For each scenario, select Yes if Claude is appropriate as the primary solution at the architectural level.
Otherwise, select No.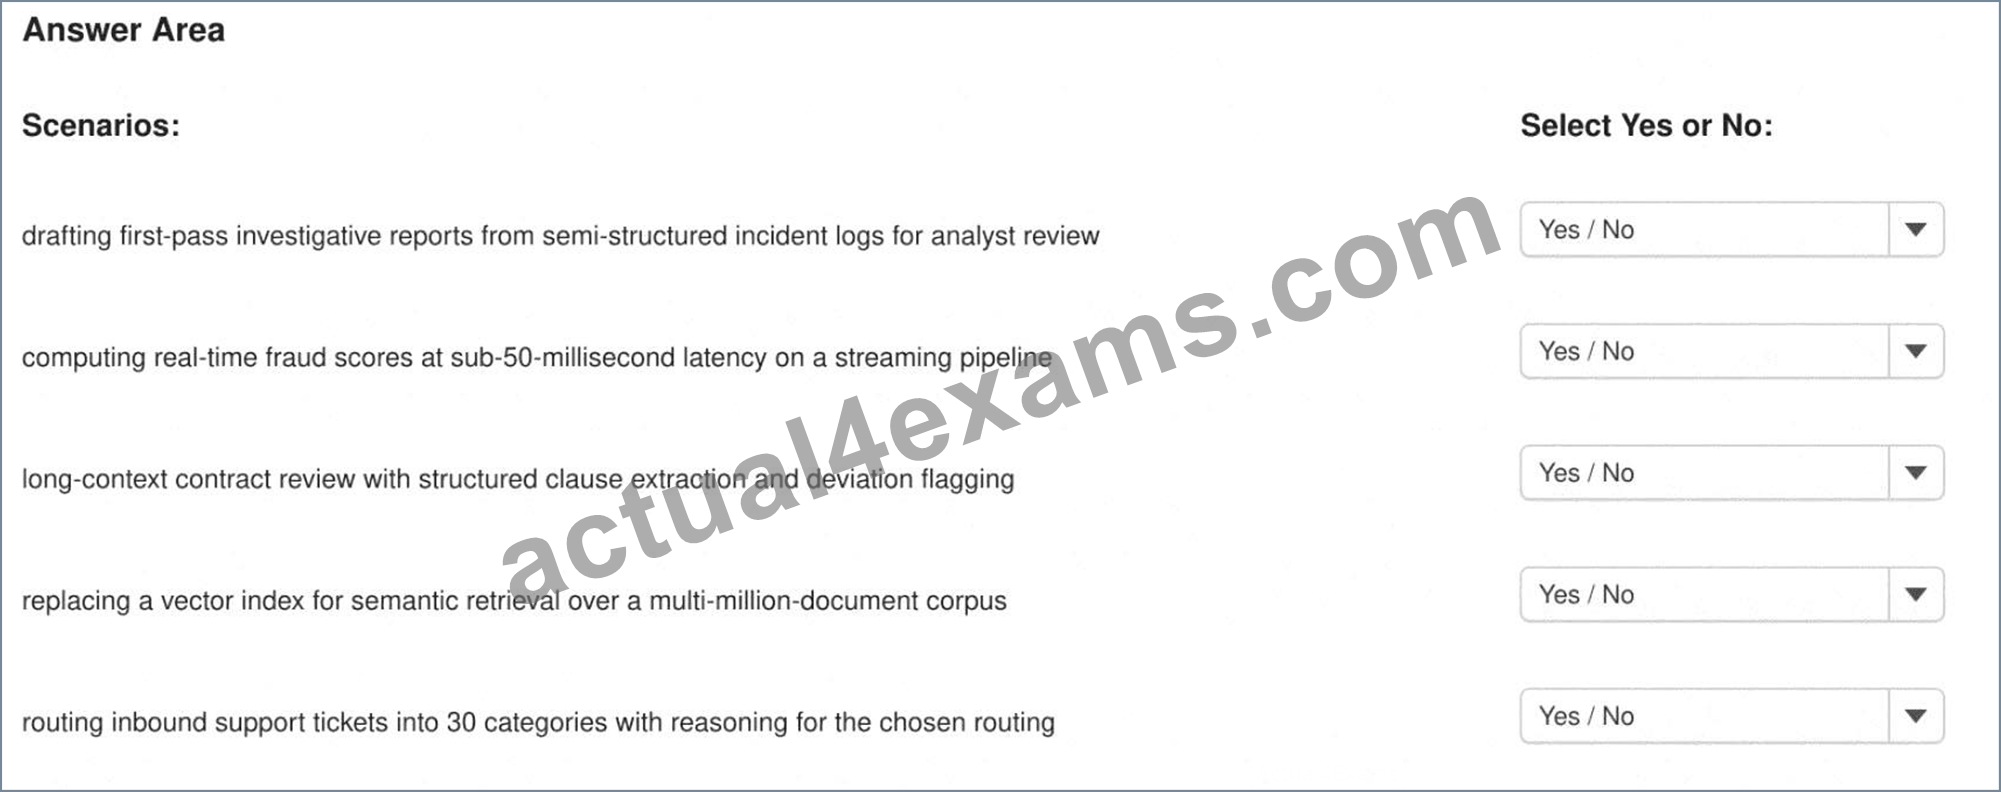
Answer:
Explanation: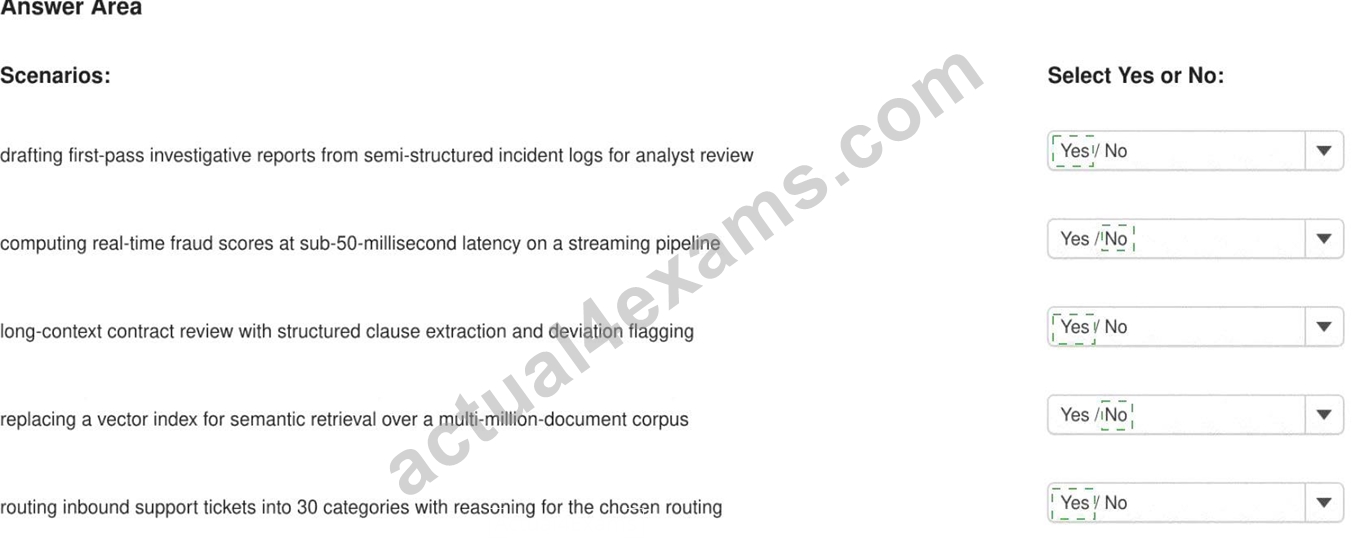
Explanation:
* Drafting first-pass investigative reports from semi-structured incident logs for analyst review - Yes
* Computing real-time fraud scores at sub-50-millisecond latency on a streaming pipeline - No
* Long-context contract review with structured clause extraction and deviation flagging - Yes
* Replacing a vector index for semantic retrieval over a multi-million-document corpus - No
* Routing inbound support tickets into 30 categories with reasoning for the selected route - Yes Claude is well suited to language-intensive analysis, summarization, extraction, classification, and drafting.
Investigative-report drafting, contract analysis, and support-ticket routing all require interpretation of unstructured or semi-structured language and can incorporate human review. A sub-50-millisecond fraud- scoring path requires deterministic, specialized real-time processing and should not place LLM inference on the critical path. Claude also does not replace the retrieval index used to search millions of documents; it consumes the results produced by that infrastructure. The correct architectural decision separates tasks requiring semantic language reasoning from deterministic computation and information-retrieval infrastructure. Model selection and evaluation must then confirm that the chosen Claude model satisfies quality, latency, and cost requirements.
NEW QUESTION # 86
You are reviewing a peer's draft architecture decision record (ADR). The ADR states the decision and the technical detail but does not state the alternatives considered or the trade-offs accepted.
Which response is most appropriate?
Answer: B
Explanation:
An ADR must preserve not only the selected decision but also the context, alternatives evaluated, and trade- offs consciously accepted. Without this information, future engineers cannot determine whether the decision remains valid after requirements, Claude models, costs, security controls, or integration capabilities change.
Option B completes the record while retaining the valid technical detail already documented. Option A destroys useful evidence and replaces durable documentation with unreliable organizational memory. Option C produces an incomplete record that cannot support audits, onboarding, or later architectural review. Option D changes the decision without evidence or a decision-making process. For Claude solutions, ADRs should typically capture the chosen model and integration pattern, rejected alternatives, evaluation evidence, security implications, operational consequences, and conditions that would trigger reconsideration.
NEW QUESTION # 87
You are classifying chunking strategies by the corpus type each is best suited to.
For each chunking strategy, select the appropriate corpus type: "Long Structured Documents,"
"Heterogeneous Short Records," or "Code or Hierarchical Specifications."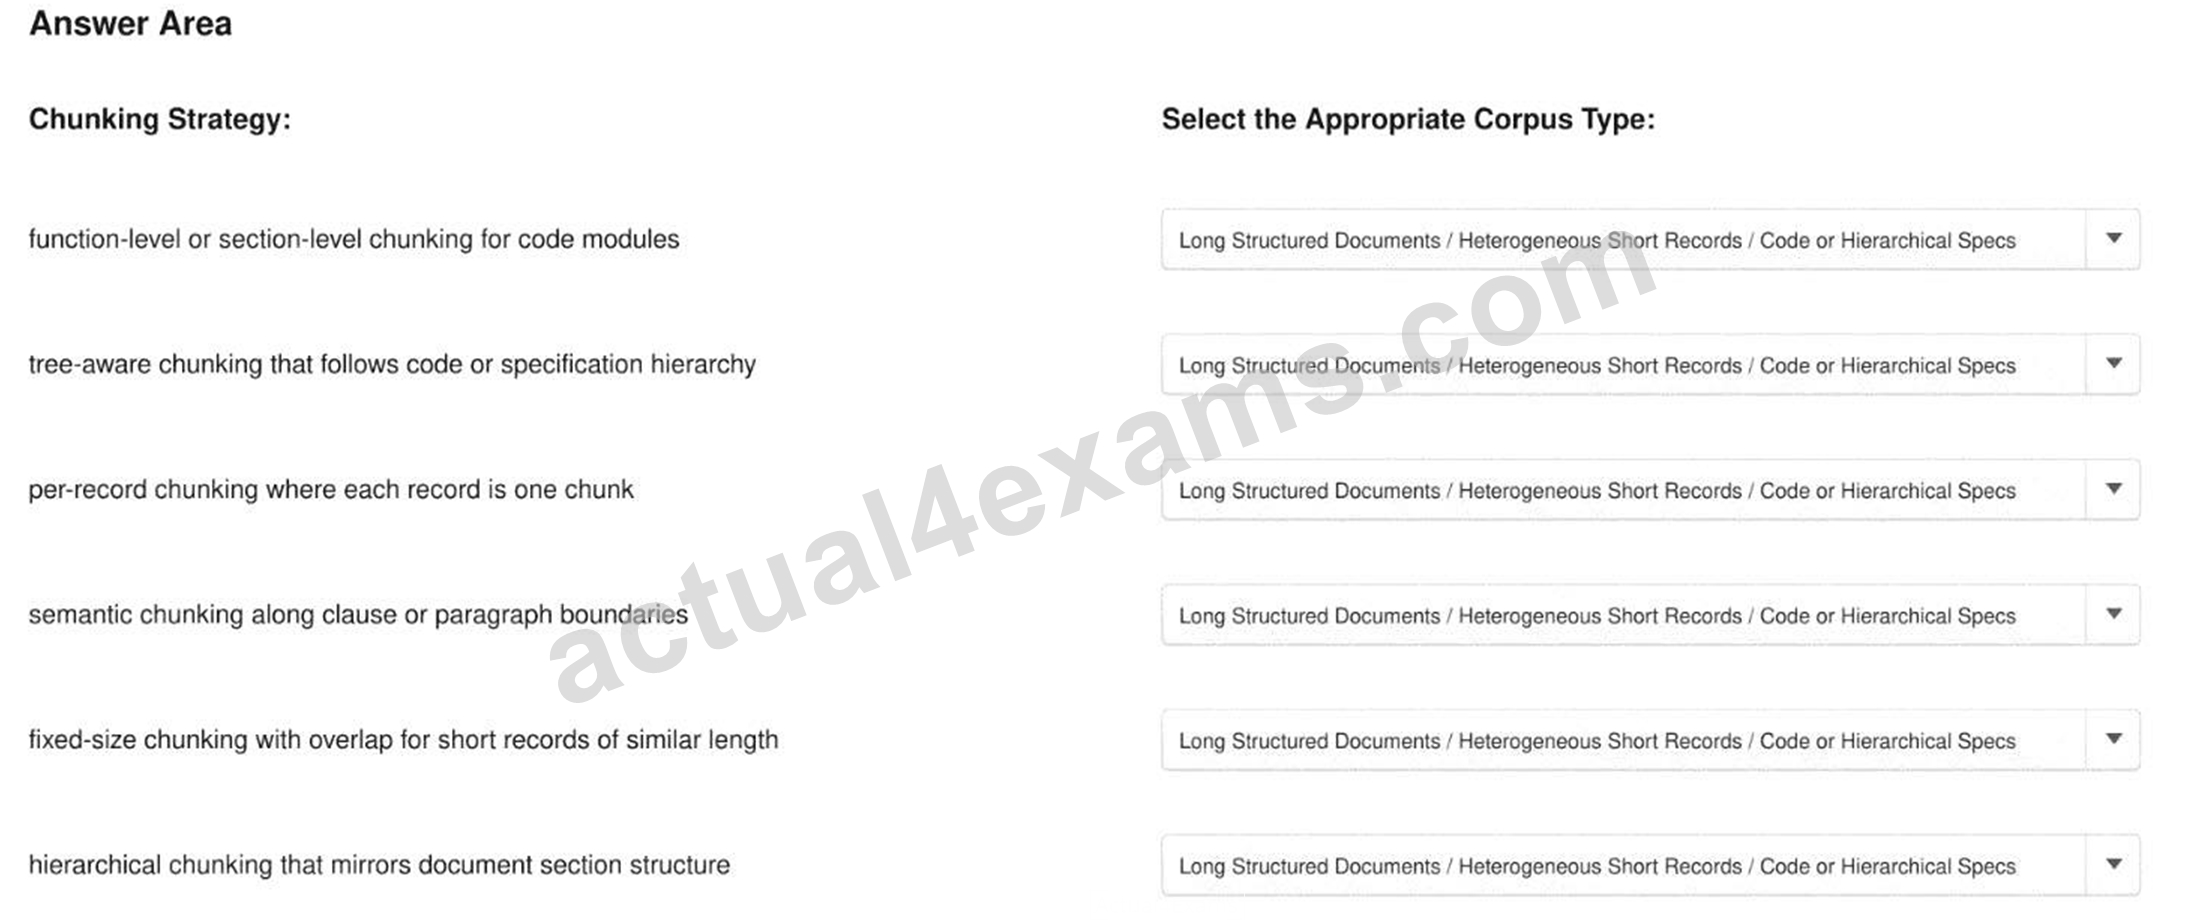
Answer:
Explanation: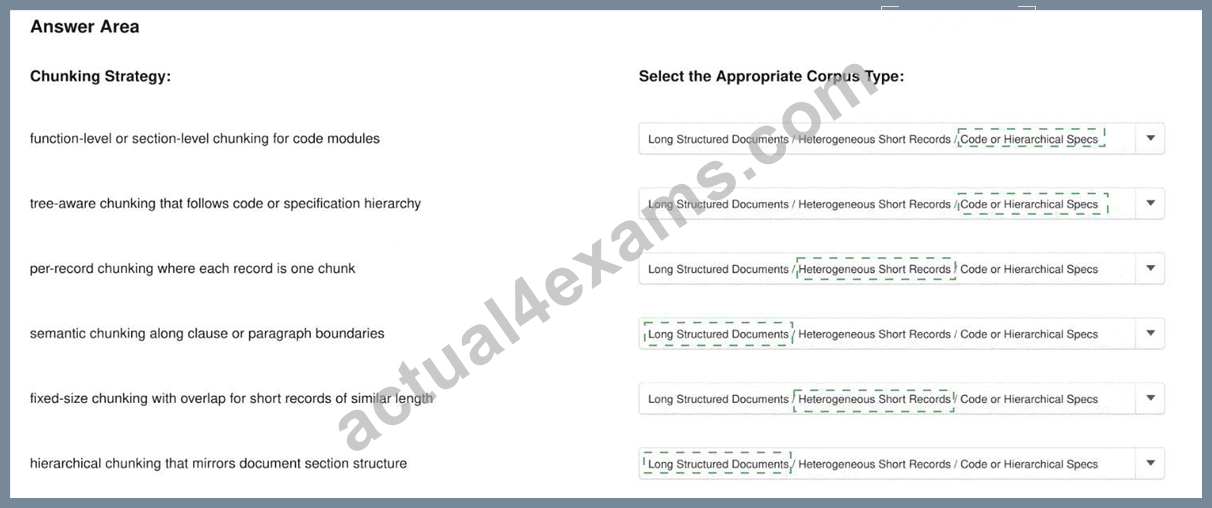
Explanation:
* Function-level or section-level chunking for code modules - Code or Hierarchical Specifications
* Tree-aware chunking that follows code or specification hierarchy - Code or Hierarchical Specifications
* Per-record chunking where each record is one chunk - Heterogeneous Short Records
* Semantic chunking along clause or paragraph boundaries - Long Structured Documents
* Fixed-size chunking with overlap for short records of similar length - Heterogeneous Short Records
* Hierarchical chunking that mirrors document section structure - Long Structured Documents Chunking must preserve the structural unit that carries meaning in the source corpus. Code and hierarchical specifications are best divided at function, module, class, or tree boundaries because arbitrary token cuts can separate definitions from their implementation or parent context. Heterogeneous short-record collections should generally preserve each record as an independent chunk. Fixed-size overlapping chunks are also effective when records have broadly similar lengths and lack meaningful internal hierarchy. Long structured documents benefit from semantic boundaries such as clauses and paragraphs, while hierarchical chunking preserves relationships among sections, subsections, and parent headings. Anthropic notes that chunk size, boundaries, and overlap materially affect retrieval performance; therefore, one universal chunking method is inappropriate. Anthropic Contextual Retrieval
NEW QUESTION # 88
You are integrating Claude Code into a workflow that runs against a production database.
Which guardrail design most directly preserves safety on data-modifying operations?
Answer: B
Explanation:
Option D applies three complementary controls. First, a read-only database credential creates an authorization boundary outside the model; prompt instructions alone cannot convert that credential into write access.
Second, restricting the subagent's tool list reduces capability exposure by preventing the agent from selecting unrelated or unnecessarily privileged operations. Third, explicit human confirmation creates a deliberate approval gate before any exceptional data-changing action is executed.
This is defense in depth. If Claude misinterprets a request or processes malicious instructions from untrusted content, the restricted credential and tool configuration limit the available action surface. Human review then protects operations with potentially irreversible production consequences. Logging and audit trails should remain enabled to record the actor, request, tool call, approval, affected records, and outcome.
Anthropic documents that Claude Code begins with read-only permissions in Manual mode and requests approval for actions that modify the environment. Its permission system also supports granular allow, ask, and deny controls for MCP tools and subagents. Claude Code Security , Configure Permissions Options A and B eliminate least privilege and approval boundaries. Option C removes essential detection and forensic evidence.
Study Guide references/topics: Production database safety; least privilege; read-only defaults; MCP permissions; subagent scoping; human confirmation; auditability.
NEW QUESTION # 89
You are building an evaluation pipeline for a Claude-based deployment and must complete the specification steps before running the deployment against the dataset.
Which two steps must be completed BEFORE running the deployment against the evaluation dataset? (Select two.) Each correct answer presents part of the solution.
Answer: B,E
Explanation:
The evaluation specification must exist before inference begins. Option D defines what the evaluation will measure and how results will be segmented. Representative cases measure normal workload performance, edge cases test boundary behavior, and adversarial cases examine safety, security, or robustness under hostile inputs.
Option B then supplies the correctly curated and labeled dataset corresponding to those slices. Labels, expected outcomes, grading rubrics, provenance, and dataset versions must be established before the deployment generates outputs. Otherwise, evaluators risk modifying criteria after seeing results and introducing confirmation bias.
Anthropic defines an evaluation as an input combined with grading logic used to measure success. Its evaluation guidance distinguishes tasks, trials, graders, traces, outcomes, and the harness that runs and aggregates them. Demystifying Evals for AI Agents Option E occurs after model execution because outputs must exist before they can be scored. Option A follows scoring and aggregation. Option C is an iterative improvement step performed after failure cases become available, although rubric calibration may also be conducted on separate development data.
Study Guide references/topics: Evaluation specification; metrics and slices; representative and adversarial datasets; labeling; scoring; aggregation; release gates.
NEW QUESTION # 90
......
We offer you to take back your money, if you do not succeed in CCAR-P exam. Such a guarantee in itself is concrete evidence on the unmatched quality of our CCAR-P dumps. For the reason, they are approved not only by a large number of professionals who are busy in developing their careers but also by the industry experts. Get the right reward for your potential, believing in the easiest and to the point CCAR-P Exam Questions that are meant to bring you a brilliant success in CCAR-P exams.
Associate CCAR-P Level Exam: https://www.actual4exams.com/CCAR-P-valid-dump.html