無料でクラウドストレージから最新のFast2test Data-Engineer-Associate PDFダンプをダウンロードする:https://drive.google.com/open?id=19kejKQc4z_xVyhO0u8vQpGuxHJ3M2Rmj
調査、研究を経って、IT職員の月給の増加とジョブのプロモーションはAmazon Data-Engineer-Associate資格認定と密接な関係があります。給料の増加とジョブのプロモーションを真になるために、Fast2testのAmazon Data-Engineer-Associate問題集を勉強しましょう。いつまでもData-Engineer-Associate試験に準備する皆様に便宜を与えるFast2testは、高品質の試験資料と行き届いたサービスを提供します。
| Section | Weight | Objectives |
|---|---|---|
| Data Security and Governance | 18% | - Ensure data encryption
|
| Data Operations and Support | 22% | - Monitor data pipelines
|
| Data Ingestion and Transformation | 34% | - Orchestrate data pipelines
|
| Data Store Management | 26% | - Understand data cataloging
|
>> Data-Engineer-Associate資格認証攻略 <<
あなたはこのような人々の一人ですか。さまざまな資料とトレーニング授業を前にして、どれを選ぶか本当に困っているのです。もしそうだったら、これ以上困ることはないです。Fast2testはあなたにとって最も正確な選択ですから。我々はあなたに試験問題と解答に含まれている全面的な試験資料を提供することができます。Fast2testの解答は最も正確な解釈ですから、あなたがより良い知識を身につけることに助けになれます。Fast2testを利用したら、AmazonのData-Engineer-Associate認定試験に受かることを信じています。それも我々が全てのお客様に対する約束です。
質問 # 243
A marketing company uses Amazon S3 to store marketing dat
a. The company uses versioning in some buckets. The company runs several jobs to read and load data into the buckets.
To help cost-optimize its storage, the company wants to gather information about incomplete multipart uploads and outdated versions that are present in the S3 buckets.
Which solution will meet these requirements with the LEAST operational effort?
正解:D
解説:
The company wants to gather information about incomplete multipart uploads and outdated versions in its Amazon S3 buckets to optimize storage costs.
Option B: Use Amazon S3 Inventory configurations reports to gather the information.
S3 Inventory provides reports that can list incomplete multipart uploads and versions of objects stored in S3. It offers an easy, automated way to track object metadata across buckets, including data necessary for cost optimization, without manual effort.
Options A (AWS CLI), C (S3 Storage Lens), and D (usage reports) either do not specifically gather the required information about incomplete uploads and outdated versions or require more manual intervention.
Reference:
Amazon S3 Inventory Documentation
質問 # 244
A mobile gaming company wants to capture data from its gaming app. The company wants to make the data available to three internal consumers of the data. The data records are approximately 20 KB in size.
The company wants to achieve optimal throughput from each device that runs the gaming app. Additionally, the company wants to develop an application to process data streams. The stream-processing application must have dedicated throughput for each internal consumer.
Which solution will meet these requirements?
正解:B
解説:
Problem Analysis:
Input Requirements: Gaming app generates approximately 20 KB data records, which must be ingested and made available to three internal consumers with dedicated throughput.
Key Requirements:
High throughput for ingestion from each device.
Dedicated processing bandwidth for each consumer.
Key Considerations:
Amazon Kinesis Data Streams supports high-throughput ingestion with PutRecords API for batch writes.
The Enhanced Fan-Out feature provides dedicated throughput to each consumer, avoiding bandwidth contention.
This solution avoids bottlenecks and ensures optimal throughput for the gaming application and consumers.
Solution Analysis:
Option A: Kinesis Data Streams + Enhanced Fan-Out
PutRecords API is designed for batch writes, improving ingestion performance.
Enhanced Fan-Out allows each consumer to process the stream independently with dedicated throughput.
Option B: Data Firehose + Dedicated Throughput Request
Firehose is not designed for real-time stream processing or fan-out. It delivers data to destinations like S3, Redshift, or OpenSearch, not multiple independent consumers.
Option C: Data Firehose + Enhanced Fan-Out
Firehose does not support enhanced fan-out. This option is invalid.
Option D: Kinesis Data Streams + EC2 Instances
Hosting stream-processing applications on EC2 increases operational overhead compared to native enhanced fan-out.
Final Recommendation:
Use Kinesis Data Streams with Enhanced Fan-Out for high-throughput ingestion and dedicated consumer bandwidth.
Kinesis Data Streams Enhanced Fan-Out
PutRecords API for Batch Writes
質問 # 245
A data engineer maintains custom Python scripts that perform a data formatting process that many AWS Lambda functions use. When the data engineer needs to modify the Python scripts, the data engineer must manually update all the Lambda functions.
The data engineer requires a less manual way to update the Lambda functions.
Which solution will meet this requirement?
正解:B
解説:
Lambda layers are a way to share code and dependencies across multiple Lambda functions. By packaging the custom Python scripts into Lambda layers, the data engineer can update the scripts in one place and have them automatically applied to all the Lambda functions that use the layer. This reduces the manual effort and ensures consistency across the Lambda functions. The other options are either not feasible or not efficient.
Storing a pointer to the custom Python scripts in the execution context object or in environment variables would require the Lambda functions to download the scripts from Amazon S3 every time they are invoked, which would increase latency and cost. Assigning the same alias to each Lambda function would not help with updating the Python scripts, as the alias only points to a specific version of the Lambda function code. References:
AWS Lambda layers
AWS Certified Data Engineer - Associate DEA-C01 Complete Study Guide, Chapter 3: Data Ingestion and Transformation, Section 3.4: AWS Lambda
質問 # 246
A data engineer needs to build an extract, transform, and load (ETL) job. The ETL job will process daily incoming .csv files that users upload to an Amazon S3 bucket. The size of each S3 object is less than 100 MB.
Which solution will meet these requirements MOST cost-effectively?
正解:C
解説:
AWS Glue is a fully managed serverless ETL service that can handle various data sources and formats, including .csv files in Amazon S3. AWS Glue provides two types of jobs: PySpark and Python shell. PySpark jobs use Apache Spark to process large-scale data in parallel, while Python shell jobs use Python scripts to process small-scale data in a single execution environment. For this requirement, a Python shell job is more suitable and cost-effective, as the size of each S3 object is less than 100 MB, which does not require distributed processing. A Python shell job can use pandas, a popular Python library fordata analysis, to transform the .csv data as needed. The other solutions are not optimal or relevant for this requirement. Writing a custom Python application and hosting it on an Amazon EKS cluster would require more effort and resources to set up and manage the Kubernetes environment, as well as to handle the data ingestion and transformation logic. Writing a PySpark ETL script and hosting it on an Amazon EMR cluster would also incur more costs and complexity to provision and configure the EMR cluster, as well as to use Apache Spark for processing small data files. Writing an AWS Glue PySpark job would also be less efficient and economical than a Python shell job, as it would involve unnecessary overhead and charges for using Apache Spark for small data files. References:
AWS Glue
Working with Python Shell Jobs
pandas
[AWS Certified Data Engineer - Associate DEA-C01 Complete Study Guide]
質問 # 247
A data engineer needs to create a new empty table in Amazon Athena that has the same schema as an existing table named old-table.
Which SQL statement should the data engineer use to meet this requirement?


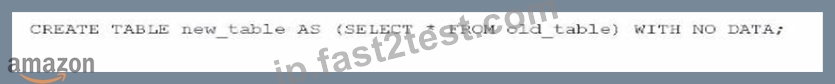

正解:C
解説:
* Problem Analysis:
* The goal is to create anew empty tablein Athena with the same schema as an existing table (old_table).
* The solution must avoid copying any data.
* Key Considerations:
* CREATE TABLE AS (CTAS)is commonly used in Athena for creating new tables based on an existing table.
* Adding the WITH NO DATA clause ensures only the schema is copied, without transferring any data.
* Solution Analysis:
* Option A: Copies both schema and data. Does not meet the requirement for an empty table.
* Option B: Inserts data into an existing table, which does not create a new table.
* Option C: Creates an empty table but does not copy the schema.
* Option D: Creates a new table with the same schema and ensures it is empty by using WITH NO DATA.
* Final Recommendation:
* UseD. CREATE TABLE new_table AS (SELECT * FROM old_table) WITH NO DATAto create an empty table with the same schema.
:
Athena CTAS Queries
CREATE TABLE Statement in Athena
質問 # 248
......
Data-Engineer-Associate試験に合格すると多くのメリットが得られることは誰もが知っていますが、Amazonすべての受験者がそれを達成するのは容易ではありません。 Data-Engineer-Associateガイド急流は、すべての受験者が試験に合格するのを支援することを目的としたツールです。 私たちの試験資料は、コンピュータと人の量に制限なしでインストールおよびダウンロードできます。 弊社が提供するData-Engineer-Associate学習資料が有用であり、テストに合格するのに役立つことを保証します。 製品を購入すると、便利な方法を使用して、いつでもどこでもData-Engineer-Associate試験トレントを学習できます。 そのため、購入の前後に安心して、Data-Engineer-Associate学習教材にウイルスがないことを信頼してください。 AWS Certified Data Engineer - Associate (DEA-C01)当社の製品Fast2testに慣れるために、Data-Engineer-Associate学習教材の機能と利点を次のようにリストします。
Data-Engineer-Associate問題集無料: https://jp.fast2test.com/Data-Engineer-Associate-premium-file.html
2026年Fast2testの最新Data-Engineer-Associate PDFダンプおよびData-Engineer-Associate試験エンジンの無料共有:https://drive.google.com/open?id=19kejKQc4z_xVyhO0u8vQpGuxHJ3M2Rmj