P.S. Free & New Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by Itbraindumps: https://drive.google.com/open?id=1pzwaXPNltmWnFbKW0ldzaS0vd1dvyJy3
You may urgently need to attend Databricks-Generative-AI-Engineer-Associate certificate exam and get the certificate to prove you are qualified for the job in some area. But why Databricks-Generative-AI-Engineer-Associate certificate is valuable and useful and can help you a lot? Because passing the test certification can help you prove that you are competent in some area and if you buy our Databricks-Generative-AI-Engineer-Associate Study Materials you will pass the test almost without any problems. We are professional in these career for more than ten years and can give you promised success.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Generative AI Engineer Associate Exam |
| Exam Number: | Databricks-Generative-AI-Engineer-Associate |
| Real Exam Qty: | 45 |
| Exam Duration: | 90 minutes |
| Certificate Validity Period: | 2 years |
| Exam Format: | Multiple choice |
| Exam Price: | USD 200 |
| Available Languages: | Korean, Brazilian Portuguese, English, Japanese |
| Passing Score: | 700/1000 or 70% |
| Recommended Training: | Generative AI Engineering with Databricks |
| Exam Registration: | Databricks Certification Registration |
| Sample Questions: | Databricks Databricks-Generative-AI-Engineer-Associate Sample Questions |
| Exam Way: | Online proctored or in-person test center |
| Pre Condition: | No formal prerequisites; recommended 6+ months hands-on experience building generative AI solutions |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/genai-engineer-associate |
>> Databricks-Generative-AI-Engineer-Associate Reliable Test Syllabus <<
Our Databricks dumps torrent contains everything you need to pass Databricks-Generative-AI-Engineer-Associate actual test smoothly. We always adhere to the principle that provides our customers best quality Databricks-Generative-AI-Engineer-Associate Exam Prep with most comprehensive service. This is the reason why most people prefer to choose our Databricks-Generative-AI-Engineer-Associate vce dumps as their best preparation materials.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
NEW QUESTION # 83
A Generative AI Engineer I using the code below to test setting up a vector store: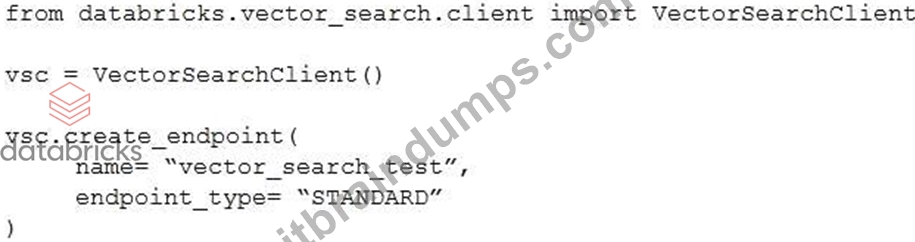
Assuming they intend to use Databricks managed embeddings with the default embedding model, what should be the next logical function call?
Answer: B
Explanation:
Context: The Generative AI Engineer is setting up a vector store using Databricks' VectorSearchClient. This is typically done to enable fast and efficient retrieval of vectorized data for tasks like similarity searches.
Explanation of Options:
* Option A: vsc.get_index(): This function would be used to retrieve an existing index, not create one, so it would not be the logical next step immediately after creating an endpoint.
* Option B: vsc.create_delta_sync_index(): After setting up a vector store endpoint, creating an index is necessary to start populating and organizing the data. The create_delta_sync_index() function specifically creates an index that synchronizes with a Delta table, allowing automatic updates as the data changes. This is likely the most appropriate choice if the engineer plans to use dynamic data that is updated over time.
* Option C: vsc.create_direct_access_index(): This function would create an index that directly accesses the data without synchronization. While also a valid approach, it's less likely to be the next logical step if the default setup (typically accommodating changes) is intended.
* Option D: vsc.similarity_search(): This function would be used to perform searches on an existing index; however, an index needs to be created and populated with data before any search can be conducted.
Given the typical workflow in setting up a vector store, the next step after creating an endpoint is to establish an index, particularly one that synchronizes with ongoing data updates, henceOption B.
NEW QUESTION # 84
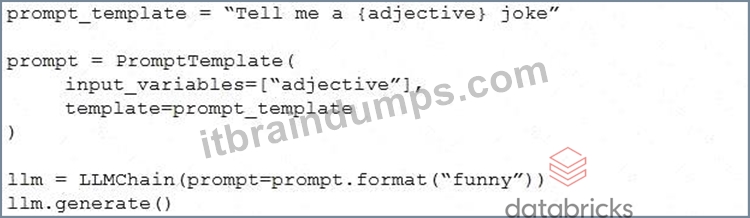
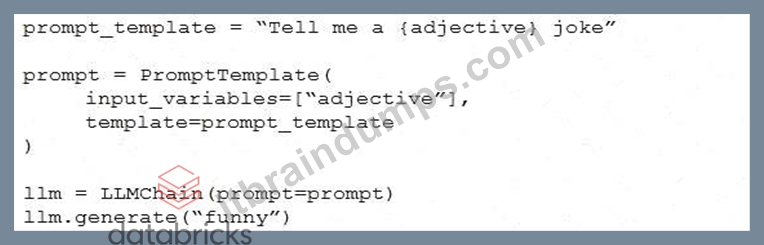
A Generative AI Engineer is testing a simple prompt template in LangChain using the code below, but is getting an error.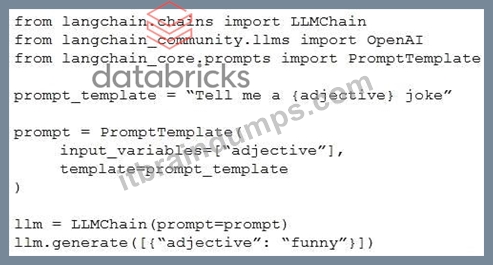
Assuming the API key was properly defined, what change does the Generative AI Engineer need to make to fix their chain?
Answer: A
Explanation:
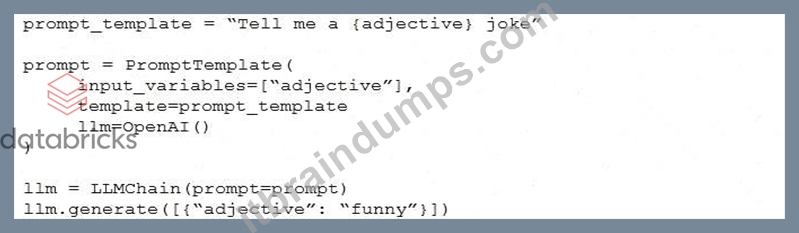
To fix the error in the LangChain code provided for using a simple prompt template, the correct approach is Option C. Here's a detailed breakdown of why Option C is the right choice and how it addresses the issue:
* Proper Initialization: In Option C, the LLMChain is correctly initialized with the LLM instance specified as OpenAI(), which likely represents a language model (like GPT) from OpenAI. This is crucial as it specifies which model to use for generating responses.
* Correct Use of Classes and Methods:
* The PromptTemplate is defined with the correct format, specifying that adjective is a variable within the template. This allows dynamic insertion of values into the template when generating text.
* The prompt variable is properly linked with the PromptTemplate, and the final template string is passed correctly.
* The LLMChain correctly references the prompt and the initialized OpenAI() instance, ensuring that the template and the model are properly linked for generating output.
Why Other Options Are Incorrect:
* Option A: Misuses the parameter passing in generate method by incorrectly structuring the dictionary.
* Option B: Incorrectly uses prompt.format method which does not exist in the context of LLMChain and PromptTemplate configuration, resulting in potential errors.
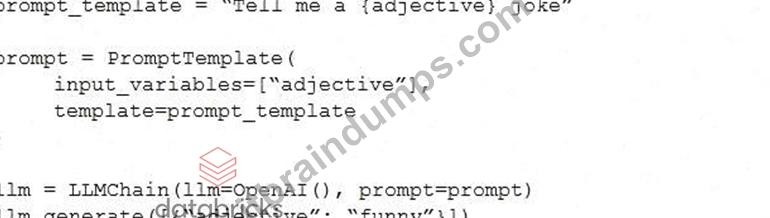
* Option D: Incorrect order and setup in the initialization parameters for LLMChain, which would likely lead to a failure in recognizing the correct configuration for prompt and LLM usage.
Thus, Option C is correct because it ensures that the LangChain components are correctly set up and integrated, adhering to proper syntax and logical flow required by LangChain's architecture. This setup avoids common pitfalls such as type errors or method misuses, which are evident in other options.
NEW QUESTION # 85
A Generative Al Engineer is helping a cinema extend its website ' s chat bot to be able to respond to questions about specific showtimes for movies currently playing at their local theater. They already have the location of the user provided by location services to their agent, and a Delta table which is continually updated with the latest showtime information by location. They want to implement this new capability In their RAG application.
Which option will do this with the least effort and in the most performant way?
Answer: C
Explanation:
The task is to extend a cinema chatbot to provide movie showtime information using a RAG application, leveraging user location and a continuously updated Delta table, with minimal effort and high performance.
Let's evaluate the options.
* Option A: Create a Feature Serving Endpoint from a FeatureSpec that references an online store synced from the Delta table. Query the Feature Serving Endpoint as part of the agent logic / tool implementation
* Databricks Feature Serving provides low-latency access to real-time data from Delta tables via an online store. Syncing the Delta table to a Feature Serving Endpoint allows the chatbot to query showtimes efficiently, integrating seamlessly into the RAG agent's tool logic. This leverages Databricks' native infrastructure, minimizing effort and ensuring performance.
* Databricks Reference : " Feature Serving Endpoints provide real-time access to Delta table data with low latency, ideal for production systems " ( " Databricks Feature Engineering Guide, "
2023).
* Option B: Query the Delta table directly via a SQL query constructed from the user ' s input using a text-to-SQL LLM in the agent logic / tool
* Using a text-to-SQL LLM to generate queries adds complexity (e.g., ensuring accurate SQL generation) and latency (LLM inference + SQL execution). While feasible, it's less performant and requires more effort than a pre-built serving solution.
* Databricks Reference : " Direct SQL queries are flexible but may introduce overhead in real- time applications " ( " Building LLM Applications with Databricks " ).
* Option C: Write the Delta table contents to a text column, then embed those texts using an embedding model and store these in the vector index. Look up the information based on the embedding as part of the agent logic / tool implementation
* Converting structured Delta table data (e.g., showtimes) into text, embedding it, and using vector search is inefficient for structured lookups. It's effort-intensive (preprocessing, embedding) and less precise than direct queries, undermining performance.
* Databricks Reference : " Vector search excels for unstructured data, not structured tabular lookups " ( " Databricks Vector Search Documentation " ).
* Option D: Set up a task in Databricks Workflows to write the information in the Delta table periodically to an external database such as MySQL and query the information from there as part of the agent logic / tool implementation
* Exporting to an external database (e.g., MySQL) adds setup effort (workflow, external DB management) and latency (periodic updates vs. real-time). It's less performant and more complex than using Databricks' native tools.
* Databricks Reference : " Avoid external systems when Delta tables provide real-time data natively " ( " Databricks Workflows Guide " ).
Conclusion : Option A minimizes effort by using Databricks Feature Serving for real-time, low-latency access to the Delta table, ensuring high performance in a production-ready RAG chatbot.
NEW QUESTION # 86
Generative AI Engineer at an electronics company just deployed a RAG application for customers to ask questions about products that the company carries. However, they received feedback that the RAG response often returns information about an irrelevant product.
What can the engineer do to improve the relevance of the RAG's response?
Answer: B
Explanation:
In a Retrieval-Augmented Generation (RAG) system, the key to providing relevant responses lies in the quality of the retrieved context. Here's why option A is the most appropriate solution:
Context Relevance:
The RAG model generates answers based on retrieved documents or context. If the retrieved information is about an irrelevant product, it suggests that the retrieval step is failing to select the right context. The Generative AI Engineer must first assess the quality of what is being retrieved and ensure it is pertinent to the query.
Vector Search and Embedding Similarity:
RAG typically uses vector search for retrieval, where embeddings of the query are matched against embeddings of product descriptions. Assessing the semantic similarity search process ensures that the closest matches are actually relevant to the query.
Fine-tuning the Retrieval Process:
By improving the retrieval quality, such as tuning the embeddings or adjusting the retrieval strategy, the system can return more accurate and relevant product information.
Why Other Options Are Less Suitable:
B (Caching FAQs): Caching can speed up responses for frequently asked questions but won't improve the relevance of the retrieved content for less frequent or new queries.
C (Use a Different LLM): Changing the LLM only affects the generation step, not the retrieval process, which is the core issue here.
D (Different Semantic Search Algorithm): This could help, but the first step is to evaluate the current retrieval context before replacing the search algorithm.
Therefore, improving and assessing the quality of the retrieved context (option A) is the first step to fixing the issue of irrelevant product information.
NEW QUESTION # 87
After changing the response generating LLM in a RAG pipeline from GPT-4 to a model with a shorter context length that the company self-hosts, the Generative AI Engineer is getting the following error:
What TWO solutions should the Generative AI Engineer implement without changing the response generating model? (Choose two.)
Answer: B,E
Explanation:
Problem Context: After switching to a model with a shorter context length, the error message indicating that the prompt token count has exceeded the limit suggests that the input to the model is too large.
Explanation of Options:
Option A: Use a smaller embedding model to generate - This wouldn't necessarily address the issue of prompt size exceeding the model's token limit.
Option B: Reduce the maximum output tokens of the new model - This option affects the output length, not the size of the input being too large.
Option C: Decrease the chunk size of embedded documents - This would help reduce the size of each document chunk fed into the model, ensuring that the input remains within the model's context length limitations.
Option D: Reduce the number of records retrieved from the vector database - By retrieving fewer records, the total input size to the model can be managed more effectively, keeping it within the allowable token limits.
Option E: Retrain the response generating model using ALiBi - Retraining the model is contrary to the stipulation not to change the response generating model.
Options C and D are the most effective solutions to manage the model's shorter context length without changing the model itself, by adjusting the input size both in terms of individual document size and total documents retrieved.
NEW QUESTION # 88
......
Learning Databricks-Generative-AI-Engineer-Associate Mode: https://www.itbraindumps.com/Databricks-Generative-AI-Engineer-Associate_exam.html
2026 Latest Itbraindumps Databricks-Generative-AI-Engineer-Associate PDF Dumps and Databricks-Generative-AI-Engineer-Associate Exam Engine Free Share: https://drive.google.com/open?id=1pzwaXPNltmWnFbKW0ldzaS0vd1dvyJy3