BTW, DOWNLOAD part of PrepAwayTest MLA-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1egUKcir1CytYRft-HUdcempxA-BqXOlp
PrepAwayTest is a professional IT certification sites, the certification success rate is 100%. This number is proved by candidates through practice. Because PrepAwayTest has a strong IT team of experts, they are committed to study exam questions and answers, and serve the vital interests of the majority of candidates. They use their own professional mind and experience to meet the needs of the candidates. According to the needs of the candidate, they consider the issue from all angles, and manufacturing applicability exam training materials. This material is Amazon MLA-C01 Exam Training materials, which including questions and answers.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: ML Model Development | 26% | - Model tuning and evaluation
|
| Topic 2: ML Solution Monitoring, Maintenance, and Security | 24% | - Security and governance
|
| Topic 3: Deployment and Orchestration of ML Workflows | 22% | - ML pipeline orchestration
|
| Topic 4: Data Preparation for Machine Learning (ML) | 28% | - Data ingestion and collection
|
You can open the Amazon PDF questions file from any location and go through actual MLA-C01 exam questions without time restrictions. The AWS Certified Machine Learning Engineer - Associate MLA-C01 practice test is ideal for intensive preparation. You can attempt our AWS Certified Machine Learning Engineer - Associate MLA-C01 Practice Exam multiple times to review and enhance your test preparation. The real MLA-C01 exam environment of desktop and web-based practice exams will help you counter AWS Certified Machine Learning Engineer - Associate MLA-C01 pass anxiety.
NEW QUESTION # 15
A company has an ML model that generates text descriptions based on images that customers upload to the company's website. The images can be up to 50 MB in total size.
An ML engineer decides to store the images in an Amazon S3 bucket. The ML engineer must implement a processing solution that can scale to accommodate changes in demand.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: A
NEW QUESTION # 16
A company uses an NFS-based data store to store data for ML training. Linux-based systems access the data store.
The company needs a hybrid system to make the shared data store accessible to on-premises servers and Amazon SageMaker AI notebooks that will consume the data. File locking is required for the data producers.
Which AWS storage solution will meet these requirements?
Answer: A
Explanation:
Option B is correct because Amazon EFS is a managed NFS-based shared file system that supports Linux clients, hybrid access, and file-system semantics such as file locking . AWS documentation states that Amazon EFS provides strong data consistency and file locking , which is an explicit requirement in the question. AWS also states that you can mount EFS file systems on on-premises data center servers when connected to your Amazon VPC through AWS Direct Connect or Site-to-Site VPN , which directly satisfies the hybrid access requirement.
For the SageMaker side, AWS documentation states that SageMaker AI creates a default Amazon EFS volume for Studio domains, and you can also add a custom Amazon EFS file system so domain users can access it in SageMaker Studio. AWS also notes that SageMaker AI Studio notebooks use Amazon EFS as a persistent storage layer. That makes EFS the most natural AWS storage service for a shared file repository that must be accessible from SageMaker notebooks.
The other choices are weaker. Amazon S3 with Mountpoint is object storage access and is not the best answer for a shared NFS-style data store with file locking requirements. FSx for Lustre is high-performance parallel file storage and can support on-premises bursting, but the question explicitly starts from an NFS- based shared data store, and EFS is AWS's native NFS file service. Amazon EBS cannot be mounted simultaneously across on-premises servers and SageMaker notebooks as a shared, managed hybrid file system. Therefore, the best verified AWS-docs answer is B .
NEW QUESTION # 17
A company deployed an ML model that uses the XGBoost algorithm to predict product failures.
The model is hosted on an Amazon SageMaker endpoint and is trained on normal operating data.
An AWS Lambda function provides the predictions to the company's application.
An ML engineer must implement a solution that uses incoming live data to detect decreased model accuracy over time.
Which solution will meet these requirements?
Answer: B
NEW QUESTION # 18
A company has an application that uses different APIs to generate embeddings for input text. The company needs to implement a solution to automatically rotate the API tokens every 3 months.
Which solution will meet this requirement?
Answer: B
Explanation:
AWS Secrets Manager is designed for securely storing, managing, and automatically rotating secrets, including API tokens. By configuring a Lambda function for custom rotation logic, the solution can automatically rotate the API tokens every 3 months as required. Secrets Manager simplifies secret management and integrates seamlessly with other AWS services, making it the ideal choice for this use case.
NEW QUESTION # 19
An ML engineer needs to use Amazon SageMaker Feature Store to create and manage features to train a model.
Select and order the steps from the following list to create and use the features in Feature Store. Each step should be selected one time. (Select and order three.)
* Access the store to build datasets for training.
* Create a feature group.
* Ingest the records.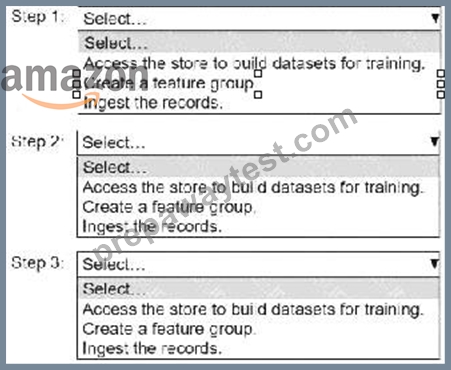
Answer:
Explanation: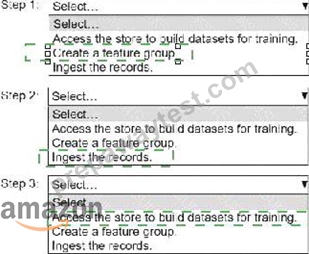
Explanation: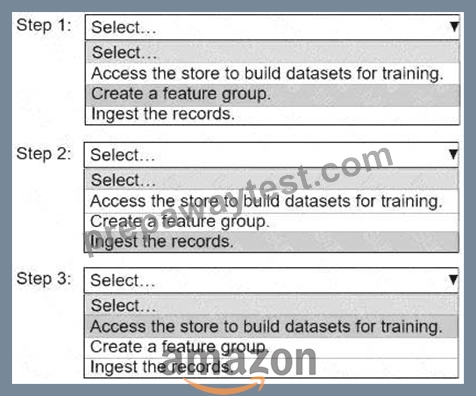
Step 1: Create a feature group.
Step 2: Ingest the records.
Step 3: Access the store to build datasets for training.
Step 1: Create a Feature Group
Why? A feature group is the foundational unit in SageMaker Feature Store, where features are defined, stored, and organized. Creating a feature group specifies the schema (name, data type) for the features and the primary keys for data identification.
How? Use the SageMaker Python SDK or AWS CLI to define the feature group by specifying its name, schema, and S3 storage location for offline access.
Step 2: Ingest the Records
Why? After creating the feature group, the raw data must be ingested into the Feature Store. This step populates the feature group with data, making it available for both real-time and offline use.
How? Use the SageMaker SDK or AWS CLI to batch-ingest historical data or stream new records into the feature group. Ensure the records conform to the feature group schema.
Step 3: Access the Store to Build Datasets for Training
Why? Once the features are stored, they can be accessed to create training datasets. These datasets combine relevant features into a single format for machine learning model training.
How? Use the SageMaker Python SDK to query the offline store or retrieve real-time features using the online store API. The offline store is typically used for batch training, while the online store is used for inference.
Order Summary:
Create a feature group.
Ingest the records.
Access the store to build datasets for training.
This process ensures the features are properly managed, ingested, and accessible for model training using Amazon SageMaker Feature Store.
NEW QUESTION # 20
......
We all know the effective diligence is in direct proportion to outcome, so by years of diligent work, our experts have collected the frequent-tested knowledge into our Amazon MLA-C01 practice materials for your reference. So our AWS Certified Machine Learning Engineer - Associate training materials are triumph of their endeavor.
Test MLA-C01 Guide: https://www.prepawaytest.com/Amazon/MLA-C01-practice-exam-dumps.html
BTW, DOWNLOAD part of PrepAwayTest MLA-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1egUKcir1CytYRft-HUdcempxA-BqXOlp