Free PDF Quiz Databricks - Certified-Data-Engineer-Professional - High Pass-Rate Databricks Certified Data Engineer Professional Exam Registration

You are desired to know where to get free and valid resource for the study of Certified-Data-Engineer-Professional actual test. Certified-Data-Engineer-Professional free demo can give you some help. You can free download the Certified-Data-Engineer-Professional free pdf demo to have a try. The questions of the free demo are part of the Databricks Certified-Data-Engineer-Professional Complete Exam Dumps. You can have a preview of the Certified-Data-Engineer-Professional practice pdf. If you think it is valid and useful, you can choose the complete one for further study. I think with the assist of Certified-Data-Engineer-Professional updated dumps, you will succeed with ease.
| Section | Objectives |
|---|
| Topic 1: Developing Code for Data Processing using Python and SQL | - Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 2. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 3. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 4. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 5. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 6. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 7. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 8. Create pipeline components using control flow operators such as if/else and foreach
- Using Python and Tools for Development
- 1. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 2. Develop User-Defined Functions using Pandas/Python UDF
- 3. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
|
| Topic 2: Data Governance | - Govern enterprise data
- 1. Create and add descriptions and metadata to enterprise data to improve discoverability
- 2. Demonstrate understanding of the Unity Catalog permission inheritance model
|
| Topic 3: Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
- 2. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
|
| Topic 4: Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 2. Apply Change Data Feed to address streaming table limitations and improve latency
- 3. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 4. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 5. Understand Delta optimization techniques such as deletion vectors and liquid clustering
|
| Topic 5: Data Sharing and Federation | - Share and federate data
- 1. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 2. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 3. Configure Lakehouse Federation with appropriate governance across supported source systems
|
| Topic 6: Data Modeling | - Design and optimize data models
- 1. Simplify data layout decisions and optimize query performance using liquid clustering
- 2. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 3. Design and implement scalable data models using Delta Lake to manage large datasets
- 4. Design dimensional models for analytical workloads with efficient querying and aggregation
|
| Topic 7: Monitoring and Alerting | - Monitoring
- 1. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 2. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 3. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 4. Use Query Profile and Spark UI to monitor workloads
- Alerting
- 1. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- 2. Use SQL Alerts to monitor data quality
|
| Topic 8: Ensuring Data Security and Compliance | - Applying Data Security Mechanisms
- 1. Use row filters and column masks to protect sensitive table data
- 2. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 3. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- Ensuring Compliance
- 1. Develop data purging solutions that comply with data retention policies
- 2. Implement compliant batch and streaming pipelines that detect and mask PII
|
| Topic 9: Debugging and Deploying | - Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 2. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 3. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
|
| Topic 10: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
>> Certified-Data-Engineer-Professional Exam Registration <<
2026 Databricks Certified-Data-Engineer-Professional Realistic Exam Registration
It’s our responsibility to offer instant help to every user on our Certified-Data-Engineer-Professional exam questions. If you have any question about Certified-Data-Engineer-Professional study materials, please do not hesitate to leave us a message or send us an email. Our customer service staff will be delighted to answer your questions on the Certified-Data-Engineer-Professional learing engine. And we will give you the most professional suggeston on the Certified-Data-Engineer-Professional practice prep with kind and considerate manner in 24/7 online.
Databricks Certified Data Engineer Professional Sample Questions (Q239-Q244):
NEW QUESTION # 239
A data engineer is reviewing the PySpark code to copy a part of the production dataset to the sandbox environment, and needs to be sure that no PII(Personally Identifiable Information) data is being copied. After checking the sales table, the data engineer notices that it has user emails as the only PII data included as well as being the only column to identify the user.
from pyspark.sql import functions as F
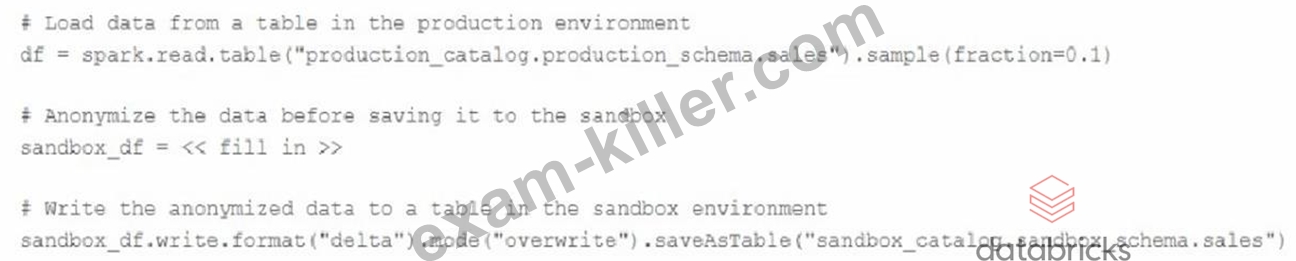
Which anonymised code should be used to achieve the required outcome?
- A. df.withColumn ("user_emai", F.expr("uuid()"))
- B. df.withColumn ("hashed_email", sha2 ("user_email"))
- C. df.withColumn ("user_email", F.regexp_replace ("user_eamail", "@*", "@anonymized.com"))
- D. df.withColumn ("user_email", F.sha2 ("user_email"))
Answer: D
Explanation:
Hashing the email column replaces the original PII with a deterministic, irreversible value while preserving its role as a unique identifier. This ensures no actual email addresses are copied to the sandbox environment, while still allowing consistent joins or user-level analysis if needed.
NEW QUESTION # 240
A senior data engineer is planning large-scale data workflows. The current task is to identify the considerations that form a foundation for creating scalable data models that are essential for effective management of large datasets. The data engineering team has identified the core capabilities as part of a scalable data model to build a modern data platform and provided their reasoning for considering Delta Lake for review. The senior data engineer is responsible for identifying the recommendations that are not valid. Which key features can be ignored while evaluating Delta Lake?
- A. Delta Lake optimizes metadata handling, efficiently managing billions of files and facilitating scalability to petabyte-scale datasets.
- B. Delta Lake's capability to process data in both batch and streaming modes seamlessly, providing flexibility in data ingestion and processing.
- C. Delta Lake provides limited support for monitoring and troubleshooting data pipelines, so relevant partner tools have to be identified and set up for enhanced operational efficiency.
- D. Delta Lake works with various data formats (e.g., Parquet, JSON, CSV) and integrates well with Spark and Databricks tools.
Answer: C
Explanation:
Delta Lake includes built-in capabilities for monitoring, auditing, and troubleshooting through transaction logs, history, and tight integration with the Databricks platform. Therefore, limited support for monitoring and troubleshooting is not a valid concern when evaluating Delta Lake and can be ignored.
NEW QUESTION # 241
A data engineer needs to provide access to a group named manufacturing-team. The team needs privileges to create tables in the quality schema. Which set of SQL commands will grant a group named manufacturing-team to create tables in a schema named production with the parent catalog named manufacturing with the least privileges?
- A. GRANT CREATE TABLE ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT CREATE SCHEMA ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT USE CATALOG ON CATALOG manufacturing TO manufacturing-team;
- B. GRANT CREATE TABLE ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT CREATE SCHEMA ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT CREATE CATALOG ON CATALOG manufacturing TO manufacturing-team;
- C. GRANT CREATE TABLE ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT USE SCHEMA ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT USE CATALOG ON CATALOG manufacturing TO manufacturing-team;
- D. GRANT USE TABLE ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT USE SCHEMA ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT USE CATALOG ON CATALOG manufacturing TO manufacturing-team;
Answer: C
Explanation:
To create a table within a schema, a principal must have CREATE TABLE on the schema, USE SCHEMA on that schema, and USE CATALOG on the parent catalog. This combination ensures the group has just enough privileges to create objects in that schema without excessive permissions like CREATE SCHEMA or CREATE CATALOG.
NEW QUESTION # 242
Which statement describes Delta Lake Auto Compaction?
- A. An asynchronous job runs after the write completes to detect if files could be further compacted; if yes, an optimize job is executed toward a default of 128 MB.
- B. Optimized writes use logical partitions instead of directory partitions; because partition boundaries are only represented in metadata, fewer small files are written.
- C. An asynchronous job runs after the write completes to detect if files could be further compacted; if yes, an optimize job is executed toward a default of 1 GB.
- D. Before a Jobs cluster terminates, optimize is executed on all tables modified during the most recent job.
- E. Data is queued in a messaging bus instead of committing data directly to memory; all data is committed from the messaging bus in one batch once the job is complete.
Answer: A
Explanation:
This is the correct answer because it describes the behavior of Delta Lake Auto Compaction, which is a feature that automatically optimizes the layout of Delta Lake tables by coalescing small files into larger ones. Auto Compaction runs as an asynchronous job after a write to a table has succeeded and checks if files within a partition can be further compacted. If yes, it runs an optimize job with a default target file size of 128 MB. Auto Compaction only compacts files that have not been compacted previously.
NEW QUESTION # 243
A departing platform owner currently holds ownership of multiple catalogs and controls storage credentials and external locations. A data engineer has been asked to ensure continuity: transfer catalog ownership to the platform team group, delegate ongoing privilege management, and retain the ability to receive and share data via Delta Sharing. Which role must be in place to perform these actions across the metastore?
- A. Catalog Owner, because catalog owners can transfer any object in any catalog in the metastore.
- B. Metastore Admin, because metastore admins can transfer ownership and manage privileges across all metastore objects, including shares and recipients.
- C. Account Admin, because account admins can only create metastores but cannot change ownership of catalogs.
- D. Workspace Admin, because workspace admins can transfer ownership of any Unity Catalog object.
Answer: B
Explanation:
Metastore Admins have the highest administrative privileges within a Unity Catalog metastore.
They can transfer ownership of any Unity Catalog object, including catalogs, schemas, tables, storage credentials, and external locations. Metastore Admins are also required to manage Delta Sharing configurations such as creating or transferring shares and recipients.
Account Admins, by contrast, only create metastores and cannot change ownership or manage Delta Sharing objects. Workspace Admins have privileges limited to workspace-level management, not cross-metastore access.
NEW QUESTION # 244
......
You also get the opportunity to download the latest Certified-Data-Engineer-Professional pdf questions and practice tests up to three months from the date of Databricks Databricks Certified Data Engineer Professional exam dumps purchase. So rest assured that with Databricks Certified-Data-Engineer-Professional real dumps you will not miss even a single Certified-Data-Engineer-Professional Exam Questions in the final exam. Now take the best decision of your career and enroll in Databricks Databricks Certified Data Engineer Professional certification exam and start this journey with Databricks Certified Data Engineer Professional Certified-Data-Engineer-Professional practice test questions.
Valid Certified-Data-Engineer-Professional Test Book: https://www.exam-killer.com/Certified-Data-Engineer-Professional-valid-questions.html
- Useful Certified-Data-Engineer-Professional Exam Registration - Easy and Guaranteed Certified-Data-Engineer-Professional Exam Success ⬅️ Search for ➤ Certified-Data-Engineer-Professional ⮘ and download it for free on ➡ www.exam4labs.com ️⬅️ website 🏔Valid Certified-Data-Engineer-Professional Test Notes
- Updated Databricks Certified-Data-Engineer-Professional Exam Questions BUNDLE PACK 🧘 Open ⏩ www.pdfvce.com ⏪ enter ▶ Certified-Data-Engineer-Professional ◀ and obtain a free download 🆔Certified-Data-Engineer-Professional Latest Dumps Sheet
- Pass Guaranteed Quiz 2026 Professional Databricks Certified-Data-Engineer-Professional Exam Registration 🆚 Search for “ Certified-Data-Engineer-Professional ” and download it for free on ▛ www.troytecdumps.com ▟ website 📭Certified-Data-Engineer-Professional Valid Braindumps Questions
- Exam Certified-Data-Engineer-Professional Material 🐘 Valid Certified-Data-Engineer-Professional Test Pattern 💨 VCE Certified-Data-Engineer-Professional Exam Simulator 🔇 Copy URL ⏩ www.pdfvce.com ⏪ open and search for ⇛ Certified-Data-Engineer-Professional ⇚ to download for free 🥜Certified-Data-Engineer-Professional Valid Test Duration
- Valid Certified-Data-Engineer-Professional Test Notes 🐝 Latest Certified-Data-Engineer-Professional Test Testking 🙈 Certified-Data-Engineer-Professional Reliable Test Blueprint 🔣 Search on ▶ www.exam4labs.com ◀ for ⮆ Certified-Data-Engineer-Professional ⮄ to obtain exam materials for free download 💖Valid Certified-Data-Engineer-Professional Test Notes
- Databricks Certified-Data-Engineer-Professional Dumps – Try Free Certified-Data-Engineer-Professional Exam Questions Demo 🔟 Search for ⇛ Certified-Data-Engineer-Professional ⇚ and download exam materials for free through ➡ www.pdfvce.com ️⬅️ 🩸Certified-Data-Engineer-Professional Latest Dumps Sheet
- Certified-Data-Engineer-Professional PDF VCE ⚓ Certified-Data-Engineer-Professional Valid Test Question 📑 Certified-Data-Engineer-Professional Reliable Test Blueprint 😊 Open ▷ www.vceengine.com ◁ enter ⮆ Certified-Data-Engineer-Professional ⮄ and obtain a free download 🤬Valid Certified-Data-Engineer-Professional Test Notes
- Get Access To Databricks Certified-Data-Engineer-Professional Questions Using Three Different Formats 🌲 Copy URL ▶ www.pdfvce.com ◀ open and search for ▛ Certified-Data-Engineer-Professional ▟ to download for free 👪Certified-Data-Engineer-Professional Valid Braindumps Questions
- Certified-Data-Engineer-Professional Latest Dumps Sheet 🚟 VCE Certified-Data-Engineer-Professional Exam Simulator 🗾 Certified-Data-Engineer-Professional Actual Test ◀ Copy URL 「 www.exam4labs.com 」 open and search for ☀ Certified-Data-Engineer-Professional ️☀️ to download for free 🦖Reliable Certified-Data-Engineer-Professional Exam Tutorial
- Confirm Your Success With Free Databricks Certified-Data-Engineer-Professional Exam Questions Updates - Demo 🔗 { www.pdfvce.com } is best website to obtain ▷ Certified-Data-Engineer-Professional ◁ for free download 🙈Reliable Certified-Data-Engineer-Professional Exam Tutorial
- Reliable Certified-Data-Engineer-Professional Exam Tutorial 👴 Certified-Data-Engineer-Professional Valid Test Duration 📣 VCE Certified-Data-Engineer-Professional Exam Simulator 📳 Search on 【 www.practicevce.com 】 for ☀ Certified-Data-Engineer-Professional ️☀️ to obtain exam materials for free download 👼Certified-Data-Engineer-Professional Valid Braindumps Questions
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.bandlab.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, tooter.in, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes