2026 Latest DumpTorrent DP-100 PDF Dumps and DP-100 Exam Engine Free Share: https://drive.google.com/open?id=1oiuUMCVEP9622ofovoZBKczfrtjgWboe
Our DP-100 study materials are compiled and verified by the first-rate experts in the industry domestically and they are linked closely with the real exam. Our products’ contents cover the entire syllabus of the exam and refer to the past years’ exam papers. Our test bank provides all the questions which may appear in the real exam and all the important information about the exam. You can use the practice test software to test whether you have mastered the DP-100 Study Materials and the function of stimulating the exam to be familiar with the real exam’s pace, atmosphere and environment. So our DP-100 study materials are real-exam-based and convenient for the clients to prepare for the exam.
To prepare for the DP-100 exam, candidates must have a solid understanding of data science and machine learning concepts, as well as experience working with Azure data services. They should be familiar with Azure Machine Learning Studio, Azure Databricks, Azure HDInsight, and other relevant Azure technologies. DP-100 exam consists of multiple-choice questions and performance-based tasks that require candidates to demonstrate their ability to design and implement data science solutions in real-world scenarios. The DP-100 Certification is a valuable credential for professionals seeking to advance their careers in data science and machine learning on the Azure platform.
DumpTorrent informs you that the Designing and Implementing a Data Science Solution on Azure (DP-100) questions regularly change the content of the Designing and Implementing a Data Science Solution on Azure real exam. Therefore, you must stay informed as per these changes to save time, money, and mental peace. As was already discussed, DumpTorrent satisfies the needs of Microsoft DP-100 Exam candidates. The customer will receive updates of Designing and Implementing a Data Science Solution on Azure (DP-100) real dumps for up to 365 days after buying the product.
NEW QUESTION # 337
You plan to use the Hyperdrive feature of Azure Machine Learning to determine the optimal hyperparameter values when training a model.
You must use Hyperdrive to try combinations of the following hyperparameter values:
* learning_rate: any value between 0.001 and 0.1
* batch_size: 16, 32, or 64
You need to configure the search space for the Hyperdrive experiment.
Which two parameter expressions should you use? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: B,D
NEW QUESTION # 338
You need to implement a new cost factor scenario for the ad response models as illustrated in the performance curve exhibit.
Which technique should you use?
Answer: A
Explanation:
Scenario:
Performance curves of current and proposed cost factor scenarios are shown in the following diagram:
The ad propensity model uses a cut threshold is 0.45 and retrains occur if weighted Kappa deviated from 0.1
+/- 5%.
Develop models
Testlet 2
Case study
This is a case study. Case studies are not timed separately. You can use as much exam time as you would like to complete each case. However, there may be additional case studies and sections on this exam. You must manage your time to ensure that you are able to complete all questions included on this exam in the time provided.
To answer the questions included in a case study, you will need to reference information that is provided in the case study. Case studies might contain exhibits and other resources that provide more information about the scenario that is described in the case study. Each question is independent of the other questions in this case study.
At the end of this case study, a review screen will appear. This screen allows you to review your answers and to make changes before you move to the next section of the exam. After you begin a new section, you cannot return to this section.
To start the case study
To display the first question in this case study, click the Next button. Use the buttons in the left pane to explore the content of the case study before you answer the questions. Clicking these buttons displays information such as business requirements, existing environment, and problem statements. If the case study has an All Information tab, note that the information displayed is identical to the information displayed on the subsequent tabs. When you are ready to answer a question, click the Question button to return to the question.
Overview
You are a data scientist for Fabrikam Residences, a company specializing in quality private and commercial property in the Unites States. Fabrikam Residences is considering expanding into Europe and has asked you to investigate prices for private residences in major European cities.
You use Azure Machine Learning Studio to measure the median value of properties. You produce a regression model to predict property prices by using the Linear Regression and Bayesian Linear Regression modules.
Datasets
There are two datasets in CSV format that contain property details for two cities, London and Paris. You add both files to Azure Machine Learning Studio as separate datasets to the starting point for an experiment. Both datasets contain the following columns:
An initial investigation shows that the datasets are identical in structure apart from the MedianValue column.
The smaller Paris dataset contains the MedianValue in text format, whereas the larger London dataset contains the MedianValue in numerical format.
Data issues
Missing values
The AccessibilityToHighway column in both datasets contains missing values. The missing data must be replaced with new data so that it is modeled conditionally using the other variables in the data before filling in the missing values.
Columns in each dataset contain missing and null values. The datasets also contain many outliers. The Age column has a high proportion of outliers. You need to remove the rows that have outliers in the Age column.
The MedianValue and AvgRoomsInHouse columns both hold data in numeric format. You need to select a feature selection algorithm to analyze the relationship between the two columns in more detail.
Model fit
The model shows signs of overfitting. You need to produce a more refined regression model that reduces the overfitting.
Experiment requirements
You must set up the experiment to cross-validate the Linear Regression and Bayesian Linear Regression modules to evaluate performance. In each case, the predictor of the dataset is the column named MedianValue. You must ensure that the datatype of the MedianValue column of the Paris dataset matches the structure of the London dataset.
You must prioritize the columns of data for predicting the outcome. You must use non-parametric statistics to measure relationships.
You must a feature selection algorithm to analyze the relationship between the MediaValue and AvgRoomsinHouse columns.
Model training
Permutation Feature Importance
Given a trained model and a test dataset, you must compute the Permutation Feature Importance scores of feature variables. You must be determined the absolute fit for the model.
Hyperparameters
You must configure hyperparameters in the model learning process to speed the learning phase. In addition, this configuration should cancel the lowest performing runs at each evaluation interval, thereby directing effort and resources towards models that are more likely to be successful.
You are concerned that the model might not efficiently use compute resources in hyperparameter tuning. You also are concerned that the model might prevent an increase in the overall tuning time. Therefore, must implement an early stopping criterion on models that provides savings without terminating promising jobs.
Testing
You must produce multiple partitions of a dataset based on sampling using the Partition and Sample module in Azure Machine Learning Studio.
Cross-validation
You must create three equal partitions for cross-validation. You must also configure the cross-validation process so that the rows in the test and training datasets are divided evenly by properties that are near each city's main river. You must complete this task before the data goes through the sampling process.
Linear regression module
When you train a Linear Regression module, you must determine the best features to use in a model. You can choose standard metrics provided to measure performance before and after the feature importance process completes. The distribution of features across multiple training models must be consistent.
Data visualization
You need to provide the test results to the Fabrikam Residences team. You create data visualizations to aid in presenting the results.
You must produce a Receiver Operating Characteristic (ROC) curve to conduct a diagnostic test evaluation of the model. You need to select appropriate methods for producing the ROC curve in Azure Learning Studio to compare the Two-Class Decision Forest and the Two-Class Decision Jungle modules with one another.
Develop models
Question Set 3
NEW QUESTION # 339
You manage an Azure Machine Learning workspace named workspace1 by using the Python SDK v2.
You must register datastores in workspace1 for Azure Blob and Azure Data Lake Gen2 storage to meet the following requirements:
* Data scientists accessing the datastore must have the same level of access.
* Access must be restricted to specified containers or folders.
You need to configure a security access method used to register the Azure Blob and Azure Data lake Gen?
storage in workspace1. Which security access method should you configure? To answer, select the appropriate options in the answers area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation: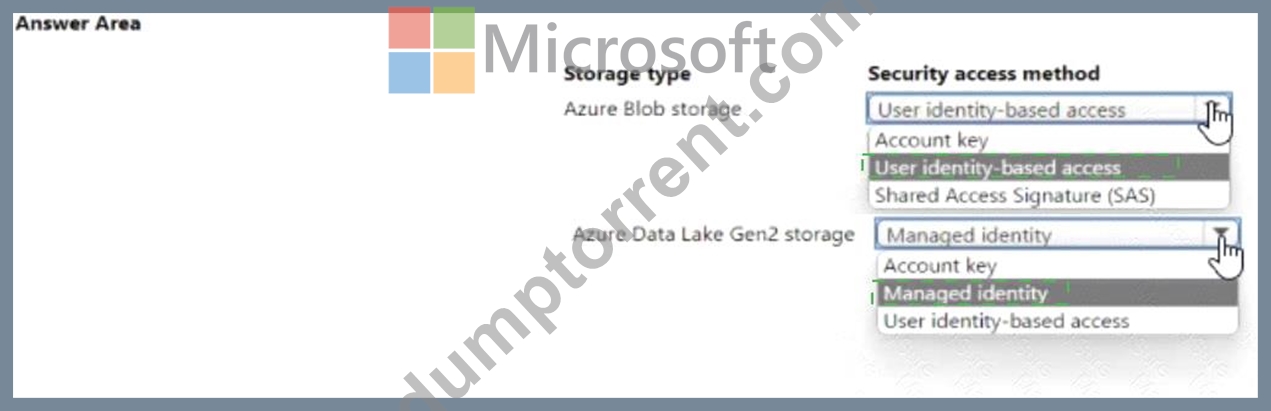
Explanation: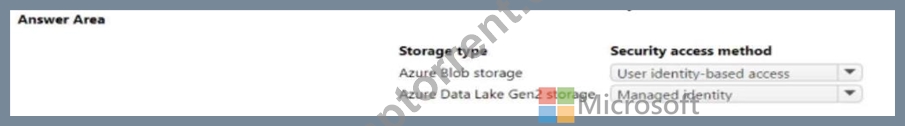
NEW QUESTION # 340
You create an Azure Machine Learning workspace. You use the Azure Machine Learning SDK for Python.
You must create a dataset from remote paths. The dataset must be reusable within the workspace.
You need to create the dataset.
How should you complete the following code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
NEW QUESTION # 341
You are tuning a hyperparameter for an algorithm. The following table shows a data set with different hyperparameter, training error, and validation errors.
Use the drop-down menus to select the answer choice that answers each question based on the information presented in the graphic.
Answer:
Explanation: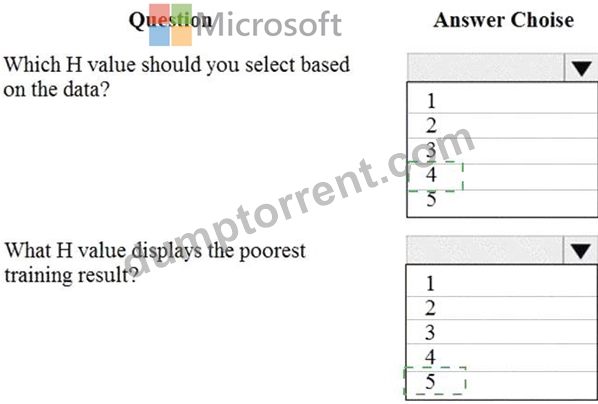
Explanation:
Box 1: 4
Choose the one which has lower training and validation error and also the closest match.
Minimize variance (difference between validation error and train error).
Box 2: 5
Minimize variance (difference between validation error and train error).
Reference:
https://medium.com/comet-ml/organizing-machine-learning-projects-project-management-guidelines-
2d2b85651bbd
NEW QUESTION # 342
......
New DP-100 Exam Question: https://www.dumptorrent.com/DP-100-braindumps-torrent.html
BTW, DOWNLOAD part of DumpTorrent DP-100 dumps from Cloud Storage: https://drive.google.com/open?id=1oiuUMCVEP9622ofovoZBKczfrtjgWboe