JPTestKingを手に入れるのは、MicrosoftのAI-103認定試験に合格する鍵を手に入れるのに等しいです。JPTestKingの MicrosoftのAI-103試験トレーニング資料は高度に認証されたIT領域の専門家の経験と創造を含めているものです。その権威性は言うまでもありません。あなたはうちのMicrosoftのAI-103問題集を購入する前に、JPTestKingは無料でサンプルを提供することができます。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Implement text and speech analysis solutions | 10–15% | - Implement natural language processing
|
| Topic 2: Implement information extraction and knowledge mining | 10–15% | - Build knowledge bases and search solutions
|
| Topic 3: Implement generative AI and agentic solutions | 30–35% | - Build generative AI applications
|
| Topic 4: Plan and manage Azure AI solutions | 25–30% | - Design Azure AI infrastructure
|
| Topic 5: Implement computer vision solutions | 10–15% | - Build multimodal solutions
|
AI-103の実践教材を使用することで、以前に想像していた以上の成果を絶対に得ることができます。 AI-103の実際のテストを選択した顧客から収集された明確なデータがあり、合格率は98〜100%です。 したがって、成功を収めるチャンスは、AI-103ブレインダンプ資料によって大幅に増加します。 さらに、一連の利点があります。 したがって、AI-103の実際のテストの重要性は言うまでもありません。 今すぐご注文いただいた場合、1年間無料の更新をお送りします。
質問 # 30
You have a Microsoft Foundry project that contains a high-traffic agent.
After a recent update, operational costs increase significantly.
Monitoring confirms that the volume of user traffic to the agent remains unchanged.
You suspect that changes to the request or response characteristics are causing the increase.
You need to identify whether the additional costs are driven by the model input size, the model output size, or expanded tool usage.
Which observability capability should you use?
正解:C
解説:
The correct capability is token usage . In Microsoft Foundry observability, token consumption is the primary signal for diagnosing model-cost changes when request volume is unchanged. Token usage lets you distinguish whether costs increased because prompts became larger, retrieved or tool-provided context expanded, responses became longer, or agent execution added more model calls. Microsoft Foundry monitoring dashboards track operational metrics such as token consumption, latency, error rates, and quality scores, and the agent monitoring dashboard is specifically intended to help analyze token usage, latency, success rates, and evaluation outcomes for production traffic.
This directly matches the scenario because the issue is not more traffic, but changed request or response characteristics. Input tokens reveal whether the prompt, chat history, grounding data, or tool outputs being sent to the model increased. Output tokens reveal whether the model is generating longer completions.
Expanded tool usage can also increase cost indirectly by adding more tool results, intermediate calls, and context into subsequent model requests; Foundry tracing and observability capture tool usage and token consumption for agent runs.
Evaluation metrics assess response quality and safety, not cost drivers. Latency identifies performance delays, and run success rate measures reliability. Reference topics: Microsoft Foundry observability, agent monitoring dashboard, token consumption, cost analysis, tool usage, and production monitoring.
質問 # 31
You need to configure the model deployment for Agent1 to meet the technical requirements.
What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.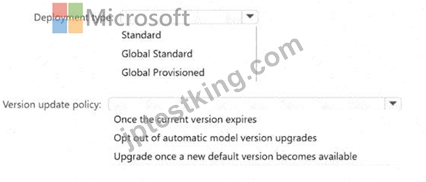
正解:
解説: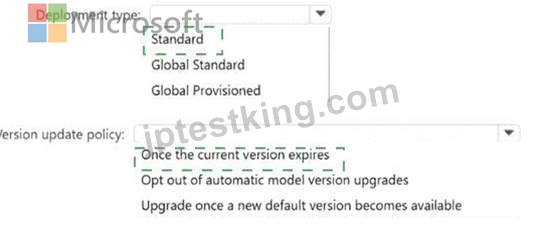
Explanation:
Deployment type: Standard
Version update policy: Once the current version expires
The correct deployment type is Standard . The case study specifies that Project1 is deployed in an EU Azure region and that model-processed data must remain within the EU. It also requires scalable, high-throughput generative AI workloads that dynamically handle variable customer support traffic without reserved throughput capacity. In Microsoft Foundry Models, Standard is a pay-per-token deployment type that processes data in a single Azure region, while Global Standard can process requests across regions and Global Provisioned uses reserved provisioned throughput. Microsoft's deployment-type guidance identifies Standard as single-region, pay-per-token, whereas Global Provisioned is cross-region with reserved capacity.
The correct version update policy is Once the current version expires . This keeps Agent1 on the selected model version during its supported lifecycle, which supports stable and consistent responses, but still preserves continuity by automatically moving to a supported replacement when the current version is retired.
Microsoft's model versioning guidance states that this policy updates only when the current model version expires, while upgrading when a new default is available changes the deployment sooner and opting out can cause the deployment to stop working after retirement. Reference topics: deployment types, regional data processing, model versioning, throughput capacity, and stable production deployments.
質問 # 32
You have a Microsoft Foundry project that generates short promotional product videos.
After several clips are approved, reviewers notice a small watermark in the top-right corner of some videos.
You need to remove the watermark without regenerating the videos.
What should you do?
正解:A
解説:
The correct action to take is to apply a mask-based inpainting edit to the affected part of the video.
This is the only option that directly modifies the existing, approved video files. Inpainting allows you to isolate the specific top-right corner using a mask and seamlessly blend it with the surrounding pixels to erase the watermark without altering or regenerating the rest of the video footage.
Reference:
https://openart.ai/features/ai-video-inpainting/
質問 # 33
You have a configurable guardrail in a Microsoft Foundry project.
You have a Python application. A text blocklist named Conf identialTerns already contains terms that must be detected in user messages. The application stores each incoming user message in a variable named inpot_text.
You plan to moderate input_text before the text is sent to a language model.
You need to analyze input_text by using the existing blocklist.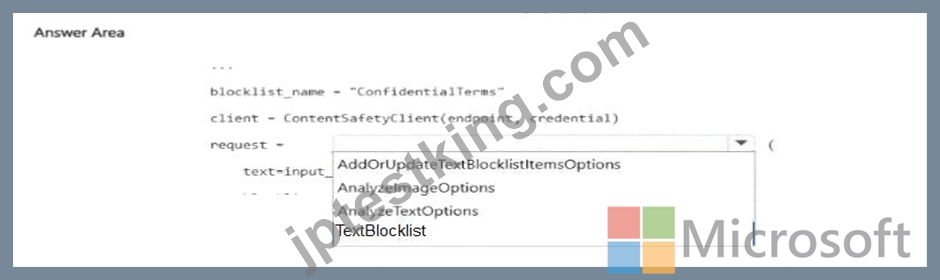
正解:
解説: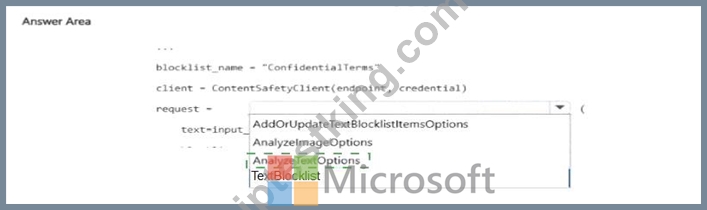
Explanation:
AnalyzeTextOptions
request = AnalyzeTextOptions(
text=input_text,
blocklist_names=[blocklist_name],
halt_on_blocklist_hit=True
)
response = client.analyze_text(request)
AnalyzeTextOptions is the request model used by the Azure AI Content Safety Python SDK to submit text for moderation. Its text property contains the user message, while blocklist_names identifies one or more existing custom blocklists that must be applied during analysis. The value must be supplied as a list, so the correct assignment is [blocklist_name]. The request is then passed to ContentSafetyClient.analyze_text(), which returns an AnalyzeTextResult containing any blocklist matches and applicable harm-category analysis.
Setting halt_on_blocklist_hit=True stops additional harm-category processing when a blocklisted term is detected. This is appropriate when a blocklist match alone is sufficient to prevent the message from reaching the language model.
AddOrUpdateTextBlocklistItemsOptions manages terms within a blocklist; it does not analyze input.
AnalyzeImageOptions is intended for image moderation, and TextBlocklist represents blocklist metadata rather than a text-analysis request.
Study Guide alignment: configure safety filters, guardrails, blocklists, risk detection, and content moderation for Azure AI applications.
質問 # 34
You have a Microsoft Foundry project that contains two agents named PolicyWriter and RiskReviewer.
PolicyWriter generates draft updates for customer policies, and RiskReviewer reviews the drafts. In the visual builder, you need to create a workflow that meets the following requirements:
* Finalizes low-risk updates without manual intervention
* Ensures predictable execution across the agents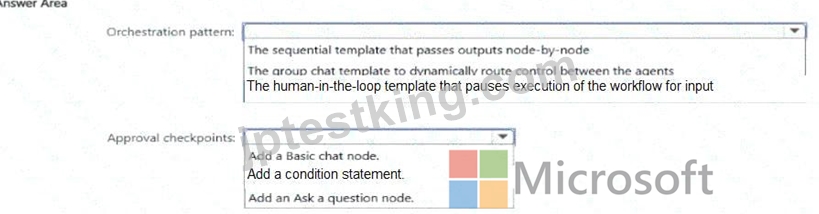
正解:
解説: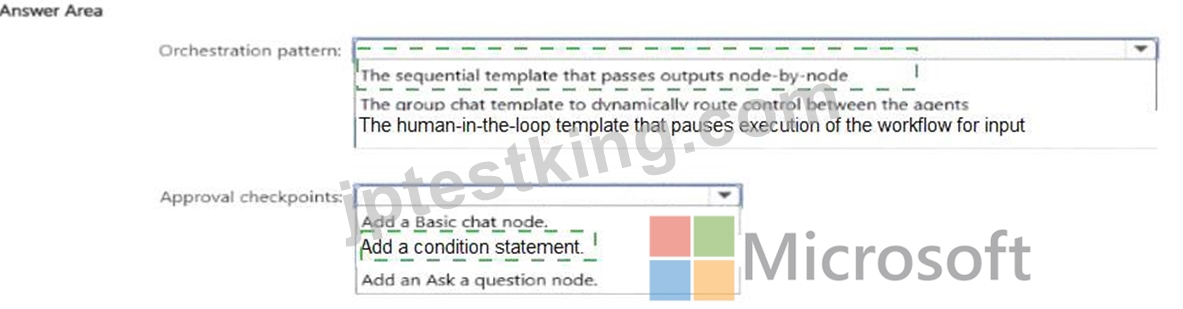
Explanation:
* Orchestration pattern: The sequential template that passes outputs node-by-node
* Approval checkpoints: Add a condition statement
Use the sequential orchestration template because the agents must execute in a fixed, predictable order.
PolicyWriter first generates the proposed policy update, and its output is then passed directly to RiskReviewer. Microsoft defines the sequential pattern as passing the result from one agent to the next in a defined order, making it appropriate for deterministic, multistage processing. The group-chat pattern would allow control to move dynamically between agents, which would reduce execution predictability.
After RiskReviewer returns a structured risk classification, add a condition statement that evaluates the result. The low-risk branch can proceed directly to the finalization action without requesting human input. A separate higher-risk branch can route to an approval step, such as an Ask a question node. Adding an Ask a question node without conditional branching would pause every workflow execution, including low-risk updates, and therefore would not satisfy the automation requirement. Microsoft Foundry workflows support if
/else branching and condition expressions for selecting the next action.
Study Guide alignment: implement orchestrated multi-agent solutions and build autonomous or semiautonomous workflows with safeguards and approval-flow controls .
質問 # 35
......
当社JPTestKingのAI-103試験資料は、約98%〜100%の高い合格率と、高い合格率の両方を高めて、テストに合格するのがほとんど困難ではないことを示しています。 AI-103試験シミュレーションは、認定された専門家の勤勉な労働者からのリソースと実際の試験に基づいて編集され、過去数年の試験用紙を授与するため、非常に実用的です。 AI-103試験問題の質問と回答の内容は洗練されており、最も重要な情報に焦点を当てています。クライアントが実際のAI-103試験の雰囲気とペースに慣れるために、試験を刺激する機能を提供します。
AI-103的中関連問題: https://www.jptestking.com/AI-103-exam.html