P.S. Free 2026 Microsoft DP-750 dumps are available on Google Drive shared by Pass4SureQuiz: https://drive.google.com/open?id=1cDb6tMYH3f5PzltdX70Hhh0nIuyzX7Io
Candidates who don't find actual DP-750 Questions remain unsuccessful in the Microsoft DP-750 test and lose their resources. That's why Pass4SureQuiz is offering real DP-750 Questions that are real and can save you from wasting time and money. Hundreds of applicants have studied successfully from our DP-750 Latest Questions in one go.
| Section | Weight | Objectives |
|---|---|---|
| Configure and manage Azure Databricks environments | 15-20% | - Security and authentication setup
|
| Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
| Deploy and manage data pipelines and workloads | 30-35% | - Operational reliability
|
| Prepare and process data | 30-35% | - Data ingestion
|
These practice tools are developed by professionals who work in fields impacting Microsoft certification, giving them a foundation of knowledge and actual competence. Our Microsoft DP-750 Exam Questions are created and curated by industry specialists. Pass4SureQuiz Is Here To Provide Top-Notch Microsoft DP-750 Exam Questions
NEW QUESTION # 60
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named catalog1.
You have a group named group1.
You plan to create a schema named schema1 in catalog1.
You need to ensure that group1 meets the following requirements:
- Can create tables in schema1
- Can modify and query tables
- Cannot grant permissions for the schema and its objects
How should you complete the SQL statements? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.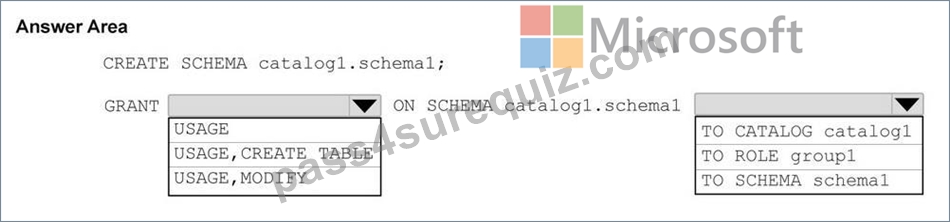
Answer:
Explanation: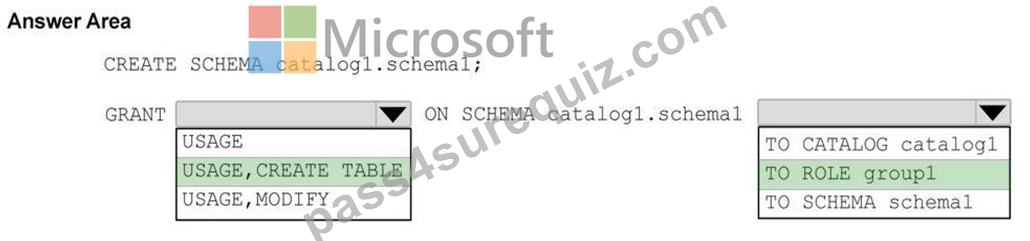
NEW QUESTION # 61
You have an Azure Databricks workspace that contains a Git folder and uses Azure Repos as the Git provider.
From the main branch, you create a branch named Branch1. You commit changes to Branch1.
You need to incorporate the changes from Branch1 into main. The solution must preserve the commit history in the repository.
Which command should you run?
Answer: A
Explanation:
To incorporate changes from your feature branch into the main branch while keeping every individual commit intact, you must use a fast-forward merge or a standard merge commit.
In the Azure Databricks Git folders UI or via standard Git operations, use the following command:
The Correct Command: git merge <branch-name>
Preserves History: Unlike a squash merge, a standard merge keeps all individual commit messages, authors, and timestamps.
Maintains Timeline: It seamlessly integrates the exact commit graph from your feature branch into the main branch.
Reference:
https://docs.databricks.com/aws/en/repos/git-operations-with-repos
NEW QUESTION # 62
You have an Azure Databricks workspace that contains a Delta table named Table1.
Table1 has accumulated obsolete files.
You need to reduce storage costs. The solution must preserve 30 days of time travel history.
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: A,D
Explanation:
To diminish storage costs while preserving 60 days of time travel history, you must perform the following two actions: Set the delta.deletedFileRetentionDuration table property to 60 days and Run the vacuum command on the table.
Set the delta.deletedFileRetentionDuration table property to 30 days
This property controls how long data files must be deleted before they become eligible for removal by a cleanup process. By default, it is set to 7 days. Increasing it to 60 days ensures that Delta Lake preserves the underlying parquet files required to query any historical snapshot within your 30-day time travel window.
Run the vacuum command on the tableChanging the retention property alone does not delete files or reduce costs. You must explicitly execute the VACUUM command. The command scans the table and permanently deletes uncommitted or deleted data files that are older than the 60- day threshold defined by your retention duration, thereby freeing up storage space.
Incorrect:
[Not C]
Set the delta.logRetentionDuration table property to 30 days
This property controls how long the transaction log (_delta_log) history is kept, which defaults to
30 days. While the transaction log is required for time travel, modifying this property alone does not delete the heavy data files causing high storage costs. Furthermore, it governs the logs rather than the actual deleted data files.
Reference:
https://www.cloudmatter.io/post/data-audit-with-databricks-delta-time-travel
NEW QUESTION # 63
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named db1.sales_orders.
db1.sales_orders is updated nightly and has change data feed (CDF) enabled.
You need to ingest all the changes from the db1.sales_orders table, including inserts, updates, and deletes, into a downstream pipeline.
How should you complete the PsySpark code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.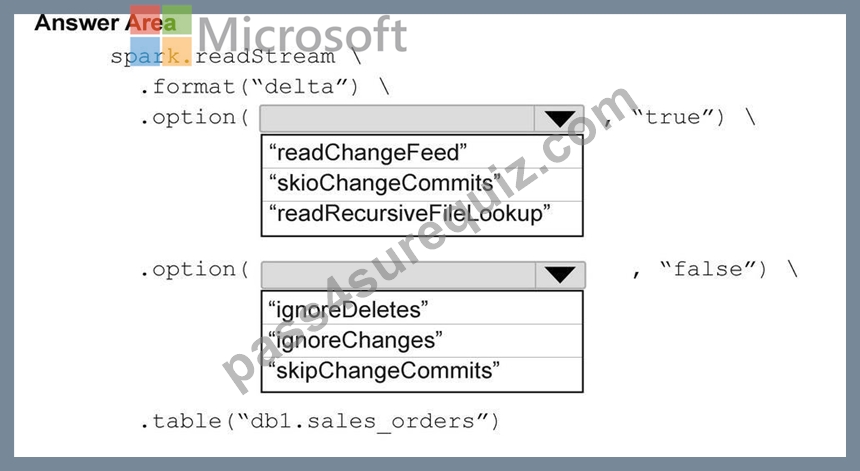
Answer:
Explanation: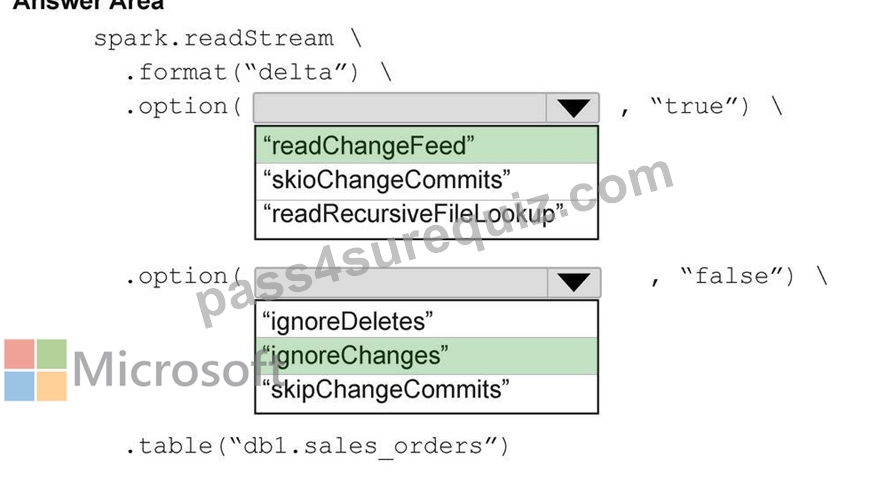
NEW QUESTION # 64
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df-fillna(0, subset=['order_amount'])
Does this meet the goal?
Answer: B
Explanation:
The correct answer is B - No.
df.fillna(0, subset=['order_amount']) does not remove null rows. It replaces null values in order_amount with the integer 0, leaving those rows in the DataFrame with 0 as their order_amount value. The row count is unchanged - nulls are imputed, not dropped.
The requirement is to exclude rows where order_amount is null, meaning those rows should not appear in the result at all. fillna is a data imputation function - it fills gaps with default values, which is a different operation entirely from filtering. After fillna, a downstream process would see order_amount = 0 and might treat it as a valid zero-value order rather than recognising it was originally null.
The correct approach is df.dropna(subset=['order_amount']) or df.filter(df.order_amount.isNotNull()), both of which physically remove null rows from the resulting DataFrame.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
NEW QUESTION # 65
......
Pass4SureQuiz Microsoft DP-750 exam information are cheap and fine. We use simulation questions and answers dedication to our candidates with ultra-low price and high quality. We sincerely hope that you can pass the exam. We provide you with a convenient online service to resolve any questions about Microsoft DP-750 Exam Questions for you.
DP-750 Pass Guarantee: https://www.pass4surequiz.com/DP-750-exam-quiz.html
BONUS!!! Download part of Pass4SureQuiz DP-750 dumps for free: https://drive.google.com/open?id=1cDb6tMYH3f5PzltdX70Hhh0nIuyzX7Io