What's more, part of that Dumpexams DP-600 dumps now are free: https://drive.google.com/open?id=1eqR63Wlfp0xYqv0xWzayXcm8wkIXOnut
The versions of our DP-600 study guide includes the PDF version, PC version, APP online version. Each version's using method and functions are different and the client can choose the most convenient version to learn our DP-600 exam materials. For example, the PDF version is convenient for you to download and print our DP-600 Test Questions and is suitable for browsing learning. If you use the PDF version you can print our DP-600 test torrent on the papers and it is convenient for you to take notes. You can learn our DP-600 test questions at any time and place.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
It is a truth well-known to all around the world that no pains and no gains. There is another proverb that the more you plough the more you gain. When you pass the DP-600 exam which is well recognized wherever you are in any field, then acquire the DP-600 certificate, the door of your new career will be open for you and your future is bright and hopeful. Our DP-600 guide torrent will be your best assistant to help you gain your certificate.
NEW QUESTION # 39
You have a Microsoft Power Bl semantic model.
You plan to implement calculation groups.
You need to create a calculation item that will change the context from the selected date to month-to-date (MTD).
How should you complete the DAX expression? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
To create a calculation item that changes the context from the selected date to month-to-date (MTD), the appropriate DAX expression involves using the CALCULATE function to alter the filter context and the DATESMTD function to specify the month-to-date context.
The correct completion for the DAX expression would be:
In the first dropdown, select CALCULATE.
In the second dropdown, select SELECTEDMEASURE.
This would create a DAX expression in the form:
CALCULATE(
SELECTEDMEASURE(),
DATESMTD('Date'[DateColumn])
)
NEW QUESTION # 40
When monitoring data flow performance, which of the following should be looked for possible bottlenecks? (Select Two)
Answer: B,D
Explanation:
Cluster start-up time is a significant potential bottleneck because it involves the time required to spin up an Apache Spark cluster. Data flows operate on a just-in-time model where each job uses an isolated cluster, and this start-up time typically takes 3-5 minutes. Reducing this start-up time can improve overall data flow performance Transformation time is another critical bottleneck to monitor. It refers to the time taken for each transformation stage in the data flow. If a transformation stage takes the longest time, it indicates a need for optimization, such as repartitioning data or increasing the integration runtime size to enhance performance.
Reference:
https://learn.microsoft.com/en-us/azure/data-factory/concepts-data-flow-performance
NEW QUESTION # 41
You have a Fabric tenant that contains a lakehouse.
You are using a Fabric notebook to save a large DataFrame by using the following code.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.
Answer:
Explanation: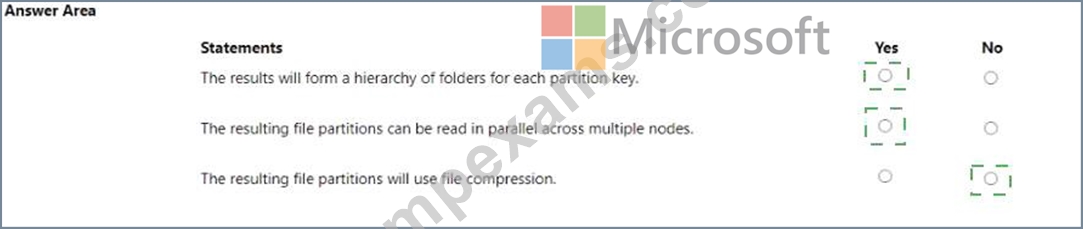
Explanation:
* The results will form a hierarchy of folders for each partition key. - Yes
* The resulting file partitions can be read in parallel across multiple nodes. - Yes
* The resulting file partitions will use file compression. - No
Partitioning data by columns such as year, month, and day, as shown in the DataFrame write operation, organizes the output into a directory hierarchy that reflects the partitioning structure. This organization can improve the performance of read operations, as queries that filter by the partitioned columns can scan only the relevant directories. Moreover, partitioning facilitates parallelism because each partition can be processed independently across different nodes in a distributed system like Spark. However, the code snippet provided does not explicitly specify that file compression should be used, so we cannot assume that the output will be compressed without additional context.
References =
* DataFrame write partitionBy
* Apache Spark optimization with partitioning
NEW QUESTION # 42
Case Study 2 - Litware, Inc
Overview
Litware, Inc. is a manufacturing company that has offices throughout North America. The analytics team at Litware contains data engineers, analytics engineers, data analysts, and data scientists.
Existing Environment
Fabric Environment
Litware has been using a Microsoft Power BI tenant for three years. Litware has NOT enabled any Fabric capacities and features.
Available Data
Litware has data that must be analyzed as shown in the following table.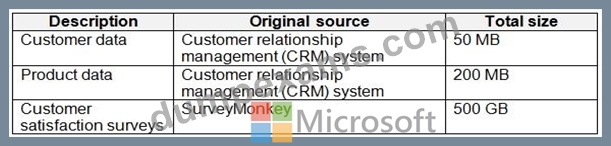
The Product data contains a single table and the following columns.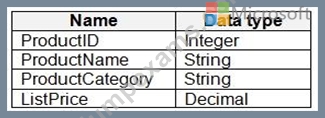
The customer satisfaction data contains the following tables:
- Survey
- Question
- Response
For each survey submitted, the following occurs:
- One row is added to the Survey table.
- One row is added to the Response table for each question in the survey.
- The Question table contains the text of each survey question. The third question in each survey response is an overall satisfaction score. Customers can submit a survey after each purchase.
User Problems
The analytics team has large volumes of data, some of which is semi-structured. The team wants to use Fabric to create a new data store.
Product data is often classified into three pricing groups: high, medium, and low. This logic is implemented in several databases and semantic models, but the logic does NOT always match across implementations.
Requirements
Planned Changes
Litware plans to enable Fabric features in the existing tenant. The analytics team will create a new data store as a proof of concept (PoC). The remaining Liware users will only get access to the Fabric features once the PoC is complete. The PoC will be completed by using a Fabric trial capacity The following three workspaces will be created:
- AnalyticsPOC: Will contain the data store, semantic models, reports pipelines, dataflow, and notebooks used to populate the data store
- DataEngPOC: Will contain all the pipelines, dataflows, and notebooks used to populate OneLake
- DataSciPOC: Will contain all the notebooks and reports created by the data scientists The following will be created in the AnalyticsPOC workspace:
- A data store (type to be decided)
- A custom semantic model
- A default semantic model
Interactive reports
The data engineers will create data pipelines to load data to OneLake either hourly or daily depending on the data source. The analytics engineers will create processes to ingest, transform, and load the data to the data store in the AnalyticsPOC workspace daily. Whenever possible, the data engineers will use low-code tools for data ingestion. The choice of which data cleansing and transformation tools to use will be at the data engineers' discretion.
All the semantic models and reports in the Analytics POC workspace will use the data store as the sole data source.
Technical Requirements
The data store must support the following:
- Read access by using T-SQL or Python
- Semi-structured and unstructured data
- Row-level security (RLS) for users executing T-SQL queries
Files loaded by the data engineers to OneLake will be stored in the Parquet format and will meet Delta Lake specifications.
Data will be loaded without transformation in one area of the AnalyticsPOC data store. The data will then be cleansed, merged, and transformed into a dimensional model The data load process must ensure that the raw and cleansed data is updated completely before populating the dimensional model The dimensional model must contain a date dimension. There is no existing data source for the date dimension. The Litware fiscal year matches the calendar year. The date dimension must always contain dates from 2010 through the end of the current year.
The product pricing group logic must be maintained by the analytics engineers in a single location. The pricing group data must be made available in the data store for T-SOL. queries and in the default semantic model. The following logic must be used:
- List prices that are less than or equal to 50 are in the low pricing group.
- List prices that are greater than 50 and less than or equal to 1,000 are in the medium pricing group.
- List prices that are greater than 1,000 are in the high pricing group.
Security Requirements
Only Fabric administrators and the analytics team must be able to see the Fabric items created as part of the PoC.
Litware identifies the following security requirements for the Fabric items in the AnalyticsPOC workspace:
- Fabric administrators will be the workspace administrators.
- The data engineers must be able to read from and write to the data store. No access must be granted to datasets or reports.
- The analytics engineers must be able to read from, write to, and create schemas in the data store. They also must be able to create and share semantic models with the data analysts and view and modify all reports in the workspace.
- The data scientists must be able to read from the data store, but not write to it. They will access the data by using a Spark notebook
- The data analysts must have read access to only the dimensional model objects in the data store. They also must have access to create Power BI reports by using the semantic models created by the analytics engineers.
- The date dimension must be available to all users of the data store.
- The principle of least privilege must be followed.
Both the default and custom semantic models must include only tables or views from the dimensional model in the data store. Litware already has the following Microsoft Entra security groups:
FabricAdmins: Fabric administrators
- AnalyticsTeam: All the members of the analytics team
- DataAnalysts: The data analysts on the analytics team
- DataScientists: The data scientists on the analytics team
- DataEngineers: The data engineers on the analytics team
- AnalyticsEngineers: The analytics engineers on the analytics team
Report Requirements
The data analysts must create a customer satisfaction report that meets the following requirements:
- Enables a user to select a product to filter customer survey responses to only those who have purchased that product.
- Displays the average overall satisfaction score of all the surveys submitted during the last 12 months up to a selected dat.
- Shows data as soon as the data is updated in the data store.
- Ensures that the report and the semantic model only contain data from the current and previous year.
- Ensures that the report respects any table-level security specified in the source data store.
- Minimizes the execution time of report queries.
Hotspot Question
You need to create a DAX measure to calculate the average overall satisfaction score.
How should you complete the DAX code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
NEW QUESTION # 43
You need to refresh the Orders table of the Online Sales department. The solution must meet the semantic model requirements. What should you include in the solution?
Answer: B
NEW QUESTION # 44
......
Dumpexams has a strong IT elite team. They use their professional eyes searching the latest DP-600 braindumps and DP-600 certification training materials. With them, you can save more time to study and pass the DP-600 Exam. After you purchase our DP-600 exam dumps, we will offer free update service in one year.
DP-600 Cost Effective Dumps: https://www.dumpexams.com/DP-600-real-answers.html
DOWNLOAD the newest Dumpexams DP-600 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1eqR63Wlfp0xYqv0xWzayXcm8wkIXOnut