
DOWNLOAD the newest iPassleader MLA-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1tuNrHl510FgZkkf-1GI-W_XctJUUyns7
With the development of society and the perfection of relative laws and regulations, the MLA-C01 certificate in our career field becomes a necessity for our countryPassing the MLA-C01 and obtaining the certificate may be the fastest and most direct way to change your position and achieve your goal. And we are just right here to give you help. Being considered the most authentic brand in this career, our professional experts are making unremitting efforts to provide our customers the latest and valid MLA-C01 Exam simulation.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
>> Testking Amazon MLA-C01 Exam Questions <<
You can get a complete new and pleasant study experience with our MLA-C01 exam preparation for the efforts that our experts devote themselves to make. They have compiled three versions of our MLA-C01study materials: the PDF, the Software and the APP online. So you are able to study the online test engine by your cellphone or computer, and you can even study MLA-C01 Exam Preparation at your home, company or on the subway, you can make full use of your fragmentation time in a highly-efficient way.
NEW QUESTION # 110
An airline company deploys ML models to one dozen Amazon SageMaker Al inference endpoints. The inference endpoints must be able to handle different types of workloads in a cost-effective way.
Select the correct inference option from the following list to handle each type of workload. Select each inference option one time. (Select FOUR.)
* Asynchronous inference
* Batch inference
* Real-time inference
* Serverless inference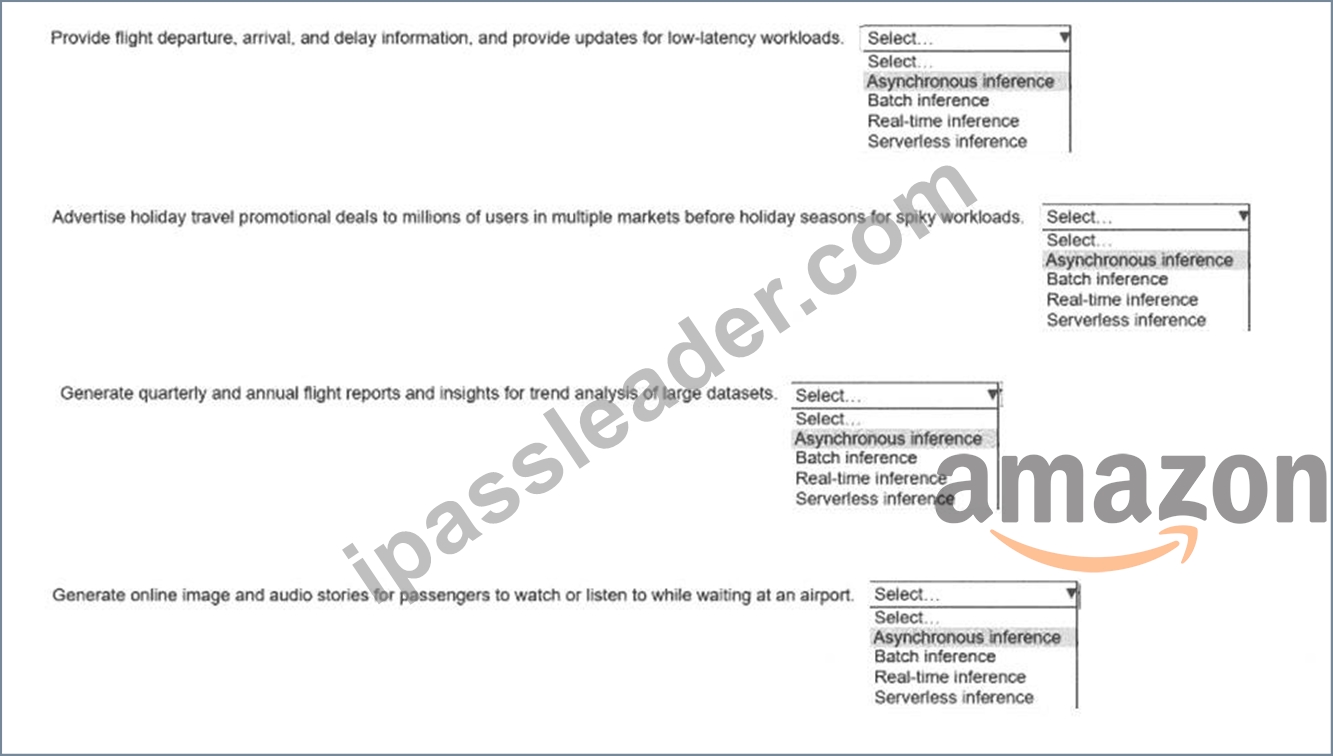
Answer:
Explanation: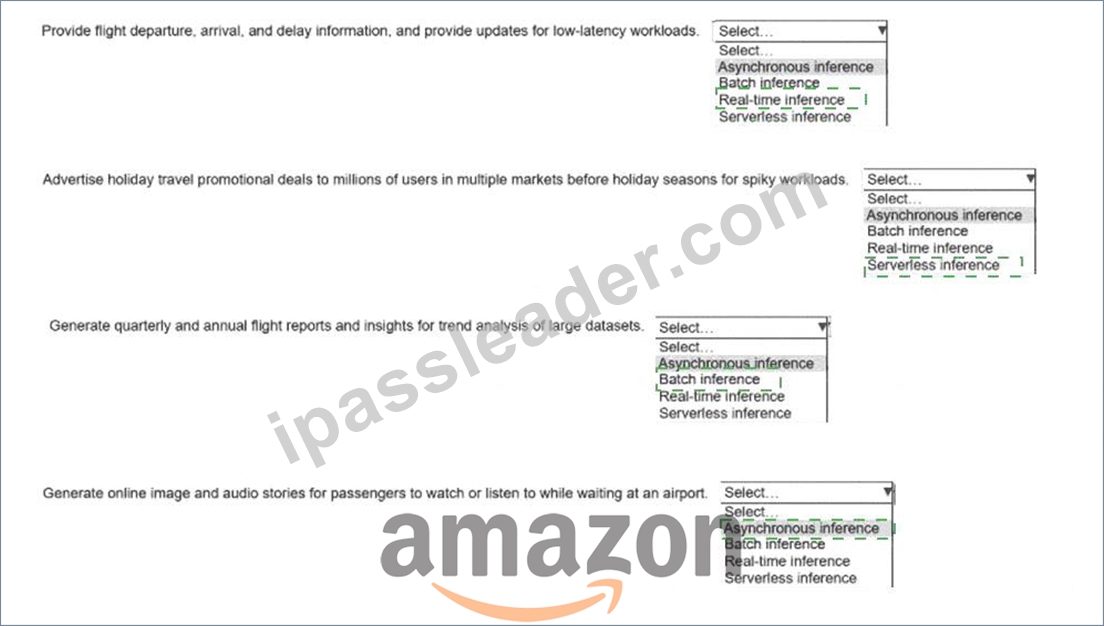
* Provide flight departure, arrival, and delay information, and provide updates for low-latency workloads# Real-time inference
* Advertise holiday travel promotional deals to millions of users in multiple markets before holiday seasons for spiky workloads# Serverless inference
* Generate quarterly and annual flight reports and insights for trend analysis of large datasets# Batch inference
* Generate online image and audio stories for passengers to watch or listen to while waiting at an airport# Asynchronous inference
* The correct mapping depends on latency requirement, traffic pattern, payload size, processing duration, and whether the workload needs a persistent endpoint.
* Real-time inference is the right choice for flight departure, arrival, and delay updates because this is an online user-facing workload that requires low latency. AWS states that SageMaker real-time inference is ideal for online inference workloads with low-latency or high-throughput requirements and uses a persistent fully managed endpoint. That fits flight status information because passengers and airline systems expect immediate responses.
* Serverless inference is the best choice for holiday promotional deals because this traffic is spiky, seasonal, and unpredictable. AWS describes SageMaker Serverless Inference as suitable for intermittent or unpredictable traffic patterns. It is cost-effective because SageMaker manages the infrastructure and scales down when there are no requests, so the company does not pay for idle endpoint capacity.
* Batch inference is correct for quarterly and annual flight reports because this workload analyzes large datasets offline and does not need an always-running endpoint. AWS says SageMaker batch transform is used to get inferences from large datasets and when a persistent endpoint is not required. Reports and trend analysis are scheduled, non-real-time analytics workloads, so batch inference is the most cost- effective option.
* Asynchronous inference is the right choice for generating online image and audio stories. These requests can have larger payloads and longer processing times than normal low-latency API calls. AWS states that SageMaker Asynchronous Inference queues incoming requests and is ideal for large payloads, long processing times, and near-real-time latency requirements. Image and audio generation can take seconds or minutes, so asynchronous inference is more appropriate than real-time inference.
NEW QUESTION # 111
A company wants to use large language models (LLMs) that are supported by Amazon Bedrock to develop a chat interface for the company ' s internal technical documentation. The company stores the documentation as dozens of text files that are several megabytes in total size. The company updates the text files often.
Which solution will meet these requirements MOST cost-effectively?
Answer: A
Explanation:
Option D is correct because Amazon Bedrock Knowledge Bases are designed for applications that need to answer questions using private documents without retraining or repeatedly fine-tuning a foundation model.
AWS documentation states that with Amazon Bedrock Knowledge Bases, you can build applications enriched by context retrieved from a knowledge base, and that this provides an out-of-the-box RAG solution. AWS also explicitly says that adding a knowledge base increases cost-effectiveness by removing the need to continually train your model to use your private data. That matches this use case very closely.
The question also says the documentation consists of text files that are only several megabytes total and are updated often. A retrieval-based approach is more economical and operationally simpler than creating a new model or repeatedly fine-tuning one whenever the documents change. AWS documentation for Bedrock knowledge bases describes adding data sources and running ingestion jobs to process and index the content, which is exactly the pattern needed for frequently updated internal documentation used by a chat interface.
The other options are not as cost-effective. Creating a new LLM is far beyond the need here. Guardrails help control model behavior and policy enforcement, but they do not serve as a document retrieval layer for internal documentation. Fine-tuning a model on frequently changing text files is usually more expensive and less flexible than using retrieval augmentation. For a modest-sized, frequently updated documentation corpus, the AWS-native and most cost-effective solution is to load the files into an Amazon Bedrock knowledge base and use it to provide context at inference time. Therefore, the best verified answer is D.
NEW QUESTION # 112
An ML engineer is training an ML model to identify medical patients for disease screening. The tabular dataset for training contains 50,000 patient records: 1,000 with the disease and 49,000 without the disease.
The ML engineer splits the dataset into a training dataset, a validation dataset, and a test dataset.
What should the ML engineer do to transform the data and make the data suitable for training?
Answer: D
Explanation:
This dataset shows severe class imbalance, with only 2% of records representing patients with the disease.
AWS ML best practices recommend correcting imbalance only in the training dataset, while keeping validation and test sets representative of real-world distributions.
Synthetic Minority Oversampling Technique (SMOTE) generates synthetic samples of the minority class by interpolating between existing minority examples. This improves the model's ability to learn disease-related patterns without discarding data.
PCA is a dimensionality reduction method, not an oversampling technique. Oversampling the majority class worsens imbalance. Altering the test dataset would invalidate evaluation results.
Therefore, applying SMOTE to the training dataset is the correct approach.
NEW QUESTION # 113
An ML engineer wants to use Amazon SageMaker Data Wrangler to perform preprocessing on a dataset. The ML engineer wants to use the processed dataset to train a classification model. During preprocessing, the ML engineer notices that a text feature has a range of thousands of values that differ only by spelling errors. The ML engineer needs to apply an encoding method so that after preprocessing is complete, the text feature can be used to train the model.
Which solution will meet these requirements?
Answer: B
Explanation:
The text feature contains high-cardinality categorical values with minor spelling variations, which is a common real-world data quality issue. Traditional encoding techniques such as ordinal encoding (Option A) or one-hot encoding (Option C) would treat each misspelled value as a completely separate category, resulting in poor generalization and very high dimensionality.
Similarity encoding addresses this problem by grouping or encoding categories based on string similarity.
Categories that differ only slightly-such as spelling errors-are encoded with similar numerical representations. Amazon SageMaker Data Wrangler supports similarity encoding specifically for such noisy categorical features.
Target encoding (Option D) depends on the target label distribution and risks target leakage if not carefully applied.
Therefore, similarity encoding is the most appropriate and AWS-recommended solution.
NEW QUESTION # 114
An ML engineer trained an ML model on Amazon SageMaker to detect automobile accidents from dosed- circuit TV footage. The ML engineer used SageMaker Data Wrangler to create a training dataset of images of accidents and non-accidents.
The model performed well during training and validation. However, the model is underperforming in production because of variations in the quality of the images from various cameras.
Which solution will improve the model's accuracy in the LEAST amount of time?
Answer: A
Explanation:
The model is underperforming in production due to variations in image quality from different cameras. Using the corrupt image transform with the impulse noise option in SageMaker Data Wrangler simulates real-world noise and variations in the training dataset. This approach helps the model become more robust to inconsistencies in image quality, improving its accuracy in production without the need to collect and process new data, thereby saving time.
NEW QUESTION # 115
......
In order to pass the exam and fight for a brighter future, these people who want to change themselves need to put their ingenuity and can do spirit to work. More importantly, it is necessary for these people to choose the convenient and helpful MLA-C01 test questions as their study tool in the next time. Because their time is not enough to prepare for the exam, and a lot of people have difficulty in preparing for the exam, so many people who want to pass the MLA-C01 exam and get the related certification in a short time have to pay more attention to the study materials. In addition, best practice indicates that people who have passed the MLA-C01 Exam would not pass the exam without the help of the MLA-C01 reference guide. So the study materials will be very important for all people. If you also want to pass the exam and get the related certification in a short, the good study materials are the best choice for you. Now we are going to make an introduction about the MLA-C01 exam prep from our company for you.
MLA-C01 Online Bootcamps: https://www.ipassleader.com/Amazon/MLA-C01-practice-exam-dumps.html
P.S. Free 2026 Amazon MLA-C01 dumps are available on Google Drive shared by iPassleader: https://drive.google.com/open?id=1tuNrHl510FgZkkf-1GI-W_XctJUUyns7