We strongly advise you to buy our windows software of the AI-200 study materials, which can simulate the real test environment. There is no doubt that you will never feel bored on learning our AI-200 practice materials because of the smooth operation. You will find that learning is becoming interesting and easy. During the operation of the AI-200 Study Materials on your computers, the running systems of the AI-200 study guide will be flexible, which saves you a lot of troubles and help you concentrate on study.
| Section | Objectives |
|---|---|
| Topic 1: Connect to and consume Azure services | - Integrate Azure services
|
| Topic 2: Develop containerized solutions on Azure | - Implement containerized applications
|
| Topic 3: Secure, monitor, troubleshoot Azure solutions | - Operate AI cloud solutions
|
| Topic 4: Develop AI solutions by using Azure data management services | - Work with Azure data platforms for AI workloads
|
>> AI-200 Exam Sample Questions <<
If you are going to buy AI-200 training materials online, the security of the website is important. We have technicians to examine the website every day, if you chose us, we provide you with a clean and safe online shopping environment. In addition, AI-200 exam materials are compiled by professional experts, and therefore the quality can be guaranteed. We offer you free demo to have a try before buying, so that you can have a deeper understanding of what you are going to buy. AI-200 Training Materials contain also have certain number of questions, and if will be enough for you to pass the exam. We have online and offline chat service stuff, if you have any questions, you can consult us.
NEW QUESTION # 105
You need to improve throughput for concurrent application requests to PostgreSQL.
What should you implement?
Answer: B
Explanation:
The correct solution is to implement connection pooling , ideally by using the built-in PgBouncer capability in Azure Database for PostgreSQL Flexible Server. Connection pooling allows many concurrent application requests to share and reuse a smaller set of established PostgreSQL server connections instead of repeatedly opening and closing database sessions. Microsoft notes that creating a new PostgreSQL connection for each operation consumes server resources because each connection involves its own backend process. Reusing pooled connections therefore reduces connection overhead, lowers CPU and memory consumption, and improves throughput for high-concurrency workloads.
This directly matches Fabrikam ' s stated requirement that database connections support high concurrency with minimal latency through connection optimization . PgBouncer can efficiently multiplex large numbers of client connections onto fewer PostgreSQL connections, particularly in transaction pooling mode.
Increasing max_connections is not the preferred solution because each additional PostgreSQL connection consumes memory and other resources; Microsoft explicitly recommends PgBouncer instead when more concurrent connections are required. Increasing shared_buffers addresses caching and memory allocation rather than connection-management overhead. Read replicas can scale read workloads, but they do not optimize the application ' s connection lifecycle.
Study Guide references: Azure Database for PostgreSQL Flexible Server # connection pooling; PgBouncer; connection management and high-concurrency performance.
NEW QUESTION # 106
You process Azure Service Bus messages that require a dependent external API call.
If the API is temporarily unavailable, you must delay processing of the message without incrementing the delivery count. You need to find a way to process the message when the API is available while keeping the message accessible. Which message action should you perform?
Answer: C
Explanation:
Detailed Explanation: Deferral is intended for a message that cannot be processed now because a particular dependency is temporarily unavailable, while the application wants to keep the message in the main queue for later retrieval by sequence number. Complete would permanently remove it, dead-letter would move it aside as a failed message, and abandon immediately releases the lock for redelivery. Deferral therefore best matches the requirement to postpone the individual message while keeping it available for deliberate later processing.
Study Guide Alignment: Azure service integration: Service Bus, Event Grid, Azure Functions triggers
/bindings, and event-driven processing.
Official Microsoft Learn References: AI-200 Study Guide | Service Bus message deferral | Service Bus message transfers, locks, and settlement
NEW QUESTION # 107
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
You are preparing a production deployment for an Azure Function app. The app will run across multiple environments.
The solution must support environment-specific configuration and prevent secrets from being stored in source control.
You need to develop the solution.
Solution: Store connection strings in the Function app application settings configured in the Azure Portal.
Does the solution meet the goal?
Answer: B
Explanation:
Correct:
* Use App Configuration with Key Vault references to store environment-specific settings and secrets, accessed from the function app by using a managed identity.
This is an industry-standard best practice architectural pattern.
Using Azure App Configuration combined with Azure Key Vault references completely satisfies your compliance requirements. It centralizes feature flags and non-sensitive configurations, keeps sensitive data safely out of source control, handles multi-environment deployments cleanly, and eliminates credentials via a passwordless Managed Identity.
Incorrect:
* Store connection strings in the Function app application settings configured in the Azure Portal.
* Store production secrets in environment variables set by the Dockerfile.
Reference:
https://learn.microsoft.com/en-us/azure/app-service/app-service-key-vault-references
NEW QUESTION # 108
Drag and Drop Question
You are implementing a Retrieval-Augmented Generation (RAG) system by using the native vector search capabilities of Azure Cosmos DB for NoSQL API.
You have a container named Documents that stores technical articles. Each article includes a property named embedding.
You must ensure that the system can perform efficient similarity searches between user queries and the stored articles.
You need to configure the database resources to support semantic retrieval.
Which configurations should you use? To answer, move the appropriate configurations to the correct requirements. You may use each configuration once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Answer:
Explanation: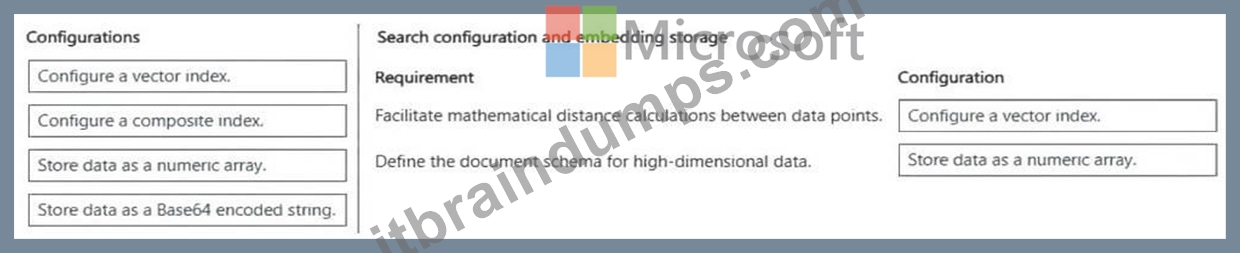
Explanation:
Box 1: Configure a vector index.
To support semantic retrieval and perform mathematical distance calculations using the native vector search capabilities of Azure Cosmos DB for NoSQL, you must configure a vector index.
Azure Cosmos DB for NoSQL relies on a specialized indexing structure (such as DiskANN or QuantizedFlat) to organize vector data. Defining a vector index policy within the container configurations is a strict requirement for enabling high-speed similarity searches (using functions like VectorDistance) without requiring full, unindexed scans of documents.
Box 2: Store data as a numeric array
Azure Cosmos DB for NoSQL, you must store the embedding property as a numeric array (an array of floating-point numbers like float32) inside your JSON documents.
Reference:
https://learn.microsoft.com/en-us/azure/cosmos-db/gen-ai/agentic-retrieval
NEW QUESTION # 109
You are designing an Azure Database for PostgreSQL table for semantic search. Queries frequently filter on the created_at column. The schema must support vector similarity search and reliable date filtering You need to ensure that the table meets the requirements.
Which two actions should you perform? Each correct answer presents part of the solution. Choose two NOTE: Each correct selection is worth one point.
Answer: A,C
Explanation:
Detailed Explanation: A semantic-search schema should use the pgvector vector type for embeddings so PostgreSQL can apply vector distance operators and vector indexes. The creation timestamp should use an actual timestamp data type so comparisons, range predicates, ordering, and indexes use date semantics rather than string ordering. Storing vectors or dates as free-form character data would sacrifice type validation and make similarity or date filtering less efficient and less reliable.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | Vector similarity search with Azure PostgreSQL
NEW QUESTION # 110
......
Itbraindumps provides accurate and up-to-date Microsoft AI-200 Exam Questions that ensure exam success. With these Microsoft AI-200 practice questions, you can pass the AI-200 exam on the first try. Itbraindumps understands the stress and anxiety that exam candidates experience while studying. As a result, they provide personalized Microsoft AI-200 Practice Exam material to assist you in efficiently preparing for the exam.
Reliable AI-200 Test Topics: https://www.itbraindumps.com/AI-200_exam.html