Pass Guaranteed Newest Microsoft - DP-750 Reliable Exam Pdf

The Microsoft modern job market is becoming more and more competitive and challenging and if you are not ready for it then you cannot pursue a rewarding career. Take a smart move right now and enroll in the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) certification exam and strive hard to pass the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) certification exam. The Implementing Data Engineering Solutions Using Azure Databricks (DP-750) certification exam offers you a unique opportunity to learn new in-demand skills and knowledge.
| Section | Weight | Objectives |
|---|
| Configure and manage Azure Databricks environments | 15-20% | - Workspace and compute configuration
- 1. Autoscaling, termination, and performance tuning
- 2. Runtime, Spark, and Photon configuration
- 3. Cluster types and configuration (job, all-purpose, serverless)
- Security and authentication setup
- 1. Azure Key Vault integration
- 2. Service principals and managed identities
- 3. Access control for compute resources
|
| Secure and govern data using Unity Catalog | 15-20% | - Access control and policies
- 1. Attribute-based access control (ABAC)
- 2. Tags and policy enforcement
- 3. Row-level and column-level security
- Data governance fundamentals
- 1. Catalog, schema, and table management
- 2. Data lineage and auditing
|
| Prepare and process data | 30-35% | - Data quality and validation
- 1. Handling nulls, duplicates, and missing data
- 2. Pipeline expectations and data quality constraints
- 3. Schema enforcement and validation rules
- Data ingestion
- 1. Batch ingestion using COPY INTO and CTAS
- 2. Streaming ingestion using Spark Structured Streaming
- 3. Auto Loader and CDC ingestion patterns
- Data transformation and modeling
- 1. Delta Lake table design and SCD patterns
- 2. SQL and PySpark transformations
- 3. Joins, aggregations, and normalization/denormalization
|
| Deploy and manage data pipelines and workloads | 30-35% | - Lakehouse architecture operations
- 1. Delta Lake optimization and clustering strategies
- 2. Delta Live Tables pipelines
- Operational reliability
- 1. Error handling and retries
- 2. Monitoring and logging (Azure Monitor integration)
- Pipeline design and orchestration
- 1. Databricks Jobs and Workflows
- 2. Notebook-based vs declarative pipelines
|
>> DP-750 Reliable Exam Pdf <<
DP-750 Reliable Exam Pdf High Pass-Rate Questions Pool Only at Prep4cram
Remember to fill in the correct mail address in order that it is easier for us to send our DP-750 study guide to you, therefore, this personal message is particularly important. We are selling virtual products, and the order of our DP-750 exam materials will be immediately automatically sent to each purchaser's mailbox according to our system. In the future, if the system updates, we will still automatically send the latest version of our DP-750 learning questions to the buyer's mailbox.
Microsoft Implementing Data Engineering Solutions Using Azure Databricks Sample Questions (Q63-Q68):
NEW QUESTION # 63
What happens if incoming data violates Delta table schema?
- A. Data is appended with nulls
- B. Table is overwritten
- C. Data is automatically cast
- D. Data is rejected
Answer: D
Explanation:
Delta Lake enforces schema by default. If incoming data does not match schema, the write operation fails unless schema evolution is explicitly enabled. It does not auto-cast or append invalid data. Overwriting would require explicit command.
NEW QUESTION # 64
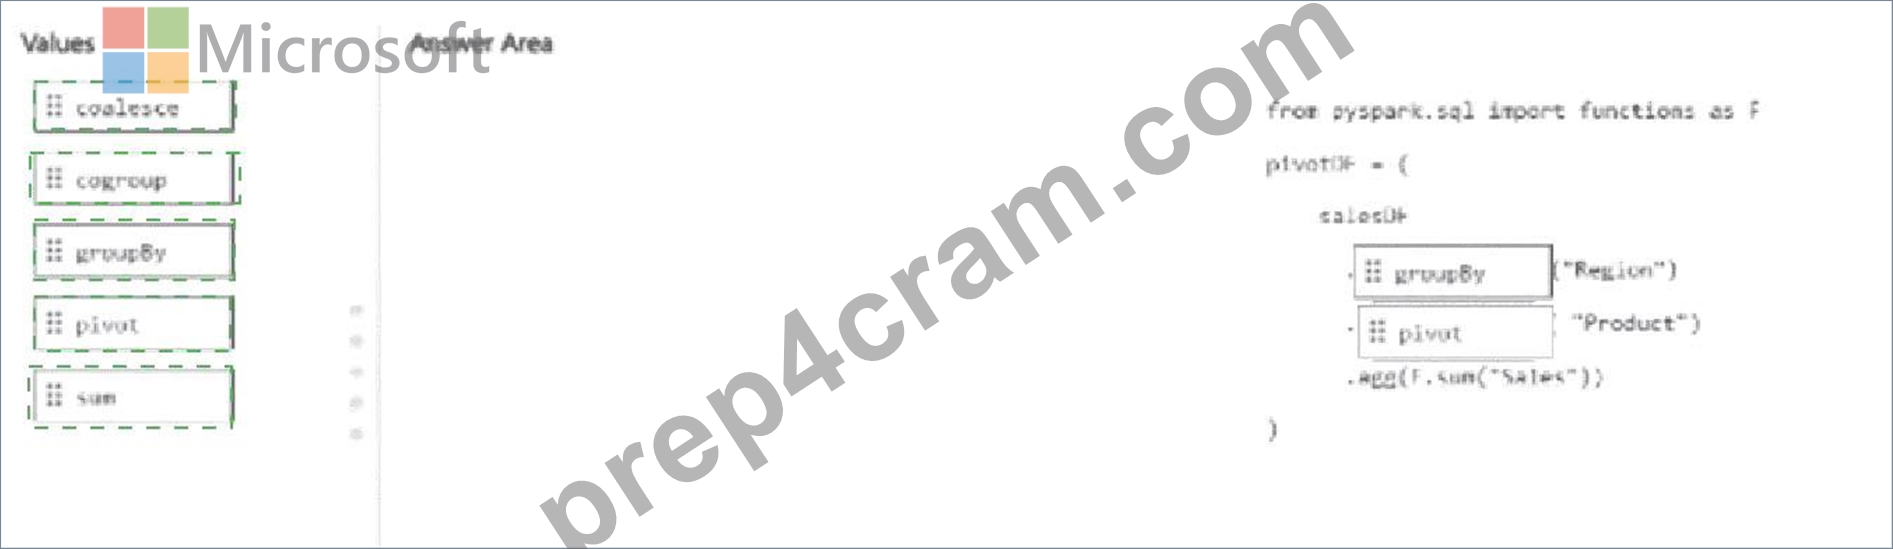
You have an Apache Spark DataFrame named salesDF that contains the following columns:
* Product
* Region
* Sales
* Date
You need to create a pivot table that shows the total sales by product for each region.
How should you complete the PySpark code segment? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.

Answer:
Explanation:
Explanation:
* groupBy
* pivot
The groupBy( " Region " ) operation establishes one aggregation group for each geographical region in the DataFrame. The subsequent pivot( " Product " ) operation converts every distinct Product value into a separate output column. Finally, agg(F.sum( " Sales " )) calculates the total sales for every product within each region. The resulting DataFrame contains one row per region and one column for each product, with the corresponding aggregated sales value. cogroup combines grouped datasets and is not used for creating a conventional pivot table. coalesce controls the number of DataFrame partitions or replaces null values, depending on its context. The sum function is already provided inside the aggregation expression and therefore is not required in either blank.
NEW QUESTION # 65
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You plan to ingest data from CSV files stored in Azure Data Lake Storage Gen2. New rows are appended frequently.
You need to implement a data ingestion solution that meets the following requirements:
- New data must be available in near-real-time (NRT).
- The data must be stored in managed Delta tables.
- The solution must minimize custom code and maintenance effort.
What should you include in the solution?
- A. scheduled Apache Spark batch jobs
- B. Auto Loader
- C. an external table that references the CSV files
- D. an Azure Data Factory pipeline
Answer: B
Explanation:
You should use Auto Loader with Delta Live Tables (DLT) or a streaming readStream using the cloudFiles format to load data into Unity Catalog managed tables.
To achieve the absolute lowest maintenance and custom code, Delta Live Tables with Auto Loader is the recommended choice.
Configure Cloud FilesFormat option: Set the source format to cloudFiles in your Spark stream.File detection: Auto Loader automatically tracks new files arriving in Azure Data Lake Storage (ADLS) Gen2.Schema evolution: It infers and adapts to schema changes without code updates.
Reference:
https://docs.databricks.com/aws/en/ingestion/cloud-object-storage/auto-loader/unity-catalog
NEW QUESTION # 66
You have an Azure Databricks workspace.
You have an Apache Spark Structured Streaming job named Job1 that processes data continuously and fails periodically due to transient errors.
You need to ensure that Job1 meets the following requirements:
- Resumes processing from the point that Job1 failed
- Minimizes how long it takes to restart Job1
- Minimizes the costs to restart Job1
What should you do?
- A. Add an alert and manually restart Job1.
- B. Implement checkpointing.
- C. Decrease the retry interval.
- D. Increase the minimum number of nodes in the cluster.
Answer: B
Explanation:
You must use checkpointing.
Checkpointing is the native Apache Spark mechanism designed specifically to handle failures in Structured Streaming jobs. It saves the exact execution state and progress to cloud storage (like Azure Data Lake Storage), allowing the job to resume precisely where it left off without data loss.
Resumes from Failure Point: The checkpoint directory stores the stream offsets. When restarted, Spark reads these offsets to pick up exactly where it failed.
Minimizes Restart Time: By saving the state, Spark does not need to recompute historical streaming data or re-evaluate the entire stream architecture from scratch.
Minimizes Restart Costs: It prevents the reprocessing of duplicate data, saving valuable cluster compute time and reducing cloud infrastructure costs.
Reference:
https://www.linkedin.com/posts/shilpa-das-ln_what-is-checkpointing-in-spark-checkpointing- activity-7297113790393815041-AhPg
NEW QUESTION # 67
Hotspot Question
You have an Azure Databricks job named Job1 that contains an ingestion task named Task1 and transformation task named Task2.
You need to ensure that if Task1 fails, the task retries automatically, and Task2 is prevented from running.
How should you configure Job1? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.

Answer:
Explanation:

NEW QUESTION # 68
......
Prep4cram designed this prep material to help you pass the exam on the first try. It may sound complicated, but once you go through regular study and intensive practice, passing the final exam would be a piece of cake. The cost of Implementing Data Engineering Solutions Using Azure Databricks (DP-750) certification itself is expensive, ranging from $100 to $1000, so you can't risk wasting that amount. Prep4cram ensures that this does not happen by providing you with reliable and updated preparation material.
DP-750 Test Lab Questions: https://www.prep4cram.com/DP-750_exam-questions.html
- DP-750 Exam Revision Plan 🎲 Latest Braindumps DP-750 Book 🤚 New DP-750 Test Pattern 😼 ▛ www.vceengine.com ▟ is best website to obtain ➠ DP-750 🠰 for free download 🤛DP-750 Valid Test Sims
- DP-750 Valid Test Sims ↔ DP-750 Exams Training 🖋 DP-750 Valid Test Sims 👜 Search for ➡ DP-750 ️⬅️ on ▷ www.pdfvce.com ◁ immediately to obtain a free download ❤DP-750 Exams Training
- 2026 Microsoft DP-750 Reliable Exam Pdf - Implementing Data Engineering Solutions Using Azure Databricks Realistic Test Lab Questions 100% Pass 😓 Download ▷ DP-750 ◁ for free by simply entering { www.practicevce.com } website 🦂DP-750 Valid Test Registration
- Maximize Your Success with Pdfvce Customizable DP-750 Implementing Data Engineering Solutions Using Azure Databricks Practice Test 🛰 Open ▷ www.pdfvce.com ◁ and search for ➥ DP-750 🡄 to download exam materials for free 📺DP-750 Exam Fees
- High-quality DP-750 Reliable Exam Pdf - Pass DP-750 Exam 🏍 Open ▶ www.pass4test.com ◀ and search for ⮆ DP-750 ⮄ to download exam materials for free 🦜DP-750 Advanced Testing Engine
- Realistic DP-750 Reliable Exam Pdf – Pass DP-750 First Attempt 💁 Open “ www.pdfvce.com ” and search for ✔ DP-750 ️✔️ to download exam materials for free 🦟DP-750 Dumps Vce
- DP-750 Exams Training 📘 Reliable DP-750 Test Questions 😀 DP-750 Exam Revision Plan 🧩 Easily obtain free download of ▶ DP-750 ◀ by searching on ▶ www.examdiscuss.com ◀ 😘DP-750 Advanced Testing Engine
- DP-750 Exams Training 🧍 Valid DP-750 Exam Tutorial 👎 DP-750 Preparation Store 🔸 Search for 《 DP-750 》 and download it for free immediately on ▶ www.pdfvce.com ◀ 🧡DP-750 Valid Test Registration
- Latest DP-750 Exam Cram 🦡 Latest DP-750 Test Pdf 🍗 New DP-750 Test Pattern ⤵ Search for ( DP-750 ) on ➤ www.practicevce.com ⮘ immediately to obtain a free download 🌰Latest DP-750 Exam Cram
- First-Grade DP-750 Reliable Exam Pdf - Leader in Qualification Exams - Perfect DP-750 Test Lab Questions 🔼 Easily obtain free download of ▛ DP-750 ▟ by searching on { www.pdfvce.com } 🥵DP-750 Valid Exam Voucher
- First-Grade DP-750 Reliable Exam Pdf - Leader in Qualification Exams - Perfect DP-750 Test Lab Questions 🔥 Copy URL ☀ www.prepawaypdf.com ️☀️ open and search for [ DP-750 ] to download for free 🚀Latest Braindumps DP-750 Book
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes