P.S. Free & New AI-300 dumps are available on Google Drive shared by ExamsReviews: https://drive.google.com/open?id=1rdzbRx1h2qJ4oZg4v4S2h9MnUIkO3eB_
The data that come up with our customers who have bought our AI-300 actual exam and provided their scores show that our high pass rate of our AI-300 exam questions is 98% to 100%. This is hard to find and compare with in the market. And numerous enthusiastic feedbacks from our worthy clients give high praises not only on our AI-300 study torrent, but also on our sincere and helpful 24 hours customer services online. All of these prove that we are the first-class vendor in this career and have authority to ensure your success in your first try on AI-300 exam.
| Section | Objectives |
|---|---|
| Topic 1: Implement secure and scalable AI systems | - Security and governance
|
| Topic 2: Design and implement generative AI solutions | - RAG (Retrieval Augmented Generation) solutions
|
| Topic 3: Plan and design AI solutions using Azure AI services | - Responsible AI design
|
| Topic 4: Operationalizing machine learning solutions | - ML lifecycle management
|
The Microsoft AI-300 exam questions on the platform have been gathered by subject matter experts to ensure that they accurately reflect the format and difficulty level of the actual Microsoft AI-300 exam. This makes these Operationalizing Machine Learning and Generative AI Solutions PDF Questions ideal for individuals looking to pass the Microsoft AI-300 Exam on their first try. You can evaluate the product with a free AI-300 demo.
NEW QUESTION # 37
Drag and Drop Question
A team maintains Infrastructure as Code (IaC) templates to provision Azure Machine Learning resources.
Provisioning must be triggered by changes in the templates and executed without manual intervention.
You need to automate resource provisioning.
Which action should you take for each requirement? To answer, move the appropriate actions to the correct requirements. You may use each action once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
NEW QUESTION # 38
-
A team is developing a Retrieval-Augmented Generation (RAG) system.
The team requires improvements to the system ' s retrieval quality to ensure accurate, grounded responses.
You need to assess RAG performance before you can suggest an improvement strategy.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.
Answer:
Explanation:
Explanation:
Correct sequence:
* Collect retrieval logs.
* Run RAG evaluators.
* Adjust chunking strategy.
* Re-index documents.
The process should begin by collecting retrieval logs . Retrieval diagnostics provide the evidence needed to understand which queries were issued, which document chunks were returned, and whether relevant content is being surfaced. Without retrieval telemetry, optimization becomes speculative rather than measurable.
Next, run RAG evaluators . Microsoft Foundry provides retrieval-oriented evaluators that assess how relevant retrieved context is to a query. The Retrieval evaluator measures contextual relevance without requiring ground truth, while the Document Retrieval evaluator can calculate metrics such as Fidelity and NDCG when labeled retrieval ground truth exists. These measurements help establish the retrieval-quality baseline before modifications are made.
After identifying retrieval deficiencies, adjust the chunking strategy . Microsoft specifically recommends reviewing chunk size and chunking methodology when retrieval returns irrelevant or incomplete passages.
Chunks that are too small can lose context, while oversized chunks can introduce irrelevant material and reduce retrieval precision.
Finally, re-index the documents so the revised chunking configuration is reflected in the searchable corpus.
Changing temperature or regenerating the prompt template primarily affects generation behavior rather than correcting the underlying retrieval pipeline.
Study Guide Reference: Implement generative AI quality assurance and observability - RAG evaluation, retrieval telemetry, retrieval-quality metrics, chunk optimization, indexing, and grounded-response assessment.
NEW QUESTION # 39
-
You have an Azure Machine Learning workspace and a collection of image files stored in two Azure Blob Storage accounts.
You need to configure data asset properties.
Which values should you use in your configuration? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Data asset type: mltable
Scheme of the URL paths to storage locations: wasbs
The correct data asset type is mltable because the image collection is distributed across multiple storage locations . Microsoft identifies MLTable as the appropriate Azure Machine Learning data asset type when unstructured data such as images, text, or audio is spread across multiple storage locations. An MLTable definition can contain multiple file, folder, or pattern entries, allowing one logical data asset to reference image data residing in different storage accounts.
A uri_folder data asset is appropriate when the required unstructured files reside within a single folder path .
It represents one folder location and therefore does not provide the same multi-path abstraction required by this scenario. uri_file represents only an individual file and is clearly unsuitable for a collection of images.
For the path scheme, Azure Machine Learning uses wasbs:// for Azure Blob Storage. Microsoft documents the canonical format as:
wasbs:// < container > @ < account > .blob.core.windows.net/ < path >
By comparison, abfss:// is used for Azure Data Lake Storage Gen2, while azureml:// identifies Azure Machine Learning datastore paths rather than direct Azure Blob Storage URLs.
Therefore, an MLTable containing multiple wasbs:// paths correctly represents image files distributed across the two Azure Blob Storage accounts.
Study Guide Reference: Design and implement an MLOps infrastructure - Azure Machine Learning data assets, MLTable, multi-location datasets, storage URI schemes, and Blob Storage integration.
NEW QUESTION # 40
Drag and Drop Question
You have an Azure Machine Learning workspace named WS1 and a GitHub account named account1 that hosts a private repository named repo1.
You need to clone repo1 to make it available directly from WS1. The configuration must maximize the performance of the repo1 clone.
Which four actions should you perform in sequence?
Answer:
Explanation:
Explanation:
Step 1: Create a compute instance
Git integration for Azure Machine Learning
Clone Git repositories into your workspace file system
Azure Machine Learning provides a shared file system for all users in the workspace. To clone a Git repository into this file share, we recommend that you create a compute instance (Step 1) & open a terminal (Step 2). Once the terminal is opened, you have access to a full Git client and can clone and work with Git via the Git CLI experience.
We recommend that you clone the repository into your user directory so that others will not make collisions directly on your working branch.
Step 2: Open a terminal window
Step 3: Generate a Secure Shell (SSH) key pair
Authenticate your Git Account with SSH
Generate a new SSH key
1. Open the terminal window in the Azure Machine Learning Notebook Tab.
2. Paste the text below, substituting in your email address.
ssh-keygen -t rsa -b 4096 -C your_email@example.com
This creates a new ssh key, using the provided email as a label.
3. When you're prompted to "Enter a file in which to save the key" press Enter. This accepts the default file location.
4. Verify that the default location is '/home/azureuser/.ssh' and press enter. Otherwise specify the location '/home/azureuser/.ssh'.
5. At the prompt, type a secure passphrase. We recommend you add a passphrase to your SSH key for added security Step 4: Add a public key to account1.
Add the public key to Git Account
1. In your terminal window, copy the contents of your public key file. If you renamed the key, replace id_rsa.pub with the public key file name.
cat ~/.ssh/id_rsa.pub
2. Select and copy the SSH key output to your clipboard.
3. Next, follow the steps to add the SSH key to your preferred account type:
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/concept-train-model-git-integration
NEW QUESTION # 41
You need to configure an optimization method to meet Fabrikam Inc.'s technical requirements.
Which strategy should you apply first? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.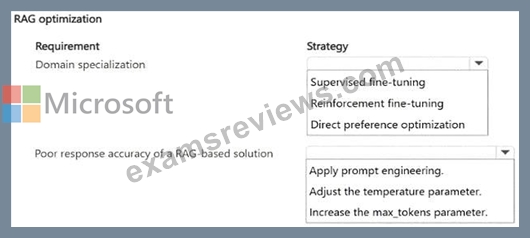
Answer:
Explanation: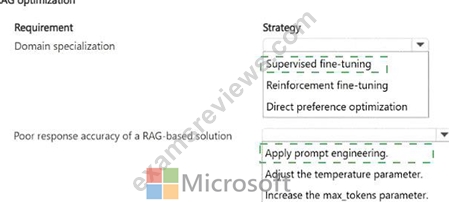
Explanation:
Domain specialization: Supervised fine-tuning
Poor response accuracy of a RAG-based solution: Apply prompt engineering For domain specialization , Supervised Fine-Tuning (SFT) is the correct first strategy. Microsoft describes SFT as the foundational fine-tuning technique for training a model from labeled input-output pairs , and specifically identifies domain specialization as one of its principal use cases. Microsoft also recommends starting with SFT for most customization projects because it supports task specialization, instruction following, style, and domain-specific behavior. Fabrikam already possesses evaluation data containing input- output pairs, which aligns directly with the SFT data model.
For poor RAG response accuracy , the first action is prompt engineering . The case explicitly requires advanced fine-tuning only when prompt engineering is insufficient. In a RAG system, prompt engineering determines how the model interprets retrieved context, constrains answers to grounding information, handles missing evidence, and formats responses. Microsoft notes that inadequate RAG prompting can produce false or incomplete answers even when retrieval returns appropriate content.
DPO is primarily appropriate for alignment using preferred versus non-preferred responses, while RFT targets complex reward-based reasoning optimization. Neither is the initial technique for domain specialization in this requirement.
Study Guide Reference: Optimize generative AI systems and model performance - prompt engineering, RAG optimization, supervised fine-tuning, preference optimization, and model customization strategy.
NEW QUESTION # 42
......
If you prefer to have your practice online, then you can choose us. AI-300 PDF version is printable and you can print them into hard one and take some notes on them. In addition, AI-300 exam dumps have free demo for you to have a try, so that you can have a deeper understanding of what you are going to buy. You can receive your download link and password within ten minutes for AI-300 Exam Dumps. We have online and offline chat service stuff for AI-300 exam materials, and if you have any questions, you can have a conversation with us, and we will give you reply as soon as we can.
Exam AI-300 Material: https://www.examsreviews.com/AI-300-pass4sure-exam-review.html
2026 Latest ExamsReviews AI-300 PDF Dumps and AI-300 Exam Engine Free Share: https://drive.google.com/open?id=1rdzbRx1h2qJ4oZg4v4S2h9MnUIkO3eB_