We are all well aware that a major problem in the industry is that there is a lack of quality study materials. Our DP-800 braindumps provides you everything you will need to take a certification examination. Details are researched and produced by DP-800 Dumps Experts who are constantly using industry experience to produce precise, logical verify for the test. You may get DP-800 exam dumps from different web sites or books, but logic is the key.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> DP-800 Latest Exam Preparation <<
Do you want to pass your exam buying using the least time? If you do, you can choose us, we have confidence help you pass your exam just one time. DP-800 training materials are edited by skilled professionals, they are familiar with the dynamics for the exam center, therefore you can know the dynamics of the exam timely. Besides, we offer you free demo for you to have a try before buying DP-800 Test Dumps, so that you can have a deeper understanding of what you are going to buy. Free update for one year is available, and you can obtain the latest version if you choose us, and the update version for DP-800 exam materials will be sent to your email address automatically.
NEW QUESTION # 63
Drag and Drop Question
You have an Azure SQL database named SalesDB that supports an ecommerce application.
SalesDB contains a table named dbo.Orders that has a clustered index on a column named OrderId.
dbo.Orders receives continuous OLTP inserts and updates during business hours.
Your analytics team runs hourly aggregate queries that scan dbo.Orders to calculate revenue trends for recent dates.
You need to improve the performance of the hourly analytics queries without significantly affecting OLTP throughput. The solution must meet the following requirements:
- Support near-real-time (NRT) analytics on the dbo.Orders table.
- Reduce read time when retrieving analytical data from dbo.Orders.
- Support indexing only rows that match a predicate, such as Active =
1.
Which type of index should you use for each requirement? To answer, drag the appropriate index types to the correct requirements. Each index type may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
NEW QUESTION # 64
Drag and Drop Question
You have an Azure AI Search service and an index named hotels that includes a vector field named DescriptionVector.
You query hotels by using the Search Documents REST API.
You need to implement a hybrid search query that uses DescriptionVector and includes captions.
How should you complete the REST request body? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
NEW QUESTION # 65
Vou have a Microsoft Fabric workspace named Workspace1 that contains a SQL database named SalesDB and an API for GraphQL tern named SalesApi.
You have a Microsoft Entra group named SqlUsers.
From Workspace1, you assign permission to SalesApi as shown in the following exhibit.
The connection to SalesDB has the connectivity option configured as shown in the following exhibit.
SqlUsers has the Viewer role for Workspace1.
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
* The members of SqlUsers can modify the data in SalesDB via SalesApi. # No
* The members of SqlUsers can view the data in SalesDB via SalesApi. # No
* The members of SqlUsers can change the field mappings of SalesApi. # Yes For both viewing and modifying data through SalesApi, the key missing permission is Run Queries and Mutations . Microsoft's Fabric GraphQL documentation states that callers need Execute permissions for the GraphQL API , which correspond to the Run Queries and Mutations option, and with SSO connectivity they also need appropriate permissions on the underlying data source. In the exhibit, SqlUsers has View and Edit GraphQL item selected, but Run Queries and Mutations is not selected, so members cannot query or mutate data through the API.
The third statement is Yes because the group was explicitly granted View and Edit GraphQL item . That permission is the one that allows users to open and modify the GraphQL item itself, including schema-related configuration such as field mappings in the API item. The workspace Viewer role does not by itself grant query execution through the API, but the direct GraphQL item permission shown does allow editing the item.
NEW QUESTION # 66
You have a SQL database in Microsoft Fabric that contains a table named dbo.Orders. dbo.Orders has a clustered index, contains three years of data, and is partitioned by a column named OrderDate by month.
You need to remove all the rows for the oldest month. The solution must minimize the impact on other queries that access the data in dbo.Orders.
Solution: Identify the partition scheme for the oldest month, and then run the following Transact-SQL statement:
SQL
ALTER TABLE dbo.Orders
DROP PARTITION SCHEME {partition_scheme_name};
Does this meet the goal?
Answer: B
NEW QUESTION # 67
You have an Azure SQL database that contains the following tables and columns.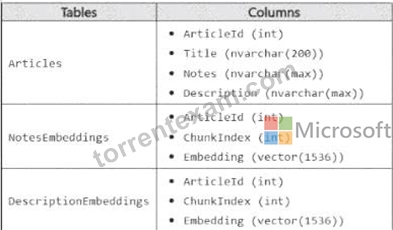
Embeddings in the NotesEnbeddings and DescriptionEabeddings tables have been generated from values in the Description and notes columns of the Articles table by using different chunk sizes.
You need to perform approximate nearest neighbor (ANN) queries across both embedding tables. The solution must minimize the impact of using different chunk sizes.
What should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.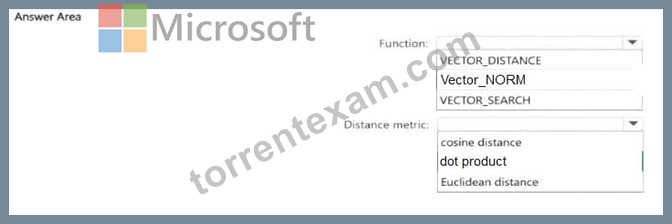
Answer:
Explanation: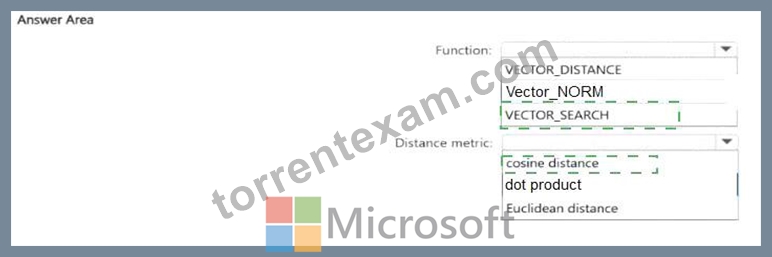
Explanation: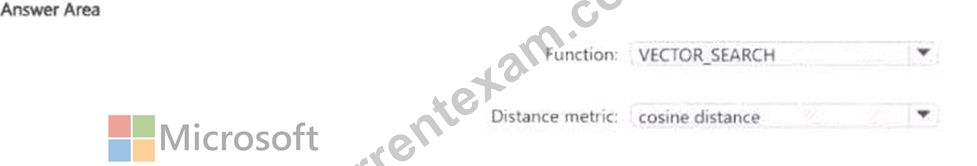
The correct function is VECTOR_SEARCH because the requirement is to perform approximate nearest neighbor (ANN) queries. Microsoft's SQL documentation states that VECTOR_SEARCH is the function used for vector similarity search, and that an ANN index is used only with VECTOR_SEARCH when a compatible vector index exists on the target column. By contrast, VECTOR_DISTANCE calculates an exact distance and does not use a vector index for ANN retrieval.
The correct distance metric is cosine distance. Microsoft documents that VECTOR_SEARCH supports cosine, dot, and euclidean metrics, and Microsoft guidance specifically notes that cosine similarity is commonly used for text embeddings. It also states that retrieval of the most similar texts to a given text typically functions better with cosine similarity, and that Azure OpenAI embeddings rely on cosine similarity to compute similarity between a query and documents. Since both NotesEmbeddings and DescriptionEmbeddings are text-derived embeddings and the goal is to minimize the impact of different chunk sizes, cosine is the best choice because it compares direction/angle rather than being as sensitive to vector magnitude as Euclidean distance.
NEW QUESTION # 68
......
TorrentExam is regarded as an acclaimed DP-800 dumps study material provider for certification exams that includes a range of helping materials, programs and pathways to ease your tensions of DP-800 exam preparation. The prime objective in developing DP-800 exam dumps is to provide you the unique opportunity of getting the best information in the possibly lesser content. It not only saves your time but also frees you from the hassle of going through tomes of books and other study material. Shorn of unnecessary burden, you better focus what is extremely important to pass exam; hence you increase your chances of success with DP-800 Exam Questions than other that of candidates.
DP-800 Certification Practice: https://www.torrentexam.com/DP-800-exam-latest-torrent.html