
2026 Latest ActualVCE Data-Engineer-Associate PDF Dumps and Data-Engineer-Associate Exam Engine Free Share: https://drive.google.com/open?id=1bayx6eDjUSHwh2CYJEjM3ltT2MRRDDX0
Our Data-Engineer-Associate exam questions are often in short supply. Every day, large numbers of people crowd into our website to browser our Data-Engineer-Associate study materials. Then they will purchase various kinds of our Data-Engineer-Associate learning braindumps at once. How diligent they are! As you can see, our products are absolutely popular in the market. And the pass rate of our Data-Engineer-Associate training guide is high as 98% to 100%. Just buy it and you will love it!
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Operations and Support | 22% | - Troubleshoot data workflow issues - Monitor and maintain data pipelines |
| Topic 2: Data Ingestion and Transformation | 34% | - Ingest and transform data using AWS services - Build and manage data pipelines |
| Topic 3: Data Store Management | 26% | - Select appropriate data storage solutions - Optimize storage performance and cost |
| Topic 4: Data Security and Governance | 18% | - Implement data security controls - Apply governance and compliance best practices |
>> Reliable Data-Engineer-Associate Exam Voucher <<
We invited a large group of professional experts who dedicated in this Data-Engineer-Associate training guide for more than ten years. To improve the accuracy of the Data-Engineer-Associate guide preparations, they keep up with the trend closely. Every page is carefully arranged by them with high efficiency and high quality. Up to now, there are three versions of Data-Engineer-Associate Exam Materials for your choice. So high-quality contents and flexible choices of Data-Engineer-Associate learning mode will bring about the excellent learning experience for you.
NEW QUESTION # 82
A data engineer maintains a materialized view that is based on an Amazon Redshift database. The view has a column named load_date that stores the date when each row was loaded.
The data engineer needs to reclaim database storage space by deleting all the rows from the materialized view.
Which command will reclaim the MOST database storage space?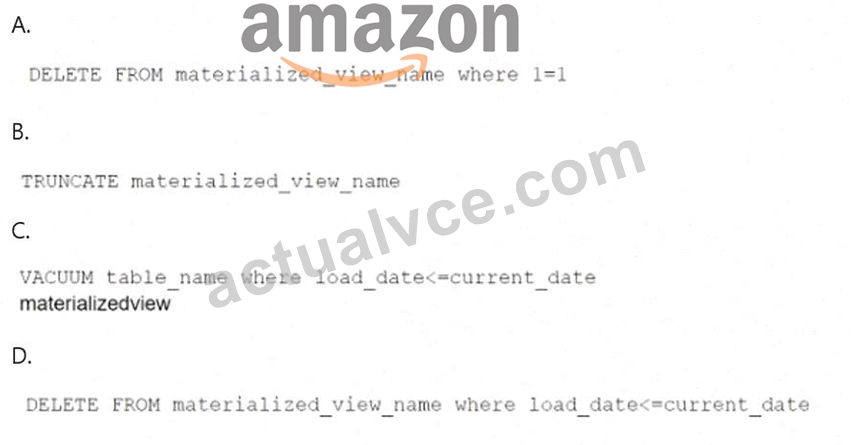
Answer: D
Explanation:
To reclaim the most storage space from a materialized view in Amazon Redshift, you should use a DELETE operation that removes all rows from the view. The most efficient way to remove all rows is to use a condition that always evaluates to true, such as 1=1. This will delete all rows without needing to evaluate each row individually based on specific column values like load_date.
* Option A: DELETE FROM materialized_view_name WHERE 1=1;This statement will delete all rows in the materialized view and free up the space. Since materialized views in Redshift store precomputed data, performing a DELETE operation will remove all stored rows.
Other options either involve inappropriate SQL statements (e.g., VACUUM in option C is used for reclaiming storage space in tables, not materialized views), or they don't remove data effectively in the context of a materialized view (e.g., TRUNCATE cannot be used directly on a materialized view).
References:
Amazon Redshift Materialized Views Documentation
Deleting Data from Redshift
NEW QUESTION # 83
A ride-sharing company stores records for all rides in an Amazon DynamoDB table. The table includes the following columns and types of values:
RideID | RiderID | DriverID | RideStatus | TripStartTime | TripEndTime
XA1231 | AXEF1 | BN123 | Active | 2025-02-11 | NULL
XA1232 | AXEF2 | BN124 | Completed | 2025-02-11 | 2025-02-11
The table currently contains billions of items. The table is partitioned by RideID and uses TripStartTime as the sort key. The company wants to use the data to build a personal interface to give drivers the ability to view the rides that each driver has completed, based on RideStatus. The solution must access the necessary data without scanning the entire table.
Which solution will meet these requirements?
Answer: C
Explanation:
Option C is correct because the required access pattern is: find all completed rides for a specific driver. In DynamoDB, when you need to query data efficiently by attributes that are not part of the base table primary key, you typically create a global secondary index (GSI). AWS documentation states that a GSI can have a key schema that is different from the base table and can use top-level attributes such as DriverID and RideStatus as its partition and sort keys. That makes it possible to query directly for a given driver and then narrow the results to completed rides, without scanning the full table.
Option A is incorrect because a local secondary index (LSI) must use the same partition key as the base table.
Since the table partition key is RideID, an LSI cannot be created with DriverID as the partitioning access path.
Option B uses RiderID, which does not satisfy the requirement to retrieve rides by driver. Option D is also wrong because filter expressions are applied after items are read and therefore do not avoid scanning large amounts of data. The study guide emphasizes choosing the correct data model and access pattern for the workload, which places this question in the Data Storage and Management domain.
NEW QUESTION # 84
An ecommerce company wants to use AWS to migrate data pipelines from an on-premises environment into the AWS Cloud. The company currently uses a third-party too in the on-premises environment to orchestrate data ingestion processes.
The company wants a migration solution that does not require the company to manage servers. The solution must be able to orchestrate Python and Bash scripts. The solution must not require the company to refactor any code.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: B
Explanation:
The ecommerce company wants to migrate its data pipelines into the AWS Cloud without managing servers, and the solution must orchestrate Python and Bash scripts without refactoring code. Amazon Managed Workflows for Apache Airflow (Amazon MWAA) is the most suitable solution for this scenario.
Option B: Amazon Managed Workflows for Apache Airflow (Amazon MWAA)
MWAA is a managed orchestration service that supports Python and Bash scripts via Directed Acyclic Graphs (DAGs) for workflows. It is a serverless, managed version of Apache Airflow, which is commonly used for orchestrating complex data workflows, making it an ideal choice for migrating existing pipelines without refactoring. It supports Python, Bash, and other scripting languages, and the company would not need to manage the underlying infrastructure.
Other options:
AWS Lambda (Option A) is more suited for event-driven workflows but would require breaking down the pipeline into individual Lambda functions, which may require refactoring.
AWS Step Functions (Option C) is good for orchestration but lacks native support for Python and Bash without using Lambda functions, and it may require code changes.
AWS Glue (Option D) is an ETL service primarily for data transformation and not suitable for orchestrating general scripts without modification.
Reference:
Amazon Managed Workflows for Apache Airflow (MWAA) Documentation
NEW QUESTION # 85
A company maintains a data warehouse in an on-premises Oracle database. The company wants to build a data lake on AWS. The company wants to load data warehouse tables into Amazon S3 and synchronize the tables with incremental data that arrives from the data warehouse every day.
Each table has a column that contains monotonically increasing values. The size of each table is less than 50 GB. The data warehouse tables are refreshed every night between 1 AM and 2 AM. A business intelligence team queries the tables between 10 AM and 8 PM every day.
Which solution will meet these requirements in the MOST operationally efficient way?
Answer: B
Explanation:
The company needs to load data warehouse tables into Amazon S3 and perform incremental synchronization with daily updates. The most efficient solution is to use AWS Database Migration Service (AWS DMS) with a combination of full load and change data capture (CDC) to handle the initial load and daily incremental updates.
Option A: Use an AWS Database Migration Service (AWS DMS) full load plus CDC job to load tables that contain monotonically increasing data columns from the on-premises data warehouse to Amazon S3. Use custom logic in AWS Glue to append the daily incremental data to a full-load copy that is in Amazon S3.
DMS is designed to migrate databases to AWS, and the combination of full load plus CDC is ideal for handling incremental data changes efficiently. AWS Glue can then be used to append the incremental data to the full data set in S3. This solution is highly operationally efficient because it automates both the full load and incremental updates.
Options B, C, and D are less operationally efficient because they either require writing custom logic to handle bookmarks manually or involve unnecessary daily full loads.
References:
AWS Database Migration Service Documentation
AWS Glue Documentation
NEW QUESTION # 86
A company needs to build a data lake in AWS. The company must provide row-level data access and column-level data access to specific teams. The teams will access the data by using Amazon Athena, Amazon Redshift Spectrum, and Apache Hive from Amazon EMR.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: C
Explanation:
Option D is the best solution to meet the requirements with the least operational overhead because AWS Lake Formation is a fully managed service that simplifies the process of building, securing, and managing data lakes. AWS Lake Formation allows you to define granular data access policies at the row and column level for different users and groups. AWS Lake Formation also integrates with Amazon Athena, Amazon Redshift Spectrum, and Apache Hive on Amazon EMR, enabling these services to access the data in the data lake through AWS Lake Formation.
Option A is not a good solution because S3 access policies cannot restrict data access by rows and columns.
S3 access policies are based on the identity and permissions of the requester, the bucket and object ownership, and the object prefix and tags. S3 access policies cannot enforce fine-grained data access control at the row and column level.
Option B is not a good solution because it involves using Apache Ranger and Apache Pig, which are not fully managed services and require additional configuration and maintenance. Apache Ranger is a framework that provides centralized security administration for data stored in Hadoop clusters, such as Amazon EMR. Apache Ranger can enforce row-level and column-level access policies for Apache Hive tables. However, Apache Ranger is not a native AWS service and requires manual installation and configuration on Amazon EMR clusters. Apache Pig is a platform that allows you to analyze large data sets using a high-level scripting language called Pig Latin. Apache Pig can access data stored in Amazon S3 and process it using Apache Hive.
However,Apache Pig is not a native AWS service and requires manual installation and configuration on Amazon EMR clusters.
Option C is not a good solution because Amazon Redshift is not a suitable service for data lake storage.
Amazon Redshift is a fully managed data warehouse service that allows you to run complex analytical queries using standard SQL. Amazon Redshift can enforce row-level and column-level access policies for different users and groups. However, Amazon Redshift is not designed to store and process large volumes of unstructured or semi-structured data, which are typical characteristics of data lakes. Amazon Redshift is also more expensive and less scalable than Amazon S3 for data lake storage.
References:
AWS Certified Data Engineer - Associate DEA-C01 Complete Study Guide
What Is AWS Lake Formation? - AWS Lake Formation
Using AWS Lake Formation with Amazon Athena - AWS Lake Formation
Using AWS Lake Formation with Amazon Redshift Spectrum - AWS Lake Formation Using AWS Lake Formation with Apache Hive on Amazon EMR - AWS Lake Formation Using Bucket Policies and User Policies - Amazon Simple Storage Service Apache Ranger Apache Pig What Is Amazon Redshift? - Amazon Redshift
NEW QUESTION # 87
......
Completing the preparation for the AWS Certified Data Engineer - Associate (DEA-C01) exam on time is the most important aspect. The other thing is to prepare for the AWS Certified Data Engineer - Associate (DEA-C01) exam by evaluating your preparation using authentic exam questions. ActualVCE provides the most authentic AWS Certified Data Engineer - Associate (DEA-C01) (Data-Engineer-Associate) Exam Questions compiled according to the rules or patterns supplied by AWS Certified Data Engineer - Associate (DEA-C01) (Data-Engineer-Associate) professionals. We provide you with everything you need to pass the Data-Engineer-Associate exam, which verifies you as a Amazon certified specialist in the domain of Amazon Data Modeling.
Data-Engineer-Associate Valid Braindumps Free: https://www.actualvce.com/Amazon/Data-Engineer-Associate-valid-vce-dumps.html
BTW, DOWNLOAD part of ActualVCE Data-Engineer-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1bayx6eDjUSHwh2CYJEjM3ltT2MRRDDX0