DOWNLOAD the newest LatestCram DP-750 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=19DTHFm41zAL1agvEMFKdQ-rwwSjz1rgL
The best reason for choosing our DP-750 exam torrent as your training materials is its reliability and authenticity. Our latest DP-750 vce dumps aimed to meet your exam requirements and making it easy for you to obtain high passing score in the DP-750 Actual Test. The learning materials provided by our website cover most of key knowledge of DP-750 practice exam and the latest updated exam information.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
| Topic 2: Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
| Topic 3: Secure and govern Unity Catalog objects | 15–20% | - Manage data sharing and permissions
|
| Topic 4: Prepare and process data | 30–35% | - Optimize and manage data storage
|
Our company has a professional team of experts to write DP-750 preparation materials and will constantly update it to ensure that it is synchronized with the exam content. In addition to the high quality, reasonable price and so on, we have many other reasons to make you choose our DP-750 Actual Exam. There are three versions of our DP-750 exam questions: PDF, Software and APP online which can provide you the varied study experiences.
NEW QUESTION # 13
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that writes records to a Delta table named Table1 by using a data quality rule named rule1 You need to meet the following requirements:
* Records that violate rule! must NOT be written to Table1. but the pipeline must continue processing valid records.
* Data engineers must be able to review expectation metrics by using minimal development effort.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.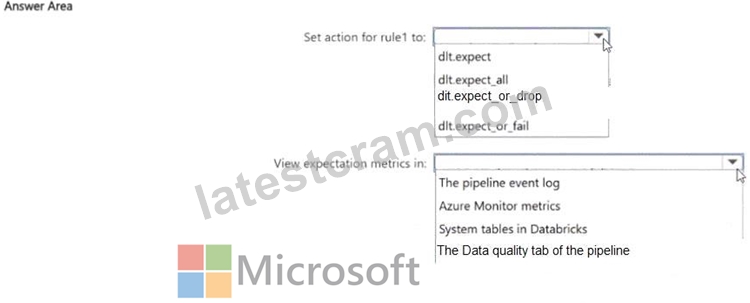
Answer:
Explanation: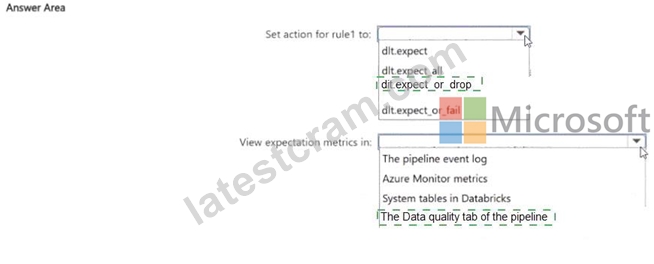
Explanation:
Two things are needed here:
For the rule enforcement: use @dlt.expect_or_drop. This drops any record that violates rule1 before it reaches Table1, while the pipeline continues processing all valid records. The table only ever receives clean data.
For reviewing metrics: the Lakeflow SDP Pipeline UI is the right tool - zero development effort required.
The pipeline graph shows expectation pass/fail counts directly on each table node, and the event log provides a detailed per-batch breakdown of how many records were dropped and why. Data engineers can inspect this at any time without writing additional monitoring queries or connecting external dashboards.
This combination is one of the strongest arguments for SDP over hand-coded Structured Streaming:
expectation observability is built in, not bolted on.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/expectations
NEW QUESTION # 14
Which tool is best for continuous ingestion of files landing in Azure Data Lake?
Answer: B
Explanation:
Auto Loader is optimized for incremental and continuous ingestion from cloud storage. It detects new files automatically and scales efficiently. Databricks Jobs schedule tasks but do not handle file detection. Logic Apps are workflow tools. ADF is batch-oriented.
NEW QUESTION # 15
You have an Azure Databricks workspace named Workspace1.
You create a compute cluster named Cluster1 that will be used to ingest data.
You need to install the required libraries on Cluster1. The solution must use Unity Catalog for access control.
What should you do?
Answer: D
Explanation:
The best action is uploading the libraries to the workspace and installing the libraries on the cluster (or ideally uploading them to Unity Catalog volumes).
Unity Catalog Compatibility: When using Unity Catalog for access control, compute clusters are typically configured with Standard (Shared) access mode. In this mode, traditional cluster init scripts [Not B.] face strict execution restrictions or are completely blocked to maintain secure user isolation.
Governance: Uploading your packages as Workspace Files or to Unity Catalog volumes allows administrators to manage access permissions directly and add them to an allowlist if needed.
Cluster-Wide Availability: Installing the libraries via the cluster's Libraries tab ensures that the required ingestion packages are automatically pre-installed and available across all nodes and notebooks running on that cluster.
Incorrect:
[Not A]
Running pip3 install manually on a cluster terminal or inside a notebook only applies to the specific notebook session (notebook-scoped). It does not natively persist across cluster restarts or handle cross-node execution effectively for data ingestion pipelines.
[Not B]
Running a custom script or a legacy init script to modify system-level paths introduces security risks and is generally incompatible with Unity Catalog's strict execution isolation policies for shared compute.
Reference:
https://docs.databricks.com/aws/en/libraries/
NEW QUESTION # 16
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Sales. Sales stores transaction data and contains the following columns:
* transactionjd (string)
* transaction date (date)
* amount (decimal)
You need to implement the following data quality requirements by using table-level data quality enforcement:
* amount must be greater than 0.
* transaction id must never be null.
* Invalid records must be rejected when data is written to the Sales table.
What should you do?
Answer: B
Explanation:
The correct answer is D - a NOT NULL constraint on transaction_id and a CHECK constraint on amount.
Delta Lake table constraints are enforced at write time by the Delta engine itself. A NOT NULL constraint rejects any INSERT or UPDATE that would place a null in transaction_id. A CHECK constraint with amount
> 0 rejects any row where amount is zero or negative. Combined, they implement exactly the stated quality rules: bad rows are rejected when data is written, not filtered away at read time.
Options A and C (SELECT with WHERE / views) are read-time constructs - they don ' t prevent invalid data from entering the table. A clever pipeline bypass could write directly to the table and skip the view entirely. Option B (row-level security with WHERE conditions) is an access-control feature for restricting which rows users see, not for enforcing data quality on writes. Table constraints are the only mechanism that genuinely blocks bad data at the storage layer.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/delta-constraints
NEW QUESTION # 17
What improves join performance for small lookup tables?
Answer: D
Explanation:
Broadcast joins send the small table to all worker nodes, avoiding expensive shuffling. This significantly improves performance. Shuffle and sort merge joins are heavier. Cartesian joins are inefficient and generally avoided.
NEW QUESTION # 18
......
Are you still hesitating about how to choose excellent DP-750 exam simulations? Our company LatestCram is engaged in studying valid exam simulation files with high passing rate many years. If you want to find valid DP-750 exam simulations, our products are helpful for you. Stop hesitating, good choice will avoid making detours in the preparing for the real test. Our DP-750 Exam Simulations will assist you clear exams and apply for international companies or better jobs with better benefits in the near future. Go and come to us!
Valid DP-750 Learning Materials: https://www.latestcram.com/DP-750-exam-cram-questions.html
2026 Latest LatestCram DP-750 PDF Dumps and DP-750 Exam Engine Free Share: https://drive.google.com/open?id=19DTHFm41zAL1agvEMFKdQ-rwwSjz1rgL