さらに、CertShiken DP-100ダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1u-MC4hlUN4WMvuesnLBB7mm_sq630uYl
Microsoft DP-100認証試験に合格することが簡単ではなくて、Microsoft DP-100証明書は君にとってはIT業界に入るの一つの手づるになるかもしれません。しかし必ずしも大量の時間とエネルギーで復習しなくて、弊社が丹精にできあがった問題集を使って、試験なんて問題ではありません。
| Section | Objectives |
|---|---|
| Topic 1: Train machine learning models | - Tune hyperparameters and evaluate models - Train models using Azure Machine Learning |
| Topic 2: Explore and analyze data | - Ingest and prepare data for modeling - Perform exploratory data analysis |
| Topic 3: Optimize and manage models | - Improve model performance - Track experiments and manage model lifecycle |
| Topic 4: Deploy and consume models | - Monitor deployed models and endpoints - Deploy models to endpoints |
| Topic 5: Design and prepare a machine learning solution | - Plan and configure Azure Machine Learning workspace - Select appropriate Azure services for machine learning workloads - Manage compute and data assets |
Microsoft認証試験を受かるかどうかが人生の重要な変化に関連することを、受験生はみんなよく知っています。CertShikenは低い価格で高品質の迫真のDP-100問題を受験生に提供して差し上げます。CertShikenの製品もコスト効率が良く、一年間の無料更新サービスを提供しています。当社のDP-100認定トレーニングの材料は、すぐに入手できます。当社のサイトは答案ダンプのリーディングプロバイダーで、あなたが利用したい最新かつ最正確のDP-100試験認定トレーニング材料、いわゆる試験問題と解答を提供しています。
質問 # 288
You have the following Azure subscriptions and Azure Machine Learning service workspaces:
You need to obtain a reference to the ml-project workspace.
Solution: Run the following Python code: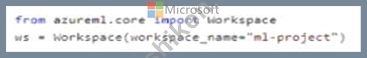
Does the solution meet the goal?
正解:A
質問 # 289
You need to identify the methods for dividing the data according, to the testing requirements.
Which properties should you select? To answer, select the appropriate option-, m the answer area. NOTE:
Each correct selection is worth one point.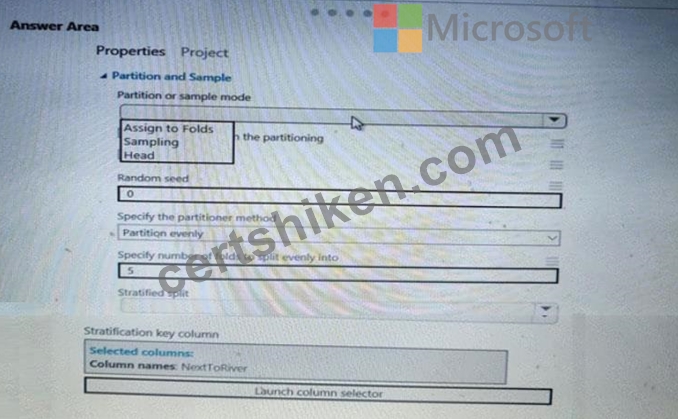
正解:
解説: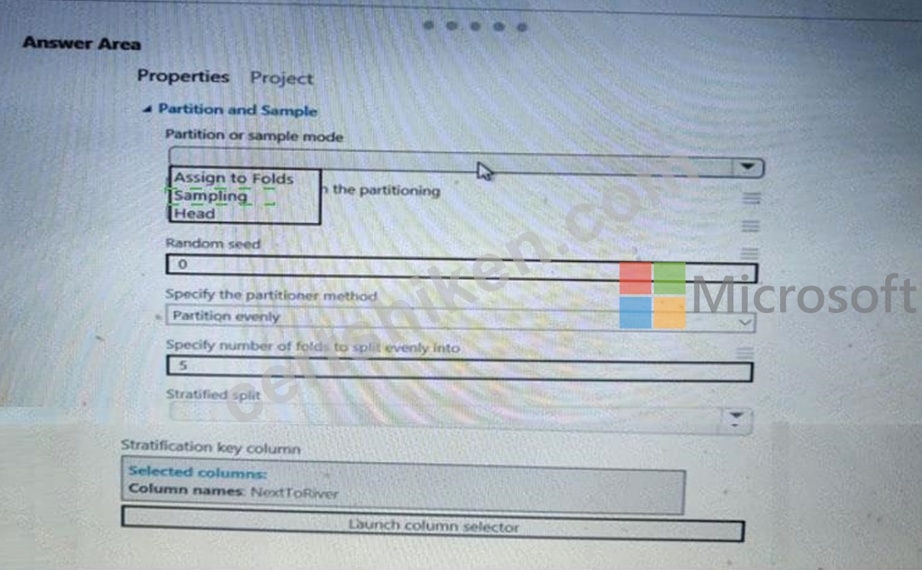
質問 # 290
You need to define an evaluation strategy for the crowd sentiment models.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.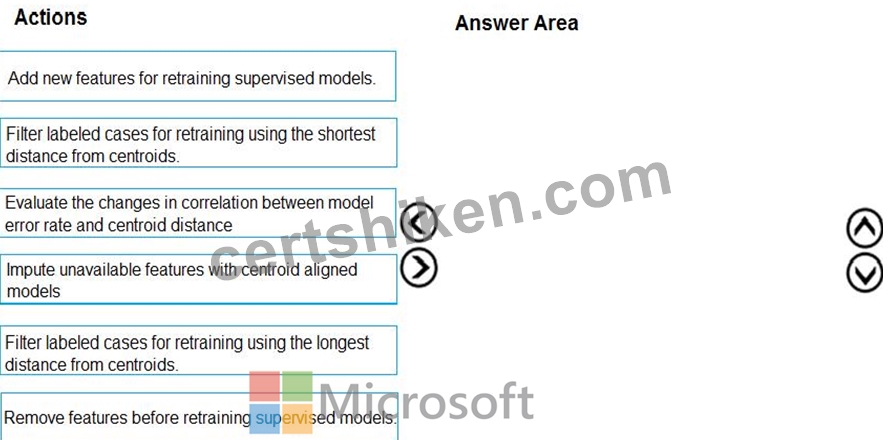
正解:
解説: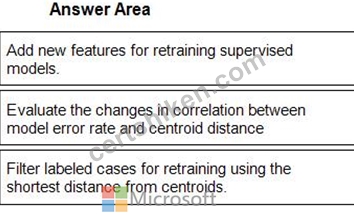
1 - Add new features for retraining supervised models.
2 - Evaluate the changes in correlation between model error rate and centroid distance
3 - Filter labeled cases for retraining using the shortest distance from centroids.
Reference:
https://en.wikipedia.org/wiki/Nearest_centroid_classifier
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/sweep-clustering
質問 # 291
You use Azure Machine Learning designer to create a real-time service endpoint. You have a single Azure Machine Learning service compute resource. You train the model and prepare the real-time pipeline for deployment You need to publish the inference pipeline as a web service. Which compute type should you use?
正解:A
解説:
Azure Kubernetes Service (AKS) can be used real-time inference.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/concept-compute-target
Topic 2, Case Study 2
Case study
Overview
You are a data scientist for Fabrikam Residences, a company specializing in quality private and commercial property in the United States. Fabrikam Residences is considering expanding into Europe and has asked you to investigate prices for private residences in major European cities. You use Azure Machine Learning Studio to measure the median value of properties. You produce a regression model to predict property prices by using the Linear Regression and Bayesian Linear Regression modules.
Datasets
There are two datasets in CSV format that contain property details for two cities, London and Paris, with the following columns: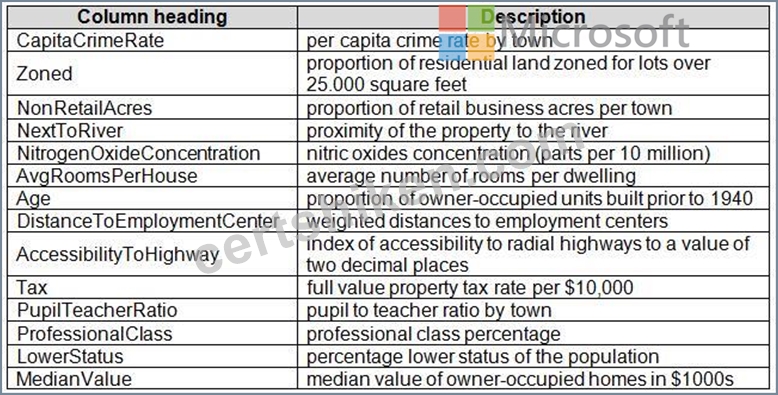
The two datasets have been added to Azure Machine Learning Studio as separate datasets and included as the starting point of the experiment.
Dataset issues
The AccessibilityToHighway column in both datasets contains missing values. The missing data must be replaced with new data so that it is modeled conditionally using the other variables in the data before filling in the missing values.
Columns in each dataset contain missing and null values. The dataset also contains many outliers. The Age column has a high proportion of outliers. You need to remove the rows that have outliers in the Age column.
The MedianValue and AvgRoomsinHouse columns both hold data in numeric format. You need to select a feature selection algorithm to analyze the relationship between the two columns in more detail.
Model fit
The model shows signs of overfitting. You need to produce a more refined regression model that reduces the overfitting.
Experiment requirements
You must set up the experiment to cross-validate the Linear Regression and Bayesian Linear Regression modules to evaluate performance.
In each case, the predictor of the dataset is the column named MedianValue. An initial investigation showed that the datasets are identical in structure apart from the MedianValue column. The smaller Paris dataset contains the MedianValue in text format, whereas the larger London dataset contains the MedianValue in numerical format. You must ensure that the datatype of the MedianValue column of the Paris dataset matches the structure of the London dataset.
You must prioritize the columns of data for predicting the outcome. You must use non-parameters statistics to measure the relationships.
You must use a feature selection algorithm to analyze the relationship between the MedianValue and AvgRoomsinHouse columns.
Model training
Given a trained model and a test dataset, you need to compute the permutation feature importance scores of feature variables. You need to set up the Permutation Feature Importance module to select the correct metric to investigate the model's accuracy and replicate the findings.
You want to configure hyperparameters in the model learning process to speed the learning phase by using hyperparameters. In addition, this configuration should cancel the lowest performing runs at each evaluation interval, thereby directing effort and resources towards models that are more likely to be successful.
You are concerned that the model might not efficiently use compute resources in hyperparameter tuning. You also are concerned that the model might prevent an increase in the overall tuning time. Therefore, you need to implement an early stopping criterion on models that provides savings without terminating promising jobs.
Testing
You must produce multiple partitions of a dataset based on sampling using the Partition and Sample module in Azure Machine Learning Studio. You must create three equal partitions for cross-validation. You must also configure the cross-validation process so that the rows in the test and training datasets are divided evenly by properties that are near each city's main river. The data that identifies that a property is near a river is held in the column named NextToRiver. You want to complete this task before the data goes through the sampling process.
When you train a Linear Regression module using a property dataset that shows data for property prices for a large city, you need to determine the best features to use in a model. You can choose standard metrics provided to measure performance before and after the feature importance process completes. You must ensure that the distribution of the features across multiple training models is consistent.
Data visualization
You need to provide the test results to the Fabrikam Residences team. You create data visualizations to aid in presenting the results.
You must produce a Receiver Operating Characteristic (ROC) curve to conduct a diagnostic test evaluation of the model. You need to select appropriate methods for producing the ROC curve in Azure Machine Learning Studio to compare the Two-Class Decision Forest and the Two-Class Decision Jungle modules with one another.
質問 # 292
You create an experiment in Azure Machine Learning Studio- You add a training dataset that contains 10.000 rows. The first 9.000 rows represent class 0 (90 percent). The first 1.000 rows represent class 1 (10 percent).
The training set is unbalanced between two Classes. You must increase the number of training examples for class 1 to 4,000 by using data rows. You add the Synthetic Minority Oversampling Technique (SMOTE) module to the experiment.
You need to configure the module.
Which values should you use? To answer, select the appropriate options in the dialog box in the answer area.
NOTE: Each correct selection is worth one point.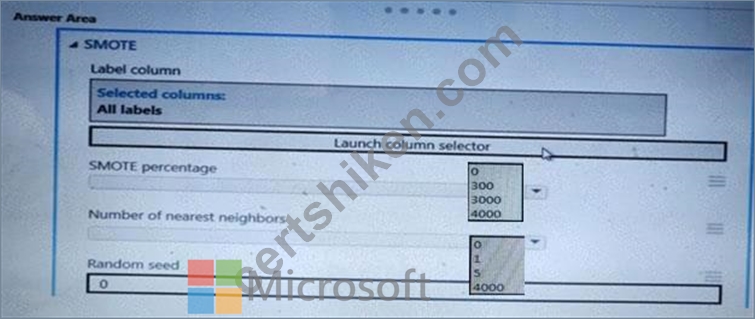
正解:
解説: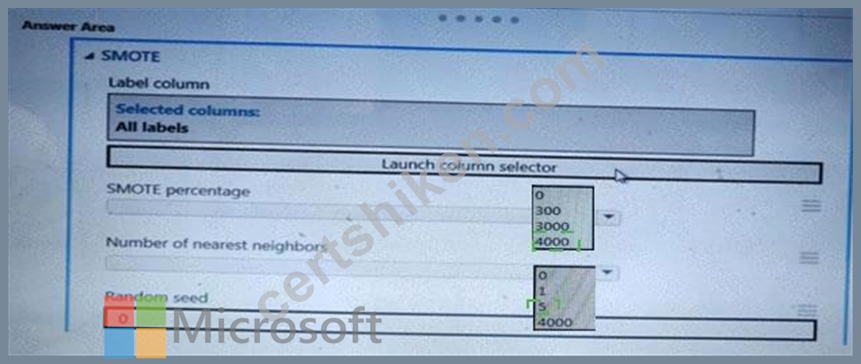
質問 # 293
......
あらゆる種類の試験を扱う場合、最も重要なことは、効果的にレビューするための科学的な方法を見つけることです。最も専門的な専門家によって編集された当社のDP-100練習資料。現在まで、世界中の何万人ものお客様がDP-100試験トレントをサポートしています。 DP-100学習教材に不慣れな場合は、参考のために無料のデモをダウンロードしてください。一部の未学習の試験の受験者は、DP-100練習教材で必需品をすばやく習得できます。したがって、教材は欠かすことのできない要素教材です。
DP-100認定内容: https://www.certshiken.com/DP-100-shiken.html
P.S.CertShikenがGoogle Driveで共有している無料の2026 Microsoft DP-100ダンプ:https://drive.google.com/open?id=1u-MC4hlUN4WMvuesnLBB7mm_sq630uYl