Databricks Databricks-Certified-Data-Engineer-Professional考題免費下載 & Databricks-Certified-Data-Engineer-Professional最新題庫

P.S. PDFExamDumps在Google Drive上分享了免費的2026 Databricks Databricks-Certified-Data-Engineer-Professional考試題庫:https://drive.google.com/open?id=1sHOHHCNrlYK6l7BmqT9L-jOfY9yg_rF8
根據過去的考試題和答案的研究,PDFExamDumps提供的Databricks Databricks-Certified-Data-Engineer-Professional練習題和真實的考試試題有緊密的相似性。PDFExamDumps是可以承諾您能100%通過你第一次參加的Databricks Databricks-Certified-Data-Engineer-Professional 認證考試。
Databricks Databricks-Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Objectives |
|---|
| Data Modeling and Transformation | - Performance optimization techniques
- Dimensional modeling concepts
- Spark SQL transformations
|
| Data Ingestion and Processing | - Structured Streaming fundamentals
- Batch and streaming ingestion with Auto Loader
- ETL pipeline design patterns
|
| Delta Lake and Data Management | - Schema evolution and enforcement
- Time travel and versioning
- Delta Lake transactions and ACID properties
|
| Production Pipelines and Orchestration | - Job scheduling and monitoring
- Databricks Workflows
- Error handling and recovery strategies
|
| Databricks Lakehouse Platform Architecture | - Data governance concepts (Unity Catalog basics)
- Medallion architecture (Bronze, Silver, Gold)
- Workspace and cluster architecture
|
>> Databricks Databricks-Certified-Data-Engineer-Professional考題免費下載 <<
Databricks-Certified-Data-Engineer-Professional最新題庫 - Databricks-Certified-Data-Engineer-Professional權威考題
在PDFExamDumps你可以很容易通過Databricks Databricks-Certified-Data-Engineer-Professional考試。在您第一次嘗試參加Databricks Databricks-Certified-Data-Engineer-Professional考試,選擇PDFExamDumps的Databricks Databricks-Certified-Data-Engineer-Professional訓練工具,下載Databricks Databricks-Certified-Data-Engineer-Professional練習題和答案,會為你考試增加信心,將有效幫助你通過Databricks Databricks-Certified-Data-Engineer-Professional考試。雖然其他線上網站也有關於Databricks Databricks-Certified-Data-Engineer-Professional認證考試的相關的培訓工具,但我們的產品品質是非常好。我們的考試練習題和答案準確性高,培訓材料覆蓋面大,不斷的更新和彙編,可以為你提供一個準確性非常高的考試準備,選擇了PDFExamDumps可以為你節約大量時間,可以讓你提早拿到Databricks Databricks-Certified-Data-Engineer-Professional認證證書,可以提早讓你成為Databricks IT行業中的專業人士。
最新的 Databricks Certification Databricks-Certified-Data-Engineer-Professional 免費考試真題 (Q151-Q156):
問題 #151
A junior data engineer is working to implement logic for a Lakehouse table named silver_device_recordings. The source data contains 100 unique fields in a highly nested JSON Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from structure.
The silver_device_recordings table will be used downstream for highly selective joins on a number of fields, and will also be leveraged by the machine learning team to filter on a handful of relevant fields, in total, 15 fields have been identified that will often be used for filter and join logic.
The data engineer is trying to determine the best approach for dealing with these nested fields before declaring the table schema.
Which of the following accurately presents information about Delta Lake and Databricks that may Impact their decision-making process?
- A. By default Delta Lake collects statistics on the first 32 columns in a table; these statistics are leveraged for data skipping when executing selective queries.
- B. Schema inference and evolution on Databricks ensure that inferred types will always accurately match the data types used by downstream systems.
- C. Tungsten encoding used by Databricks is optimized for storing string data: newly-added native support for querying JSON strings means that string types are always most efficient.
- D. Because Delta Lake uses Parquet for data storage, Dremel encoding information for nesting can be directly referenced by the Delta transaction log.
答案:A
解題說明:
Delta Lake, built on top of Parquet, enhances query performance through data skipping, which is based on the statistics collected for each file in a table. For tables with a large number of columns, Delta Lake by default collects and stores statistics only for the first 32 columns. These statistics include min/max values and null counts, which are used to optimize query execution by skipping irrelevant data files. When dealing with highly nested JSON structures, understanding this behavior is crucial for schema design, especially when determining which fields should be flattened or prioritized in the table structure to leverage data skipping efficiently for performance optimization.
問題 #152
Which statement regarding spark configuration on the Databricks platform is true?
- A. The Databricks REST API can be used to modify the Spark configuration properties for an interactive cluster without interrupting jobs.
- B. Spark configuration properties can only be set for an interactive cluster by creating a global init script.
- C. Spark configuration properties set for an interactive cluster with the Clusters UI will impact all notebooks attached to that cluster.
- D. Spark configuration set within an notebook will affect all SparkSession attached to the same interactive cluster
- E. When the same spar configuration property is set for an interactive to the same interactive cluster.
答案:C
解題說明:
When Spark configuration properties are set for an interactive cluster using the Clusters UI in Databricks, those configurations are applied at the cluster level. This means that all notebooks attached to that cluster will inherit and be affected by these configurations. This approach ensures consistency across all executions within that cluster, as the Spark configuration properties dictate aspects such as memory allocation, number of executors, and other vital execution parameters. This centralized configuration management helps maintain standardized execution environments across different notebooks, aiding in debugging and performance optimization.
問題 #153
A data engineer is testing a collection of mathematical functions, one of which calculates the area under a curve as described by another function.
Which kind of the test does the above line exemplify?
- A. functional
- B. Unit
- C. Manual
- D. End-to-end
- E. Integration
答案:B
解題說明:
A unit test is designed to verify the correctness of a small, isolated piece of code, typically a single function. Testing a mathematical function that calculates the area under a curve is an example of a unit test because it is testing a specific, individual function to ensure it operates as expected.
問題 #154
A data engineer wants to join a stream of advertisement impressions (when an ad was shown) with another stream of user clicks on advertisements to correlate when impression led to monitizable clicks.
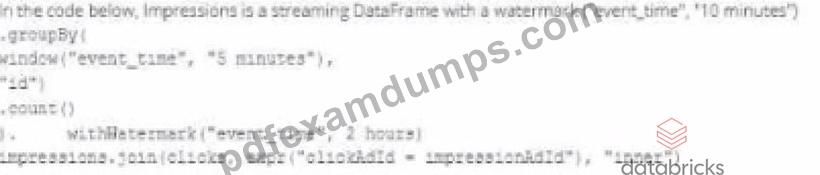
Which solution would improve the performance?
答案:A
解題說明:
When joining a stream of advertisement impressions with a stream of user clicks, you want to minimize the state that you need to maintain for the join. Option A suggests using a left outer join with the condition that clickTime == impressionTime, which is suitable for correlating events that occur at the exact same time. However, in a real-world scenario, you would likely need some leeway to account for the delay between an impression and a possible click. It's important to design the join condition and the window of time considered to optimize performance while still capturing the relevant user interactions. In this case, having the watermark can help with state management and avoid state growing unbounded by discarding old state data that's unlikely to match with new data.
問題 #155
A data team is implementing an append-only Delta Lake pipeline that processes both batch and streaming data. They want to ensure that schema changes in the source data are automatically incorporated without breaking the pipeline. Which configuration should the team use when writing data to the Delta table?
- A. mergeSchema = true
- B. validateSchema = false
- C. overwriteSchema = true
- D. ignoreChanges = false
答案:A
解題說明:
Setting mergeSchema to true allows Delta Lake to automatically evolve the table schema by incorporating new columns from the source data during writes. This enables append-only pipelines to handle schema changes seamlessly in both batch and streaming workloads without breaking the pipeline.
問題 #156
......
在我們的网站中,你可以獲得關于 Databricks Databricks-Certified-Data-Engineer-Professional 考古題的培訓工具。我們的IT精英團隊會及時為你提供準確以及詳細的關于 Databricks Databricks-Certified-Data-Engineer-Professional 考古題的培訓材料。通過使用我們提供的學習材料以及考試練習題和答案,能確保你第一次參加 Databricks Databricks-Certified-Data-Engineer-Professional 考古題認證考試時挑戰成功,而且不用花費大量時間和精力來準備考試。如果在考試過程中變題了,考生可以享受全額退費或一年內更新考題的服務,保障了考生的權利。
Databricks-Certified-Data-Engineer-Professional最新題庫: https://www.pdfexamdumps.com/Databricks-Certified-Data-Engineer-Professional_valid-braindumps.html
- 高質量的Databricks-Certified-Data-Engineer-Professional考題免費下載,最有效的學習資料幫助妳快速通過Databricks-Certified-Data-Engineer-Professional考試 🍕 在“ www.kaoguti.com ”網站上免費搜索➡ Databricks-Certified-Data-Engineer-Professional ️⬅️題庫Databricks-Certified-Data-Engineer-Professional套裝
- 高質量的Databricks-Certified-Data-Engineer-Professional考題免費下載,最有效的學習資料幫助妳快速通過Databricks-Certified-Data-Engineer-Professional考試 ⚖ 《 www.newdumpspdf.com 》上的“ Databricks-Certified-Data-Engineer-Professional ”免費下載只需搜尋Databricks-Certified-Data-Engineer-Professional證照考試
- 最有效的Databricks-Certified-Data-Engineer-Professional考題免費下載-最新考試題庫幫助妳壹次性通過考試Databricks-Certified-Data-Engineer-Professional:Databricks Certified Data Engineer Professional Exam 👷 請在【 www.newdumpspdf.com 】網站上免費下載▷ Databricks-Certified-Data-Engineer-Professional ◁題庫Databricks-Certified-Data-Engineer-Professional權威認證
- 精準的Databricks-Certified-Data-Engineer-Professional考題免費下載,高質量的考試資料幫助妳快速通過Databricks-Certified-Data-Engineer-Professional考試 🏣 透過⇛ www.newdumpspdf.com ⇚輕鬆獲取▛ Databricks-Certified-Data-Engineer-Professional ▟免費下載Databricks-Certified-Data-Engineer-Professional資料
- 最有效的Databricks-Certified-Data-Engineer-Professional考題免費下載-最新考試題庫幫助妳壹次性通過考試Databricks-Certified-Data-Engineer-Professional:Databricks Certified Data Engineer Professional Exam 🔸 ➽ tw.fast2test.com 🢪上的⏩ Databricks-Certified-Data-Engineer-Professional ⏪免費下載只需搜尋Databricks-Certified-Data-Engineer-Professional認證題庫
- 最有效的Databricks-Certified-Data-Engineer-Professional考題免費下載-最新考試題庫幫助妳壹次性通過考試Databricks-Certified-Data-Engineer-Professional:Databricks Certified Data Engineer Professional Exam 🥭 在{ www.newdumpspdf.com }搜索最新的➽ Databricks-Certified-Data-Engineer-Professional 🢪題庫Databricks-Certified-Data-Engineer-Professional資料
- 高質量的Databricks-Certified-Data-Engineer-Professional考題免費下載,最有效的學習資料幫助妳快速通過Databricks-Certified-Data-Engineer-Professional考試 🛄 ⇛ www.pdfexamdumps.com ⇚最新「 Databricks-Certified-Data-Engineer-Professional 」問題集合最新Databricks-Certified-Data-Engineer-Professional考證
- Databricks-Certified-Data-Engineer-Professional真題材料 👲 Databricks-Certified-Data-Engineer-Professional在線題庫 🚊 Databricks-Certified-Data-Engineer-Professional在線題庫 🎨 到( www.newdumpspdf.com )搜索「 Databricks-Certified-Data-Engineer-Professional 」輕鬆取得免費下載Databricks-Certified-Data-Engineer-Professional考古題分享
- Databricks-Certified-Data-Engineer-Professional資料 🚹 Databricks-Certified-Data-Engineer-Professional考題套裝 🍮 Databricks-Certified-Data-Engineer-Professional認證考試解析 🎅 進入⏩ www.newdumpspdf.com ⏪搜尋➽ Databricks-Certified-Data-Engineer-Professional 🢪免費下載新版Databricks-Certified-Data-Engineer-Professional題庫
- Databricks-Certified-Data-Engineer-Professional證照 ⏬ Databricks-Certified-Data-Engineer-Professional在線題庫 📢 Databricks-Certified-Data-Engineer-Professional認證題庫 ⛪ 免費下載➠ Databricks-Certified-Data-Engineer-Professional 🠰只需在▷ www.newdumpspdf.com ◁上搜索Databricks-Certified-Data-Engineer-Professional認證考試解析
- Databricks-Certified-Data-Engineer-Professional考題免費下載100%通過考試|Databricks Databricks-Certified-Data-Engineer-Professional最新題庫:Databricks Certified Data Engineer Professional Exam 🐋 免費下載{ Databricks-Certified-Data-Engineer-Professional }只需進入▶ www.newdumpspdf.com ◀網站Databricks-Certified-Data-Engineer-Professional認證題庫
- www.stes.tyc.edu.tw, doodleordie.com, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
2026 PDFExamDumps最新的Databricks-Certified-Data-Engineer-Professional PDF版考試題庫和Databricks-Certified-Data-Engineer-Professional考試問題和答案免費分享:https://drive.google.com/open?id=1sHOHHCNrlYK6l7BmqT9L-jOfY9yg_rF8



