Pass Guaranteed 2026 DY0-001: Unparalleled CompTIA DataAI Certification Exam Test Prep

DOWNLOAD the newest BraindumpStudy DY0-001 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1__RQEcqLzVCHYr8HcjaQJQvmMMU2F3tT
If you buy the DY0-001 learning materials from our company, we are glad to provide you with the high quality DY0-001 study question and the best service. The philosophy of our company is "quality is life, customer is god." We can promise that our company will provide all customers with the perfect quality guarantee system and sound management system. It is not necessary for you to have any worry about the quality and service of the DY0-001 Learning Materials from our company. If you decide to buy the DY0-001 study question from our company, you will receive a lot beyond your imagination.
CompTIA DY0-001 Exam Overview:
| Certification Vendor: | CompTIA |
|---|
| Exam Name: | CompTIA DataAI Certification Exam |
|---|
| Exam Number: | DY0-001 |
|---|
| Certificate Validity Period: | Usually 3 years |
|---|
| Exam Price: | $529 USD |
|---|
| Available Languages: | Japanese, English |
|---|
| Passing Score: | Pass/Fail (No scaled score) |
|---|
| Exam Format: | Performance-Based, Multiple Choice |
|---|
| Related Certifications: | CompTIA DataAI (formerly DataX) |
|---|
| Exam Duration: | 165 minutes |
|---|
| Real Exam Qty: | Up to 90 |
|---|
| Sample Questions: | CompTIA DY0-001 Sample Questions |
|---|
| Exam Way: | Available at Pearson VUE testing centers or via online proctoring (OnVUE). |
|---|
| Pre Condition: | 5+ years of experience in data science or a similar role recommended. |
|---|
| Official Syllabus URL: | https://www.comptia.org/en-us/certifications/dataai |
|---|
>> DY0-001 Test Prep <<
Test DY0-001 Answers | DY0-001 Test Dump
We know how expensive it is to take DY0-001 exam. It costs both time and money. However, with the most reliable exam dumps material from BraindumpStudy, we guarantee that you will pass the DY0-001 exam on your first try! You’ve heard it right. We are so confident about our DY0-001 Exam Dumps for CompTIA DY0-001 exam that we are offering a money back guarantee, if you fail. Yes you read it right, if our DY0-001 exam braindumps didn’t help you pass, we will issue a refund - no other questions asked.
| Topic | Details |
|---|
| Topic 1 | - Machine Learning: This section of the exam measures skills of a Machine Learning Engineer and covers foundational ML concepts such as overfitting, feature selection, and ensemble models. It includes supervised learning algorithms, tree-based methods, and regression techniques. The domain introduces deep learning frameworks and architectures like CNNs, RNNs, and transformers, along with optimization methods. It also addresses unsupervised learning, dimensionality reduction, and clustering models, helping candidates understand the wide range of ML applications and techniques used in modern analytics.
|
| Topic 2 | - Mathematics and Statistics: This section of the exam measures skills of a Data Scientist and covers the application of various statistical techniques used in data science, such as hypothesis testing, regression metrics, and probability functions. It also evaluates understanding of statistical distributions, types of data missingness, and probability models. Candidates are expected to understand essential linear algebra and calculus concepts relevant to data manipulation and analysis, as well as compare time-based models like ARIMA and longitudinal studies used for forecasting and causal inference.
|
| Topic 3 | - Operations and Processes: This section of the exam measures skills of an AI
- ML Operations Specialist and evaluates understanding of data ingestion methods, pipeline orchestration, data cleaning, and version control in the data science workflow. Candidates are expected to understand infrastructure needs for various data types and formats, manage clean code practices, and follow documentation standards. The section also explores DevOps and MLOps concepts, including continuous deployment, model performance monitoring, and deployment across environments like cloud, containers, and edge systems.
|
| Topic 4 | - Modeling, Analysis, and Outcomes: This section of the exam measures skills of a Data Science Consultant and focuses on exploratory data analysis, feature identification, and visualization techniques to interpret object behavior and relationships. It explores data quality issues, data enrichment practices like feature engineering and transformation, and model design processes including iterations and performance assessments. Candidates are also evaluated on their ability to justify model selections through experiment outcomes and communicate insights effectively to diverse business audiences using appropriate visualization tools.
|
| Topic 5 | - Specialized Applications of Data Science: This section of the exam measures skills of a Senior Data Analyst and introduces advanced topics like constrained optimization, reinforcement learning, and edge computing. It covers natural language processing fundamentals such as text tokenization, embeddings, sentiment analysis, and LLMs. Candidates also explore computer vision tasks like object detection and segmentation, and are assessed on their understanding of graph theory, anomaly detection, heuristics, and multimodal machine learning, showing how data science extends across multiple domains and applications.
|
CompTIA DataAI Certification Exam Sample Questions (Q62-Q67):
NEW QUESTION # 62
Given the following:
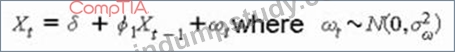
Which of the following time series models best represents this process?
- A. SARIMA(1, 1, 1) x (1, 1, 1)1
- B. AR(1)
- C. ARIMA(1,1,1)
- D. ARMA(1,1)
Answer: B
Explanation:
The model has a single autoregressive term and only white‐noise errors, matching the definition of an AR(1) process.
NEW QUESTION # 63
Which of the following describes the appropriate use case for PCA?
- A. Dimensionality reduction
- B. Regression
- C. Recommendation
- D. Classification
Answer: A
Explanation:
# Principal Component Analysis (PCA) is an unsupervised technique used to reduce the dimensionality of large datasets by transforming correlated features into a smaller set of uncorrelated components (principal components) while retaining the most variance.
Why the other options are incorrect:
* B: Classification is a predictive modeling task; PCA is not inherently predictive.
* C: Regression models numerical relationships; PCA does not predict outcomes.
* D: Recommendation systems use collaborative or content filtering, not PCA directly.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 3.3:"PCA is primarily used for reducing the number of variables while preserving data structure and minimizing information loss."
* Pattern Recognition and Machine Learning, Chapter 12:"PCA identifies principal axes of variation and is widely used in preprocessing for dimensionality reduction."
-
NEW QUESTION # 64
SIMULATION
A data scientist needs to determine whether product sales are impacted by other contributing factors. The client has provided the data scientist with sales and other variables in the data set.
The data scientist decides to test potential models that include other information.
INSTRUCTIONS
Part 1
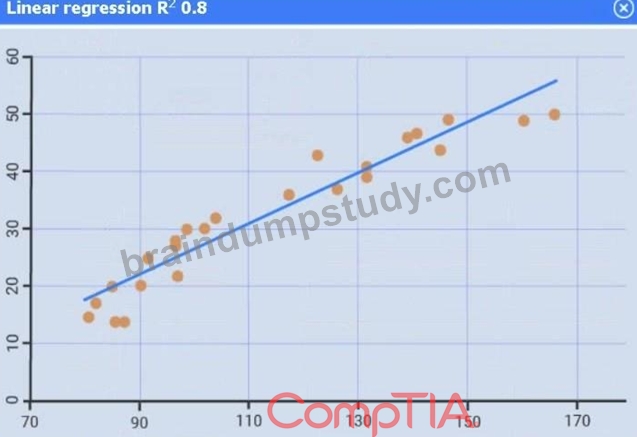
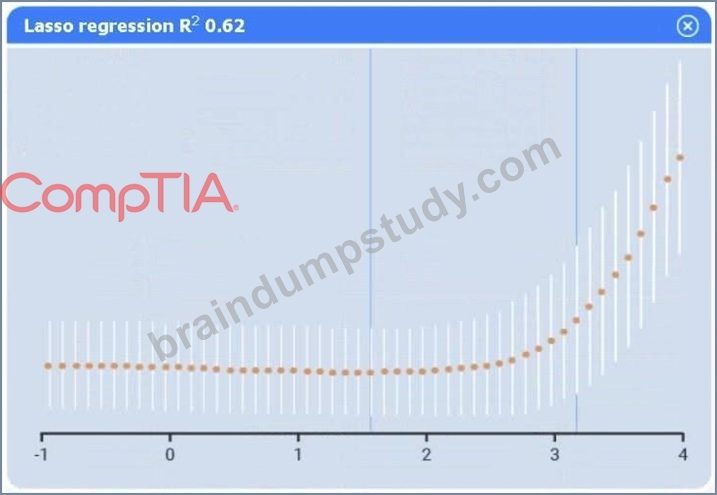
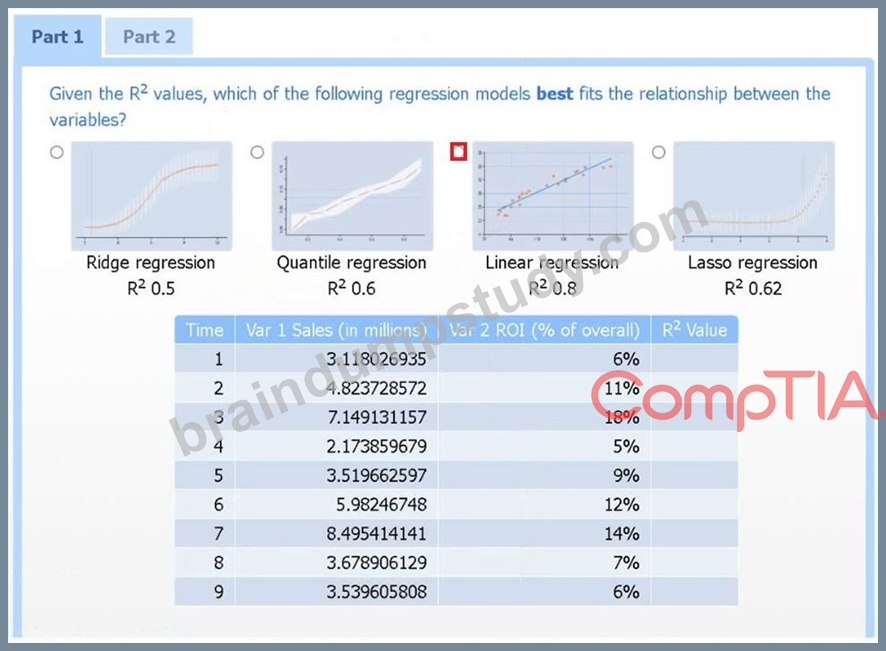
Use the information provided in the table to select the appropriate regression model.
Part 2
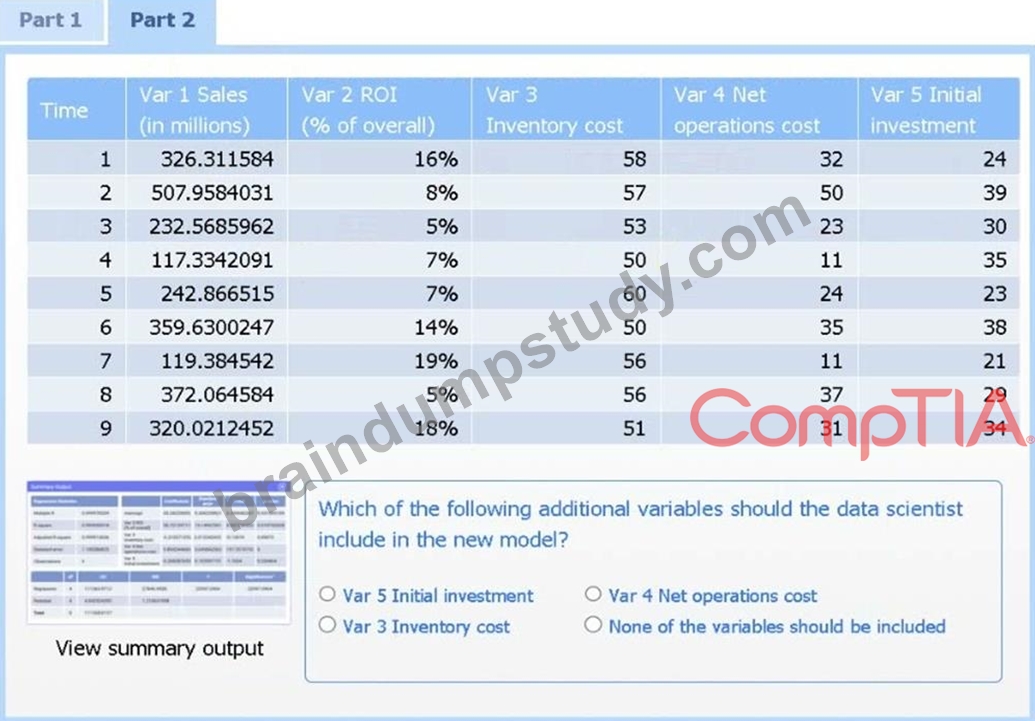
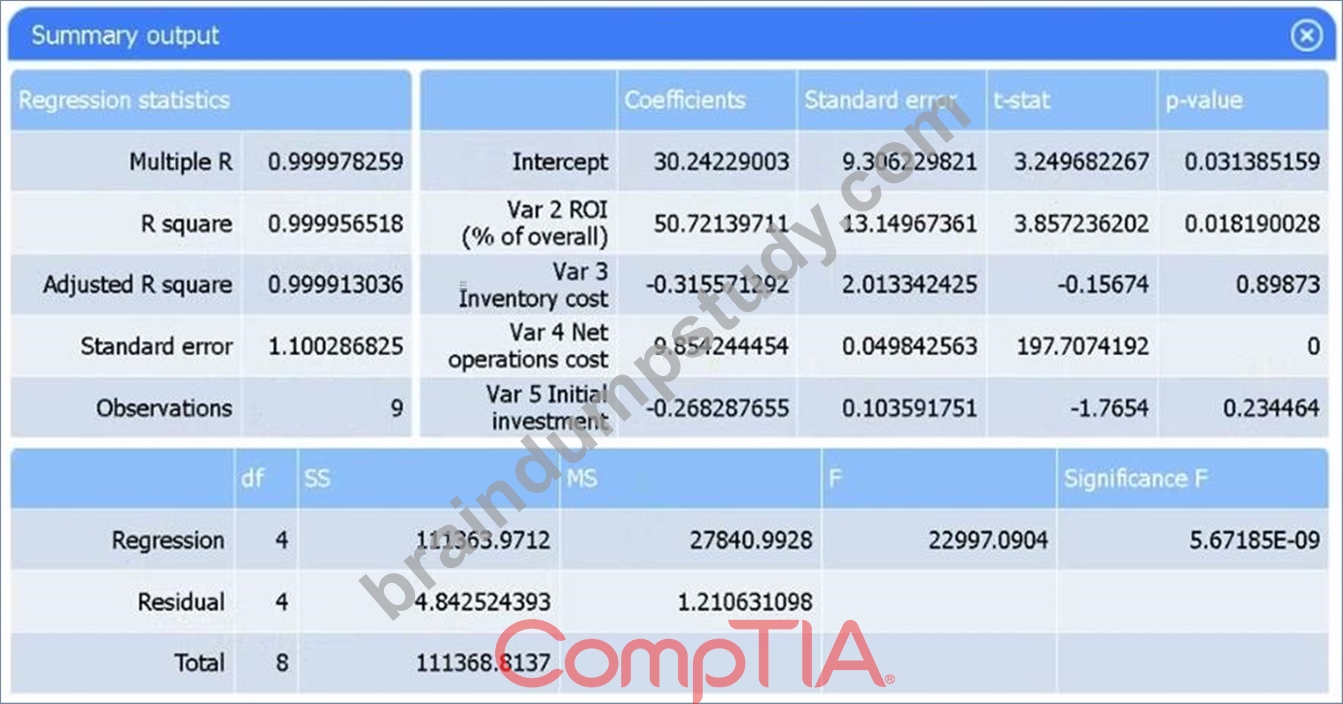
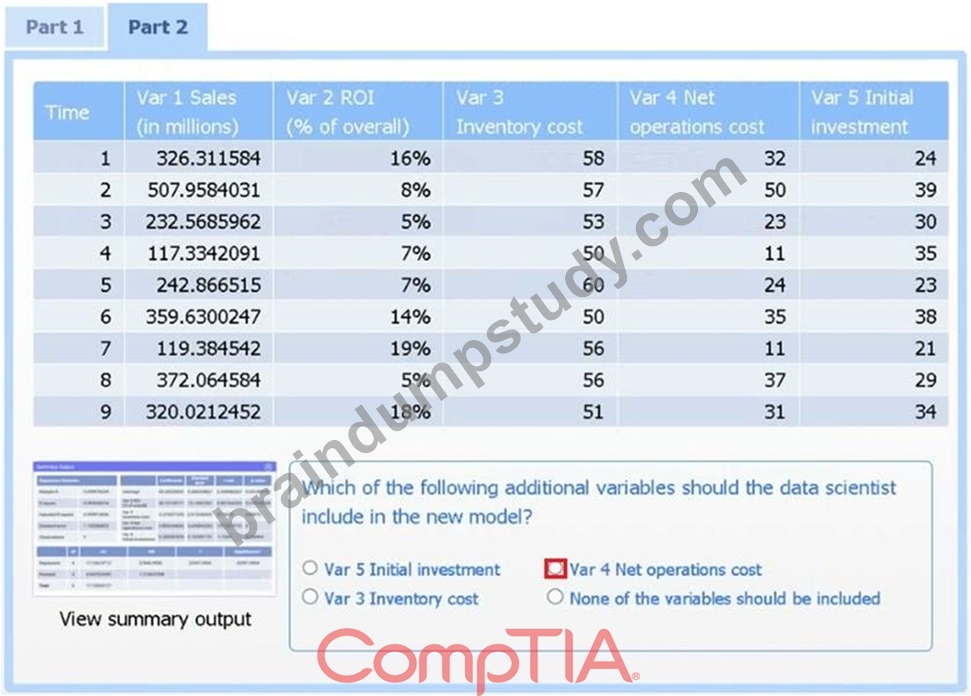
Review the summary output and variable table to determine which variable is statistically significant.
If at any time you would like to bring back the initial state of the simulation, please click the Reset All button.
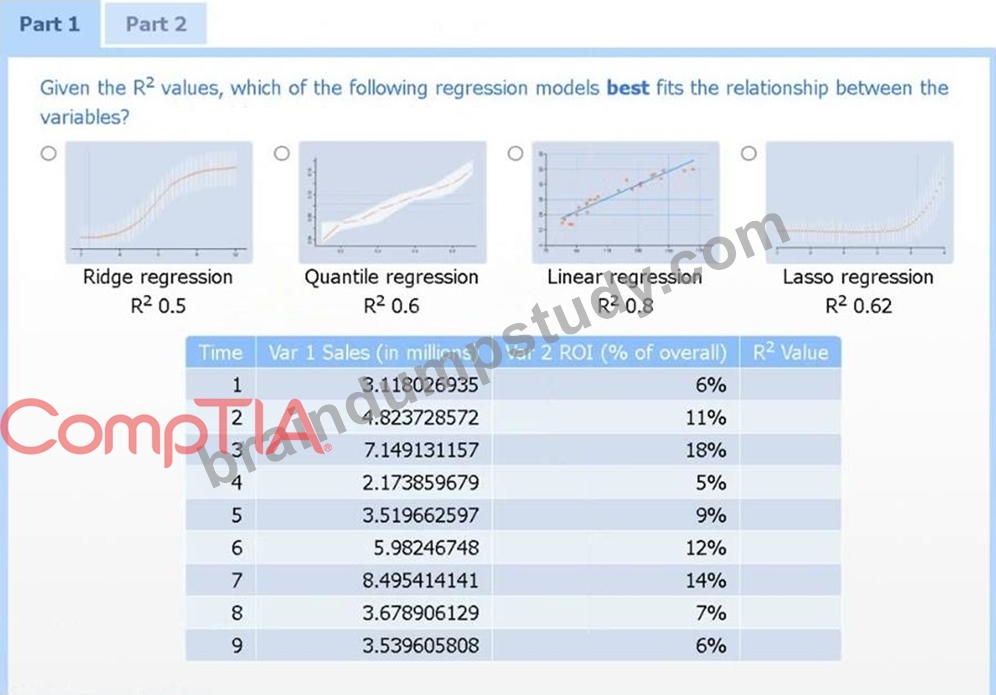
Answer:
Explanation:
Part 1
Linear regression.
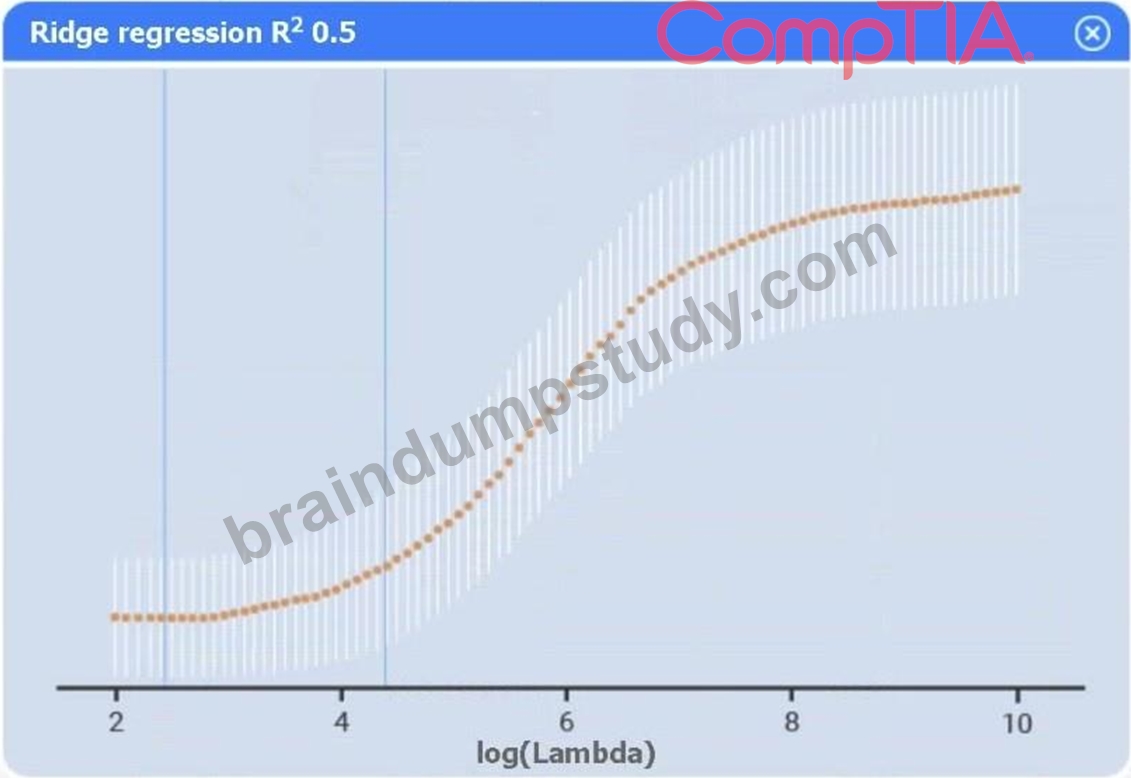
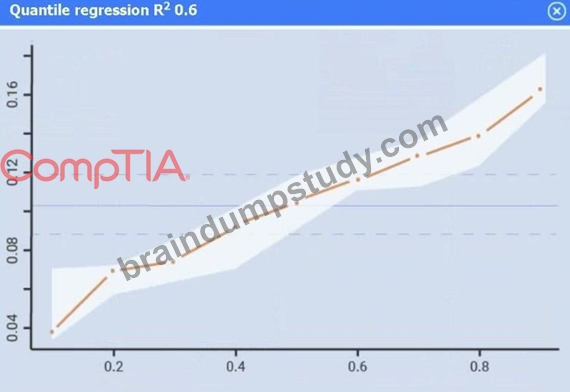
Of the four models, linear regression has the highest R² (0.8), indicating it explains the greatest proportion of variance in sales.
Part 2
Var 4 - Net operations cost.
Net operations cost has a p-value of essentially 0 (far below 0.05), indicating it is the only additional predictor statistically significant in explaining sales. Neither inventory cost (p≈0.90) nor initial investment (p≈0.23) reach significance.
NEW QUESTION # 65
A data analyst wants to use compression on an analyzed data set and send it to a new destination for further processing. Which of the following issues will most likely occur?
- A. Server memory usage will be too high.
- B. Operating system support will be missing.
- C. Server CPU usage will be too high.
- D. Library dependency will be missing.
Answer: C
Explanation:
Compression and decompression are CPU‐intensive operations; on large data sets, the extra processing load can significantly spike CPU utilization. Memory, OS support, or library dependencies are far less likely to be the primary bottleneck in a standard compression workflow.
NEW QUESTION # 66
A data scientist is building a model to predict customer credit scores based on information collected from reporting agencies. The model needs to automatically adjust its parameters to adapt to recent changes in the information collected. Which of the following is the best model to use?
- A. Decision tree
- B. XGBoost
- C. Random forest
- D. Linear discriminant analysis
Answer: B
Explanation:
# XGBoost (Extreme Gradient Boosting) is a high-performance, scalable ensemble algorithm that builds decision trees in sequence and adjusts to errors iteratively. It also supports incremental training, making it adaptive to changing data patterns - ideal for dynamically updated credit information.
Why the other options are incorrect:
* A: Decision trees are static once trained and don't adapt unless retrained.
* B: Random forest is an ensemble of trees but lacks the adaptive boosting component.
* C: LDA is a linear classification technique - not suited for adapting to changing data distributions.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 4.3:"XGBoost is highly efficient and supports iterative learning, making it well-suited for data environments that evolve over time."
* Applied Machine Learning Guide, Chapter 8:"XGBoost adapts to changes by refining errors across iterations, providing robustness in dynamic systems."
-
NEW QUESTION # 67
......
Test DY0-001 Answers: https://www.braindumpstudy.com/DY0-001_braindumps.html
- Top DY0-001 Test Prep | Professional Test DY0-001 Answers: CompTIA DataAI Certification Exam 🦦 Search for ✔ DY0-001 ️✔️ and download it for free immediately on “ www.troytecdumps.com ” 👠DY0-001 Reliable Test Online
- CompTIA certification DY0-001 the latest examination questions and answers come out 🕸 Search for ➡ DY0-001 ️⬅️ and download exam materials for free through ▛ www.pdfvce.com ▟ 🕙DY0-001 Book Pdf
- DY0-001 Exam Materials 🐗 DY0-001 Exam Tips 🔙 DY0-001 Book Pdf 🏵 Open [ www.prepawaypdf.com ] enter “ DY0-001 ” and obtain a free download 👈Latest DY0-001 Test Question
- DY0-001 Exam Materials 🤦 Latest DY0-001 Exam Registration 🔏 Latest DY0-001 Test Question 🍒 Immediately open ⏩ www.pdfvce.com ⏪ and search for [ DY0-001 ] to obtain a free download 😅DY0-001 Test Topics Pdf
- Latest updated DY0-001 Test Prep | Easy To Study and Pass Exam at first attempt - Hot CompTIA CompTIA DataAI Certification Exam ⚖ Search for ⏩ DY0-001 ⏪ on ➠ www.examdiscuss.com 🠰 immediately to obtain a free download 🈵Real DY0-001 Torrent
- Exam Dumps DY0-001 Collection 🦔 DY0-001 Exam Materials 🥅 DY0-001 Reliable Test Online ⤴ Search for ⮆ DY0-001 ⮄ and download it for free immediately on “ www.pdfvce.com ” 🙋DY0-001 Book Pdf
- Latest DY0-001 Test Question 🤶 DY0-001 Free Exam Questions 🍏 DY0-001 Test Questions Fee 🟧 Search for ➽ DY0-001 🢪 and download it for free immediately on { www.pdfdumps.com } 🤩DY0-001 Study Reference
- DY0-001 Test Topics Pdf 🦳 Latest DY0-001 Test Question 🏡 Free DY0-001 Practice 💸 Download ( DY0-001 ) for free by simply searching on ⏩ www.pdfvce.com ⏪ 🎬Exam Dumps DY0-001 Collection
- Will CompTIA DY0-001 Practice Questions help You to Pass the certification exam? 🟥 Easily obtain free download of ▷ DY0-001 ◁ by searching on ➤ www.dumpsquestion.com ⮘ ✉DY0-001 Test Topics Pdf
- CompTIA certification DY0-001 the latest examination questions and answers come out 😅 Search for “ DY0-001 ” on ➠ www.pdfvce.com 🠰 immediately to obtain a free download 😹DY0-001 Test Topics Pdf
- CompTIA certification DY0-001 the latest examination questions and answers come out 🛢 Search for ( DY0-001 ) on “ www.testkingpass.com ” immediately to obtain a free download 🙅Download DY0-001 Pdf
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, writeablog.net, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
What's more, part of that BraindumpStudy DY0-001 dumps now are free: https://drive.google.com/open?id=1__RQEcqLzVCHYr8HcjaQJQvmMMU2F3tT