그 외, Pass4Test DP-600 시험 문제집 일부가 지금은 무료입니다: https://drive.google.com/open?id=15FYJ595AQHdJ6BRT_o2ZfbFbbLOHHEle
Pass4Test 의 Microsoft인증 DP-600덤프는Microsoft인증 DP-600시험에 도전장을 던진 분들이 신뢰할수 있는 든든한 길잡이 입니다. Microsoft인증 DP-600시험대비 덤프뿐만아니라 다른 IT인증시험에 대비한 덤프자료도 적중율이 끝내줍니다. Microsoft인증 DP-600시험이나 다른 IT인증자격증시험이나Pass4Test제품을 사용해보세요.투자한 덤프비용보다 훨씬 큰 이득을 보실수 있을것입니다.
| 주제 | 소개 |
|---|---|
| 주제 1 |
|
| 주제 2 |
|
| 주제 3 |
|
Pass4Test 에서 출시한Microsoft인증DP-600 덤프는Microsoft인증DP-600 실제시험의 출제범위와 출제유형을 대비하여 제작된 최신버전 덤프입니다. 시험문제가 바뀌면 제일 빠른 시일내에 덤프를 업데이트 하도록 최선을 다하고 있으며 1년 무료 업데이트서비스를 제공해드립니다. 1년 무료 업데이트서비스를 제공해드리기에 시험시간을 늦추어도 시험성적에 아무런 페를 끼치지 않습니다. Pass4Test에 믿음을 느낄수 있도록 구매사이트마다 무료샘플 다운가능기능을 설치하였습니다.무료샘플을 체험해보시고Pass4Test을 선택해주세요.
질문 # 176
You have a Fabric workspace named Workspace1.
You have three groups named Group1, Group2, and Group3.
You need to assign a workspace role to each group. The solution must follow the principle of least privilege and meet the following requirements:
Group1 must be able to write data to Workspace1, but be unable to add members to Workspace1.
Group2 must be able to configure and maintain the settings of Workspace1.
Group3 must be able to write data and add members to Workspace1, but be unable to delete Workspace1.
Which workspace role should you assign to each group? To answer, drag the appropriate roles to the correct groups. Each role may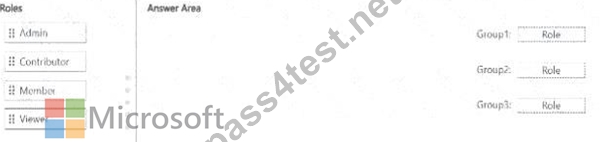
정답:
설명: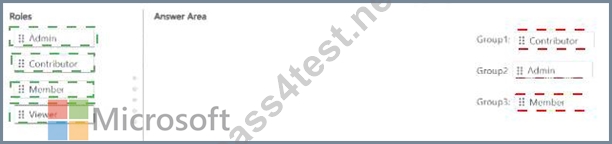
Explanation: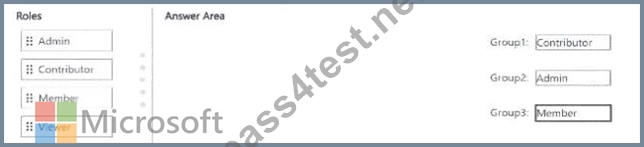
Comprehensive Detailed Explanation
Workspace Roles in Microsoft Fabric (same as Power BI workspaces):
Viewer
Can only read/view content.
Cannot create or edit.
Contributor
Can create and write data (datasets, reports, semantic models).
Cannot manage permissions or workspace settings.
Member
Can create and edit content.
Can also add/remove people to the workspace (except Admins).
Cannot delete the workspace itself.
Admin
Full control: can configure settings, add/remove members, and delete the workspace.
Step 1: Group1 Requirements
Must be able to write data.
Must NOT be able to add members.
# Contributor (can write but cannot manage membership).
Step 2: Group2 Requirements
Must be able to configure and maintain workspace settings.
# Only Admin role allows configuring workspace-level settings.
# Admin.
Step 3: Group3 Requirements
Must be able to write data.
Must be able to add members.
Must NOT be able to delete the workspace.
# This matches the Member role.
질문 # 177
Drag and Drop Question
You have a Fabric lakehouse named Lakehouse1.
You have the data sources shown in the following table.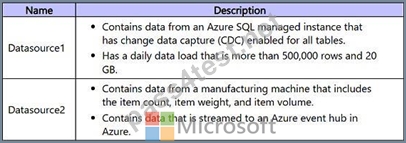
You need to ingest data from both data sources into Lakehouse1. The solution must minimize maintenance and development time.
What should you use to ingest the data into each data source? To answer, drag the appropriate options to the correct data sources. Each option may be used once, more than once, or not at all.
You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.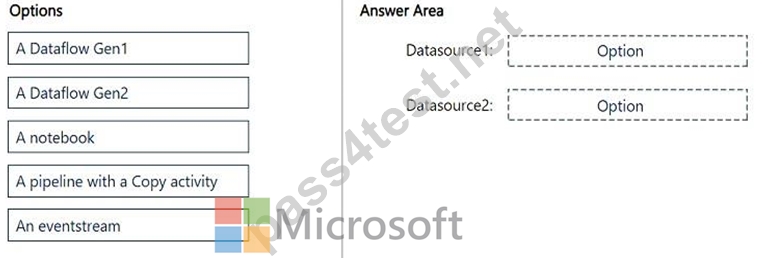
정답:
설명: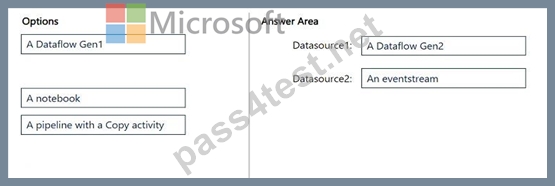
Explanation:
Box 1: ADLS Gen2
Contains data from an Azure SQL managed instance that has a change data capture (CDC) enabled for all tables.
Has a daily data load that is more than 500,000 rows and 20 GB.
Change data capture in Azure Data Factory and Azure Synapse Analytics.
Auto incremental extraction in mapping data flow.
The newly updated rows or updated files can be automatically detected and extracted by ADF mapping data flow from the source stores. When you want to get delta data from the databases, the incremental column is required to identify the changes. When you want to load new files or updated files only from a storage store, ADF mapping data flow just works through files' last modify time.
Box 2: An eventstream
Contains data from a manufacturing machine that includes the item count, item weight, and item volume.
Contains data that is streamed to an Azure event hub in Azure.
Reference:
https://learn.microsoft.com/en-us/azure/data-factory/concepts-change-data-capture
https://learn.microsoft.com/en-us/fabric/real-time-intelligence/event-streams/transform-and- stream-real-time-events-to-lakehouse
질문 # 178
You have a Fabric tenant that contains a warehouse named DW1 and a lakehouse named LH1.
DW1 contains a table named Sales.Product. LH1 contains a table named Sales.Orders.
You plan to schedule an automated process that will create a new point-in-time (PIT) table named Sales.ProductOrder in DW1. Sales.ProductOrder will be built by using the results of a query that will join Sales.Product and Sales.Orders.
You need to ensure that the types of columns in Sales.ProductOrder match the column types in the source tables. The solution must minimize the number of operations required to create the new table.
Which operation should you use?
정답:C
설명:
The CREATE TABLE AS SELECT (CTAS) statement allows you to create a new table directly from the results of a query, including joining tables. It automatically determines the column types based on the query's result set, ensuring they match the source tables. This minimizes the number of operations required.
질문 # 179
You have a KQL database that contains a table named Readings.
You need to query Readings and return the results shown in the following table.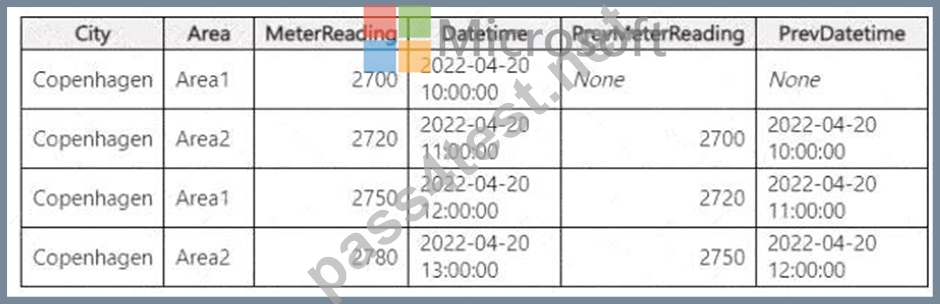
How should you complete the query? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.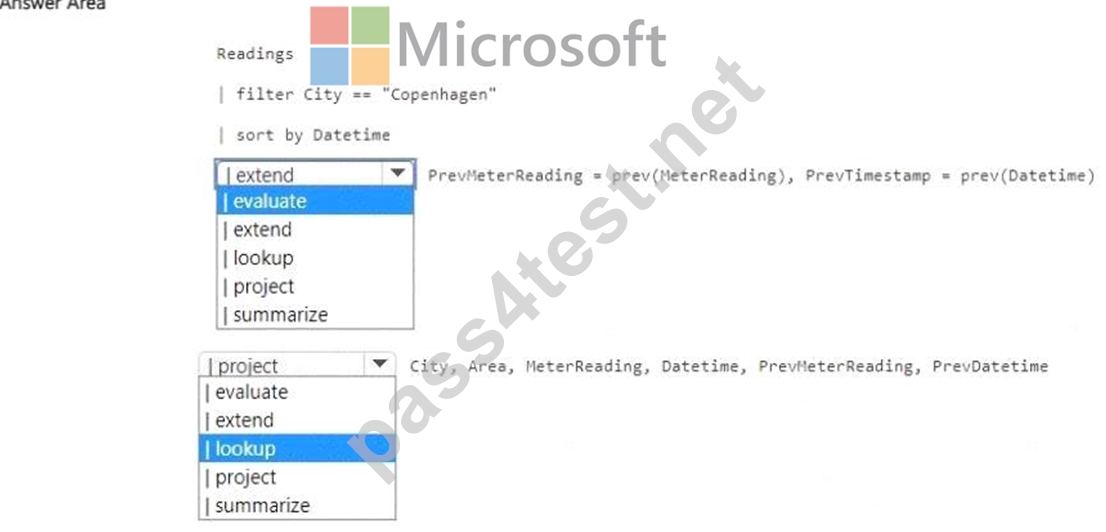
정답:
설명: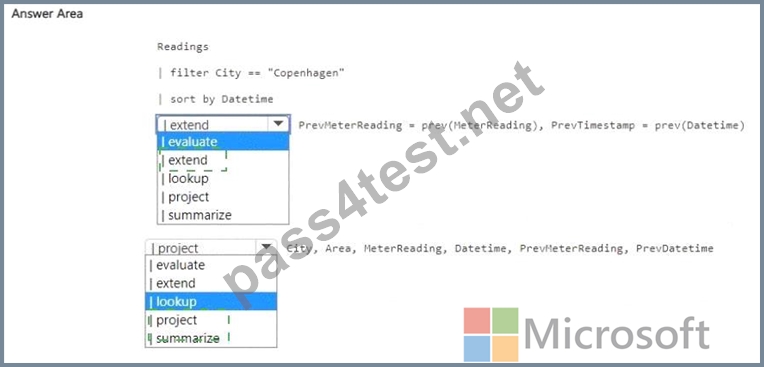
Explanation: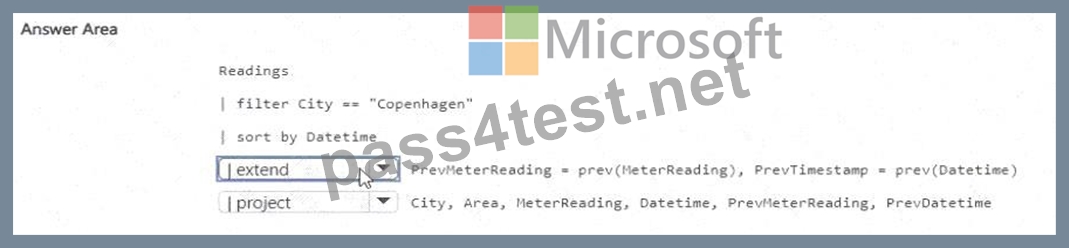
Comprehensive Detailed Explanation
We need to query a KQL database table named Readings to generate output that includes both the current reading and the previous reading values and datetime for each row.
Step 1: Understanding Requirements
The output table shows:
City, Area, MeterReading, Datetime
PrevMeterReading, PrevDatetime
The prev() function in KQL is used to access the value of a column from the previous row (based on order).
Step 2: Query Construction
We start with filtering:
Readings
| where City == " Copenhagen "
| sort by Datetime
To add columns that calculate the previous reading and previous datetime, we use extend:
| extend PrevMeterReading = prev(MeterReading), PrevDatetime = prev(Datetime) extend creates new columns.
prev() pulls the previous row's values.
Finally, we only want specific columns in the output. For this, we use project:
| project City, Area, MeterReading, Datetime, PrevMeterReading, PrevDatetime Step 3: Completed Query Readings
| where City == " Copenhagen "
| sort by Datetime
| extend PrevMeterReading = prev(MeterReading), PrevDatetime = prev(Datetime)
| project City, Area, MeterReading, Datetime, PrevMeterReading, PrevDatetime Why This is Correct extend adds calculated columns.
prev() gives access to the previous row.
project selects only the required columns.
This matches exactly the table shown in the question.
References
Kusto Query Language - extend operator
Kusto Query Language - project operator
prev() function in KQL
질문 # 180
You have a Fabric workspace named Workspace1 that contains an eventstream named Eventstream1.
Eventstream1 reads data from an Azure event hub named Eventhub1.
Eventhub1 contains the following columns.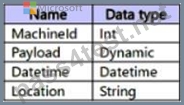
You need to add a continuous percentile calculation to the Payload column. The solution must minimize development effort.
What should you do?
정답:B
설명:
The Aggregate transformation in Fabric event streams can be used to calculate a continuous percentile. You can add a "Percentile (continuous)" aggregation to the transformation to achieve this.
By using the Aggregate transformation and selecting the "Percentile (continuous)" option, you can calculate the percentile of a column's values within the event stream, making it a valuable tool for real-time analytics in Fabric.
Reference:
https://learn.microsoft.com/en-us/fabric/real-time-intelligence/event-streams/overview
질문 # 181
......
Microsoft DP-600시험은 Pass4Test 에서 출시한Microsoft DP-600덤프로 도전하시면 됩니다. Microsoft DP-600 덤프를 페펙트하게 공부하시면 시험을 한번에 패스할수 있습니다. 구매후 일년무료 업데이트 서비스를 제공해드리기에Microsoft DP-600시험문제가 변경되어도 업데이트된 덤프를 받으면 가장 최신시험에 대비할수 있습니다.
DP-600시험유효덤프: https://www.pass4test.net/DP-600.html
참고: Pass4Test에서 Google Drive로 공유하는 무료 2026 Microsoft DP-600 시험 문제집이 있습니다: https://drive.google.com/open?id=15FYJ595AQHdJ6BRT_o2ZfbFbbLOHHEle