NVIDIA NCP-AIO Latest Exam Guide | NCP-AIO Examinations Actual Questions

DOWNLOAD the newest PrepAwayPDF NCP-AIO PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=10hee2PulS_hVDIiPJZ5jK1Hw-iUkoRZF
If you want to progress and achieve their ideal life, if you are not satisfied with life now, if you still use the traditional methods by exam, so would you please choose the NCP-AIO test materials, it will surely make you shine at the moment. Our NCP-AIO latest dumps provide users with three different versions, including a PDF version, a software version, and an online version. Although involved three versions of the teaching content is the same, but for all types of users can realize their own needs, whether it is which version of NCP-AIO Learning Materials, believe that can give the user a better learning experience. Below, I would like to introduce you to the main advantages of our research materials, and I'm sure you won't want to miss it.
| Topic | Details |
|---|
| Topic 1 | - Installation and Deployment: This section of the exam measures the skills of system administrators and addresses core practices for installing and deploying infrastructure. Candidates are tested on installing and configuring Base Command Manager, initializing Kubernetes on NVIDIA hosts, and deploying containers from NVIDIA NGC as well as cloud VMI containers. The section also covers understanding storage requirements in AI data centers and deploying DOCA services on DPU Arm processors, ensuring robust setup of AI-driven environments.
|
| Topic 2 | - Administration: This section of the exam measures the skills of system administrators and covers essential tasks in managing AI workloads within data centers. Candidates are expected to understand fleet command, Slurm cluster management, and overall data center architecture specific to AI environments. It also includes knowledge of Base Command Manager (BCM), cluster provisioning, Run.ai administration, and configuration of Multi-Instance GPU (MIG) for both AI and high-performance computing applications.
|
| Topic 3 | - Troubleshooting and Optimization: NVIThis section of the exam measures the skills of AI infrastructure engineers and focuses on diagnosing and resolving technical issues that arise in advanced AI systems. Topics include troubleshooting Docker, the Fabric Manager service for NVIDIA NVlink and NVSwitch systems, Base Command Manager, and Magnum IO components. Candidates must also demonstrate the ability to identify and solve storage performance issues, ensuring optimized performance across AI workloads.
|
| Topic 4 | - Workload Management: This section of the exam measures the skills of AI infrastructure engineers and focuses on managing workloads effectively in AI environments. It evaluates the ability to administer Kubernetes clusters, maintain workload efficiency, and apply system management tools to troubleshoot operational issues. Emphasis is placed on ensuring that workloads run smoothly across different environments in alignment with NVIDIA technologies.
|
>> NVIDIA NCP-AIO Latest Exam Guide <<
NCP-AIO Practice Exam Materials: NVIDIA AI Operations and NCP-AIO Study Guide - PrepAwayPDF
PrepAwayPDF provides accurate valid products which are regards as the best provider in this field since 2015. If you still hesitate how to choose NCP-AIO new exam cram review, many candidates will advise us to you. Although IT exams are difficult it is key to IT staff's career so that IT staff can have an achievement. So our NVIDIA NCP-AIO new exam cram review can help thousands of candidates to pass exam and get certification they dream.
NVIDIA AI Operations Sample Questions (Q22-Q27):
NEW QUESTION # 22
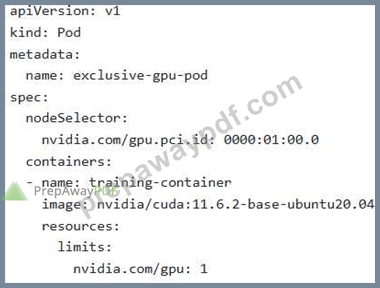
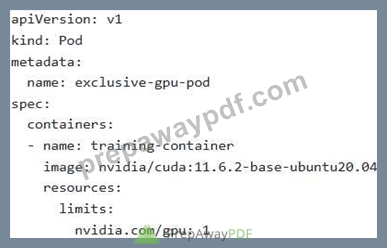
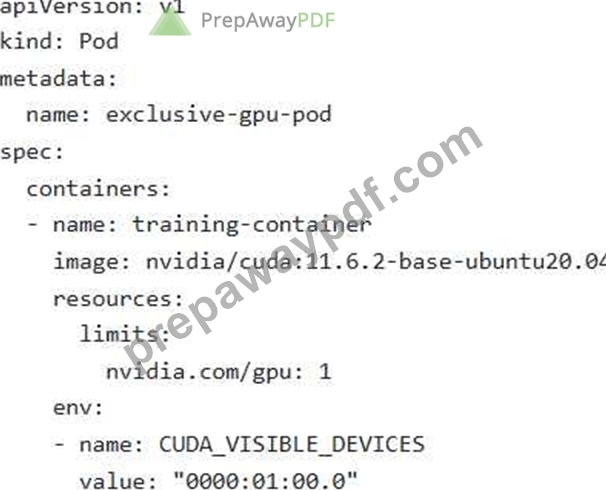
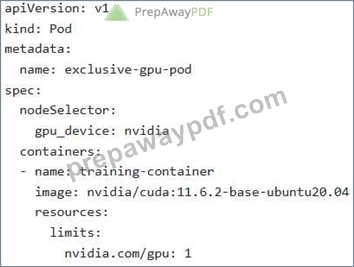
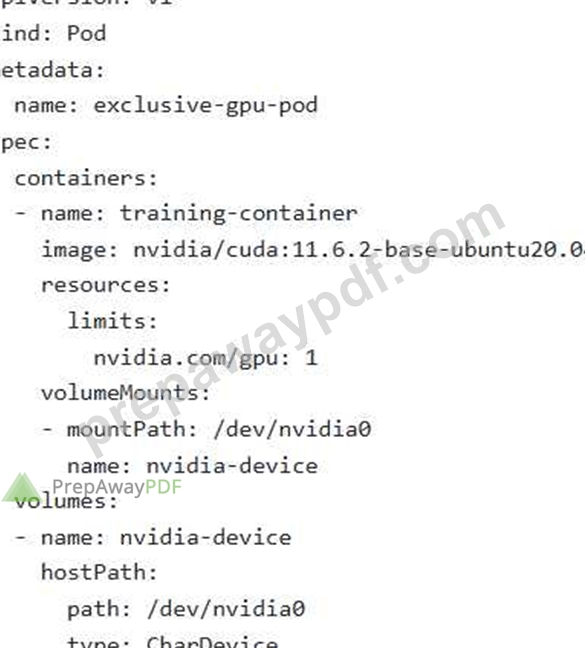
You are managing a Kubernetes cluster used for AI model training. One of the training jobs requires exclusive access to a specific GPU with PCI ID Which of the following Kubernetes manifests correctly configures this requirement for the pod?
Answer: C
Explanation:
The correct answer is A. Setting the 'CUDA VISIBLE DEVICES environment variable with the specific PCI ID ensures the container only sees that GPU. Option B attempts to use a nodeselector, which is not the correct way to request specific GPUs; it's more for scheduling to a node with GPUs. Options C and D do not enforce PCI ID exclusivity. Option E is too generic and doesn't target a specific GPU.
NEW QUESTION # 23
You are tasked with designing a data center network for AI workloads that must support both RDMA over Converged Ethernet (RoCEv2) and traditional TCP/IP traffic. How should you configure the network to ensure optimal performance for both types of traffic?
- A. Implement Priority Flow Control (PFC) and Explicit Congestion Notification (ECN) to prevent packet loss and congestion for RoCEv2 traffic.
- B. Use separate physical networks for RoCEv2 and TCP/IP traffic.
- C. Allocate a larger MTU to TCP/IP traffic and small MTU to RoCEv2 traffic.
- D. Disable QOS (Quality of Service) to treat all traffic equally.
- E. Configure all network switches with the default settings.
Answer: A
Explanation:
RoCEv2 is sensitive to packet loss and congestion. PFC and ECN are essential mechanisms to ensure reliable and high- performance RoCEv2 communication on a converged Ethernet network. Disabling QOS treats all traffic equally, which can starve RoCEv2. Using separate networks adds complexity and cost. Default settings are unlikely to be optimized for RoCEv2. PFC prevents packet loss due to congestion, and ECN provides feedback to sources to slow down before congestion occurs. Large MTUs are beneficial for both but not the primary config.
NEW QUESTION # 24
Which metric is most appropriate for evaluating classification models when dealing with highly imbalanced datasets where one class significantly outnumbers the other?
- A. Precision-recall F1 score
- B. Accuracy
- C. Mean squared error
- D. R-squared
Answer: A
Explanation:
Accuracy can be misleading in imbalanced datasets. Precision, recall, and F1 score provide better insight into model performance, especially for minority classes. They help ensure the model correctly identifies important but rare events.
NEW QUESTION # 25
You have a Run.ai cluster with multiple GPU nodes. You want to configure a specific job to ONLY run on nodes equipped with NVIDIA A100 GPUs. How can you achieve this node selection using Run.ai?
- A. Use Run.ai's built-in 'gpu-type' parameter in the job definition.
- B. Configure node affinity rules in the Run.ai job definition to target nodes with the 'nvidia.com/gpu.product' label equal to 'A1 00'.
- C. Specify the A100 GPU type in the Run.ai cluster configuration.
- D. Manually schedule the job on a specific AIOO node using the Run.ai CLI.
- E. Use Kubernetes taints and tolerations to restrict the job to A100 nodes.
Answer: B
Explanation:
Explanation:Using node affinity rules is the correct approach. By setting node affinity rules in the Run.ai job definition, you can target nodes based on labels, such as 'nvidia.com/gpu.product=A100'. Kubernetes taints and tolerations could also be used, but configuring node affinity within the Run.ai job definition provides a more streamlined approach. Run.ai doesn't have a built-in 'gpu-type' parameter for this specific purpose.
NEW QUESTION # 26
A system administrator notices that jobs are failing intermittently on Base Command Manager due to incorrect GPU configurations in Slurm. The administrator needs to ensure that jobs utilize GPUs correctly.
How should they troubleshoot this issue?
- A. Check if MIG (Multi-Instance GPU) mode has been enabled incorrectly and reconfigure Slurm accordingly.
- B. Increase the number of GPUs requested in the job script to avoid using unconfigured GPUs.
- C. Verify that non-MIG GPUs are automatically configured in Slurm when detected, and adjust configurations if needed.
- D. Ensure that GPU resource limits have been correctly defined in Slurm's configuration file for each job type.
Answer: A
Explanation:
Misconfiguration related to MIG mode can cause Slurm to improperly allocate GPUs, leading to job failures. The administrator should verify whether MIG has been enabled on the GPUs and ensure that Slurm's configuration matches the hardware setup. If MIG is enabled, Slurm must be configured to recognize and schedule MIG partitions correctly to avoid resource conflicts.
NEW QUESTION # 27
......
Our NCP-AIO study materials concentrate the essence of exam materials and seize the focus information to let the learners master the key points. And our NCP-AIO learning materials provide multiple functions and considerate services to help the learners have no inconveniences to use our product. We guarantee to the clients if only they buy our study materials and learn patiently for some time they will be sure to pass the NCP-AIO test with few failure odds.
NCP-AIO Examinations Actual Questions: https://www.prepawaypdf.com/NVIDIA/NCP-AIO-practice-exam-dumps.html
- 100% Pass Quiz 2026 NVIDIA NCP-AIO: NVIDIA AI Operations – Professional Latest Exam Guide 🔯 Search for 《 NCP-AIO 》 and download exam materials for free through ✔ www.dumpsmaterials.com ️✔️ 🎢Test NCP-AIO Dumps Free
- Updated NCP-AIO Latest Exam Guide - Guaranteed NVIDIA NCP-AIO Exam Success with Well-Prepared NCP-AIO Examinations Actual Questions 🍩 Search on 「 www.pdfvce.com 」 for ☀ NCP-AIO ️☀️ to obtain exam materials for free download 🍒NCP-AIO Exam Questions
- Quiz NVIDIA - Efficient NCP-AIO - NVIDIA AI Operations Latest Exam Guide 🚍 ☀ www.torrentvce.com ️☀️ is best website to obtain ➤ NCP-AIO ⮘ for free download ♿Download NCP-AIO Free Dumps
- NCP-AIO Valid Test Bootcamp ⛺ NCP-AIO Valid Exam Discount ↔ NCP-AIO Exam Collection 🚊 Search for [ NCP-AIO ] and download it for free immediately on ➠ www.pdfvce.com 🠰 🦥Test NCP-AIO Dumps Free
- NVIDIA AI Operations Latest Materials are Highly Effective to Make Use of - www.practicevce.com 💛 Open ➽ www.practicevce.com 🢪 and search for ☀ NCP-AIO ️☀️ to download exam materials for free 🌈Hot NCP-AIO Spot Questions
- NCP-AIO Test Torrent 🌋 Certification NCP-AIO Training ✅ Question NCP-AIO Explanations 🧐 Easily obtain free download of ➤ NCP-AIO ⮘ by searching on ⏩ www.pdfvce.com ⏪ 🔋Hot NCP-AIO Spot Questions
- NCP-AIO Valid Test Bootcamp 💲 NCP-AIO Valid Dumps Book 🔒 Download NCP-AIO Free Dumps 🧼 ➤ www.vceengine.com ⮘ is best website to obtain ⮆ NCP-AIO ⮄ for free download 🚒NCP-AIO Exam Collection
- Certification NCP-AIO Training 🥢 NCP-AIO Reliable Braindumps Sheet 🍈 NCP-AIO Knowledge Points 🛑 Download ➤ NCP-AIO ⮘ for free by simply entering { www.pdfvce.com } website ⬇Download NCP-AIO Free Dumps
- Ace NVIDIA NCP-AIO Exam Instantly with This Tried-and-Tested Method 😤 Open website ➽ www.examdiscuss.com 🢪 and search for ⇛ NCP-AIO ⇚ for free download ⚠NCP-AIO Valid Test Bootcamp
- Hot NCP-AIO Spot Questions 🏑 Question NCP-AIO Explanations 🧏 NCP-AIO Knowledge Points 🟫 Simply search for ⇛ NCP-AIO ⇚ for free download on ⏩ www.pdfvce.com ⏪ 🌮Valid NCP-AIO Practice Questions
- NCP-AIO Test Torrent 🥱 NCP-AIO Reliable Test Syllabus 🏂 100% NCP-AIO Accuracy 🚀 Easily obtain { NCP-AIO } for free download through ☀ www.pdfdumps.com ️☀️ 🥎Certification NCP-AIO Training
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, scalar.usc.edu, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
P.S. Free 2026 NVIDIA NCP-AIO dumps are available on Google Drive shared by PrepAwayPDF: https://drive.google.com/open?id=10hee2PulS_hVDIiPJZ5jK1Hw-iUkoRZF