更新するDatabricks-Certified-Data-Engineer-Associate日本語参考 &合格スムーズDatabricks-Certified-Data-Engineer-Associate技術問題 |最新のDatabricks-Certified-Data-Engineer-Associate合格体験記Databricks Certified Data Engineer Associate Exam

無料でクラウドストレージから最新のPassTest Databricks-Certified-Data-Engineer-Associate PDFダンプをダウンロードする:https://drive.google.com/open?id=1VkrTsUfhIZiB6WkwS1NyW7HyEiOAfaDN
PassTestは最高な品質で最速なスピードでDatabricksのDatabricks-Certified-Data-Engineer-Associate認定試験の資料を更新するサイトでございます。もしかすると君はほかのサイトもDatabricksのDatabricks-Certified-Data-Engineer-Associate認証試験に関する資料があるのを見つけた、比較したらPassTestが提供したのがいちばん全面的で品質が最高なことがわかりました。
Databricks Databricks-Certified-Data-Engineer-Associate Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Topic 1: Delta Lake Fundamentals | 20-25% | - Understand ACID transactions and time travel
- Explain Delta Lake features and benefits
- Create and manage Delta tables
- Write to and read from Delta tables
|
| Topic 2: Lakehouse Platform Concepts | 10-15% | - Understand the Lakehouse architecture and its benefits
- Describe key Databricks Lakehouse platform components
- Explain data governance and security concepts
|
| Topic 3: Spark SQL and DataFrames | 15-20% | - Join and union DataFrames
- Handle null values and data quality
- Aggregate and group data
- Write and execute Spark SQL queries
|
| Topic 4: Apache Spark Data Processing Fundamentals | 20-25% | - Apply transformations and actions on DataFrames
- Use Spark SQL for data processing
- Work with structured data types (arrays, maps, structs)
- Create and use Spark DataFrames
|
| Topic 5: Python for Data Engineering | 10-15% | - Work with Spark APIs in Python
- Implement user-defined functions (UDFs)
- Use PySpark for data processing
|
| Topic 6: Data Pipeline Architecture | 15-20% | - Monitor and optimize pipeline performance
- Implement incremental data processing
- Design data pipelines for batch and streaming
- Understand ELT vs ETL patterns
|
>> Databricks-Certified-Data-Engineer-Associate日本語参考 <<
Databricks-Certified-Data-Engineer-Associate技術問題、Databricks-Certified-Data-Engineer-Associate合格体験記
品質は、時間と量の試練に耐えることです。我々PassTestがあなたに提供するDatabricksのDatabricks-Certified-Data-Engineer-Associateソフトはこれを保証します。我々の問題集の更新と解答への専門的な分析は我々の商品に多くの受験生の試験に合格する秘密武器にならせます。試験に失敗したら全額d返金するという承諾は我々への励ましです。我々はあなたにDatabricksのDatabricks-Certified-Data-Engineer-Associateソフトを改善し続けることを喜んでいます。ご購入した一年間、あなたはDatabricksのDatabricks-Certified-Data-Engineer-Associateソフトの最新の資料を無料で得られます。
Databricks Certified Data Engineer Associate Exam 認定 Databricks-Certified-Data-Engineer-Associate 試験問題 (Q14-Q19):
質問 # 14
A new data engineering team team. has been assigned to an ELT project. The new data engineering team will need full privileges on the database customers to fully manage the project.
Which of the following commands can be used to grant full permissions on the database to the new data engineering team?
- A. GRANT USAGE ON DATABASE customers TO team;
- B. GRANT ALL PRIVILEGES ON DATABASE customers TO team;
- C. GRANT SELECT CREATE MODIFY USAGE PRIVILEGES ON DATABASE customers TO team;
- D. GRANT ALL PRIVILEGES ON DATABASE team TO customers;
- E. GRANT SELECT PRIVILEGES ON DATABASE customers TO teams;
正解:B
解説:
Explanation
To grant full privileges on the database "customers" to the new data engineering team, you can use the GRANT ALL PRIVILEGES command as shown in option E. This command provides the team with all possible privileges on the specified database, allowing them to fully manage it.
質問 # 15
A data engineer wants to schedule their Databricks SQL dashboard to refresh every hour, but they only want the associated SQL endpoint to be running when It is necessary. The dashboard has multiple queries on multiple datasets associated with it. The data that feeds the dashboard is automatically processed using a Databricks Job.
Which approach can the data engineer use to minimize the total running time of the SQL endpoint used in the refresh schedule of their dashboard?
- A. O They can set up the dashboard's SQL endpoint to be serverless.
- B. 0 They can ensure the dashboard's SQL endpoint matches each of the queries' SQL endpoints.
- C. Q They can turn on the Auto Stop feature for the SQL endpoint.
- D. O They can reduce the cluster size of the SQL endpoint.
正解:C
解説:
To minimize the total running time of the SQL endpoint used in the refresh schedule of a dashboard in Databricks, the most effective approach is to utilize the Auto Stop feature. This feature allows the SQL endpoint to automatically stop after a period of inactivity, ensuring that it only runs when necessary, such as during the dashboard refresh or when actively queried. This minimizes resource usage and associated costs by ensuring the SQL endpoint is not running idle outside of these operations.
References:Databricks documentation on SQL endpoints: SQL Endpoints in Databricks
質問 # 16
A data engineer needs to configure an external location and a storage credential so that a new bronze ingestion pipeline can land data in cloud storage governed by Unity Catalog. The engineer has CREATE TABLE permission on schemas but receives a permission error when attempting to create the external location. Which role is required to unblock this setup, the principle of least privilege?
- A. Grant ALL PRIVILEGES on the catalog so the engineer can create external locations under its schemas.
- B. Promote the engineer to Workspace Admin so they can manage objects and jobs.
- C. Grant CREATE EXTERNAL LOCATION on both the metastore and the referenced storage credential so the engineer can define the external location.
- D. Assign the engineer as Metastore Admin because only Metastore Admins can create external locations.
正解:C
解説:
Creating an external location requires specific privileges on both the metastore and the referenced storage credential, enabling the engineer to define the external location without granting broader administrative permissions, aligning with least privilege.
質問 # 17
A data engineer runs a statement every day to copy the previous day's sales into the table transactions. Each day's sales are in their own file in the location "/transactions/raw".
Today, the data engineer runs the following command to complete this task:
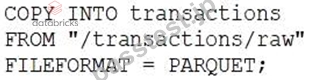
After running the command today, the data engineer notices that the number of records in table transactions has not changed.
Which of the following describes why the statement might not have copied any new records into the table?
- A. The PARQUET file format does not support COPY INTO.
- B. The previous day's file has already been copied into the table.
- C. The names of the files to be copied were not included with the FILES keyword.
- D. The COPY INTO statement requires the table to be refreshed to view the copied rows.
- E. The format of the files to be copied were not included with the FORMAT_OPTIONS keyword.
正解:B
解説:
The COPY INTO statement is an idempotent operation, which means that it will skip any files that have already been loaded into the target table1. This ensures that the data is not duplicated or corrupted by multiple attempts to load the same file. Therefore, if the data engineer runs the same command every day without specifying the names of the files to be copied with the FILES keyword or a glob pattern with the PATTERN keyword, the statement will only copy the first file that matches the source location and ignore the rest. To avoid this problem, the data engineer should either use the FILES or PATTERN keywords to filter the files to be copied based on the date or some other criteria, or delete the files from the source location after they are copied into the table2. References: 1: COPY INTO | Databricks on AWS 2: Get started using COPY INTO to load data | Databricks on AWS
質問 # 18
A data engineer has a single-task Job that runs each morning before they begin working. After identifying an upstream data issue, they need to set up another task to run a new notebook prior to the original task.
Which of the following approaches can the data engineer use to set up the new task?
- A. They can create a new job from scratch and add both tasks to run concurrently.
- B. They can create a new task in the existing Job and then add the original task as a dependency of the new task.
- C. They can create a new task in the existing Job and then add it as a dependency of the original task.
- D. They can clone the existing task in the existing Job and update it to run the new notebook.
- E. They can clone the existing task to a new Job and then edit it to run the new notebook.
正解:C
質問 # 19
......
PassTestのDatabricksのDatabricks-Certified-Data-Engineer-Associate試験トレーニング資料を利用すれば、認定試験に合格するのは簡単になります。うちのDatabricksのDatabricks-Certified-Data-Engineer-Associate試験トレーニング資料は豊富な経験を持っている専門家が長年の研究を通じて開発されたものです。PassTestの学習教材は君の初めての試しでDatabricksのDatabricks-Certified-Data-Engineer-Associate認定試験に合格するのに助けます。
Databricks-Certified-Data-Engineer-Associate技術問題: https://www.passtest.jp/Databricks/Databricks-Certified-Data-Engineer-Associate-shiken.html
- 効率的なDatabricks-Certified-Data-Engineer-Associate日本語参考 - 資格試験におけるリーダーオファー - 無料PDF Databricks-Certified-Data-Engineer-Associate: Databricks Certified Data Engineer Associate Exam ♥ ➽ www.jpexam.com 🢪で【 Databricks-Certified-Data-Engineer-Associate 】を検索して、無料で簡単にダウンロードできますDatabricks-Certified-Data-Engineer-Associate試験時間
- Databricks-Certified-Data-Engineer-Associate勉強資、Databricks-Certified-Data-Engineer-Associate試験模擬、Databricks-Certified-Data-Engineer-Associateテスト問題集 🍽 ウェブサイト{ www.goshiken.com }から✔ Databricks-Certified-Data-Engineer-Associate ️✔️を開いて検索し、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Associate試験情報
- Databricks-Certified-Data-Engineer-Associate試験番号 🎷 Databricks-Certified-Data-Engineer-Associate復習時間 🦇 Databricks-Certified-Data-Engineer-Associate日本語参考 🚅 《 www.xhs1991.com 》から簡単に➡ Databricks-Certified-Data-Engineer-Associate ️⬅️を無料でダウンロードできますDatabricks-Certified-Data-Engineer-Associateコンポーネント
- Databricks-Certified-Data-Engineer-Associate模擬トレーリング 📪 Databricks-Certified-Data-Engineer-Associate日本語参考 🐁 Databricks-Certified-Data-Engineer-Associate日本語学習内容 ⛳ ✔ www.goshiken.com ️✔️に移動し、▛ Databricks-Certified-Data-Engineer-Associate ▟を検索して無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Associate試験問題集
- Databricks-Certified-Data-Engineer-Associate技術内容 💯 Databricks-Certified-Data-Engineer-Associateキャリアパス 😧 Databricks-Certified-Data-Engineer-Associate試験時間 🥪 ▛ jp.fast2test.com ▟サイトにて《 Databricks-Certified-Data-Engineer-Associate 》問題集を無料で使おうDatabricks-Certified-Data-Engineer-Associateキャリアパス
- Databricks Databricks-Certified-Data-Engineer-Associate認定試験に対する最も優秀な参考書 🤟 「 www.goshiken.com 」を入力して“ Databricks-Certified-Data-Engineer-Associate ”を検索し、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Associate資格専門知識
- Databricks Databricks-Certified-Data-Engineer-Associate Exam | Databricks-Certified-Data-Engineer-Associate日本語参考 - オフィシャルパス認証 Databricks-Certified-Data-Engineer-Associate技術問題 🚰 ▛ www.passtest.jp ▟から簡単に[ Databricks-Certified-Data-Engineer-Associate ]を無料でダウンロードできますDatabricks-Certified-Data-Engineer-Associate赤本勉強
- コンプリートDatabricks-Certified-Data-Engineer-Associate日本語参考 | 素晴らしい合格率のDatabricks-Certified-Data-Engineer-Associate Exam | 正確的なDatabricks-Certified-Data-Engineer-Associate: Databricks Certified Data Engineer Associate Exam 💎 ▷ www.goshiken.com ◁を開き、( Databricks-Certified-Data-Engineer-Associate )を入力して、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Associate試験時間
- Databricks-Certified-Data-Engineer-Associate試験 🧒 Databricks-Certified-Data-Engineer-Associate復習時間 🐝 Databricks-Certified-Data-Engineer-Associate試験問題集 🍪 ✔ www.xhs1991.com ️✔️から▷ Databricks-Certified-Data-Engineer-Associate ◁を検索して、試験資料を無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Associateコンポーネント
- Databricks-Certified-Data-Engineer-Associate試験時間 🐼 Databricks-Certified-Data-Engineer-Associateリンクグローバル 😊 Databricks-Certified-Data-Engineer-Associate技術内容 🚨 ▶ www.goshiken.com ◀サイトにて➡ Databricks-Certified-Data-Engineer-Associate ️⬅️問題集を無料で使おうDatabricks-Certified-Data-Engineer-Associate試験問題集
- 人気のあるDatabricks-Certified-Data-Engineer-Associate日本語参考 - 資格試験のリーダープロバイダー - 実用的なDatabricks-Certified-Data-Engineer-Associate技術問題 🛑 ウェブサイト( www.passtest.jp )から▷ Databricks-Certified-Data-Engineer-Associate ◁を開いて検索し、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Associate試験問題集
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
2026年PassTestの最新Databricks-Certified-Data-Engineer-Associate PDFダンプおよびDatabricks-Certified-Data-Engineer-Associate試験エンジンの無料共有:https://drive.google.com/open?id=1VkrTsUfhIZiB6WkwS1NyW7HyEiOAfaDN