P.S. Kostenlose 2026 Databricks Databricks-Certified-Data-Engineer-Associate Prüfungsfragen sind auf Google Drive freigegeben von PrüfungFrage verfügbar: https://drive.google.com/open?id=13mDVYP3FJJ1BUO_8yPDUwgJkljz4T6nL
Die Prüfungsmaterialien von Databricks Databricks-Certified-Data-Engineer-Associate Zertifizierungsprüfung von unserem PrüfungFrage existieren in der Form von PDF und Stimulationssoftware, in der alle Testaufgaben und Antworten von Databricks Databricks-Certified-Data-Engineer-Associate Zertifizierung enthalten sind. Inhalte dieser Lehrbücher sind umfassend und zuversichtlich. Hoffentlich kann PrüfungFrage Ihr bester Hilfer bei der Vorbereitung der Databricks Databricks-Certified-Data-Engineer-Associate Zertifizierungsprüfung werden. Falls Sie leider die Databricks-Certified-Data-Engineer-Associate Prüfung nicht bestehen, bitte machen Sie keine Sorge, denn wir werden alle Ihre Einkaufsgebühren bedingungslos zurückgeben.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Apache Spark Data Processing Fundamentals | 20-25% | - Use Spark SQL for data processing - Work with structured data types (arrays, maps, structs) - Create and use Spark DataFrames - Apply transformations and actions on DataFrames |
| Topic 2: Data Pipeline Architecture | 15-20% | - Understand ELT vs ETL patterns - Design data pipelines for batch and streaming - Monitor and optimize pipeline performance - Implement incremental data processing |
| Topic 3: Spark SQL and DataFrames | 15-20% | - Write and execute Spark SQL queries - Aggregate and group data - Handle null values and data quality - Join and union DataFrames |
| Topic 4: Delta Lake Fundamentals | 20-25% | - Create and manage Delta tables - Explain Delta Lake features and benefits - Write to and read from Delta tables - Understand ACID transactions and time travel |
| Topic 5: Python for Data Engineering | 10-15% | - Implement user-defined functions (UDFs) - Work with Spark APIs in Python - Use PySpark for data processing |
| Topic 6: Lakehouse Platform Concepts | 10-15% | - Describe key Databricks Lakehouse platform components - Understand the Lakehouse architecture and its benefits - Explain data governance and security concepts |
>> Databricks-Certified-Data-Engineer-Associate Prüfung <<
Sie können im Internet teilweise die Fragen und Antworten zur Databricks Databricks-Certified-Data-Engineer-Associate Zertifizierungsprüfung von PrüfungFrage kostenlos als Probe herunterladen. Dann würden Sie finden, dass die Übungen von PrüfungFrage ist die umfassendesten und ganau was, was Sie wollen.
29. Frage
A Delta Live Table pipeline includes two datasets defined using streaming live table. Three datasets are defined against Delta Lake table sources using live table.
The table is configured to run in Production mode using the Continuous Pipeline Mode.
What is the expected outcome after clicking Start to update the pipeline assuming previously unprocessed data exists and all definitions are valid?
Antwort: C
Begründung:
In Delta Live Tables (DLT), when configured to run in Continuous Pipeline Mode, particularly in a production environment, the system is designed to continuously process and update data as it becomes available. This mode keeps the compute resources active to handle ongoing data processing and automatically updates all datasets defined in the pipeline at predefined intervals. Once the pipeline is manually stopped, the compute resources are terminated to conserve resources and reduce costs. This mode is suitable for production environments where datasets need to be kept up-to-date with the latest data.
References:Databricks documentation on Delta Live Tables: Delta Live Tables Guide
30. Frage
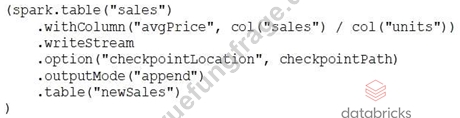
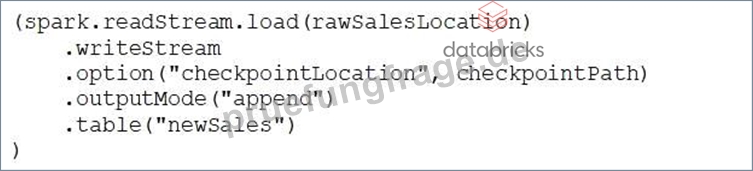
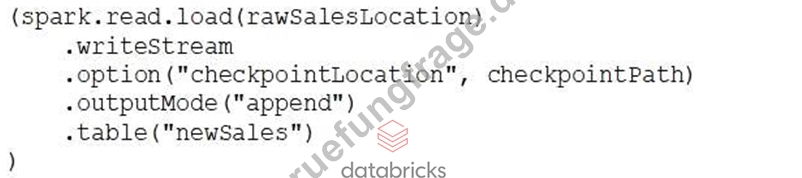
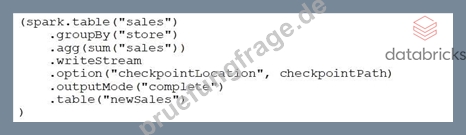
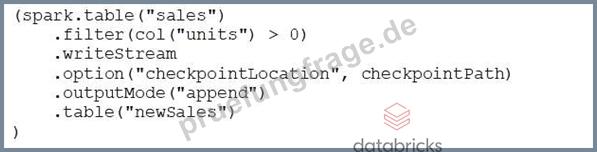
Which of the following Structured Streaming queries is performing a hop from a Silver table to a Gold table?
Antwort: D
Begründung:
The best practice is to use "Complete" as output mode instead of "append" when working with aggregated tables. Since gold layer is work final aggregated tables, the only option with output mode as complete is option E.
31. Frage
In which of the following scenarios should a data engineer use the MERGE INTO command instead of the INSERT INTO command?
Antwort: E
Begründung:
The MERGE INTO command is used to perform upserts, which are a combination of insertions and updates, based on a source table into a target Delta table1. The MERGE INTO command can handle scenarios where the target table cannot contain duplicate records, such as when there is a primary key or a unique constraint on the target table. The MERGE INTO command can match the source and target rows based on a merge condition and perform different actions depending on whether the rows are matched or not. For example, the MERGE INTO command can update the existing target rows with the new source values, insert the new source rows that do not exist in the target table, or delete the target rows that do not exist in the source table1.
The INSERT INTO command is used to append new rows to an existing table or create a new table from a query result2. The INSERT INTO command does not perform any updates or deletions on the existing target table rows. The INSERT INTO command can handle scenarios where the location of the data needs to be changed, such as when the data needs to be moved from one table to another, or when the data needs to be partitioned by a certain column2. The INSERT INTO command can also handle scenarios where the target table is an external table, such as when the data is stored in an external storage system like Amazon S3 or Azure Blob Storage3. The INSERT INTO command can also handle scenarios where the source table can be deleted, such as when the source table is a temporary table or a view4. The INSERT INTO command can also handle scenarios where the source is not a Delta table, such as when the source is a Parquet, CSV, JSON, or Avro file5.
Reference:
1: MERGE INTO | Databricks on AWS
2: [INSERT INTO | Databricks on AWS]
3: [External tables | Databricks on AWS]
4: [Temporary views | Databricks on AWS]
5: [Data sources | Databricks on AWS]
32. Frage
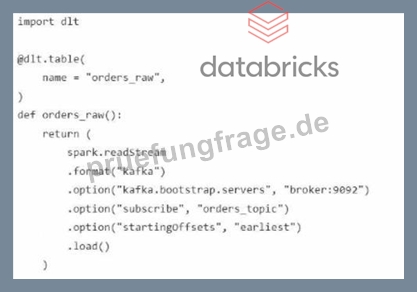
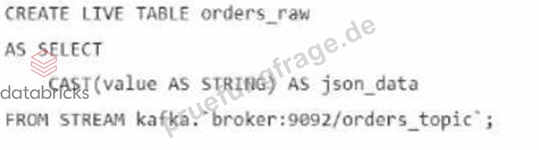
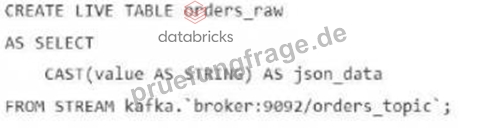
A data engineer streams customer orders into a Kafka topic (orders_topic) and is currently writing the ingestion script of a DLT pipeline. The data engineer needs to ingest the data from Kafka brokers to DLT using Databricks What is the correct code for ingesting the data?
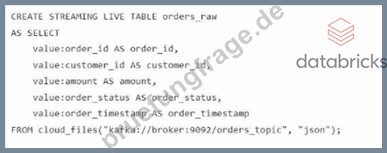
Antwort: A
33. Frage
A data engineer needs to combine sales data from an on-premises PostgreSQL database with customer data in Azure Synapse for a comprehensive report. The goal is to avoid data duplication and ensure up-to-date information. How should the data engineer achieve this using Databricks?
Antwort: D
Begründung:
Lakehouse Federation allows Databricks to directly query external data sources like PostgreSQL and Azure Synapse without duplicating data. This ensures the report always uses up-to-date information while avoiding the overhead and cost of data movement.
34. Frage
......
Die Databricks Databricks-Certified-Data-Engineer-Associate Zertifizierungsprüfung stellt eine wichtige Position in der IT-Branche dar, worüber viele IT-Experten sich einig sind. Die Databricks Databricks-Certified-Data-Engineer-Associate (Databricks Certified Data Engineer Associate Exam) Zertifizierungsprüfung zu bestehen ist jedoch nicht einfach. Es erfordert umfangreiche Fachkenntnisse und Erfahrungen, weil die Databricks Databricks-Certified-Data-Engineer-Associate Zertifizierungsprüfung sowieso eine autoritäre Prüfung, die das Niveau der IT-Fachkenntnissen überprüft. Wenn Sie das Databricks Databricks-Certified-Data-Engineer-Associate Zertifikat bekommen, wird Ihre Fähigkeit von den Firmen akzeptiert. Das bedeutet, dass die zielgerichteten Schulungsunterlagen von PrüfungFrage sehr wirksam ist. Mit unseren Prüfungsmaterialien können Sie 100% die Prüfung bestehen.
Databricks-Certified-Data-Engineer-Associate Prüfungsfragen: https://www.pruefungfrage.de/Databricks-Certified-Data-Engineer-Associate-dumps-deutsch.html
P.S. Kostenlose 2026 Databricks Databricks-Certified-Data-Engineer-Associate Prüfungsfragen sind auf Google Drive freigegeben von PrüfungFrage verfügbar: https://drive.google.com/open?id=13mDVYP3FJJ1BUO_8yPDUwgJkljz4T6nL