What's more, part of that Itcertmaster DP-100 dumps now are free: https://drive.google.com/open?id=1V7Ko2WaGgwyyEvcZue7mIDtKyTMxlyhk
Our DP-100 study questions are suitable for a variety of levels of users, no matter you are in a kind of cultural level, even if you only have high cultural level, you can find in our DP-100 training materials suitable for their own learning methods. So, for every user of our DP-100 Study Materials are a great opportunity, a variety of types to choose from, more and more students also choose our DP-100 test guide, then why are you hesitating? Just choose our Designing and Implementing a Data Science Solution on Azure study questions!
After successfully passing the Microsoft DP-100 Exam, you will obtain the Microsoft Certified: Azure Data Scientist Associate certification. Getting certified will allow you to qualify for several positions, including the following titles:
Obtaining this certification is also beneficial from a financial point of view. In fact, the average salary that a certified professional can earn is $96,642 per year.
Passing the DP-100 exam with least time while achieving aims effortlessly is like a huge dreams for some exam candidates. Actually, it is possible with our proper DP-100 learning materials. To discern what ways are favorable for you to practice and what is essential for exam syllabus, our experts made great contributions to them. All DP-100 Practice Engine is highly interrelated with the exam. You will figure out this is great opportunity for you.
| Topic | Details |
|---|---|
Manage Azure resources for machine learning (25-30%) | |
| Create an Azure Machine Learning workspace | - create an Azure Machine Learning workspace - configure workspace settings - manage a workspace by using Azure Machine Learning studio |
| Manage data in an Azure Machine Learning workspace | - select Azure storage resources - register and maintain datastores - create and manage datasets |
| Manage compute for experiments in Azure Machine Learning | - determine the appropriate compute specifications for a training workload - create compute targets for experiments and training - configure Attached Compute resources including Azure Databricks - monitor compute utilization |
| Implement security and access control in Azure Machine Learning | - determine access requirements and map requirements to built-in roles - create custom roles - manage role membership - manage credentials by using Azure Key Vault |
| Set up an Azure Machine Learning development environment | - create compute instances - share compute instances - access Azure Machine Learning workspaces from other development environments |
| Set up an Azure Databricks workspace | - create an Azure Databricks workspace - create an Azure Databricks cluster - create and run notebooks in Azure Databricks - link and Azure Databricks workspace to an Azure Machine Learning workspace |
Run Experiments and Train Models (20-25%) | |
| Create models by using the Azure Machine Learning Designer | - create a training pipeline by using Azure Machine Learning designer - ingest data in a designer pipeline - use designer modules to define a pipeline data flow - use custom code modules in designer |
| Run model training scripts | - create and run an experiment by using the Azure Machine Learning SDK - configure run settings for a script - consume data from a dataset in an experiment by using the Azure Machine Learning SDK - run a training script on Azure Databricks compute - run code to train a model in an Azure Databricks notebook |
| Generate metrics from an experiment run | - log metrics from an experiment run - retrieve and view experiment outputs - use logs to troubleshoot experiment run errors - use MLflow to track experiments - track experiments running in Azure Databricks |
| Use Automated Machine Learning to create optimal models | - use the Automated ML interface in Azure Machine Learning studio - use Automated ML from the Azure Machine Learning SDK - select pre-processing options - select the algorithms to be searched - define a primary metric - get data for an Automated ML run - retrieve the best model |
| Tune hyperparameters with Azure Machine Learning | - select a sampling method - define the search space - define the primary metric - define early termination options - find the model that has optimal hyperparameter values |
Deploy and operationalize machine learning solutions (35-40%) | |
| Select compute for model deployment | - consider security for deployed services - evaluate compute options for deployment |
| Deploy a model as a service | - configure deployment settings - deploy a registered model - deploy a model trained in Azure Databricks to an Azure Machine Learning endpoint - consume a deployed service - troubleshoot deployment container issues |
| Manage models in Azure Machine Learning | - register a trained model - monitor model usage - monitor data drift |
| Create an Azure Machine Learning pipeline for batch inferencing | - configure a ParallelRunStep - configure compute for a batch inferencing pipeline - publish a batch inferencing pipeline - run a batch inferencing pipeline and obtain outputs - obtain outputs from a ParallelRunStep |
| Publish an Azure Machine Learning designer pipeline as a web service | - create a target compute resource - configure an Inference pipeline - consume a deployed endpoint |
| Implement pipelines by using the Azure Machine Learning SDK | - create a pipeline - pass data between steps in a pipeline - run a pipeline - monitor pipeline runs |
| Apply ML Ops practices | - trigger an Azure Machine Learning pipeline from Azure DevOps - automate model retraining based on new data additions or data changes - refactor notebooks into scripts - implement source control for scripts |
Implement Responsible ML (5-10%) | |
| Use model explainers to interpret models | - select a model interpreter - generate feature importance data |
NEW QUESTION # 432
You need to configure the Feature Based Feature Selection module based on the experiment requirements and datasets.
How should you configure the module properties? To answer, select the appropriate options in the dialog box in the answer area.
NOTE: Each correct selection is worth one point.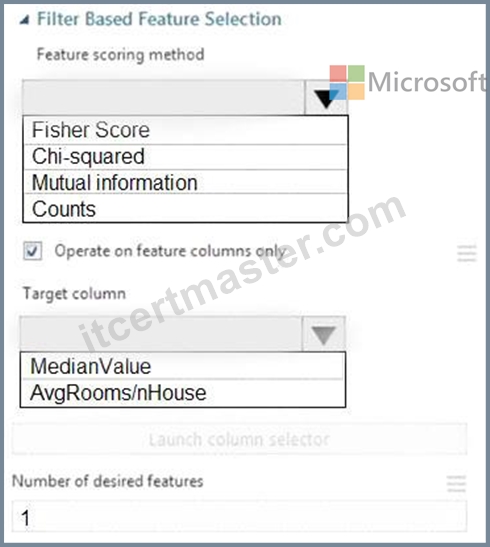
Answer:
Explanation: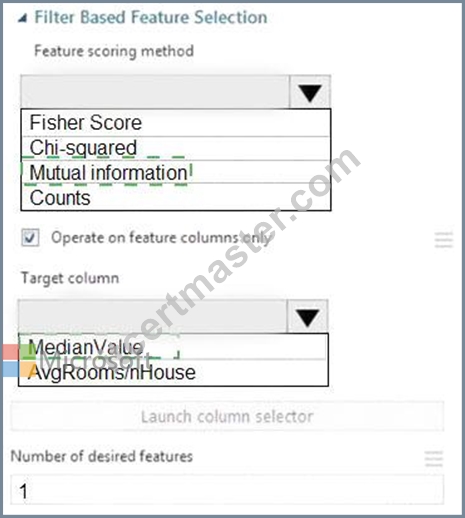
Explanation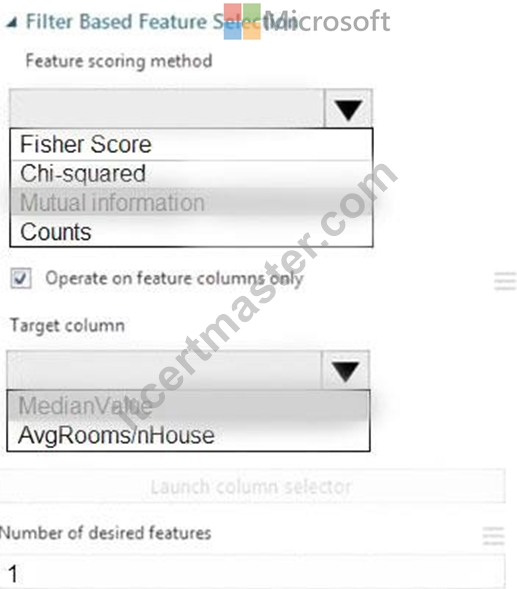
Box 1: Mutual Information.
The mutual information score is particularly useful in feature selection because it maximizes the mutual information between the joint distribution and target variables in datasets with many dimensions.
Box 2: MedianValue
MedianValue is the feature column, , it is the predictor of the dataset.
Scenario: The MedianValue and AvgRoomsinHouse columns both hold data in numeric format. You need to select a feature selection algorithm to analyze the relationship between the two columns in more detail.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/filter-based-feature-selection
NEW QUESTION # 433
You create a training pipeline using the Azure Machine Learning designer. You upload a CSV file that contains the data from which you want to train your model.
You need to use the designer to create a pipeline that includes steps to perform the following tasks:
Select the training features using the pandas filter method.
Train a model based on the naive_bayes.GaussianNB algorithm.
Return only the Scored Labels column by using the query SELECT [Scored Labels] FROM t1; Which modules should you use? To answer, drag the appropriate modules to the appropriate locations. Each module name may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.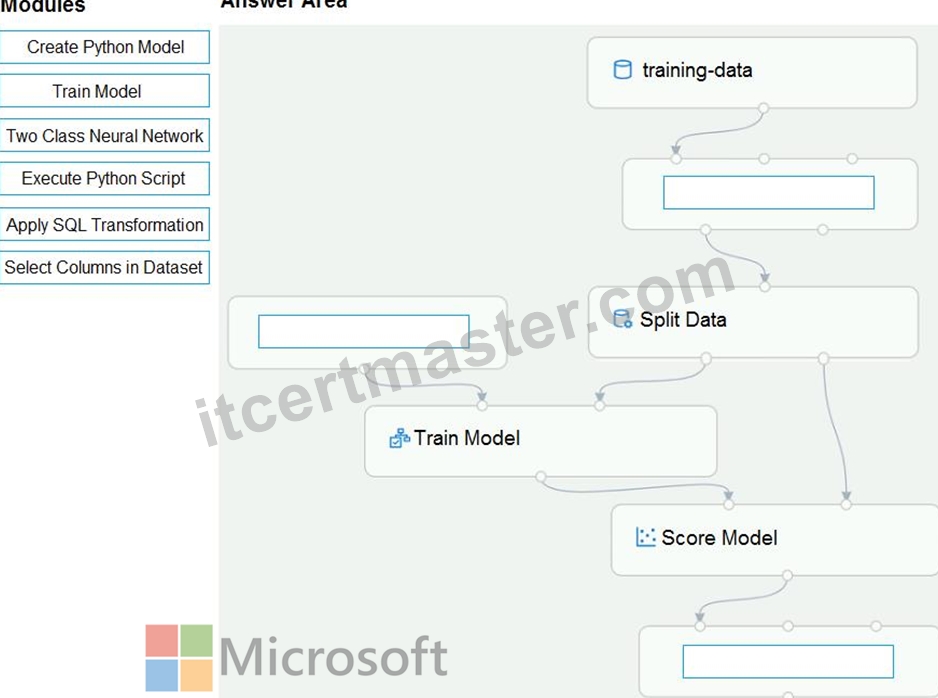
Answer:
Explanation: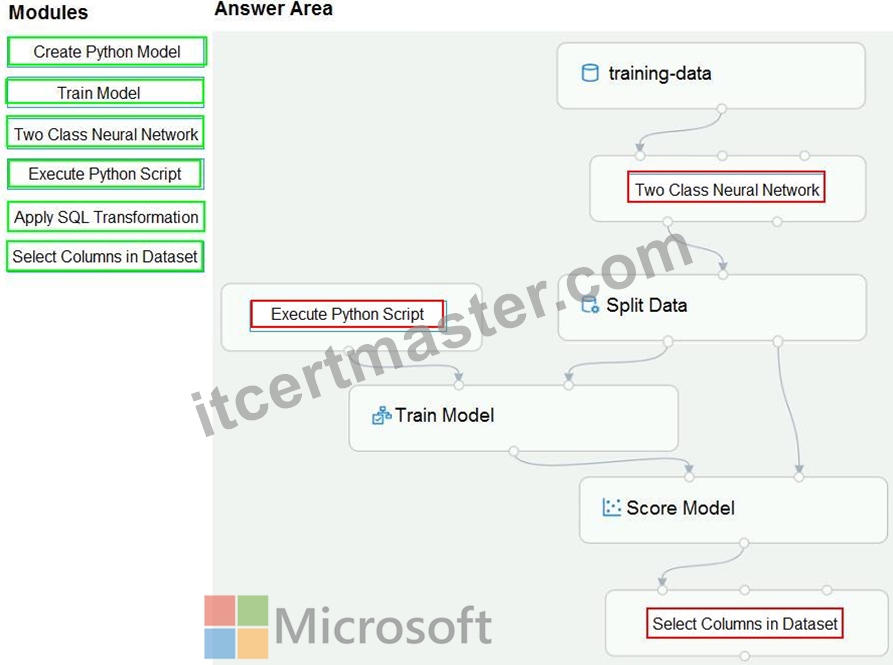
NEW QUESTION # 434
You create a binary classification model. The model is registered in an Azure Machine Learning workspace.
You use the Azure Machine Learning Fairness SDK to assess the model fairness.
You develop a training script for the model on a local machine.
You need to load the model fairness metrics into Azure Machine Learning studio.
What should you do?
Answer: D
Explanation:
Explanation
import azureml.contrib.fairness package to perform the upload:
from azureml.contrib.fairness import upload_dashboard_dictionary, download_dashboard_by_upload_id Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-machine-learning-fairness-aml
NEW QUESTION # 435
You have an Azure Machine Learning workspace named workspace1 that is accessible from a public endpoint. The workspace contains an Azure Blob storage datastore named store1 that represents a blob container in an Azure storage account named account1. You configure workspace1 and account1 to be accessible by using private endpoints in the same virtual network.
You must be able to access the contents of store1 by using the Azure Machine Learning SDK for Python. You must be able to preview the contents of store1 by using Azure Machine Learning studio.
You need to configure store1.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.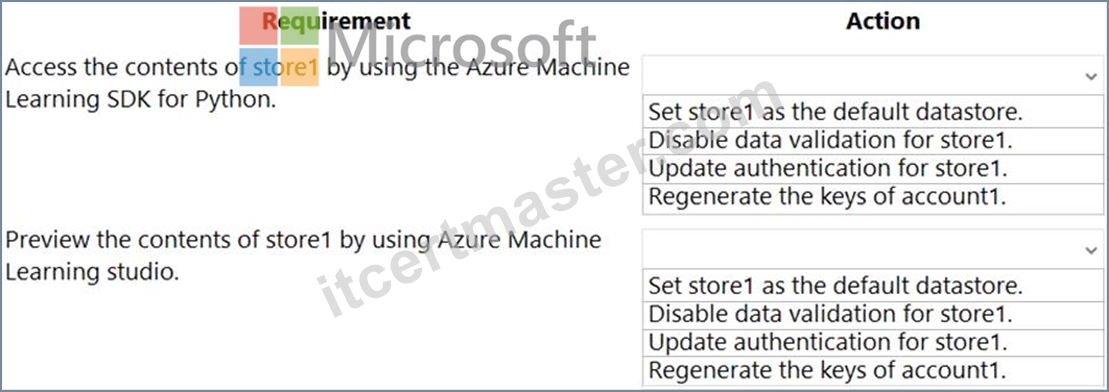
Answer:
Explanation: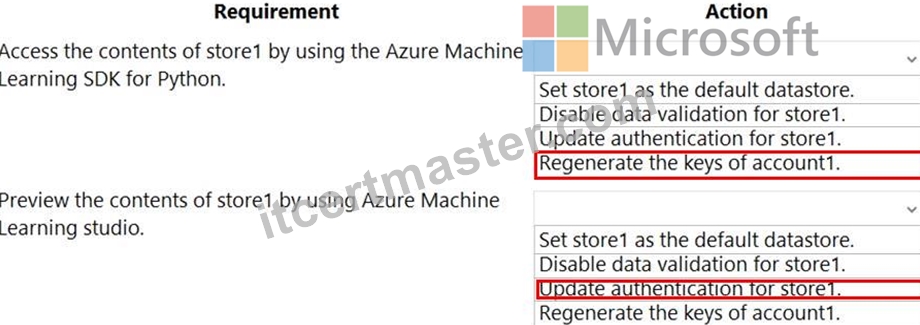
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-access-data
NEW QUESTION # 436
You manage an Azure Machine Learning workspace named workspace1 by using the Python SDK v2.
You must register datastores in workspace1 for Azure Blob and Azure Data Lake Gen2 storage to meet the following requirements:
* Data scientists accessing the datastore must have the same level of access.
* Access must be restricted to specified containers or folders.
You need to configure a security access method used to register the Azure Blob and Azure Data lake Gen?
storage in workspace1. Which security access method should you configure? To answer, select the appropriate options in the answers area.
NOTE: Each correct selection is worth one point.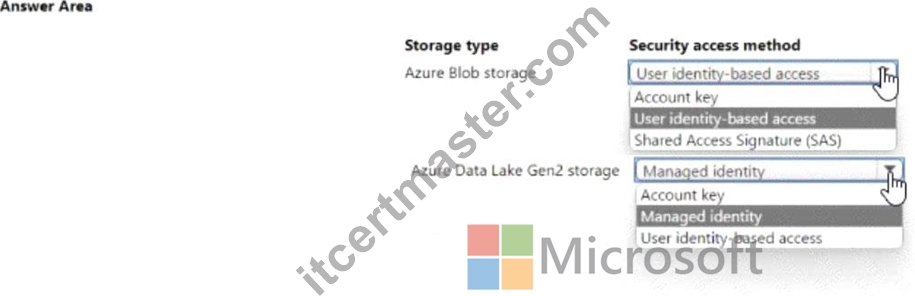
Answer:
Explanation: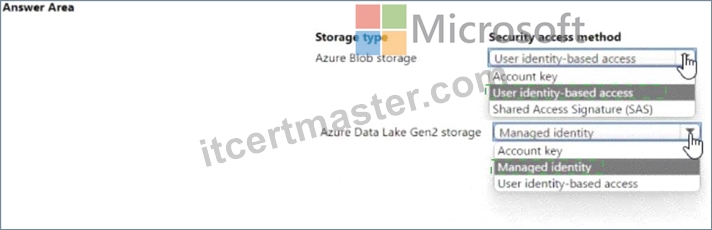
Explanation: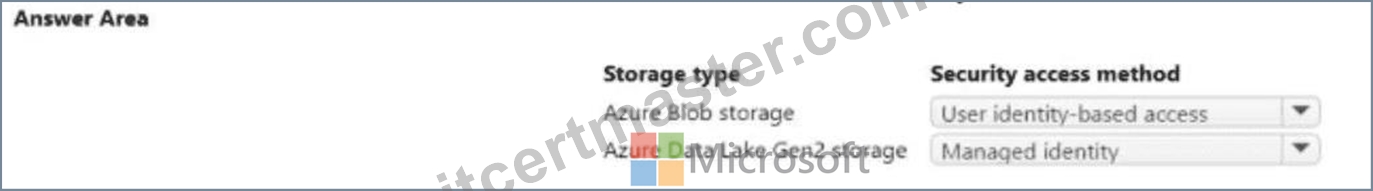
NEW QUESTION # 437
......
DP-100 Free Braindumps: https://www.itcertmaster.com/DP-100.html
BTW, DOWNLOAD part of Itcertmaster DP-100 dumps from Cloud Storage: https://drive.google.com/open?id=1V7Ko2WaGgwyyEvcZue7mIDtKyTMxlyhk