BTW, DOWNLOAD part of ExamcollectionPass MLA-C01 dumps from Cloud Storage: https://drive.google.com/open?id=17OBpJWPDa_Y-F_e40sjXiJpDEnNZf9f7
Our MLA-C01 practice materials are on the cutting edge of this line with all the newest contents for your reference. Free demos are understandable materials as well as the newest information for your practice. Under coordinated synergy of all staff, our MLA-C01 practice materials achieved to a higher level of perfection by keeping close attention with the trend of dynamic market. They eliminated stereotypical content from our AWS Certified Machine Learning Engineer - Associate practice materials. And if you download our MLA-C01 practice materials this time, we will send free updates for you one year long.
| Section | Weight | Objectives |
|---|---|---|
| Deployment and Orchestration of ML Workflows | 22% | - Configure deployment for scalability and availability
|
| ML Model Development | 26% | - Evaluate and analyze model performance
|
| Data Preparation for Machine Learning | 28% | - Transform data and perform feature engineering
|
| ML Solution Monitoring, Maintenance, and Security | 24% | - Monitor model and data quality
|
The Amazon MLA-C01 dumps pdf formats are specially created for candidates having less time and a vast syllabus to cover. It has various crucial features that you will find necessary for your AWS Certified Machine Learning Engineer - Associate (MLA-C01) exam preparation. Each MLA-C01 practice test questions format supports a different kind of study tempo and you will find each MLA-C01 exam dumps format useful in various ways.
NEW QUESTION # 109
An ML engineer is building a generative AI application on Amazon Bedrock by using large language models (LLMs).
Select the correct generative AI term from the following list for each description. Each term should be selected one time or not at all. (Select three.)
* Embedding
* Retrieval Augmented Generation (RAG)
* Temperature
* Token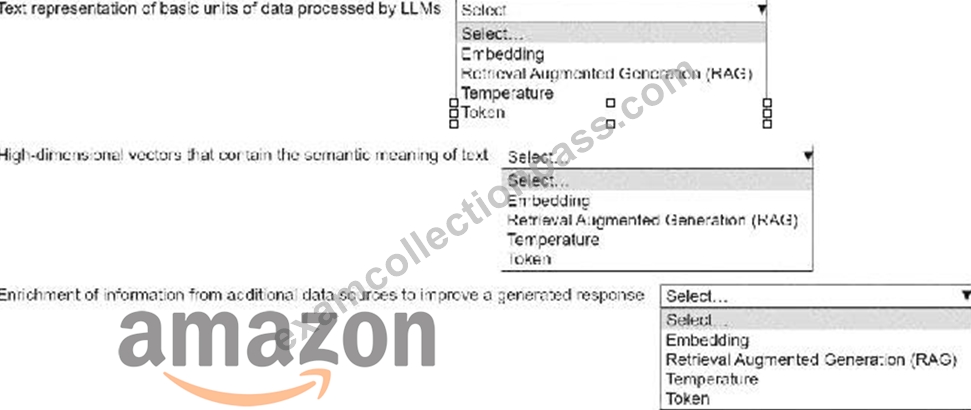
Answer:
Explanation: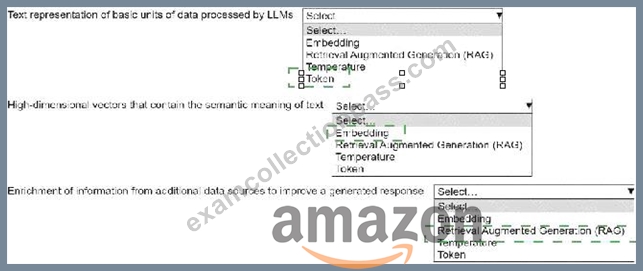
Explanation: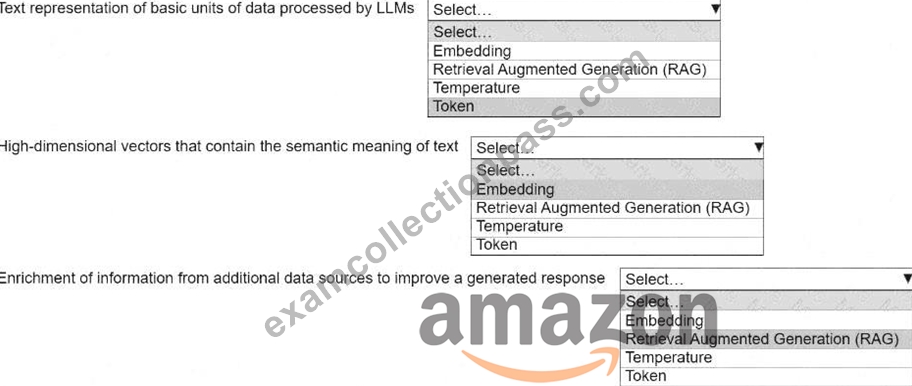
Text representation of basic units of data processed by LLMs: Token
High-dimensional vectors that contain the semantic meaning of text: Embedding Enrichment of information from additional data sources to improve a generated response: Retrieval Augmented Generation (RAG) Comprehensive Detailed Explanation Token:
Description: A token represents the smallest unit of text (e.g., a word or part of a word) that an LLM processes. For example, " running " might be split into two tokens: " run " and " ing. " Why? Tokens are the fundamental building blocks for LLM input and output processing, ensuring that the model can understand and generate text efficiently.
Embedding:
Description: High-dimensional vectors that encode the semantic meaning of text. These vectors are representations of words, sentences, or even paragraphs in a way that reflects their relationships and meaning.
Why? Embeddings are essential for enabling similarity search, clustering, or any task requiring semantic understanding. They allow the model to " understand " text contextually.
Retrieval Augmented Generation (RAG):
Description: A technique where information is enriched or retrieved from external data sources (e.g., knowledge bases or document stores) to improve the accuracy and relevance of a model ' s generated responses.
Why? RAG enhances the generative capabilities of LLMs by grounding their responses in factual and up-to- date information, reducing hallucinations in generated text.
By matching these terms to their respective descriptions, the ML engineer can effectively leverage these concepts to build robust and contextually aware generative AI applications on Amazon Bedrock.
NEW QUESTION # 110
Case study
An ML engineer is developing a fraud detection model on AWS. The training dataset includes transaction logs, customer profiles, and tables from an on-premises MySQL database. The transaction logs and customer profiles are stored in Amazon S3.
The dataset has a class imbalance that affects the learning of the model's algorithm. Additionally, many of the features have interdependencies. The algorithm is not capturing all the desired underlying patterns in the data.
The training dataset includes categorical data and numerical data. The ML engineer must prepare the training dataset to maximize the accuracy of the model.
Which action will meet this requirement with the LEAST operational overhead?
Answer: D
Explanation:
Preparing a training dataset that includes both categorical and numerical data is essential for maximizing the accuracy of a machine learning model. Transforming categorical data into numerical format is a critical step, as most ML algorithms require numerical input.
Why Transform Categorical Data into Numerical Data?
* Model Compatibility: Many ML algorithms cannot process categorical data directly and require numerical representations.
* Improved Performance: Proper encoding of categorical variables can enhance model accuracy and convergence speed.
Why Use Amazon SageMaker Data Wrangler?
Amazon SageMaker Data Wrangler offers a visual interface with over 300 built-in data transformations, including tools for encoding categorical variables.
Implementation Steps:
* Import Data:
* Load the dataset into SageMaker Data Wrangler from sources like Amazon S3 or on-premises databases.
* Identify Categorical Features:
* Use Data Wrangler's data type inference to detect categorical columns.
* Apply Categorical Encoding:
* Choose appropriate encoding techniques (e.g., one-hot encoding or ordinal encoding) from Data Wrangler's transformation options.
* Apply the selected transformation to convert categorical features into numerical format.
* Validate Transformations:
* Review the transformed dataset to ensure accuracy and completeness.
Advantages of Using SageMaker Data Wrangler:
* Ease of Use: Provides a user-friendly interface for data transformation without extensive coding.
* Operational Efficiency: Integrates data preparation steps, reducing the need for multiple tools and minimizing operational overhead.
* Flexibility: Supports various data sources and transformation techniques, accommodating diverse datasets.
By utilizing SageMaker Data Wrangler to transform categorical data into numerical format, the ML engineer can efficiently prepare the dataset, thereby enhancing the model's accuracy with minimal operational overhead.
References:
* Transform Data - Amazon SageMaker
* Prepare ML Data with Amazon SageMaker Data Wrangler
NEW QUESTION # 111
A company is building a web-based AI application by using Amazon SageMaker. The application will provide the following capabilities and features: ML experimentation, training, a central model registry, model deployment, and model monitoring.
The application must ensure secure and isolated use of training data during the ML lifecycle. The training data is stored in Amazon S3.
The company must implement a manual approval-based workflow to ensure that only approved models can be deployed to production endpoints.
Which solution will meet this requirement?
Answer: D
Explanation:
To implement a manual approval-based workflow ensuring that only approved models are deployed to production endpoints, Amazon SageMaker provides integrated tools such as SageMaker Pipelines and the SageMaker Model Registry.
SageMaker Pipelines is a robust service for building, automating, and managing end-to-end machine learning workflows. It facilitates the orchestration of various steps in the ML lifecycle, including data preprocessing, model training, evaluation, and deployment. By integrating with the SageMaker Model Registry, it enables seamless tracking and management of model versions and their approval statuses.
Implementation Steps:
* Define the Pipeline:
* Create a SageMaker Pipeline encompassing steps for data preprocessing, model training, evaluation, and registration of the model in the Model Registry.
* Incorporate a Condition Step to assess model performance metrics. If the model meets predefined criteria, proceed to the next step; otherwise, halt the process.
* Register the Model:
* Utilize the RegisterModel step to add the trained model to the Model Registry.
* Set the ModelApprovalStatus parameter to PendingManualApproval during registration. This status indicates that the model awaits manual review before deployment.
* Manual Approval Process:
* Notify the designated approver upon model registration. This can be achieved by integrating Amazon EventBridge to monitor registration events and trigger notifications via AWS Lambda functions.
* The approver reviews the model's performance and, if satisfactory, updates the model's status to Approved using the AWS SDK or through the SageMaker Studio interface.
* Deploy the Approved Model:
* Configure the pipeline to automatically deploy models with an Approved status to the production endpoint. This can be managed by adding deployment steps conditioned on the model's approval status.
Advantages of This Approach:
* Automated Workflow: SageMaker Pipelines streamline the ML workflow, reducing manual interventions and potential errors.
* Governance and Compliance: The manual approval step ensures that only thoroughly evaluated models are deployed, aligning with organizational standards.
* Scalability: The solution supports complex ML workflows, making it adaptable to various project requirements.
By implementing this solution, the company can establish a controlled and efficient process for deploying models, ensuring that only approved versions reach production environments.
References:
Automate the machine learning model approval process with Amazon SageMaker Model Registry and Amazon SageMaker Pipelines Update the Approval Status of a Model - Amazon SageMaker
NEW QUESTION # 112
An ML engineer wants an Amazon SageMaker notebook to automatically stop running after
1 hour of idle time. How can the ML engineer accomplish this goal?
Answer: D
Explanation:
The correct approach is to use a SageMaker lifecycle configuration and place the auto-stop-idle script in the Start Notebook section. This ensures the notebook runs the monitoring script on startup, which checks for idle time and automatically stops the notebook after the defined threshold (1 hour in this case).
NEW QUESTION # 113
A company is building a deep learning model on Amazon SageMaker. The company uses a large amount of data as the training dataset. The company needs to optimize the model's hyperparameters to minimize the loss function on the validation dataset.
Which hyperparameter tuning strategy will accomplish this goal with the LEAST computation time?
Answer: C
Explanation:
Hyperband is a hyperparameter tuning strategy designed to minimize computation time by adaptively allocating resources to promising configurations and terminating underperforming ones early. It efficiently balances exploration and exploitation, making it ideal for large datasets and deep learning models where training can be computationally expensive.
NEW QUESTION # 114
......
Amazon MLA-C01 Practice tests are formatted like real tests. The ExamcollectionPass platform provides an exceptional level of support for individuals preparing for and taking the Amazon MLA-C01 exam. Their dedicated support team is available to assist candidates with any issues or concerns related to Amazon MLA-C01 Test Preparation. Additionally, the platform offers a money-back guarantee for those who do not pass the MLA-C01 test on their first attempt.
Practice MLA-C01 Engine: https://www.examcollectionpass.com/Amazon/MLA-C01-practice-exam-dumps.html
BONUS!!! Download part of ExamcollectionPass MLA-C01 dumps for free: https://drive.google.com/open?id=17OBpJWPDa_Y-F_e40sjXiJpDEnNZf9f7