DP-600試験解説 & DP-600対応資料

ちなみに、CertJuken DP-600の一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=1vpW1vFkmL29wWqtHkW7ZNC2bYz1uBQkn
現在の仕事に満足していますか。自分がやっていることに満足していますか。自分のレベルを高めたいですか。では、仕事に役に立つスキルをもっと身に付けましょう。もちろん、IT業界で働いているあなたはIT認定試験を受けて資格を取得することは一番良い選択です。それはより良く自分自身を向上させることができますから。もっと大切なのは、あなたもより多くの仕事のスキルをマスターしたことを証明することができます。では、はやくMicrosoftのDP-600認定試験を受験しましょう。この試験はあなたが自分の念願を達成するのを助けることができます。試験に合格する自信を持たなくても大丈夫です。CertJukenへ来てあなたがほしいヘルパーと試験の準備ツールを見つけることができますから。CertJukenの資料はきっとあなたがDP-600試験の認証資格を取ることを助けられます。
Microsoft DP-600 認定試験の出題範囲:
| トピック | 出題範囲 |
|---|
| トピック 1 | - Implement and manage semantic models: This section of the exam measures the skills of architects and focuses on designing and optimizing semantic models to support enterprise-scale analytics. It evaluates understanding of storage modes and implementing star schemas and complex relationships, such as bridge tables and many-to-many joins. Architects must write DAX-based calculations using variables, iterators, and filtering techniques. The use of calculation groups, dynamic format strings, and field parameters is included. The section also includes configuring large semantic models and designing composite models. For optimization, candidates are expected to improve report visual and DAX performance, configure Direct Lake behaviors, and implement incremental refresh strategies effectively.
|
| トピック 2 | - Maintain a data analytics solution: This section of the exam measures the skills of administrators and covers tasks related to enforcing security and managing the Power BI environment. It involves setting up access controls at both workspace and item levels, ensuring appropriate permissions for users and groups. Row-level, column-level, object-level, and file-level access controls are also included, alongside the application of sensitivity labels to classify data securely. This section also tests the ability to endorse Power BI items for organizational use and oversee the complete development lifecycle of analytics assets by configuring version control, managing Power BI Desktop projects, setting up deployment pipelines, assessing downstream impacts from various data assets, and handling semantic model deployments using XMLA endpoint. Reusable asset management is also a part of this domain.
|
| トピック 3 | - Prepare data: This section of the exam measures the skills of engineers and covers essential data preparation tasks. It includes establishing data connections and discovering sources through tools like the OneLake data hub and the real-time hub. Candidates must demonstrate knowledge of selecting the appropriate storage type—lakehouse, warehouse, or eventhouse—depending on the use case. It also includes implementing OneLake integrations with Eventhouse and semantic models. The transformation part involves creating views, stored procedures, and functions, as well as enriching, merging, denormalizing, and aggregating data. Engineers are also expected to handle data quality issues like duplicates, missing values, and nulls, along with converting data types and filtering. Furthermore, querying and analyzing data using tools like SQL, KQL, and the Visual Query Editor is tested in this domain.
|
>> DP-600試験解説 <<
DP-600対応資料 & DP-600予想試験
DP-600試験問題は、学習結果を検出するためのさまざまな自己学習および自己評価機能を備えたソフトウェアを提供します。統計レポート機能は、学生が弱点を見つけて対処するのに役立つように提供されています。当社のソフトウェアには、時間制限やシミュレートされたテスト機能など、多くの新しい機能も搭載されています。速度を調整してアラートを維持できるDP-600テストガイドでシミュレーションテストタイマーを設定したら、知識を習得するために心を傾けることができます。この関数がDP-600試験の合格に役立つことは間違いありません。
Microsoft Implementing Analytics Solutions Using Microsoft Fabric 認定 DP-600 試験問題 (Q138-Q143):
質問 # 138
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a Fabric tenant that contains a lakehouse named Lakehousel. Lakehousel contains a Delta table named Customer.
When you query Customer, you discover that the query is slow to execute. You suspect that maintenance was NOT performed on the table.
You need to identify whether maintenance tasks were performed on Customer.
Solution: You run the following Spark SQL statement:
DESCRIBE DETAIL customer
Does this meet the goal?
正解:A
解説:
The command:
DESCRIBE DETAIL Customer
Returns metadata about the Delta table, such as format, schema, partitioning, size, number of files, and creation/modification timestamps.
However, it does not provide information about whether maintenance tasks (such as OPTIMIZE, VACUUM, or Z-Ordering) were performed on the table.
To check maintenance history, you would typically use:
DESCRIBE HISTORY Customer
which shows operations executed on the table (e.g., OPTIMIZE, VACUUM, MERGE).
Since DESCRIBE DETAIL does not satisfy the requirement, the solution does not meet the goal.
Reference:
DESCRIBE DETAIL in Delta Lake
DESCRIBE HISTORY in Delta Lake
質問 # 139
You have a Microsoft Fabric tenant that contains a dataflow.
You are exploring a new semantic model.
From Power Query, you need to view column information as shown in the following exhibit.

Which three Data view options should you select? Each correct answer presents part of the solution. NOTE:
Each correct answer is worth one point.
- A. Show column quality details
- B. Enable details pane
- C. Show column profile in details pane
- D. Show column value distribution
- E. Enable column profile
正解:A、B、E
解説:
To view column information like the one shown in the exhibit in Power Query, you need to select the options that enable profiling and display quality and distribution details. These are: A. Enable column profile - This option turns on profiling for each column, showing statistics such as distinct and unique values. B. Show column quality details - It displays the column quality bar on top of each column showing the percentage of valid, error, and empty values. E. Show column value distribution - It enables the histogram display of value distribution for each column, which visualizes how often each value occurs.
References: These features and their descriptions are typically found in the Power Query documentation, under the section for data profiling and quality features.
質問 # 140
You have a Fabric warehouse named Watehousel that contains a table named TaxiTrips. TaxiTrips contains the following columns.

You need to create a query that shows the top three taxi companies based on the total miles traveled.
How should you complete the T-SQL statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
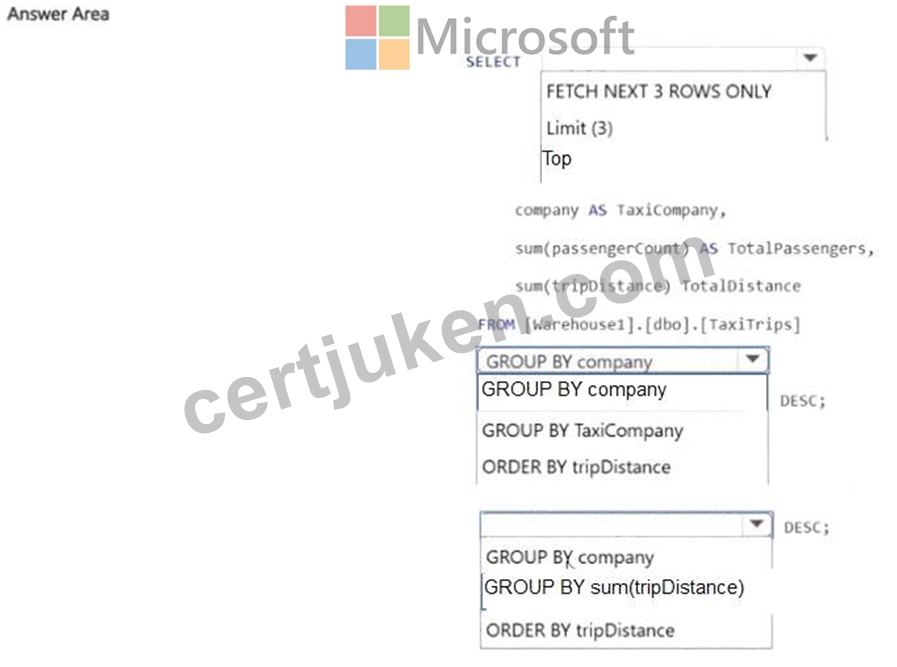
正解:
解説:

Explanation:

質問 # 141
You have a Fabric tenant that contains two workspaces named Workspace1 and Workspace2.
Workspace1 contains a lakehouse named Lakehouse1. Workspace2 contains a lakehouse named Lakehouse2. Lakehouse1 contains a table named dbo.Sales. Lakehouse2 contains a table named dbo.Customers.
You need to ensure that you can write queries that reference both dbo.Sales and dbo.Customers in the same SQL query without making additional copies of the tables.
What should you use?
- A. a dataflow
- B. a view
- C. a shortcut
- D. a managed table
正解:C
質問 # 142
You have a Fabric tenant that contains a semantic model named model1. The two largest columns in model1 are shown in the following table.
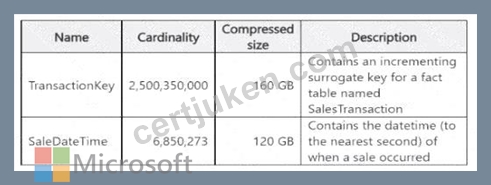
You need to optimize model 1. The solution must meet the following requirements:
* Reduce the model size.
* Increase refresh performance when using Import mode.
* Ensure that the datetime value for each sales transaction is available in the model.
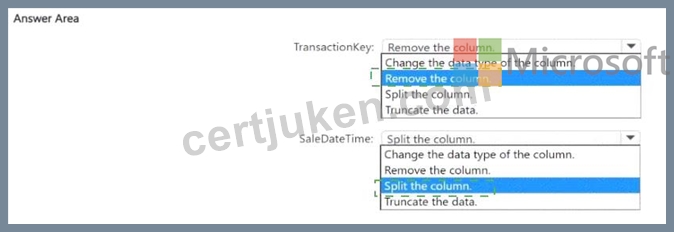
What should you do on each column? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.

正解:
解説:
Explanation:
We are optimizing model1 in Fabric with two very large columns:
TransactionKey
Cardinality: 2.5 billion
Size: 160 GB
Description: surrogate key for SalesTransaction fact table.
SaleDateTime
Cardinality: 6.8 million
Size: 120 GB
Description: datetime (to the second) of when a sale occurred.
Goal:
Reduce model size.
Improve refresh performance (Import mode).
Ensure datetime values remain available .
Analysis per column
1. TransactionKey (very high cardinality)
Surrogate keys with extremely high cardinality do not add analytical value in a semantic model because they are not used in measures or grouping.
They take a lot of memory and reduce refresh performance.
Best practice: remove the column from the model.
2. SaleDateTime
Needed to analyze transactions by date and time.
However, storing the full datetime at second-level cardinality causes huge memory usage.
To optimize: split the column into Date and Time columns.
Reduces cardinality significantly.
Preserves full datetime information (can recombine if needed).
Improves compression and refresh speed.
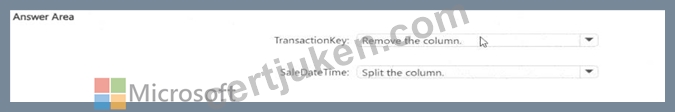
TransactionKey: Remove the column.
SaleDateTime: Split the column.
References:
Microsoft Fabric optimization guidance - reduce cardinality
Best practices for datetime optimization in semantic models
# Answer Selection:
TransactionKey # Remove the column
SaleDateTime # Split the column
質問 # 143
......
常にMicrosoft DP-600試験に参加する予定があるお客様は「こちらの問題集には、全部で何問位、掲載されておりますか?」といった質問を提出しました。心配なくて我々CertJukenのMicrosoft DP-600試験問題集は実際試験のすべての問題種類をカバーします。70%の問題は解説がありますし、試験の内容を理解しやすいと助けます。
DP-600対応資料: https://www.certjuken.com/DP-600-exam.html
- ハイパスレートのDP-600試験解説 - 合格スムーズDP-600対応資料 | 認定するDP-600予想試験 🍍 検索するだけで➠ www.passtest.jp 🠰から➥ DP-600 🡄を無料でダウンロードDP-600日本語認定
- ハイパスレートのDP-600試験解説 - 合格スムーズDP-600対応資料 | 認定するDP-600予想試験 🚄 ➽ www.goshiken.com 🢪に移動し、➡ DP-600 ️⬅️を検索して無料でダウンロードしてくださいDP-600資格練習
- 完璧DP-600|ハイパスレートのDP-600試験解説試験|試験の準備方法Implementing Analytics Solutions Using Microsoft Fabric対応資料 🌲 「 DP-600 」を無料でダウンロード{ jp.fast2test.com }ウェブサイトを入力するだけDP-600受験料過去問
- ハイパスレートのDP-600試験解説 - 合格スムーズDP-600対応資料 | 認定するDP-600予想試験 ⛽ ☀ DP-600 ️☀️を無料でダウンロード《 www.goshiken.com 》で検索するだけDP-600クラムメディア
- 便利-一番優秀なDP-600試験解説試験-試験の準備方法DP-600対応資料 🔆 ✔ www.mogiexam.com ️✔️で➡ DP-600 ️⬅️を検索して、無料でダウンロードしてくださいDP-600資格関連題
- 信頼的なDP-600試験解説 - 合格スムーズDP-600対応資料 | 高品質なDP-600予想試験 🎣 今すぐ➥ www.goshiken.com 🡄を開き、⇛ DP-600 ⇚を検索して無料でダウンロードしてくださいDP-600資格試験
- 実際的なDP-600 試験ツールの保証購入の安全性-Implementing Analytics Solutions Using Microsoft Fabric対応資料 🥩 ⇛ www.jptestking.com ⇚サイトにて➡ DP-600 ️⬅️問題集を無料で使おうDP-600合格体験記
- DP-600資格試験 🐡 DP-600復習対策書 🕔 DP-600対応資料 🎂 [ www.goshiken.com ]サイトにて➤ DP-600 ⮘問題集を無料で使おうDP-600復習資料
- DP-600復習資料 🍫 DP-600日本語認定 🐋 DP-600模擬解説集 🏔 《 jp.fast2test.com 》を開いて▶ DP-600 ◀を検索し、試験資料を無料でダウンロードしてくださいDP-600資格練習
- 試験の準備方法-正確的なDP-600試験解説試験-最新のDP-600対応資料 ➡ URL ▷ www.goshiken.com ◁をコピーして開き、⇛ DP-600 ⇚を検索して無料でダウンロードしてくださいDP-600模擬解説集
- 便利-一番優秀なDP-600試験解説試験-試験の準備方法DP-600対応資料 🧫 《 www.topexam.jp 》の無料ダウンロード( DP-600 )ページが開きますDP-600資格練習
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, devfolio.co, Disposable vapes
さらに、CertJuken DP-600ダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1vpW1vFkmL29wWqtHkW7ZNC2bYz1uBQkn