DOWNLOAD the newest ITExamDownload DP-100 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1mKlaKcdIWfE687R0URl2kmPUIOGDNby8
The ITExamDownload Designing and Implementing a Data Science Solution on Azure (DP-100) exam dumps are ready for quick download. Just choose the right DP-100 exam questions format and download it after paying an affordable Designing and Implementing a Data Science Solution on Azure in DP-100 Practice Questions charge and start this journey. Best of luck in the Microsoft DP-100 exam and career!!!
The DP-100 certification exam is an excellent way for professionals to demonstrate their expertise in data science and machine learning on Azure. Designing and Implementing a Data Science Solution on Azure certification exam covers a range of topics, including data exploration, data preparation, modeling, and deployment. It also covers topics such as data ingestion, storage, and processing, as well as the use of various Azure services such as Azure Machine Learning, Azure Databricks, and Azure Cognitive Services. By passing the DP-100 Certification Exam, professionals can demonstrate their skills and knowledge to potential employers, and also gain access to a range of new career opportunities in the field of data science and machine learning.
>> Reliable DP-100 Real Test <<
It is acknowledged that high-quality service after sales plays a vital role in enhancing the quality of our DP-100 learning engine. Therefore, we, as a leader in the field specializing in the DP-100 exam material especially focus on the service after sales. In order to provide the top service on our DP-100 training prep, our customer agents will work 24/7. So if you have any doubts about the DP-100study guide, you can contact us by email or the Internet at any time you like.
Microsoft DP-100 certification exam is a highly regarded certification in the field of data science. DP-100 exam is designed to test the candidate's expertise in designing and implementing data science solutions on Microsoft Azure. DP-100 Exam is primarily intended for data scientists who have experience in designing and implementing data science solutions on Microsoft Azure.
NEW QUESTION # 94
You use the following code to run a script as an experiment in Azure Machine Learning: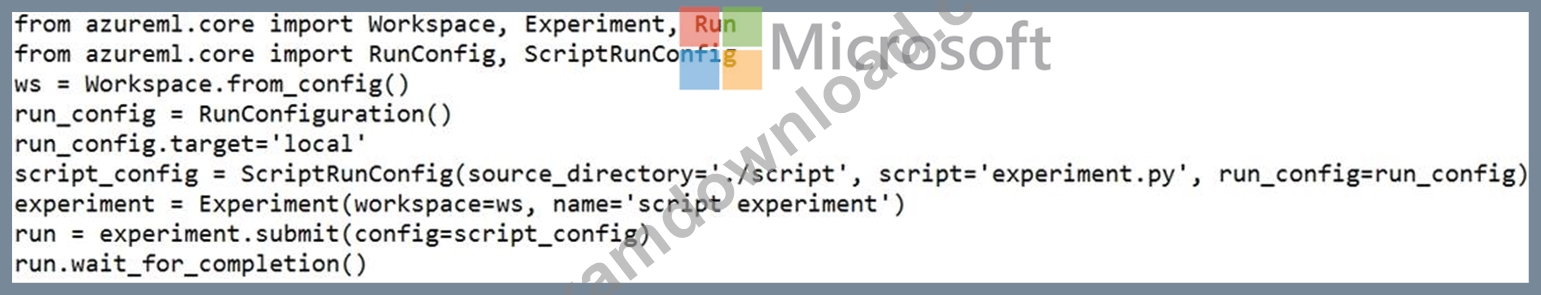
You must identify the output files that are generated by the experiment run.
You need to add code to retrieve the output file names.
Which code segment should you add to the script?
Answer: E
Explanation:
Explanation
You can list all of the files that are associated with this run record by called run.get_file_names() Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-track-experiments
NEW QUESTION # 95
You are solving a classification task.
You must evaluate your model on a limited data sample by using k-fold cross validation. You start by configuring a k parameter as the number of splits.
You need to configure the k parameter for the cross-validation.
Which value should you use?
Answer: A
Explanation:
Explanation/Reference:
Explanation:
Leave One Out (LOO) cross-validation
Setting K = n (the number of observations) yields n-fold and is called leave-one out cross-validation (LOO), a special case of the K-fold approach.
LOO CV is sometimes useful but typically doesn't shake up the data enough. The estimates from each fold are highly correlated and hence their average can have high variance.
This is why the usual choice is K=5 or 10. It provides a good compromise for the bias-variance tradeoff.
NEW QUESTION # 96
Your Azure Machine Learning workspace has a dataset named real_estate_data. A sample of the data in the dataset follows.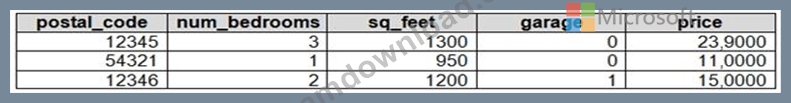
You want to use automated machine learning to find the best regression model for predicting the price column.
You need to configure an automated machine learning experiment using the Azure Machine Learning SDK.
How should you complete the code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.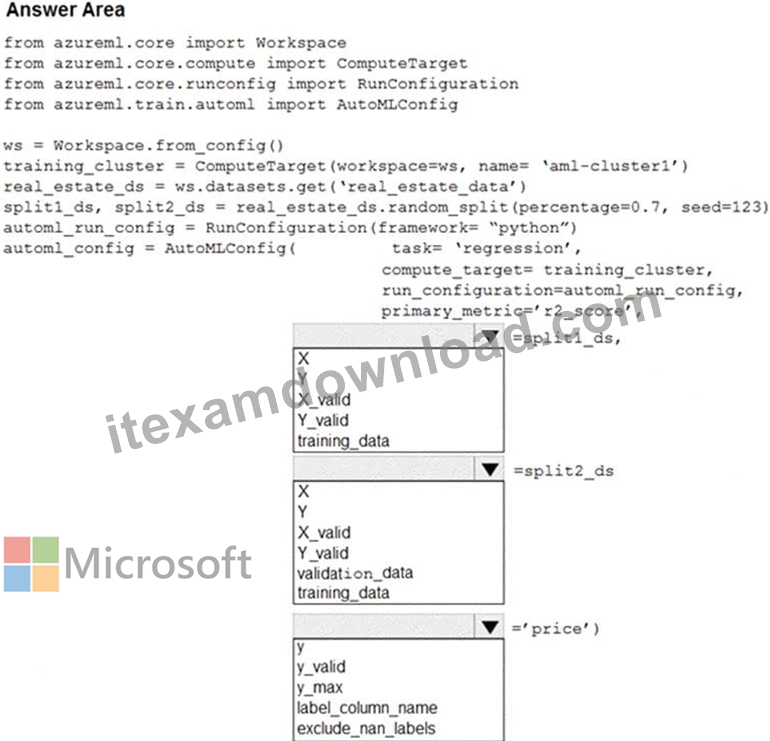
Answer:
Explanation: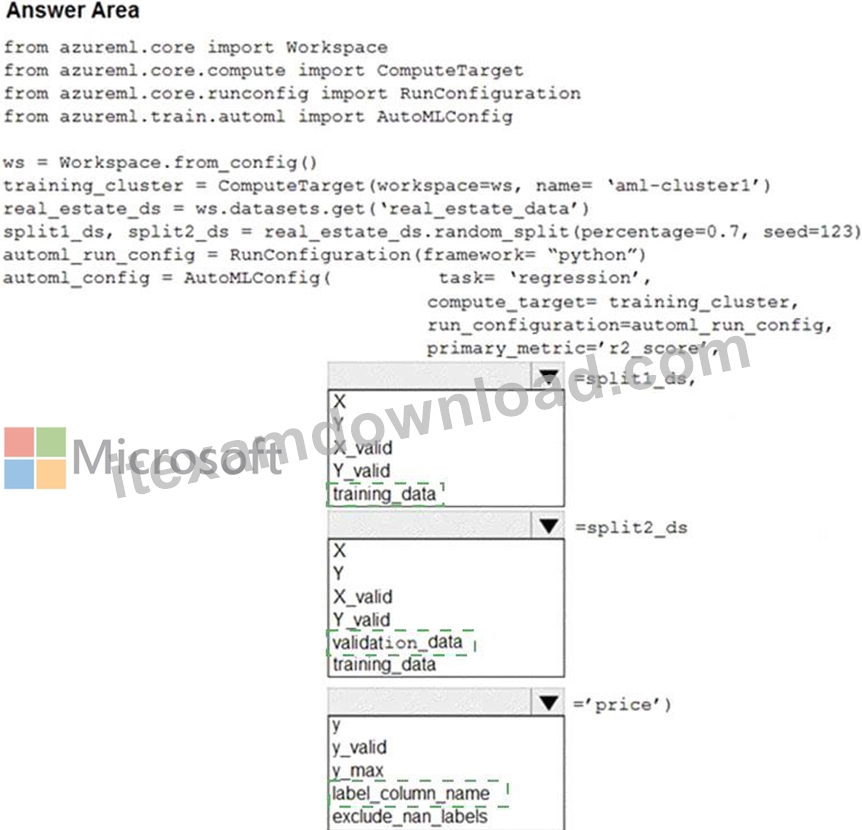
Explanation: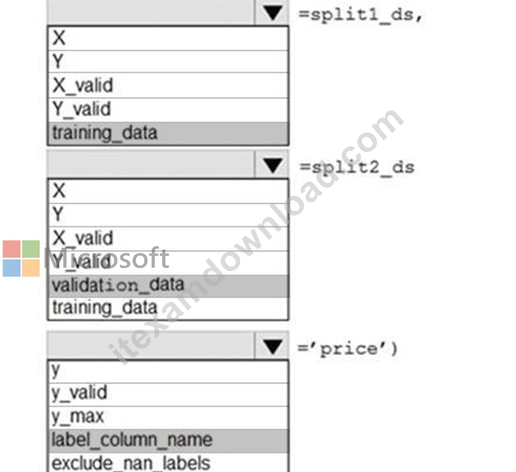
Box 1: training_data
The training data to be used within the experiment. It should contain both training features and a label column (optionally a sample weights column). If training_data is specified, then the label_column_name parameter must also be specified.
Box 2: validation_data
Provide validation data: In this case, you can either start with a single data file and split it into training and validation sets or you can provide a separate data file for the validation set. Either way, the validation_data parameter in your AutoMLConfig object assigns which data to use as your validation set.
Example, the following code example explicitly defines which portion of the provided data in dataset to use for training and validation.
dataset = Dataset.Tabular.from_delimited_files(data)
training_data, validation_data = dataset.random_split(percentage=0.8, seed=1) automl_config = AutoMLConfig(compute_target = aml_remote_compute, task = 'classification', primary_metric = 'AUC_weighted', training_data = training_data, validation_data = validation_data, label_column_name = 'Class' ) Box 3: label_column_name label_column_name:
The name of the label column. If the input data is from a pandas.DataFrame which doesn't have column names, column indices can be used instead, expressed as integers.
This parameter is applicable to training_data and validation_data parameters.
Reference:
https://docs.microsoft.com/en-us/python/api/azureml-train-automl-client/azureml.train.automl.automlconfig.
automlconfig?view=azure-ml-py
NEW QUESTION # 97
Hotspot Question
You create an Azure Machine Learning workspace. You use the Azure Machine Learning SDK for Python.
You must create a dataset from remote paths. The dataset must be reusable within the workspace.
You need to create the dataset.
How should you complete the following code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.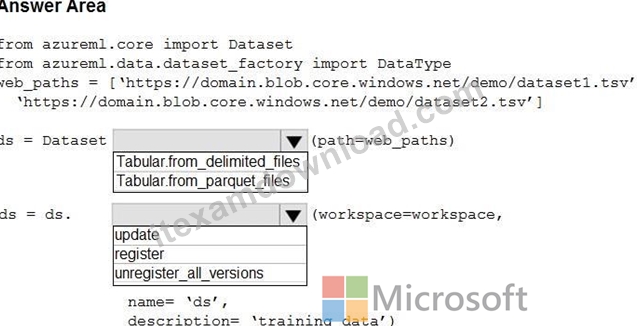
Answer:
Explanation: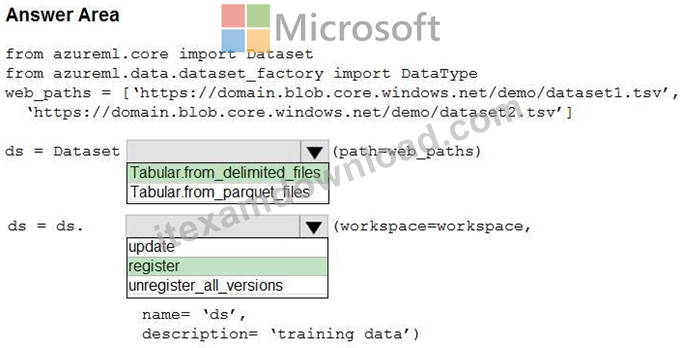
NEW QUESTION # 98
You manage an Azure Al Foundry project.
You are evaluating two RAG solutions.
When generating answers, the solutions display the following results:
* The first solution displays low completeness and low utilization.
* The second solution displays low completeness and high utilization.
You need to address the issues found during evaluation.
Which action should you perform first for each issue? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.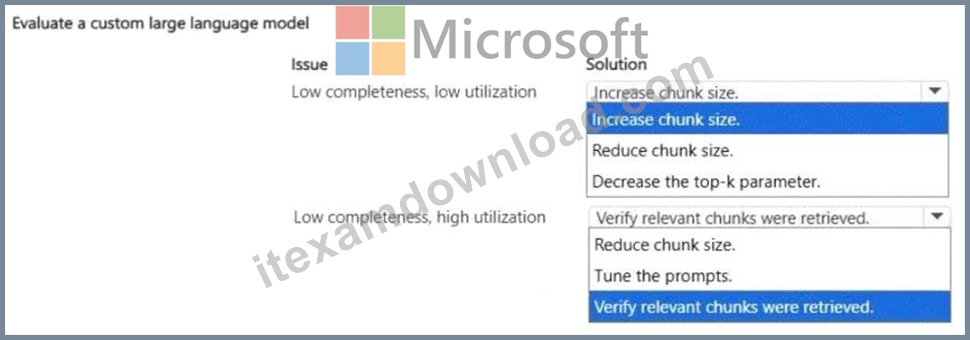
Answer:
Explanation: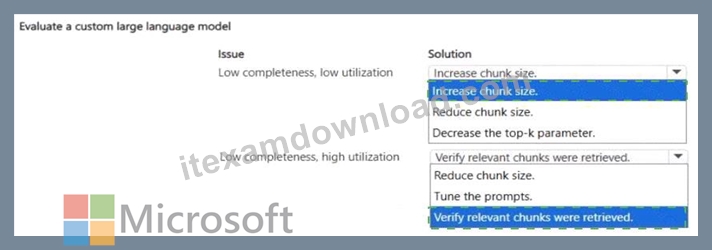
Explanation: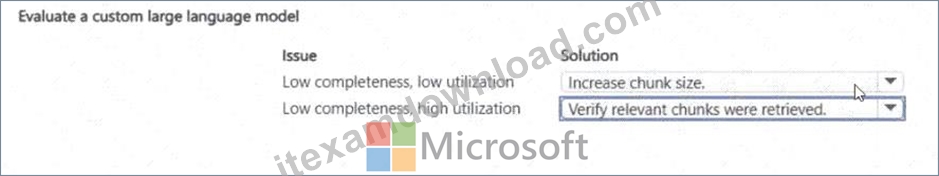
NEW QUESTION # 99
......
Reliable DP-100 Exam Test: https://www.itexamdownload.com/DP-100-valid-questions.html
DOWNLOAD the newest ITExamDownload DP-100 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1mKlaKcdIWfE687R0URl2kmPUIOGDNby8