2026 Latest PassTorrent SPS-C01 PDF Dumps and SPS-C01 Exam Engine Free Share: https://drive.google.com/open?id=1xKhr5XUUOdxKAI1ejZpT31MupQc7PE3T
We provide Snowflake SPS-C01 web-based self-assessment practice software that will help you to prepare for the Snowflake certification exam. Snowflake SPS-C01 Web-based software offers computer-based assessment solutions to help you automate the entire Snowflake Certified SnowPro Specialty - Snowpark testing procedure. The stylish and user-friendly interface works with all browsers, including Mozilla Firefox, Google Chrome, Opera, Safari, and Internet Explorer. It will make your certification exam preparation simple, quick, and smart. So, rest certain that you will discover all you need to study for and pass the Snowflake SPS-C01 Exam on the first try.
| Section | Objectives |
|---|---|
| Topic 1: Testing, Debugging, and Deployment | - Production readiness
|
| Topic 2: Snowpark Fundamentals | - Snowpark architecture and concepts
|
| Topic 3: Performance Optimization and Best Practices | - Efficient Snowpark execution
|
| Topic 4: User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| Topic 5: DataFrame Operations and Data Processing | - Data transformation workflows
|
| Topic 6: Data Engineering with Snowpark | - Pipeline development
|
Professionals have designed this Snowflake SPS-C01 exam dumps product for the ones who want to clear the SPS-C01 test in a short time. Success in the Snowflake SPS-C01 exam questions helps you get a good salary job in a reputed company. PassTorrent Snowflake SPS-C01 Study Material is available in three formats. These formats have SPS-C01 real dumps so that the applicants can memorize them and crack the SPS-C01 certification test with a good score.
NEW QUESTION # 216
Consider a Snowflake table 'orders' with columns 'order_id', 'customer_id', 'order_date', and 'status'. You need to update the 'status' of all orders placed before January 1, 2023, to 'Archived'. Which of the following approaches is the most efficient and idiomatic way to achieve this using Snowpark DataFrames, assuming 'orders df DataFrame represents the 'orders' table?
Answer: A,E
Explanation:
Options C and D are both valid and efficient solutions. Option C leverages Snowpark's 'with_column' and 'when' functions to conditionally update the 'status' column within the DataFrame and persists the changes back to the table using 'save_as_table'. Using lit function makes sure that 'Archived' status is passed as a literal. Option D uses a direct SQL update statement executed through the Snowpark session. This bypasses DataFrame operations but directly modifies the table, which can sometimes be more efficient for simple update operations. Option A is almost correct but the with_column and filter are applied separately. Option B doesn't work due to the way update functions are implemented in Snowpark. Option E unnecessarily collects the filtered data back to the driver, creating a new DataFrame from the collected data, then applying 'with_column'. This is an inefficient approach.
NEW QUESTION # 217
You have developed a Snowpark application that uses a Python UDF to perform sentiment analysis on text data extracted from JSON files stored in a Snowflake stage. The UDF relies on a large pre-trained machine learning model that is loaded during the UDF initialization. After deploying the application, you observe that the UDF initialization is taking a significant amount of time, causing slow query performance. What are the three MOST effective strategies to optimize the UDF initialization time in this scenario?
Answer: A,D,E
Explanation:
Optimizing UDF initialization is crucial for performance. Option A is correct because caching the model using 'cachetoolS avoids reloading it for each UDF call. Option C is also correct; 'context.add_dependency' tells Snowflake to distribute and cache the model on worker nodes, further reducing load times. Option D avoids the need for the UDF to load the model, reducing the initialization step down entirely. Streamlit caching is not valid for Snowflake operations, making option E incorrect. 'SnowflakeFile' isn't best used within a UDF initializer as its inefficient, making option B incorrect.
NEW QUESTION # 218
You have a Snowpark DataFrame containing semi-structured data in a column named 'payload'. The 'payload' column contains JSON objects, and some of these objects contain nested arrays. You need to flatten all arrays, regardless of their level of nesting, and extract specific fields from the flattened data'. What is the MOST efficient approach using Snowpark to achieve this while minimizing the amount of code?
Answer: E
Explanation:
Option D, using 'LATERAL FLATTEN' within a SQL context, is the most efficient approach. 'LATERAL FLATTEN' is designed specifically for flattening arrays in Snowflake and can handle nested structures efficiently within SQL. By crafting a SQL statement and using session.sqr, one can leverage the power of Snowflake's SQL engine for this task. Other options involve more complex code (UDFs, RDD conversions) or are less efficient (iterative exploding).
NEW QUESTION # 219
You are using VS Code with the Snowflake extension to develop a Snowpark application. You have successfully connected to your Snowflake account and are writing a script that creates a stage and then loads data from a local file into a Snowflake table using Snowpark. However, you're encountering issues with file paths and permission errors. Which of the following strategies would best address these challenges and ensure your Snowpark application can reliably load data from local files?
Answer: A
Explanation:
Option B is the most secure and recommended approach. Snowflake's security model restricts direct access to local file systems. Using 'session.file.put' uploads the file to a Snowflake-managed stage (either internal or external), ensuring data is transferred securely and access is controlled within the Snowflake environment. Then, 'copy_into' safely loads the staged data into the table. The other options are problematic for these reasons: Option A is incorrect because Snowflake does not directly access the local file system for security reasons. Option C is overly complex and introduces external dependencies that can be difficult to manage and secure. Option D is incorrect as Snowflake does not allow modifications to account-level parameters to grant direct local file system access. This would be a major security risk. Option E is incorrect. VS Code's remote development is for connecting to remote servers; it cannot run code on Snowflake compute nodes.
NEW QUESTION # 220
You are developing a Snowpark application to load data into a Snowflake table named 'SALES DATA. The DataFrame 'sales_df contains new sales records. You need to insert these records into 'SALES DATA. Which of the following Snowpark DataFrame methods will efficiently perform this operation, considering potential data type mismatches between the DataFrame and the target table? Assume no explicit schema definition is necessary.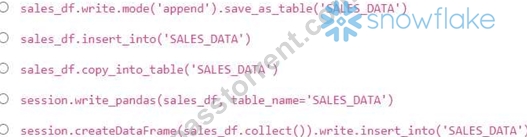
Answer: D
Explanation:
The method directly inserts the DataFrame's data into the specified Snowflake table. Snowpark implicitly handles data type conversions where possible. is generally for creating new tables. is for loading data from files in stages, and 'write_pandas' method requires pandas DataFrame and session object. Using is inefficient as it collects all the data into the driver and then inserts and can cause memory issues.
NEW QUESTION # 221
......
If you want a relevant and precise content that imparts you the most updated, relevant and practical knowledge on all the key topics of the SPS-C01 Certification Exam, no other SPS-C01study material meets these demands so perfectly as does PassTorrent’s study guides. The SPS-C01 questions and answers in these guides have been prepared by the best professionals who have deep exposure of the certification exams and the exam takers needs. The result is that PassTorrent's study guides are liked by so many ambitious professionals who give them first priority for their exams. The astonishing success rate of PassTorrent's clients is enough to prove the quality and benefit of the study questions of PassTorrent.
Exam SPS-C01 Exercise: https://www.passtorrent.com/SPS-C01-latest-torrent.html
P.S. Free 2026 Snowflake SPS-C01 dumps are available on Google Drive shared by PassTorrent: https://drive.google.com/open?id=1xKhr5XUUOdxKAI1ejZpT31MupQc7PE3T