Reliable Databricks-Certified-Professional-Data-Engineer Test Sample - Exam Databricks-Certified-Professional-Data-Engineer Cram Questions
You should figure out what kind of Databricks-Certified-Professional-Data-Engineer test guide is most suitable for you. We here promise you that our Databricks-Certified-Professional-Data-Engineer certification material is the best in the market, which can definitely exert positive effect on your study. Our Databricks-Certified-Professional-Data-Engineer learn tool create a kind of relaxing leaning atmosphere that improve the quality as well as the efficiency, on one hand provide conveniences, on the other hand offer great flexibility and mobility for our customers. And we believe you will love our Databricks-Certified-Professional-Data-Engineer Exam Questions if you can free download the demo of our Databricks-Certified-Professional-Data-Engineer learning guide.
| Section | Weight | Objectives |
|---|
| Topic 1: Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
- 1. Data governance fundamentals
- 2. Bronze, silver, gold data layers
- 3. Differences between data lake, data warehouse, and lakehouse
|
| Topic 2: Data Processing with Spark | 25-30% | - Spark DataFrames and Spark SQL
- 1. Window functions
- 2. DataFrame operations and transformations
- 3. Spark SQL queries and functions
- Python and SQL for data engineering
- 1. Built-in and user-defined functions
- 2. Performance optimization techniques
- 3. Spark APIs in Python
|
| Topic 3: Delta Lake | 20-25% | - Delta Lake fundamentals
- 1. Optimize and Z-order
- 2. ACID transactions
- 3. Time travel and data versioning
- Delta Lake operations
- 1. Delta Live Tables
- 2. Merge, update, delete operations
- 3. Schema evolution and enforcement
|
| Topic 4: Data Ingestion | 15-20% | - Streaming ingestion
- 1. Structured streaming fundamentals
- 2. Kafka integration
- Batch ingestion methods
- 1. Integration with external systems
- 2. Spark APIs for ingestion
- 3. DBR autoloader
|
| Topic 5: Pipeline Development and Orchestration | 10-15% | - Databricks workflows
- 1. Task dependencies and orchestration
- 2. Monitoring and alerting
- 3. Jobs and job scheduling
|
>> Reliable Databricks-Certified-Professional-Data-Engineer Test Sample <<
Exam Databricks-Certified-Professional-Data-Engineer Cram Questions - Exam Dumps Databricks-Certified-Professional-Data-Engineer Free
To be out of the ordinary and seek an ideal life, we must master an extra skill to get high scores and win the match in the workplace. Contemporarily, social competitions stimulate development of modern science, technology and business, which revolutionizes our society's recognition to Databricks-Certified-Professional-Data-Engineer Exam and affect the quality of people's life. Our Databricks-Certified-Professional-Data-Engineer exam question can help make your dream come true. What's more, you can have a visit of our website that provides you more detailed information about the Databricks-Certified-Professional-Data-Engineer guide torrent.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q37-Q42):
NEW QUESTION # 37
The business reporting team requires that data for their dashboards be updated every hour. The total processing time for the pipeline that extracts, transforms, and loads the data for their pipeline runs in 10 minutes. Assuming normal operating conditions, which configuration will meet their service-level agreement requirements with the lowest cost?
- A. Schedule a job to execute the pipeline once an hour on a dedicated interactive cluster.
- B. Schedule a job to execute the pipeline once an hour on a new job cluster.
- C. Schedule a Structured Streaming job with a trigger interval of 60 minutes.
- D. Configure a job that executes every time new data lands in a given directory.
Answer: B
Explanation:
* Exact extract: "Job clusters are created for a job run and terminate when the job completes." References: Cluster types (job vs all-purpose); Databricks Jobs scheduling.
NEW QUESTION # 38
A data ingestion task requires a one-TB JSON dataset to be written out to Parquet with a target part-file size of
512 MB. Because Parquet is being used instead of Delta Lake, built-in file-sizing features such as Auto-Optimize & Auto-Compaction cannot be used.
Which strategy will yield the best performance without shuffling data?
- A. Set spark.sql.shuffle.partitions to 512, ingest the data, execute the narrow transformations, and then write to parquet.
- B. Set spark.sql.shuffle.partitions to 2,048 partitions (1TB*1024*1024/512), ingest the data, execute the narrow transformations, optimize the data by sorting it (which automatically repartitions the data), and then write to parquet.
- C. Set spark.sql.adaptive.advisoryPartitionSizeInBytes to 512 MB bytes, ingest the data, execute the narrow transformations, coalesce to 2,048 partitions (1TB*1024*1024/512), and then write to parquet.
- D. Ingest the data, execute the narrow transformations, repartition to 2,048 partitions (1TB*
1024*1024/512), and then write to parquet. - E. Set spark.sql.files.maxPartitionBytes to 512 MB, ingest the data, execute the narrow transformations, and then write to parquet.
Answer: B
NEW QUESTION # 39
A Delta Lake table was created with the below query:
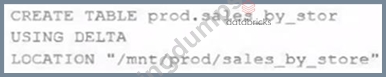
Realizing that the original query had a typographical error, the below code was executed:
ALTER TABLE prod.sales_by_stor RENAME TO prod.sales_by_store
Which result will occur after running the second command?
- A. A new Delta transaction log Is created for the renamed table.
- B. The table reference in the metastore is updated and all data files are moved.
- C. The table reference in the metastore is updated and no data is changed.
- D. The table name change is recorded in the Delta transaction log.
- E. All related files and metadata are dropped and recreated in a single ACID transaction.
Answer: C
Explanation:
The query uses the CREATE TABLE USING DELTA syntax to create a Delta Lake table from an existing Parquet file stored in DBFS. The query also uses the LOCATION keyword to specify the path to the Parquet file as /mnt/finance_eda_bucket/tx_sales.parquet. By using the LOCATION keyword, the query creates an external table, which is a table that is stored outside of the default warehouse directory and whose metadata is not managed by Databricks. An external table can be created from an existing directory in a cloud storage system, such as DBFS or S3, that contains data files in a supported format, such as Parquet or CSV.
The result that will occur after running the second command is that the table reference in the metastore is updated and no data is changed. The metastore is a service that stores metadata about tables, such as their schema, location, properties, and partitions. The metastore allows users to access tables using SQL commands or Spark APIs without knowing their physical location or format. When renaming an external table using the ALTER TABLE RENAME TO command, only the table reference in the metastore is updated with the new name; no data files or directories are moved or changed in the storage system. The table will still point to the same location and use the same format as before. However, if renaming a managed table, which is a table whose metadata and data are both managed by Databricks, both the table reference in the metastore and the data files in the default warehouse directory are moved and renamed accordingly. Verified References:
[Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "ALTER TABLE RENAME TO" section; Databricks Documentation, under "Metastore" section; Databricks Documentation, under "Managed and external tables" section.
NEW QUESTION # 40
A junior data engineer is working to implement logic for a Lakehouse table namedsilver_device_recordings.
The source data contains 100 unique fields in a highly nested JSON structure.
Thesilver_device_recordingstable will be used downstream to power several production monitoring dashboards and a production model. At present, 45 of the 100 fields are being used in at least one of these applications.
The data engineer is trying to determine the best approach for dealing with schema declaration given the highly-nested structure of the data and the numerous fields.
Which of the following accurately presents information about Delta Lake and Databricks that may impact their decision-making process?
- A. Because Delta Lake uses Parquet for data storage, data types can be easily evolved by just modifying file footer information in place.
- B. Human labor in writing code is the largest cost associated with data engineering workloads; as such, automating table declaration logic should be a priority in all migration workloads.
- C. The Tungsten encoding used by Databricks is optimized for storing string data; newly-added native support for querying JSON strings means that string types are always most efficient.
- D. Schema inference and evolution on .Databricks ensure that inferred types will always accurately match the data types used by downstream systems.
- E. Because Databricks will infer schema using types that allow all observed data to be processed, setting types manually provides greater assurance of data quality enforcement.
Answer: E
Explanation:
This is the correct answer because it accurately presents information about Delta Lake and Databricks that may impact the decision-making process of a junior data engineer who is tryingto determine the best approach for dealing with schema declaration given the highly-nested structure of the data and the numerous fields.
Delta Lake and Databricks support schema inference and evolution, which means that they can automatically infer the schema of a table from the source data and allow adding new columns or changing column types without affecting existing queries or pipelines. However, schema inference and evolution may not always be desirable or reliable, especially when dealing with complex or nested data structures or when enforcing data quality and consistency across different systems. Therefore, setting types manually can provide greater assurance of data quality enforcement and avoid potential errors or conflicts due to incompatible or unexpected data types. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Schema inference and partition of streaming DataFrames/Datasets" section.
NEW QUESTION # 41
A data engineer needs to capture pipeline settings from an existing in the workspace, and use them to create and version a JSON file to create a new pipeline.
Which command should the data engineer enter in a web terminal configured with the Databricks CLI?
- A. Use list pipelines to get the specs for all pipelines; get the pipeline spec from the return results parse and use this to create a pipeline
- B. Use the get command to capture the settings for the existing pipeline; remove the pipeline_id and rename the pipeline; use this in a create command
- C. Use the alone command to create a copy of an existing pipeline; use the get JSON command to get the pipeline definition; save this to git
- D. Stop the existing pipeline; use the returned settings in a reset command
Answer: B
Explanation:
The Databricks CLI provides a way to automate interactions with Databricks services. When dealing with pipelines, you can use the databricks pipelines get --pipeline-id command to capture the settings of an existing pipeline in JSON format. This JSON can then be modified by removing the pipeline_id to prevent conflicts and renaming the pipeline to create a new pipeline. The modified JSON file can then be used with the databricks pipelines create command to create a new pipeline with those settings.
:
Databricks Documentation on CLI for Pipelines: Databricks CLI - Pipelines
NEW QUESTION # 42
......
Our Databricks-Certified-Professional-Data-Engineer prep material target all users and any learners, regardless of their age, gender and education background. We provide 3 versions of our Databricks-Certified-Professional-Data-Engineer learning prep for the clients to choose based on the consideration that all the users can choose the most suitable version to learn. The 3 versions each support different using method and equipment and the client can use the Databricks-Certified-Professional-Data-Engineer Exam study materials on the smart phones, laptops or the tablet computers. The clients can choose the version of our Databricks-Certified-Professional-Data-Engineer exam questions which supports their equipment on their hands to learn.
Exam Databricks-Certified-Professional-Data-Engineer Cram Questions: https://www.trainingdumps.com/Databricks-Certified-Professional-Data-Engineer_exam-valid-dumps.html
- Databricks Databricks-Certified-Professional-Data-Engineer Dumps-Ensure your Brilliant Success In Exam 😜 Search for ➤ Databricks-Certified-Professional-Data-Engineer ⮘ on ▷ www.vceengine.com ◁ immediately to obtain a free download 🧬Databricks-Certified-Professional-Data-Engineer Reliable Study Materials
- Valid Databricks-Certified-Professional-Data-Engineer Test Vce 🔈 Latest Databricks-Certified-Professional-Data-Engineer Test Vce 🚝 Databricks-Certified-Professional-Data-Engineer Interactive Course 📪 Open ✔ www.pdfvce.com ️✔️ and search for ➠ Databricks-Certified-Professional-Data-Engineer 🠰 to download exam materials for free 🏓Unlimited Databricks-Certified-Professional-Data-Engineer Exam Practice
- 100% Pass 2026 Databricks Databricks-Certified-Professional-Data-Engineer: Pass-Sure Reliable Databricks Certified Professional Data Engineer Exam Test Sample 🍳 Search for ▷ Databricks-Certified-Professional-Data-Engineer ◁ and download it for free on ☀ www.prep4sures.top ️☀️ website 🥒Latest Databricks-Certified-Professional-Data-Engineer Test Vce
- Databricks-Certified-Professional-Data-Engineer Quiz Prep Makes Databricks-Certified-Professional-Data-Engineer Exam Easy - Pdfvce 🌀 Go to website 《 www.pdfvce.com 》 open and search for ▷ Databricks-Certified-Professional-Data-Engineer ◁ to download for free 🙏Latest Databricks-Certified-Professional-Data-Engineer Test Vce
- Reliable Reliable Databricks-Certified-Professional-Data-Engineer Test Sample - Leading Provider in Qualification Exams - Verified Exam Databricks-Certified-Professional-Data-Engineer Cram Questions 🤲 Search for ➥ Databricks-Certified-Professional-Data-Engineer 🡄 and download it for free immediately on ✔ www.prepawaypdf.com ️✔️ 🚤Detailed Databricks-Certified-Professional-Data-Engineer Study Dumps
- Actual Databricks Databricks-Certified-Professional-Data-Engineer Exam Questions in PDF 💑 Enter ( www.pdfvce.com ) and search for ⮆ Databricks-Certified-Professional-Data-Engineer ⮄ to download for free 🤼Online Databricks-Certified-Professional-Data-Engineer Version
- Valid Databricks-Certified-Professional-Data-Engineer Test Vce 🏁 Databricks-Certified-Professional-Data-Engineer Latest Braindumps Book ☀ Databricks-Certified-Professional-Data-Engineer Valid Braindumps Sheet 💖 Search on ⮆ www.validtorrent.com ⮄ for ( Databricks-Certified-Professional-Data-Engineer ) to obtain exam materials for free download 🌿Valid Databricks-Certified-Professional-Data-Engineer Test Vce
- 100% Pass Quiz Databricks - Reliable Databricks-Certified-Professional-Data-Engineer Test Sample 🐧 Open { www.pdfvce.com } enter ➽ Databricks-Certified-Professional-Data-Engineer 🢪 and obtain a free download 👬Latest Databricks-Certified-Professional-Data-Engineer Test Vce
- Detailed Databricks-Certified-Professional-Data-Engineer Study Dumps 💉 Databricks-Certified-Professional-Data-Engineer Valid Braindumps Sheet 🥃 Databricks-Certified-Professional-Data-Engineer Interactive Practice Exam 🧀 Simply search for ✔ Databricks-Certified-Professional-Data-Engineer ️✔️ for free download on ▛ www.dumpsquestion.com ▟ 🏣Online Databricks-Certified-Professional-Data-Engineer Version
- Relevant Databricks-Certified-Professional-Data-Engineer Questions 🌎 Databricks-Certified-Professional-Data-Engineer Latest Exam Preparation 🤽 Questions Databricks-Certified-Professional-Data-Engineer Exam 🕜 Search for ⮆ Databricks-Certified-Professional-Data-Engineer ⮄ on ▷ www.pdfvce.com ◁ immediately to obtain a free download 🧏Databricks-Certified-Professional-Data-Engineer Latest Braindumps Book
- Trusted Databricks-Certified-Professional-Data-Engineer Exam Resource 🥞 Trusted Databricks-Certified-Professional-Data-Engineer Exam Resource 💺 Databricks-Certified-Professional-Data-Engineer Free Dump Download 🏤 Search for “ Databricks-Certified-Professional-Data-Engineer ” on { www.prepawaypdf.com } immediately to obtain a free download 🕺Valid Databricks-Certified-Professional-Data-Engineer Test Vce
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes