DOWNLOAD the newest Prep4sureGuide DP-100 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=133W67LwSkSA40qucMF2DDTnoJddNlr5y
When you decide to buy a product, you definitely want to use it right away. Our staffs who are working on the DP-100 exam questions certainly took this into consideration. Many of our worthy customers worried that it will take a long time to get our DP-100 study braindumps, but in fact as long as your payment is successful, we will send a link of the DP-100 learning guide to your e-mail within five to ten minutes. You can download and study with our DP-100 practice engine immediately.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Design and prepare a machine learning solution | 20-25% | - Manage Azure Machine Learning workspace
|
| Topic 2: Explore data and run experiments | 20-25% | - Explore and visualize data
|
| Topic 3: Optimize language models for AI applications | 25-30% | - Implement generative AI solutions
|
| Topic 4: Train and deploy models | 25-30% | - Monitor and maintain models
|
>> Microsoft DP-100 Latest Test Answers <<
The three formats of DP-100 practice material that we have discussed above are created after receiving feedback from thousands of professionals around the world. You can instantly download the Designing and Implementing a Data Science Solution on Azure (DP-100) real questions of the Prep4sureGuide right after the payment. We also offer our clients free demo version to evaluate the of our Designing and Implementing a Data Science Solution on Azure (DP-100) valid exam dumps before purchasing.
NEW QUESTION # 194
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You train a classification model by using a logistic regression algorithm.
You must be able to explain the model's predictions by calculating the importance of each feature, both as an overall global relative importance value and as a measure of local importance for a specific set of predictions.
You need to create an explainer that you can use to retrieve the required global and local feature importance values.
Solution: Create a TabularExplainer.
Does the solution meet the goal?
Answer: A
Explanation:
Instead use Permutation Feature Importance Explainer (PFI).
Note 1: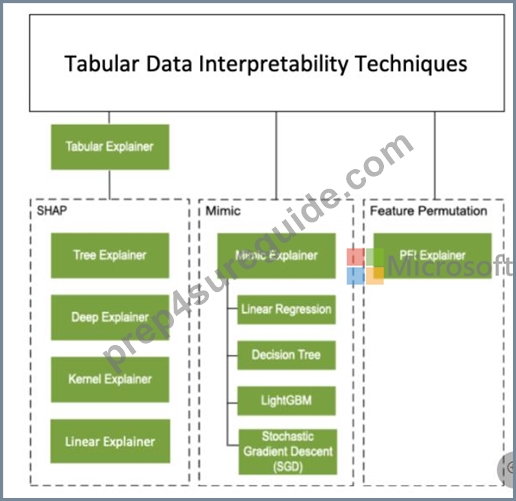
Note 2: Permutation Feature Importance Explainer (PFI): Permutation Feature Importance is a technique used to explain classification and regression models. At a high level, the way it works is by randomly shuffling data one feature at a time for the entire dataset and calculating how much the performance metric of interest changes. The larger the change, the more important that feature is. PFI can explain the overall behavior of any underlying model but does not explain individual predictions.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-machine-learning-interpretability
NEW QUESTION # 195
You use Azure Machine Learning to train and register a model.
You must deploy the model into production as a real-time web service to an inference cluster named service-compute that the IT department has created in the Azure Machine Learning workspace.
Client applications consuming the deployed web service must be authenticated based on their Azure Active Directory service principal.
You need to write a script that uses the Azure Machine Learning SDK to deploy the model. The necessary modules have been imported.
How should you complete the code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.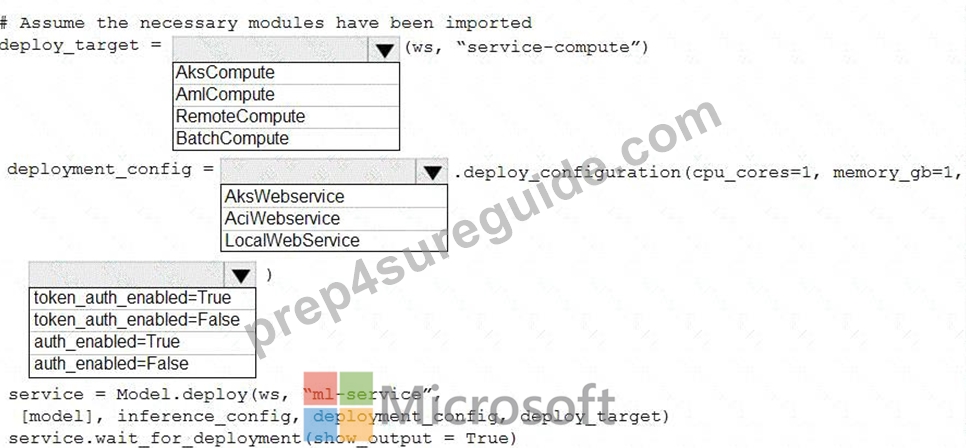
Answer:
Explanation: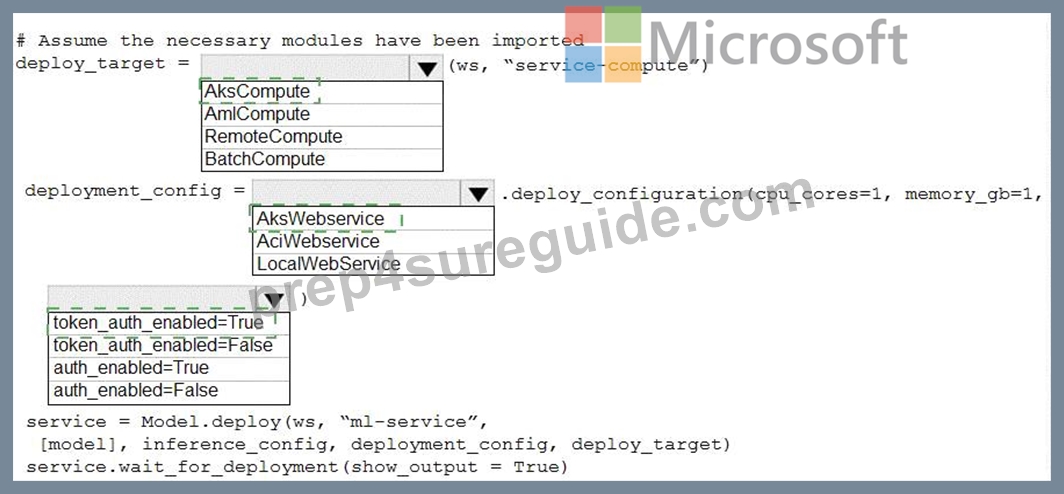
Explanation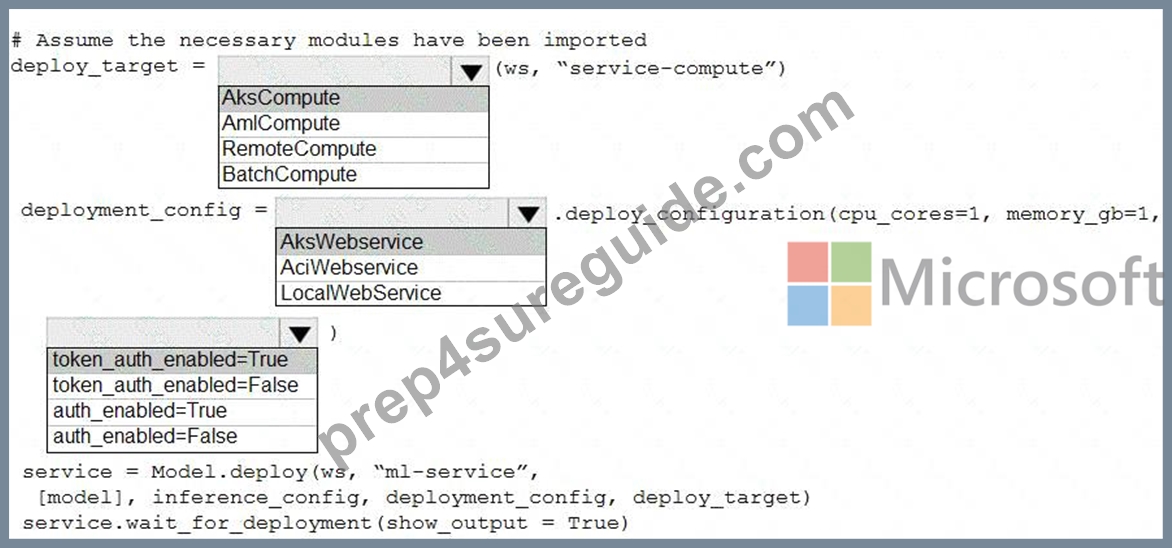
Box 1: AksCompute
Example:
aks_target = AksCompute(ws,"myaks")
# If deploying to a cluster configured for dev/test, ensure that it was created with enough
# cores and memory to handle this deployment configuration. Note that memory is also used by
# things such as dependencies and AML components.
deployment_config = AksWebservice.deploy_configuration(cpu_cores = 1, memory_gb = 1) service = Model.deploy(ws, "myservice", [model], inference_config, deployment_config, aks_target) Box 2: AksWebservice Box 3: token_auth_enabled=Yes Whether or not token auth is enabled for the Webservice.
Note: A Service principal defined in Azure Active Directory (Azure AD) can act as a principal on which authentication and authorization policies can be enforced in Azure Databricks.
The Azure Active Directory Authentication Library (ADAL) can be used to programmatically get an Azure AD access token for a user.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-deploy-azure-kubernetes-service
https://docs.microsoft.com/en-us/azure/databricks/dev-tools/api/latest/aad/service-prin-aad-token
NEW QUESTION # 196
You need to define a process for penalty event detection.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.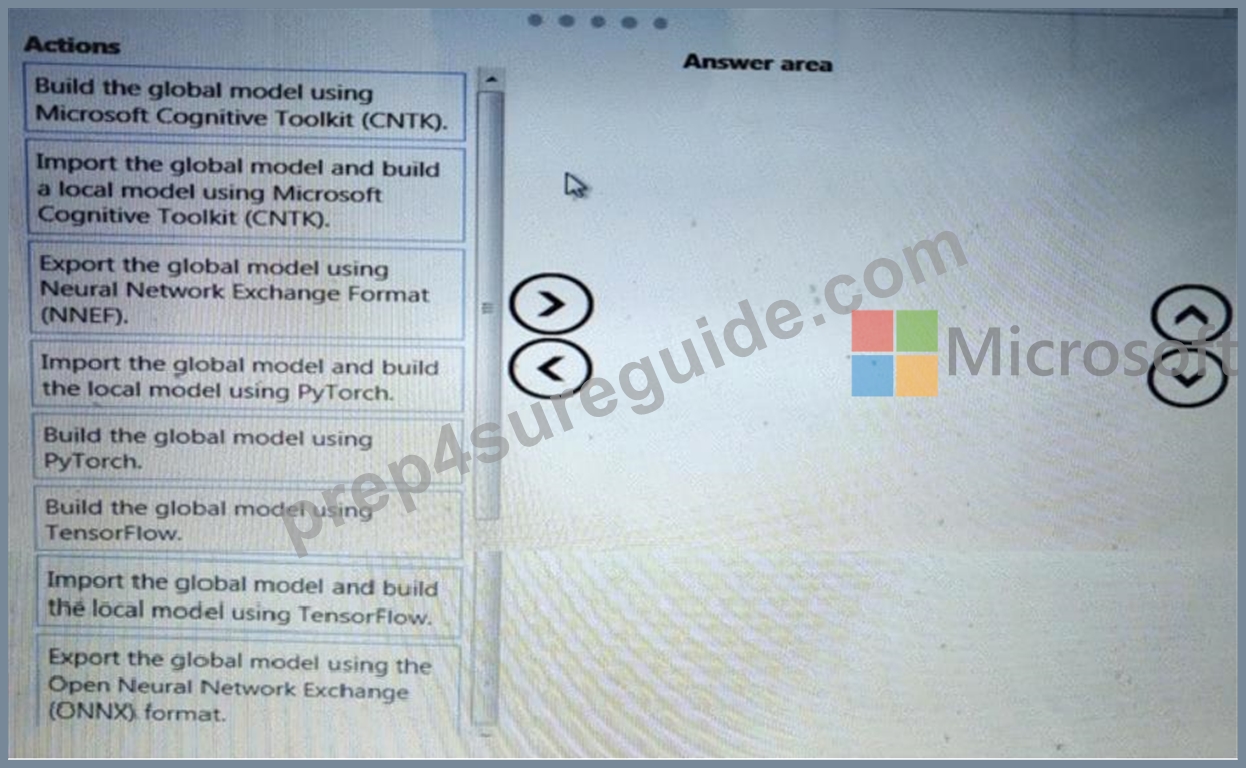
Answer:
Explanation: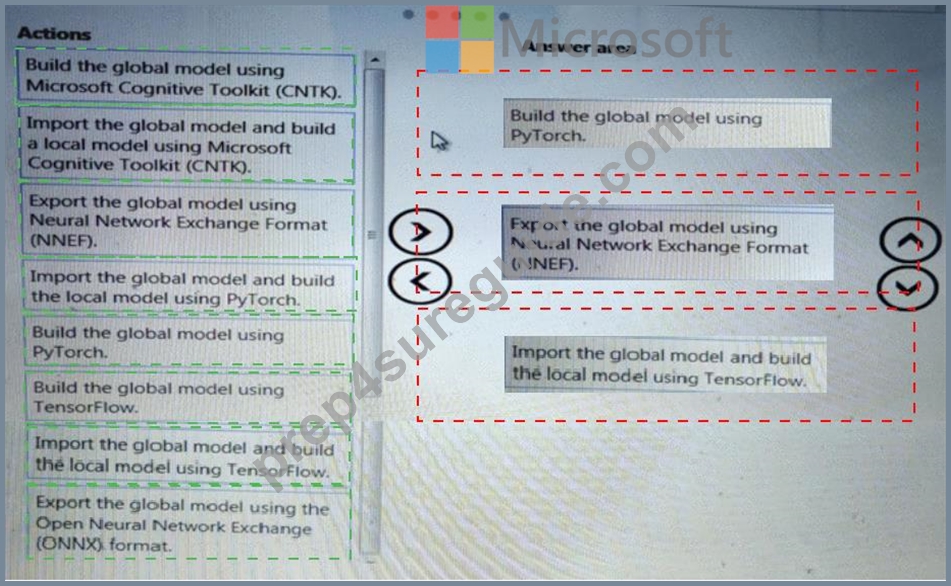
NEW QUESTION # 197
You create an Azure Machine Learning compute target named ComputeOne by using the STANDARD_D1 virtual machine image.
You define a Python variable named was that references the Azure Machine Learning workspace. You run the following Python code: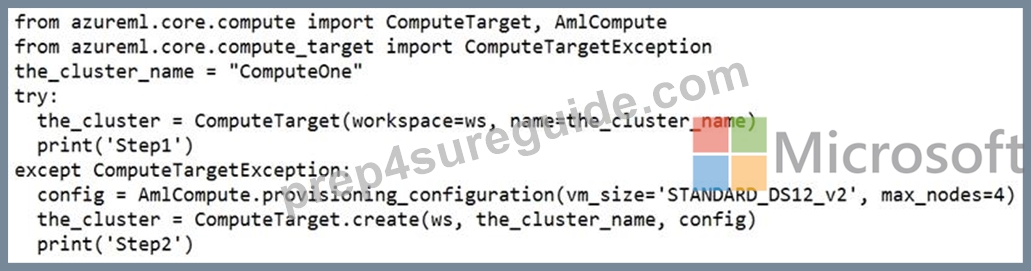
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.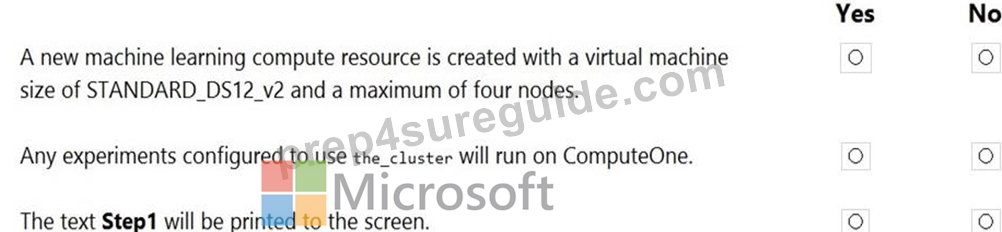
Answer:
Explanation: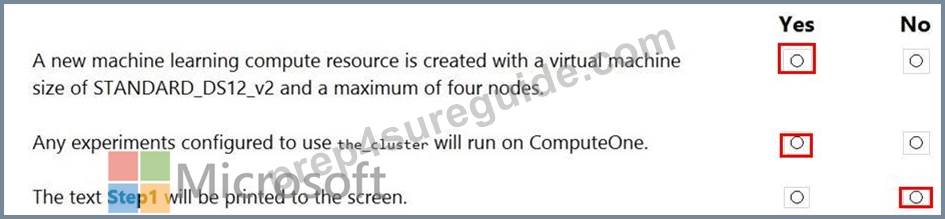
Reference:
https://docs.microsoft.com/en-us/python/api/azureml-core/azureml.core.compute.computetarget
NEW QUESTION # 198
You need to use the Python language to build a sampling strategy for the global penalty detection models.
How should you complete the code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.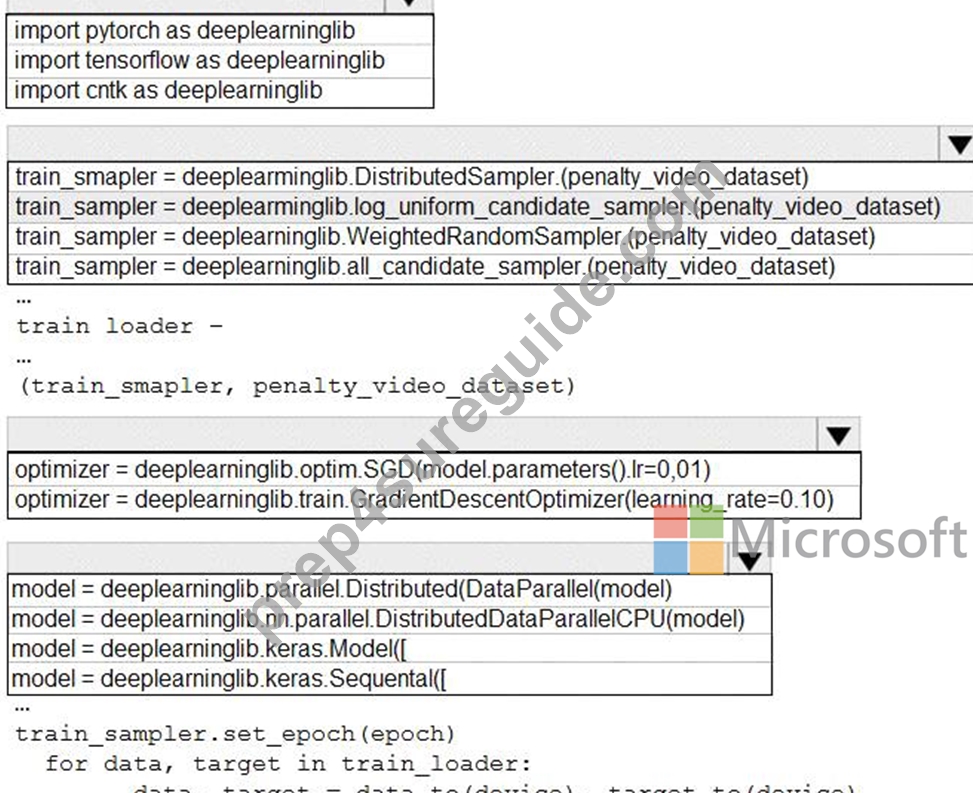
Answer:
Explanation: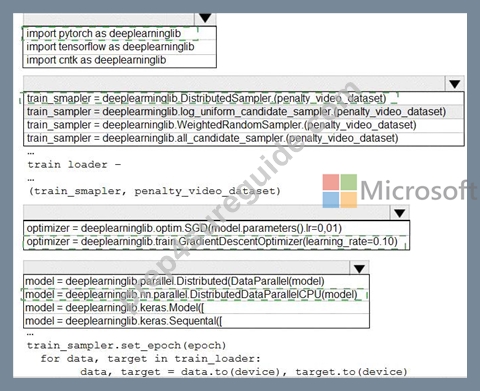
Explanation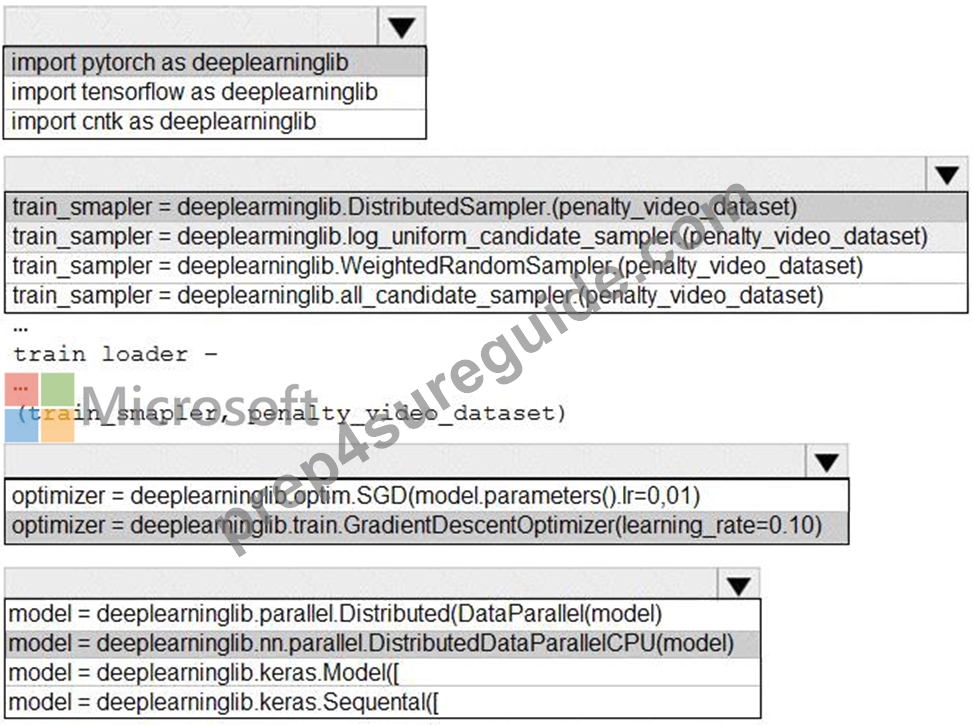
Box 1: import pytorch as deeplearninglib
Box 2: ..DistributedSampler(Sampler)..
DistributedSampler(Sampler):
Sampler that restricts data loading to a subset of the dataset.
It is especially useful in conjunction with class:`torch.nn.parallel.DistributedDataParallel`. In such case, each process can pass a DistributedSampler instance as a DataLoader sampler, and load a subset of the original dataset that is exclusive to it.
Scenario: Sampling must guarantee mutual and collective exclusively between local and global segmentation models that share the same features.
Box 3: optimizer = deeplearninglib.train. GradientDescentOptimizer(learning_rate=0.10)
NEW QUESTION # 199
......
The DP-100 training materials provide you with free demo, and you can have a try in our website. If you are satisfied with the free demo, you just need to add them to your shopping cart, and pay for it, please check the email address carefully, due to we will send the DP-100 Exam Dumps to you by email. Besides, we support online payment with credit card, and the payment tools will change the currency of your country, and there is no necessary for you to exchange by yourself.
Top DP-100 Questions: https://www.prep4sureguide.com/DP-100-prep4sure-exam-guide.html
What's more, part of that Prep4sureGuide DP-100 dumps now are free: https://drive.google.com/open?id=133W67LwSkSA40qucMF2DDTnoJddNlr5y