BONUS!!! Fast2test CT-AIダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1FG6hb4FLQKY-GF-zYeV4tdJmURM_hZsR
現在、CT-AI認証試験に助けがある参考資料を提供するサイトがあります。我々は過去の試験のデータを整理し分析して、CT-AI問題集を研究することができます。我々の研究成果は100%試験に合格するのを保証することができます。我々Fast2testの支援で、あなたはCT-AI試験に合格することだけでなく、時間とお金を節約することができます。
| Certification Vendor: | ISTQB |
|---|---|
| Exam Name: | ISTQB Certified Tester - AI Testing Exam |
| Exam Number: | CT-AI |
| Available Languages: | Korean, Portuguese, Chinese, Japanese, English, German, French, Spanish |
| Exam Price: | €180 - €250 (varies by region and provider) |
| Passing Score: | 65% (29/44 points for v2.0; 31/47 points for v1.0) |
| Related Certifications: | ISTQB Certified Tester Foundation Level (CTFL) ISTQB Certified Tester Testing with Generative AI (CT-GenAI) |
| Exam Duration: | 60 (75 for non-native language) |
| Real Exam Qty: | 40 |
| Exam Format: | Multiple-choice questions, 1-2 points per question |
| Certificate Validity Period: | Valid indefinitely (no expiration) |
| Recommended Training: | CT-AI Syllabus v2.0 ISTQB Accredited Training Providers |
| Exam Registration: | iSQI Exam Registration ISTQB Official Registration Pearson VUE |
| Sample Questions: | ISTQB CT-AI Sample Questions |
| Exam Way: | Online remote proctored / Onsite test center |
| Pre Condition: | Must hold ISTQB Certified Tester Foundation Level (CTFL) certification |
| Official Syllabus URL: | https://istqb.org/certifications/certified-tester-ai-testing-ct-ai/ |
CT-AI実践教材は、すべての点で同様の製品よりも優れていると自信を持って伝えることができます。まず、ユーザーはCT-AI試験準備を無料で試用して、CT-AIスタディガイドをよりよく理解することができます。ユーザーが製品が自分に適していないことに気付いた場合、ユーザーは別の種類の学習教材を選択できます。ユーザーの選択を尊重し、ユーザーがCT-AI実践教材を購入する必要があることを強制しません。ユーザーが適格なCT-AI試験に合格できるように、ユーザーのすべての要件を可能な限り満たすことができます。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
| トピック 4 |
|
| トピック 5 |
|
| トピック 6 |
|
| トピック 7 |
|
| トピック 8 |
|
| トピック 9 |
|
| トピック 10 |
|
| トピック 11 |
|
質問 # 34
Data used for an object detection ML system was found to have been labelled incorrectly in many cases.
Which ONE of the following options is most likely the reason for this problem?
SELECT ONE OPTION
正解:A
解説:
The question refers to a problem where data used for an object detection ML system was labelled incorrectly. This issue is most closely related to "accuracy issues." Here's a detailed explanation:
Accuracy Issues: The primary goal of labeling data in machine learning is to ensure that the model can accurately learn and make predictions based on the given labels. Incorrectly labeled data directly impacts the model's accuracy, leading to poor performance because the model learns incorrect patterns.
Why Not Other Options:
Security Issues: This pertains to data breaches or unauthorized access, which is not relevant to the problem of incorrect data labeling.
Privacy Issues: This concerns the protection of personal data and is not related to the accuracy of data labeling.
Bias Issues: While bias in data can affect model performance, it specifically refers to systematic errors or prejudices in the data rather than outright incorrect labeling.
質問 # 35
Which statement regarding testing transparency, explainability, or interpretability is MOST correct?
Choose ONE option (1 out of 4)
正解:D
解説:
The ISTQB CT-AI syllabus states in Section2.10 - Explainability, Transparency, and Interpretabilitythat interpretability isuser-dependent, meaning different users understand explanations differently. This is because interpretability depends not only on the ML algorithm but also on the user's domain knowledge, experience, and expectations. OptionBdirectly reflects this syllabus principle: interpretability testing must consideruser background, and explanations must be comprehensible to the intended user group.
Option A is incorrect because explainability testing requires substantial information about the model, data, and expected behavior-not just exploratory effort. Option C is incorrect because explainability isnot generally quantifiable through dynamic testing alone, and the syllabus does not assert model-type specificity in this way. Option D exaggerates LIME's capabilities. LIME offers approximate local explanations, but cannotpreciselystate root causes; the syllabus emphasizes itslimitationsand that explanations are approximations, not exact reasons.
Therefore,Option Bis the most syllabus-aligned and correct statement.
質問 # 36
"AllerEgo" is a product that uses sell-learning to predict the behavior of a pilot under combat situation for a variety of terrains and enemy aircraft formations. Post training the model was exposed to the real- world data and the model was found to be behaving poorly. A lot of data quality tests had been performed on the data to bring it into a shape fit for training and testing.
Which ONE of the following options is least likely to describes the possible reason for the fall in the performance, especially when considering the self-learning nature of the Al system?
SELECT ONE OPTION
* The difficulty of defining criteria for improvement before the model can be accepted.
* The fast pace of change did not allow sufficient time for testing.
* The unknown nature and insufficient specification of the operating environment might have caused the poor performance.
* There was an algorithmic bias in the Al system.
正解:
解説:
* A. The difficulty of defining criteria for improvement before the model can be accepted.
* Defining criteria for improvement is a challenge in the acceptance of AI models, but it is not directly related to the performance drop in real-world scenarios. It relates more to the evaluation and deployment phase rather than affecting the model's real-time performance post-deployment.
* B. The fast pace of change did not allow sufficient time for testing.
* This can significantly affect the model's performance. If the system is self-learning, it needs to adapt quickly, and insufficient testing time can lead to incomplete learning and poor performance.
* C. The unknown nature and insufficient specification of the operating environment might have caused the poor performance.
* This is highly likely to affect performance. Self-learning AI systems require detailed specifications of the operating environment to adapt and learn effectively. If the environment is insufficiently specified, the model may fail to perform accurately in real-world scenarios.
* D. There was an algorithmic bias in the AI system.
* Algorithmic bias can significantly impact the performance of AI systems. If the model has biases, it will not perform well across different scenarios and data distributions.
Given the context of the self-learning nature and the need for real-time adaptability, optionAis least likely to describe the fall in performance because it deals with acceptance criteria rather than real-time performance issues.
質問 # 37
Upon testing a model used to detect rotten tomatoes, the following data was observed by the test engineer, based on certain number of tomato images.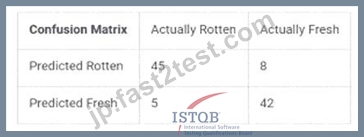
For this confusion matrix which combinations of values of accuracy, recall, and specificity respectively is CORRECT?
SELECT ONE OPTION
正解:D
解説:
To calculate the accuracy, recall, and specificity from the confusion matrix provided, we use the following formulas:
Confusion Matrix:
Actually Rotten: 45 (True Positive), 8 (False Positive)
Actually Fresh: 5 (False Negative), 42 (True Negative)
Accuracy:
Accuracy is the proportion of true results (both true positives and true negatives) in the total population.
Formula: Accuracy=TP+TNTP+TN+FP+FN\text{Accuracy} = \frac{TP + TN}{TP + TN + FP + FN} Accuracy=TP+TN+FP+FNTP+TN Calculation: Accuracy=45+4245+42+8+5=87100=0.87\text{Accuracy} = \frac{45 + 42}{45 + 42 + 8 + 5} =
\frac{87}{100} = 0.87Accuracy=45+42+8+545+42=10087=0.87
Recall (Sensitivity):
Recall is the proportion of true positive results in the total actual positives.
Formula: Recall=TPTP+FN\text{Recall} = \frac{TP}{TP + FN}Recall=TP+FNTP Calculation: Recall=4545+5=4550=0.9\text{Recall} = \frac{45}{45 + 5} = \frac{45}{50} = 0.9 Recall=45+545=5045=0.9 Specificity:
Specificity is the proportion of true negative results in the total actual negatives.
Formula: Specificity=TNTN+FP\text{Specificity} = \frac{TN}{TN + FP}Specificity=TN+FPTN Calculation: Specificity=4242+8=4250=0.84\text{Specificity} = \frac{42}{42 + 8} = \frac{42}{50} = 0.84 Specificity=42+842=5042=0.84 Therefore, the correct combinations of accuracy, recall, and specificity are 0.87, 0.9, and 0.84 respectively.
References:
ISTQB CT-AI Syllabus, Section 5.1, Confusion Matrix, provides detailed formulas and explanations for calculating various metrics including accuracy, recall, and specificity.
"ML Functional Performance Metrics" (ISTQB CT-AI Syllabus, Section 5).
質問 # 38
Which ONE of the following statements provides the BEST description of the AI effect?
正解:B
解説:
The correct answer is C because it directly describes the AI effect , where systems once classified as artificial intelligence cease to be regarded as AI after the technology becomes familiar, understood, or superseded. The CT-AI syllabus states that the changing perception of what constitutes AI is known as the "AI Effect," and explains that computer chess systems, including Deep Blue's victory over Garry Kasparov, were formerly viewed as AI but are no longer considered by many to be "true" AI because they used a brute-force approach rather than learning from data or self-learning. Appendix B reinforces this by defining the AI effect as the situation where a previously labelled AI system is no longer considered AI as technology advances.
Option A refers to technological singularity , which belongs to the distinction between general AI and super AI, not the AI effect. Option B describes adaptive or machine-learning behaviour, not a shift in social perception. Option D describes human-like behaviour, which is related to AI capability but not to reclassification over time.
References/topics: CT-AI Syllabus Chapter 1, Section 1.1 "Definition of AI and AI Effect"; Appendix B
"AI effect."
質問 # 39
......
CT-AI問題集無料: https://jp.fast2test.com/CT-AI-premium-file.html
無料でクラウドストレージから最新のFast2test CT-AI PDFダンプをダウンロードする:https://drive.google.com/open?id=1FG6hb4FLQKY-GF-zYeV4tdJmURM_hZsR