P.S. Free & New Professional-Machine-Learning-Engineer dumps are available on Google Drive shared by Dumpcollection: https://drive.google.com/open?id=1mzhSUdOAWvzNCM9EQMPbKJj91oICdmTk
You can conveniently test your performance by checking your score each time you use our Google Professional-Machine-Learning-Engineer practice exam software (desktop and web-based). It is heartening to announce that all Dumpcollection users will be allowed to capitalize on a free Google Professional-Machine-Learning-Engineer Exam Questions demo of all three formats of Google Professional-Machine-Learning-Engineer practice test.
| Certification Vendor: | Google Cloud |
|---|---|
| Exam Name: | Google Cloud Professional Machine Learning Engineer Certification Exam |
| Exam Number: | Professional-Machine-Learning-Engineer |
| Exam Price: | $200 USD (plus tax where applicable) |
| Available Languages: | English, Japanese |
| Certificate Validity Period: | 2 years |
| Related Certifications: | Google Cloud Professional Data Engineer Google Cloud Professional Cloud Architect |
| Exam Format: | Multiple choice, Multiple select |
| Passing Score: | Not officially published, approximately 70% |
| Exam Duration: | 120 minutes |
| Real Exam Qty: | 50-60 |
| Recommended Training: | Official Exam Guide Google Cloud Skills Boost - Professional Machine Learning Engineer Learning Path |
| Exam Registration: | Google Cloud Certification Registration |
| Sample Questions: | Google Professional-Machine-Learning-Engineer Sample Questions |
| Exam Way: | Online-proctored remote exam or onsite-proctored exam at authorized test centers |
| Pre Condition: | No mandatory prerequisites; recommended 3+ years industry experience including 1+ year designing/managing Google Cloud solutions |
| Official Syllabus URL: | https://cloud.google.com/learn/certification/machine-learning-engineer |
>> Google Professional-Machine-Learning-Engineer Download Free Dumps <<
Have similar features to the desktop-based exam simulator contains actual Google Professional-Machine-Learning-Engineer Practice Test that will help you grasp every topic Compatible with every operating system such as Mac, Linus, iOS, Windows, and Android Works properly on Google chrome, Internet explorer, Microsoft Edge, Opera, etc. Does not require any special plugins to operate creates an exam atmosphere making candidates more confident. Keep track of your progress with self-analysis Points out mistakes at the end of every attempt.
Google Professional Machine Learning Engineer Certification Exam is a challenging and rewarding test that requires a deep understanding of machine learning principles and their practical application. Professional-Machine-Learning-Engineer Exam is designed to test the candidate's ability to design, implement, and deploy machine learning models using Google Cloud Platform. It covers a broad range of topics, including data preprocessing, model training, hyperparameter tuning, and model evaluation.
Individuals who pass the Google Professional Machine Learning Engineer Certification Exam will receive a certificate that validates their expertise in the field of machine learning. The certificate is recognized by Google Cloud Platform and is a valuable asset for individuals who are seeking career advancement opportunities in the field of machine learning. Google Professional Machine Learning Engineer certification exam is a challenging but rewarding experience that can help individuals take their career to the next level.
NEW QUESTION # 193
You are pre-training a large language model on Google Cloud. This model includes custom TensorFlow operations in the training loop Model training will use a large batch size, and you expect training to take several weeks You need to configure a training architecture that minimizes both training time and compute costs What should you do?



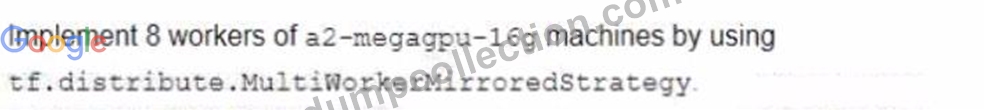
Answer: C
NEW QUESTION # 194
A company's Machine Learning Specialist needs to improve the training speed of a time-series forecasting model using TensorFlow. The training is currently implemented on a single-GPU machine and takes approximately 23 hours to complete. The training needs to be run daily.
The model accuracy is acceptable, but the company anticipates a continuous increase in the size of the training data and a need to update the model on an hourly, rather than a daily, basis. The company also wants to minimize coding effort and infrastructure changes.
What should the Machine Learning Specialist do to the training solution to allow it to scale for future demand?
Answer: D
NEW QUESTION # 195
You are building a predictive maintenance model to preemptively detect part defects in bridges. You plan to use high definition images of the bridges as model inputs. You need to explain the output of the model to the relevant stakeholders so they can take appropriate action. How should you build the model?
Answer: D
Explanation:
According to the official exam guide1, one of the skills assessed in the exam is to "explain the predictions of a trained model". TensorFlow2 is an open source framework for developing and deploying machine learning and deep learning models. TensorFlow supports various model explainability methods, such as Integrated Gradients3, which is a technique that assigns an importance score to each input feature by approximating the integral of the gradients along the path from a baseline input to the actual input. Integrated Gradients can help explain the output of a deep learning-based model by highlighting the most influential features in the input images. Therefore, option C is the best way to build the model for the given use case. The other options are not relevant or optimal for this scenario. Reference:
Professional ML Engineer Exam Guide
TensorFlow
Integrated Gradients
Google Professional Machine Learning Certification Exam 2023
Latest Google Professional Machine Learning Engineer Actual Free Exam Questions
NEW QUESTION # 196
Your organization wants to make its internal shuttle service route more efficient. The shuttles currently stop at all pick-up points across the city every 30 minutes between 7 am and 10 am. The development team has already built an application on Google Kubernetes Engine that requires users to confirm their presence and shuttle station one day in advance. What approach should you take?
Answer: A
NEW QUESTION # 197
You work for the AI team of an automobile company, and you are developing a visual defect detection model using TensorFlow and Keras. To improve your model performance, you want to incorporate some image augmentation functions such as translation, cropping, and contrast tweaking. You randomly apply these functions to each training batch. You want to optimize your data processing pipeline for run time and compute resources utilization. What should you do?
Answer: B
Explanation:
The best option for optimizing the data processing pipeline for run time and compute resources utilization is to embed the augmentation functions dynamically in the tf.Data pipeline. This option has the following advantages:
It allows the data augmentation to be performed on the fly, without creating or storing additional copies of the data. This saves storage space and reduces the data transfer time.
It leverages the parallelism and performance of the tf.Data API, which can efficiently apply the augmentation functions to multiple batches of data in parallel, using multiple CPU cores or GPU devices. The tf.Data API also supports various optimization techniques, such as caching, prefetching, and autotuning, to improve the data processing speed and reduce the latency.
It integrates seamlessly with the TensorFlow and Keras models, which can consume the tf.Data datasets as inputs for training and evaluation. The tf.Data API also supports various data formats, such as images, text, audio, and video, and various data sources, such as files, databases, and web services.
The other options are less optimal for the following reasons:
Option B: Embedding the augmentation functions dynamically as part of Keras generators introduces some limitations and overhead. Keras generators are Python generators that yield batches of data for training or evaluation. However, Keras generators are not compatible with the tf.distribute API, which is used to distribute the training across multiple devices or machines. Moreover, Keras generators are not as efficient or scalable as the tf.Data API, as they run on a single Python thread and do not support parallelism or optimization techniques.
Option C: Using Dataflow to create all possible augmentations, and store them as TFRecords introduces additional complexity and cost. Dataflow is a fully managed service that runs Apache Beam pipelines for data processing and transformation. However, using Dataflow to create all possible augmentations requires generating and storing a large number of augmented images, which can consume a lot of storage space and incur storage and network costs. Moreover, using Dataflow to create the augmentations requires writing and deploying a separate Dataflow pipeline, which can be tedious and time-consuming.
Option D: Using Dataflow to create the augmentations dynamically per training run, and stage them as TFRecords introduces additional complexity and latency. Dataflow is a fully managed service that runs Apache Beam pipelines for data processing and transformation. However, using Dataflow to create the augmentations dynamically per training run requires running a Dataflow pipeline every time the model is trained, which can introduce latency and delay the training process. Moreover, using Dataflow to create the augmentations requires writing and deploying a separate Dataflow pipeline, which can be tedious and time-consuming.
Reference:
[tf.data: Build TensorFlow input pipelines]
[Image augmentation | TensorFlow Core]
[Dataflow documentation]
NEW QUESTION # 198
......
Real Professional-Machine-Learning-Engineer Testing Environment: https://www.dumpcollection.com/Professional-Machine-Learning-Engineer_braindumps.html
BTW, DOWNLOAD part of Dumpcollection Professional-Machine-Learning-Engineer dumps from Cloud Storage: https://drive.google.com/open?id=1mzhSUdOAWvzNCM9EQMPbKJj91oICdmTk