Actual4Labs offers a free demo of Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) exam dumps before the purchase to test the features of the products. Actual4Labs also offers 1 year of free Databricks-Certified-Professional-Data-Engineer exam questions updates if the Databricks-Certified-Professional-Data-Engineer certification exam content changes after purchasing our Databricks-Certified-Professional-Data-Engineer Exam Dumps. It is possible to adjust the Databricks-Certified-Professional-Data-Engineer practice test difficulty levels according to your needs. You can choose the number of Databricks Databricks-Certified-Professional-Data-Engineer questions and topics.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Modelling | 6% | - Delta Lake table design - Schema design and management - Medallion Architecture implementation |
| Topic 2: Monitoring and Alerting | 10% | - Setting up alerts and notifications - Pipeline observability and logging - Performance and health monitoring |
| Topic 3: Cost & Performance Optimisation | 13% | - Cluster configuration and scaling - Query optimization and caching - Storage optimization (partitioning, Z-order, indexing) |
| Topic 4: Data Ingestion & Acquisition | 7% | - Schema inference and evolution - Connecting to diverse data sources - Auto Loader and streaming ingestion |
| Topic 5: Data Governance | 7% | - Unity Catalog management - Data lineage and metadata tracking - Policy enforcement |
| Topic 6: Data Sharing and Federation | 5% | - Unity Catalog data sharing - Cross-workspace and cross-cloud access |
| Topic 7: Data Transformation, Cleansing, and Quality | 10% | - Data validation and quality checks - Standardization and normalization - Handling missing or inconsistent data |
| Topic 8: Debugging and Deploying | 10% | - Troubleshooting pipelines and errors - CI/CD and DevOps practices - Deployment using bundles, CLI, and APIs |
| Topic 9: Developing Code for Data Processing using Python and SQL | 22% | - Batch and incremental processing logic - Integration with Databricks APIs and tools - Data transformation and aggregation |
| Topic 10: Ensuring Data Security and Compliance | 10% | - Data encryption and masking - Access control and permissions - Compliance standards implementation |
>> Databricks-Certified-Professional-Data-Engineer Reliable Test Blueprint <<
The modern Databricks world is changing its dynamics at a fast pace. To stay and compete in this challenging market, you have to learn and enhance your in-demand skills. Fortunately, with the Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) certification exam you can do this job nicely and quickly. To do this you just need to enroll in the Databricks-Certified-Professional-Data-Engineer certification exam and put all your efforts to pass the Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) certification exam. After successful competition of the Databricks Databricks-Certified-Professional-Data-Engineer certification, the certified candidates can put their career on the right track and achieve their professional career objectives in a short time period.
NEW QUESTION # 121
The data engineering team maintains a table of aggregate statistics through batch nightly updates. This includes total sales for the previous day alongside totals and averages for a variety of time periods including the 7 previous days, year-to-date, and quarter-to-date. This table is named store_saies_summary and the schema is as follows:
The table daily_store_sales contains all the information needed to update store_sales_summary. The schema for this table is:
store_id INT, sales_date DATE, total_sales FLOAT
If daily_store_sales is implemented as a Type 1 table and the total_sales column might be adjusted after manual data auditing, which approach is the safest to generate accurate reports in the store_sales_summary table?
Answer: C
Explanation:
The daily_store_sales table contains all the information needed to update store_sales_summary. The schema of the table is:
store_id INT, sales_date DATE, total_sales FLOAT
The daily_store_sales table is implemented as a Type 1 table, which means that old values are overwritten by new values and no history is maintained. The total_sales column might be adjusted after manual data auditing, which means that the data in the table may change over time.
The safest approach to generate accurate reports in the store_sales_summary table is to use Structured Streaming to subscribe to the change data feed for daily_store_sales and apply changes to the aggregates in the store_sales_summary table with each update. Structured Streaming is a scalable and fault-tolerant stream processing engine built on Spark SQL. Structured Streaming allows processing data streams as if they were tables or DataFrames, using familiar operations such as select, filter, groupBy, or join. Structured Streaming also supports output modes that specify how to write the results of a streaming query to a sink, such as append, update, or complete. Structured Streaming can handle both streaming and batch data sources in a unified manner.
The change data feed is a feature of Delta Lake that provides structured streaming sources that can subscribe to changes made to a Delta Lake table. The change data feed captures both data changes and schema changes as ordered events that can be processed by downstream applications or services. The change data feed can be configured with different options, such as starting from a specific version or timestamp, filtering by operation type or partition values, or excluding no-op changes.
By using Structured Streaming to subscribe to the change data feed for daily_store_sales, one can capture and process any changes made to the total_sales column due to manual data auditing. By applying these changes to the aggregates in the store_sales_summary table with each update, one can ensure that the reports are always consistent and accurate with the latest data. Verified Reference: [Databricks Certified Data Engineer Professional], under "Spark Core" section; Databricks Documentation, under "Structured Streaming" section; Databricks Documentation, under "Delta Change Data Feed" section.
NEW QUESTION # 122
A task orchestrator has been configured to run two hourly tasks. First, an outside system writes Parquet data to a directory mounted at /mnt/raw_orders/. After this data is written, a Databricks job containing the following code is executed:
(spark.readStream
.format("parquet")
.load("/mnt/raw_orders/")
.withWatermark("time", "2 hours")
.dropDuplicates(["customer_id", "order_id"])
.writeStream
.trigger(once=True)
.table("orders")
)
Assume that the fields customer_id and order_id serve as a composite key to uniquely identify each order, and that the time field indicates when the record was queued in the source system. If the upstream system is known to occasionally enqueue duplicate entries for a single order hours apart, which statement is correct?
Answer: D
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
Exact extract: "dropDuplicates with watermark performs stateful deduplication on the keys within the watermark delay." Exact extract: "Records older than the event-time watermark are considered late and may be dropped." Exact extract: "trigger(once) processes all available data once and then stops." The watermark of 2 hours bounds the deduplication state. Duplicate orders within the 2-hour window are removed; duplicates arriving later than 2 hours behind the corresponding first event are considered late and are ignored, so they won't appear, but any orders that themselves arrive later than the watermark will be dropped and thus be missing.
Reference:
NEW QUESTION # 123
You are looking to process the data based on two variables, one to check if the department is supply chain and second to check if process flag is set to True
Answer: E
NEW QUESTION # 124
The following code has been migrated to a Databricks notebook from a legacy workload: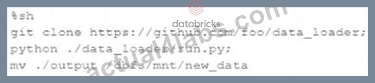
The code executes successfully and provides the logically correct results, however, it takes over 20 minutes to extract and load around 1 GB of data.
Which statement is a possible explanation for this behavior?
Answer: A
Explanation:
https://www.databricks.com/blog/2020/08/31/introducing-the-databricks-web-terminal.html The code is using %sh to execute shell code on the driver node. This means that the code is not taking advantage of the worker nodes or Databricks optimized Spark. This is why the code is taking longer to execute. A better approach would be to use Databricks libraries and APIs to read and write data from Git and DBFS, and to leverage the parallelism and performance of Spark. For example, you can use the Databricks Connect feature to run your Python code on a remote Databricks cluster, or you can use the Spark Git Connector to read data from Git repositories as Spark DataFrames.
NEW QUESTION # 125
An upstream system is emitting change data capture (CDC) logs that are being written to a cloud object storage directory. Each record in the log indicates the change type (insert, update, or delete) and the values for each field after the change. The source table has a primary key identified by the fieldpk_id.
For auditing purposes, the data governance team wishes to maintain a full record of all values that have ever been valid in the source system. For analytical purposes, only the most recent value for each record needs to be recorded. The Databricks job to ingest these records occurs once per hour, but each individual record may have changed multiple times over the course of an hour.
Which solution meets these requirements?
Answer: E
Explanation:
Explanation
This is the correct answer because it meets the requirements of maintaining a full record of all values that have ever been valid in the source system and recreating the current table state with only the most recent value for each record. The code ingests all log information into a bronze table, which preserves the raw CDC data as it is. Then, it uses merge into to perform an upsert operation on a silver table, which means it will insert new records or update or delete existing records based on the change type and the pk_id columns. This way, the silver table will alwaysreflect the current state of the source table, while the bronze table will keep the history of all changes. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Upsert into a table using merge" section.
NEW QUESTION # 126
......
During the learning process on our Databricks-Certified-Professional-Data-Engineer study materials, you can contact us anytime if you encounter any problems. The staff of Databricks-Certified-Professional-Data-Engineer actual exam will be online 24 hours, hoping to solve the problem in time for you. You can contact our services via email or online, as long as you leave your message, our services will give you suggestions right away. And even you have problem when you already bought our Databricks-Certified-Professional-Data-Engineer learning guide, we will still help you solve it.
Reliable Databricks-Certified-Professional-Data-Engineer Exam Braindumps: https://www.actual4labs.com/Databricks/Databricks-Certified-Professional-Data-Engineer-actual-exam-dumps.html