BONUS!!! Download part of Exam4Tests AI-300 dumps for free: https://drive.google.com/open?id=10n-CN4Juqxr7WDBwfpGj_QQaW63P997f
It is known to us that our AI-300 study materials have been keeping a high pass rate all the time. There is no doubt that it must be due to the high quality of our study materials. It is a matter of common sense that pass rate is the most important standard to testify the AI-300 Study Materials. The high pass rate of our study materials means that our products are very effective and useful for all people to pass their exam and get the related certification.
| Section | Objectives |
|---|---|
| Implement generative AI quality assurance and observability | - Conduct red teaming, adversarial testing, and content filtering - Implement logging, tracing, and telemetry for GenAI applications - Monitor latency, token usage, cost, and error rates - Evaluate generative AI outputs for quality, safety, and grounding |
| Optimize generative AI systems and model performance | - Implement cost management and scaling strategies for GenAI workloads - Tune prompts, system messages, and grounding strategies - Optimize inference performance, caching, and throughput - Fine-tune and distill models for specific use cases |
| Design and implement a GenAIOps infrastructure | - Implement RAG (Retrieval-Augmented Generation) pipelines and vector search - Configure prompt orchestration, prompt flows, and agent frameworks - Set up Microsoft Foundry and Azure AI services for generative AI workloads - Manage API keys, rate limits, and responsible AI guardrails |
| Implement machine learning model lifecycle and operations | - Monitor model performance, data drift, and operational health - Deploy models to real-time and batch endpoints - Retrain, update, and manage model versions in production - Train, register, and version models using Azure Machine Learning |
| Design and implement an MLOps infrastructure | - Set up Azure Machine Learning workspace and compute targets - Implement security, governance, and compliance for MLOps - Manage environments, data stores, and model registries - Configure source control, CI/CD pipelines, and automation for ML workflows |
>> Accurate AI-300 Prep Material <<
The Microsoft AI-300 online practice test engine that comes with the Operationalizing Machine Learning and Generative AI Solutions (AI-300) exam questions from Exam4Tests assists you in simulating the real Operationalizing Machine Learning and Generative AI Solutions (AI-300) exams. This is excellent for familiarizing yourself with the Operationalizing Machine Learning and Generative AI Solutions and learning what to anticipate on test day. You can also use the Microsoft Practice Test (Links to an external site.) engine to monitor your progress and review your answers to see where you need to improve for the Operationalizing Machine Learning and Generative AI Solutions (AI-300) exam.
NEW QUESTION # 117
Hotspot Question
You download a .csv file from a notebook in an Azure Machine Learning workspace to a data/sample.csv folder on a compute instance. The file contains 10,000 records.
You must generate the summary statistics for the data in the file. The statistics must include the following for each numerical column:
- number of non-empty values
- average value
- standard deviation
- minimum and maximum values
- 25th, 50th, and 75th percentiles
You need to complete the Python code that will generate the summary statistics.
Which code segments should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Box 1: pandas
Pandas read_csv() - How to read a csv file in Python
Most of the data is available in a tabular format of CSV files. It is very popular. You can convert them to a pandas DataFrame using the read_csv function. The pandas.read_csv is used to load a CSV file as a pandas dataframe.
Step 1: pandas
import pandas as pd
Step 2: Read the CSV
# Read the csv file
df = pd.read_csv("data1.csv")
Box 2: describe
The pandas.describe function is used to get a descriptive statistics summary of a given dataframe. This includes mean, count, std deviation, percentiles, and min-max values of all the features.
Pandas Describe function on DataFrame
On applying pandas describe function to a dataframe, the result is also returned as a dataframe .
This dataframe will consist of a statistics summary for all the numeric features of the dataframe.
# Create a dataframe
df = pd.DataFrame({
'Subject_1_Marks': [14, 42, 21, 12, 45],
'Subject_2_Marks': [32, 43, 23, 50, 21],
'Subject_3_Marks': [45.0, 34.0, 23.0, 8.0, 21.0],
'Names': ['Saksham', 'Ayushi', 'Abhishek', 'Saksham', 'Saumya']
}
)
# Apply describe function
df.describe()
Incorrect:
* rank
Reference:
https://www.machinelearningplus.com/pandas/pandas-read_csv-completed/
https://www.machinelearningplus.com/pandas/pandas-describe/
NEW QUESTION # 118
You are reviewing a dataset that will be used for an advanced fine-tuning job in Microsoft Foundry.
The fine-tuning job uses preference comparison data.
You review the following dataset excerpt.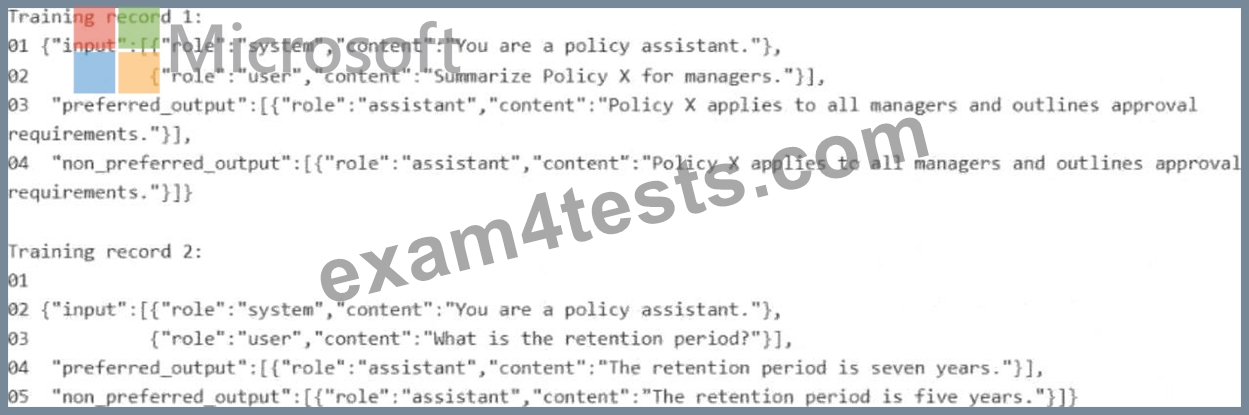
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Preference comparison data with chosen versus rejected response pairs is the input format for Direct Preference Optimization (DPO) or RLHF-style fine-tuning - an advanced fine-tuning technique available in Microsoft Foundry. A valid DPO dataset record must have three fields: a prompt as the input, a chosen field containing the preferred response, and a rejected field containing the less preferred response. The file must be in JSONL format with UTF-8 encoding, where each line represents one complete preference pair. When evaluating statements about this dataset, mark True if the dataset contains all three required fields and chosen responses represent higher-quality outputs than rejected ones. Mark False if the format is incompatible with DPO requirements, if the required rejected field is missing, or if the chosen and rejected responses appear to be of equivalent quality with no clear preference signal.
Microsoft Learn Reference Topic: Advanced fine-tuning with preference data in Microsoft Foundry - DPO dataset format
NEW QUESTION # 119
Hotspot Question
You manage an Azure Machine Learning workspace by using the Python SDK v2.
You must create an automated machine learning job to generate a classification model by using data files stored in Parquet format. You must configure an autoscaling compute target and a data asset for the job.
You need to configure the resources for the job.
Which resource configuration should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.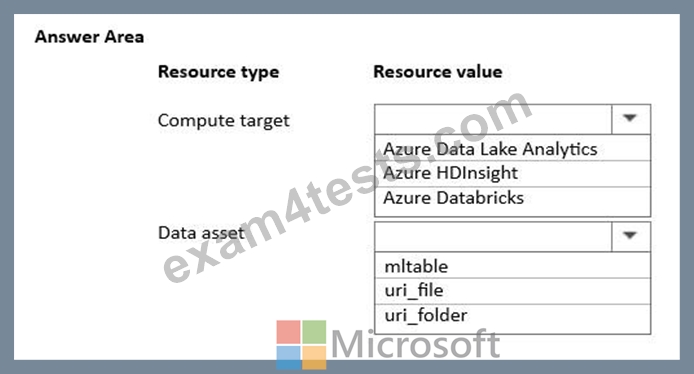
Answer:
Explanation:
Explanation:
Box 1: Azure Databricks
Autoscaling: Out of the provided choices, Azure Databricks is the only compute target that natively supports the automated scaling up and down of worker nodes required to efficiently match the computation demands of your specific job.
Compatibility: Azure HDInsight and Azure Data Lake Analytics are legacy analytics platforms that do not offer the same direct, optimized, and auto-scaling compute integration within Azure ML SDK v2 pipelines for AutoML training.
Box 2: uri_folder
Directory access: Since your data consists of multiple data files stored in the Parquet format, pointing your asset type to a uri_folder allows the training job to automatically read and ingest all individual Parquet partition files stored inside that directory.
Reference:
https://github.com/Azure/MachineLearningNotebooks/blob/master/how-to-use-azureml/azure-databricks/automl/automl-databricks-local-01.ipynb
NEW QUESTION # 120
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals.
You have an Azure Machine Learning workspace. You connect to a terminal session from the Notebooks page in Azure Machine Learning studio.
You plan to add a new Jupyter kernel that will be accessible from the same terminal session.
You need to perform the task that must be completed before you can add the new kernel.
Solution: Delete the Python 3.6 - AzureML kernel.
Does the solution meet the goal?
Answer: B
Explanation:
No. Removing the existing Python 3.6 - AzureML kernel is not a prerequisite for adding a new kernel. Azure Machine Learning supports multiple installed Jupyter kernels on the same compute instance, and notebooks can select among those kernels without requiring one existing kernel to be removed first. Microsoft states that the notebook environment automatically discovers all Jupyter kernels installed on the connected compute instance.
The supported new-kernel workflow begins by creating a separate environment, for example with conda create --name newenv, and activating it. The required pip and ipykernel packages are then installed in the environment before registering it with Jupyter by using python -m ipykernel install --user --name newenv.
Deleting an existing AzureML kernel provides no technical benefit to that workflow. Microsoft also explicitly cautions users not to delete Conda environments or Jupyter kernels they did not create , because doing so can interfere with built-in Jupyter/JupyterLab functionality on the compute instance.
Therefore, the existing Python 3.6 kernel should remain untouched; the new kernel should be installed alongside it in its own environment.
Study Guide Reference: Design and implement an MLOps infrastructure - Jupyter kernel management, Conda environments, Azure Machine Learning compute instances, and development environment isolation.
NEW QUESTION # 121
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
You work in Microsoft Foundry with a prompt flow.
You must manually evaluate prompts and compare results across prompt variants.
You need to capture the inputs, outputs, token usage, and latencies for each flow run for the evaluation.
Solution: Use the prompt flow SDK to enable tracing for the flow before executing runs. Then run the flow to generate traceable results.
Does the solution meet the goal?
Answer: B
Explanation:
Correct:
* In Microsoft Foundry, turn on Tracing for the prompt flow of the project and execute test runs to produce trace data.
Incorrect:
* Create prompt variants and compare their outputs in the Evaluation experience.
* Use the prompt flow SDK to enable tracing for the flow before executing runs. Then run the flow to generate traceable results.
Note:
In Azure AI Foundry, you can capture and compare these metrics by enabling Tracing and using the Bulk Test feature. This allows you to systematically evaluate different prompt variants against a common dataset.
Steps to Evaluate and Compare Prompt Variants
*-> 1. Enable Tracing
Navigate to your Prompt Flow project.
Locate the Tracing toggle at the top of the flow authoring page.
Switch it to On.
This ensures every execution captures latency, token counts, and node-level inputs/outputs.
2. Create Prompt Variants
Within your flow, identify the LLM node you want to test.
Click Variants to create multiple versions of your prompt (e.g., Variant_0, Variant_1).
This allows you to test different instructions or few-shot examples side-by-side.
3. Run a Bulk Test (Evaluation)
4. Analyze the Results
Reference:
https://www.linkedin.com/pulse/streamlining-generative-ai-development-azure-foundry-tracing- taneja-mbwze
NEW QUESTION # 122
......
You can use this Operationalizing Machine Learning and Generative AI Solutions (AI-300) practice exam software to test and enhance your Operationalizing Machine Learning and Generative AI Solutions (AI-300) exam preparation. Your practice will be made easier by having the option to customize the Microsoft in AI-300 exam dumps. Only Windows-based computers can run this Microsoft AI-300 Exam simulation software. The fact that it runs without an active internet connection is an incredible comfort for users who don't have access to the internet all the time.
Valid Dumps AI-300 Book: https://www.exam4tests.com/AI-300-valid-braindumps.html
BONUS!!! Download part of Exam4Tests AI-300 dumps for free: https://drive.google.com/open?id=10n-CN4Juqxr7WDBwfpGj_QQaW63P997f