P.S.JpshikenがGoogle Driveで共有している無料の2026 Snowflake SPS-C01ダンプ:https://drive.google.com/open?id=1S4NDvMNjaTp5_TuJc5l-QDor04O3qJap
SPS-C01スタディガイドのサポーターは、Jpshiken世界中で数万を超えており、それらの品質を直接反映しています。 試験はあなたの肩に大きな負担をかけるかもしれないので、私たちSnowflakeの練習資料は時間の経過とともにそれらの問題をあなたを和らげることができます。 定期的にSPS-C01試験シミュレーションに時間を費やしただけで、それを取得できる可能性が大幅に向上します。 ご参考までに、合格率は現在までに98%を超えています。 これまでの練習教材は3つのバージョンで構成されており、これら3つの基本タイプはすべて、好みや傾向に応じてサポーターに人気があります。 成功に向かって進む途中で、SPS-C01準備資料:Snowflake Certified SnowPro Specialty - Snowparkは常に素晴らしいサポートを提供します。
| Section | Objectives |
|---|---|
| Topic 1: Testing, Debugging, and Deployment | - Production readiness
|
| Topic 2: Data Engineering with Snowpark | - Pipeline development
|
| Topic 3: DataFrame Operations and Data Processing | - Data transformation workflows
|
| Topic 4: Performance Optimization and Best Practices | - Efficient Snowpark execution
|
| Topic 5: Snowpark Fundamentals | - Snowpark architecture and concepts
|
| Topic 6: User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
我々のSPS-C01問題集に興味がありますか?ありましたら、Jpshikenのサイトで探しましょう。我々は弊社の商品の品質を保証しています。お客様は信じられないなら、我々の無料のSPS-C01サンプルをダウンロードして体験することができます。あなたの要求を満たすなら、我々のサイトでSPS-C01問題集を購入してください。
質問 # 145
You are working with a Snowpark DataFrame 'sales_data' containing sales transactions. The DataFrame includes columns 'transaction_id' (STRING), 'product_id' (IN T), 'sale_date' (DATE), and 'sale_amount' (DOUBLE). You need to calculate the total sales amount for each product on a daily basis. Furthermore, you want to filter out any days where the total sales amount for a specific product is less than $50. Which of the following code snippets correctly achieves this using Snowpark Python?





正解:D、E
解説:
Options A and B are correct. Both first group the data by 'product_id' and 'sale_date' and calculate the sum of 'sale_amount' for each group. They then filter the results to include only those rows where 'total_sales' is greater than 50. 'filter' and 'where' are interchangable. C would be invalid snowpark as you use 'having' after group_by. Option D and E would also be valid if the prompt asked for all days with a sale amount equal to greater than $50 not greater.
質問 # 146
You've transformed a large Snowpark DataFrame and want to persist it to a Snowflake stage for downstream applications. Your requirements are: 1. The data must be written in CSV format. 2. The files must be GZIP compressed. 3. A header row should be included in each file. 4. The files should be stored in a stage named 'customer_stage' in your Snowflake database. Which of the following code snippets correctly implements this, ensuring optimal performance and resource utilization?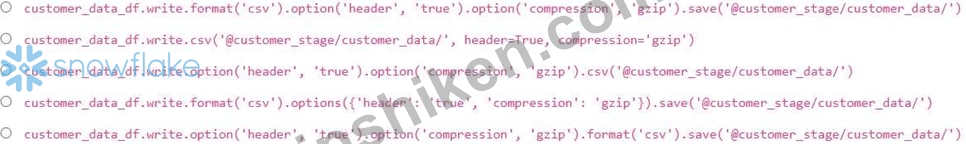
正解:C
解説:
Option B provides the most concise and readable way to achieve the desired outcome using the dedicated writer method. It directly specifies the header and compression options as parameters. Options A, D, and E require specifying the file format separately using 'format('csv')' and configuring header and compression through options, which is less direct. Option C has incorrect order - it need to set format first before setting options, so its less readable.
質問 # 147
You are developing a Snowpark application that needs to connect to Snowflake using account identifiers. Your organization's Snowflake account is configured with federated authentication (Okta). Which of the following methods is the most secure and recommended way to establish a Snowpark session in this scenario, avoiding hardcoding credentials in your application and leveraging existing authentication mechanisms?
正解:A
解説:
Using OAuth with an external identity provider like Okta is the most secure and recommended method for federated authentication. It avoids storing credentials directly in the application and leverages the organization's existing authentication mechanisms. Options A, B, and D are less secure due to the risk of exposing credentials. Option E does not address the federated authenication requirment.
質問 # 148
You are working with a Snowpark DataFrame 'df that contains user profile data'. A column named 'profile' stores user information as JSON, including 'age' (which can be a number or a string), 'is active' (which can be a boolean or a string 'true'/'false'), and registration date' (stored as a string in 'YYYY-MM-DD' format). You need to perform the following data transformations: 1. Cast the 'age' to an integer, defaulting to -1 if casting fails. 2. Cast 'is active' to a boolean, treating 'true' (case-insensitive) as true and any other string as false. 3. Convert 'registration_date' to a date object. Select the code snippets (multiple answers can be correct) that correctly accomplish these tasks using Snowpark DataFrame transformations.





正解:D、E
解説:
Options A and D are both correct. Option A : Uses lit(-l for handling age casting failures. This is good because it can handle errors and provides null safe casting. try to cast to a number, and if it fails, return null, then coalesce use -1 instead. Option A : Correctly converts to a boolean using 'when' and 'lower' for case-insensitive matching. If it's the string 'true', returns 'true'. Otherwise, returns 'false'. Option A : Uses 'to_date' for 'registration_date' since the column stores date. Option D is not supported. It should be 'is_number' for the age field. Option D : Correctly converts to a boolean using 'when' and 'lower' for case-insensitive matching. If it's the string 'true , returns 'true. Otherwise, returns 'false. Option D : Uses 'to_date' for 'registration_date' since the column stores date. Option B 'try_cast' does not exist in Snowpark. Option C 'Trye' is never equal to 'True'. Option E: The 'registration_date' needs to be converted with 'to date' and not 'to_timestamp'.
質問 # 149
A data engineer is developing a Snowpark application using Python and needs to connect to Snowflake. They want to avoid hardcoding credentials directly in the script and utilize environment variables for authentication. Which of the following approaches is the MOST secure and RECOMMENDED way to retrieve Snowflake connection parameters (account, user, password, database, schema, warehouse, role) from environment variables and establish a Snowpark session?
正解:E
解説:
Option E, 'Session.builder.getOrCreate(V , is the most concise and recommended approach. It automatically retrieves connection parameters from standard environment variables (e.g., SNOWFLAKE_USER, SNOWFLAKE_PASSWORD, SNOWFLAKE_ACCOUNT). This simplifies the code and reduces the risk of errors. Option A is verbose and prone to errors. Option B introduces unnecessary complexity and parsing. Option C involves the classic Snowflake connector, which is not the recommended way with Snowpark for Python. Option D involves snowCLl profiles and is not using Environment Variables.
質問 # 150
......
Snowflake SPS-C01試験参考書に疑問を持たれば、Snowflake会社のウエブサイトから無料でSPS-C01試験のためのデモをダウンロードできます。SPS-C01試験参考書の高品質でSPS-C01試験の受験者は弊社と長期的な協力関係を築いています。SPS-C01試験参考書はお客様の試験のために最も役に立つ商品だとも言えます。
SPS-C01リンクグローバル: https://www.jpshiken.com/SPS-C01_shiken.html
ちなみに、Jpshiken SPS-C01の一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=1S4NDvMNjaTp5_TuJc5l-QDor04O3qJap