DOWNLOAD the newest VCEPrep KCNA PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1C9GVrC7N6jCMZVN1Oa-iIOMoqZbQJDHT
The certification of Linux Foundation KCNA exam is what IT people want to get. Because it relates to their future fate. Linux Foundation KCNA exam training materials are the learning materials that each candidate must have. With this materials, the candidates will have the confidence to take the exam. Training materials in the VCEPrep are the best training materials for the candidates. With VCEPrep's Linux Foundation KCNA Exam Training materials, you will pass the exam easily.
Linux Foundation KCNA (Kubernetes and Cloud Native Associate) Exam is a certification program that assesses the knowledge and skills of IT professionals in Kubernetes and cloud native technologies. It is designed to validate the expertise of individuals who want to demonstrate their proficiency in these areas and to enhance their career opportunities in the tech industry.
The Linux Foundation KCNA certification exam also enables you to stay updated and competitive in the market which will help you to gain more career opportunities. Do you want to gain all these KCNA certification exam benefits? Looking for the quick and complete Kubernetes and Cloud Native Associate (KCNA) exam dumps preparation way that enables you to pass the Kubernetes and Cloud Native Associate in KCNA certification exam with good scores?
Linux Foundation Kubernetes and Cloud Native Associate (KCNA) exam is a certification program designed to test the skills and knowledge of individuals who are interested in working with Kubernetes and other cloud-native technologies. KCNA Exam is intended to provide a standardized measure of proficiency in these areas, which can be used by employers to evaluate potential candidates for job openings or by individuals to demonstrate their expertise to colleagues and clients.
NEW QUESTION # 130
Which tool is used to streamline installing and managing Kubernetes applications?
Answer: D
Explanation:
Helm is the Kubernetes package manager used to streamline installing and managing applications, so B is correct. Helm packages Kubernetes resources into charts, which contain templates, default values, and metadata. When you install a chart, Helm renders templates into concrete manifests and applies them to the cluster. Helm also tracks a "release," enabling upgrades, rollbacks, and consistent lifecycle operations across environments.
This is why Helm is widely used for complex applications that require multiple Kubernetes objects (Deployments/StatefulSets, Services, Ingresses, ConfigMaps, RBAC, CRDs). Rather than manually maintaining many YAML files per environment, teams can parameterize configuration with values and reuse the same chart across dev/stage/prod with different overrides.
Option A (apt) and option D (brew) are OS package managers (Debian/Ubuntu and macOS/Linuxbrew respectively), not Kubernetes application managers. Option C (service) is a Linux service manager command pattern and not relevant here.
In cloud-native delivery pipelines, Helm often integrates with GitOps and CI/CD: the pipeline builds an image, updates chart values (image tag/digest), and deploys via Helm or via GitOps controllers that render/apply Helm charts. Helm also supports chart repositories and versioning, making it easier to standardize deployments and manage dependencies.
So, the verified tool for streamlined Kubernetes app install/management is Helm (B).
NEW QUESTION # 131
How is application data maintained in containers?
Answer: A
Explanation:
Container filesystems are ephemeral: the writable layer is tied to the container lifecycle and can be lost when containers are recreated. Therefore, maintaining application data correctly means storing it in volumes, making D the correct answer. In Kubernetes, volumes provide durable or shareable storage that is mounted into containers at specific paths. Depending on the volume type, the data can persist across container restarts and even Pod rescheduling.
Kubernetes supports many volume patterns. For transient scratch data you might use emptyDir (ephemeral for the Pod's lifetime). For durable state, you typically use PersistentVolumes consumed by PersistentVolumeClaims (PVCs), backed by storage systems via CSI drivers (cloud disks, SAN/NAS, distributed storage). This decouples the application container image from its state and enables rolling updates, rescheduling, and scaling without losing data.
Options A and B ("folders") are incomplete because folders inside the container filesystem do not guarantee persistence. A folder is only as durable as the underlying storage; without a mounted volume, it lives in the container's writable layer and will disappear when the container is replaced. Option C is incorrect because "sidecar containers" are not a data durability mechanism; sidecars can help ship logs or sync data, but persistent data should still be stored on volumes (or external services like managed databases).
From an application delivery standpoint, the principle is: containers should be immutable and disposable, and state should be externalized. Volumes (and external managed services) make this possible. In Kubernetes, this is a foundational pattern enabling safe rollouts, self-healing, and portability: the platform can kill and recreate Pods freely because data is maintained independently via volumes.
Therefore, the verified correct choice is D: Store data into volumes.
NEW QUESTION # 132
Which of the following would fall under the responsibilities of an SRE?
Answer: B
Explanation:
Site Reliability Engineering (SRE) focuses on reliability, availability, performance, and operational excellence using engineering approaches. Among the options, creating a monitoring baseline for an application is a classic SRE responsibility, so B is correct. A monitoring baseline typically includes defining key service-level signals (latency, traffic, errors, saturation), establishing dashboards, setting sensible alert thresholds, and ensuring telemetry is complete enough to support incident response and capacity planning.
In Kubernetes environments, SRE work often involves ensuring that workloads expose health endpoints for probes, that resource requests/limits are set to allow stable scheduling and autoscaling, and that observability pipelines (metrics, logs, traces) are consistent. Building a monitoring baseline also ties into SLO/SLI practices: SREs define what "good" looks like, measure it continuously, and create alerts that notify teams when the system deviates from those expectations.
Option A is primarily an application developer task-SREs may contribute to reliability features, but core product feature development is usually owned by engineering teams. Option C is more aligned with finance, FinOps, or management responsibilities, though SRE data can inform costs. Option D is closer to governance, platform policy, or developer experience/process ownership; SREs might influence processes, but "policy on how to submit code change" is not the defining SRE duty compared to monitoring and reliability engineering.
Therefore, the best verified choice is B, because establishing monitoring baselines is central to operating reliable services on Kubernetes.
NEW QUESTION # 133
How long should a stable API element in Kubernetes be supported (at minimum) after deprecation?
Answer: B
Explanation:
Kubernetes has a formal API deprecation policy to balance stability for users with the ability to evolve the platform. For a stable (GA) API element, Kubernetes commits to supporting that API for a minimum period after it is deprecated. The correct minimum in this question is 12 months, which corresponds to option C.
In practice, Kubernetes releases occur roughly every three to four months, and the deprecation policy is commonly communicated in terms of "releases" as well as time. A GA API that is deprecated in one release is typically kept available for multiple subsequent releases, giving cluster operators and application teams time to migrate manifests, client libraries, controllers, and automation. This matters because Kubernetes is often at the center of production delivery pipelines; abrupt API removals would break deployments, upgrades, and tooling. By guaranteeing a minimum support window, Kubernetes enables predictable upgrades and safer lifecycle management.
This policy also encourages teams to track API versions and plan migrations. For example, workloads might start on a beta API (which can change), but once an API reaches stable, users can expect a stronger compatibility promise. Deprecation warnings help surface risk early. In many clusters, you'll see API server warnings and tooling hints when manifests use deprecated fields/versions, allowing proactive remediation before the removal release.
Options 6 or 9 months would be too short for many enterprises to coordinate changes across multiple teams and environments. 24 months may be true for some ecosystems, but the Kubernetes stated minimum in this exam-style framing is 12 months. The key operational takeaway is: don't ignore deprecation notices-they' re your clock for migration planning. Treat API version upgrades as part of routine cluster lifecycle hygiene to avoid being blocked during Kubernetes version upgrades when deprecated APIs are finally removed.
=========
NEW QUESTION # 134
How does service logical group set of pods?
Answer: A
Explanation:
https://kubernetes.io/docs/concepts/services-networking/service/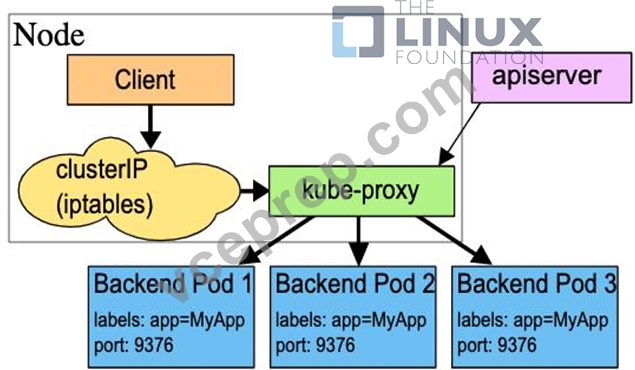
NEW QUESTION # 135
......
KCNA Exam Sample Online: https://www.vceprep.com/KCNA-latest-vce-prep.html
BONUS!!! Download part of VCEPrep KCNA dumps for free: https://drive.google.com/open?id=1C9GVrC7N6jCMZVN1Oa-iIOMoqZbQJDHT