検証する-素晴らしいDatabricks-Certified-Data-Engineer-Professional日本語受験教科書試験-試験の準備方法Databricks-Certified-Data-Engineer-Professional問題集

P.S. GoShikenがGoogle Driveで共有している無料かつ新しいDatabricks-Certified-Data-Engineer-Professionalダンプ:https://drive.google.com/open?id=1jr3WOglFiylFTlyPZdqISvOkMkWe5mEq
これらの問題を解決するための基本的な方法は、社会の発展よりも速いスピードで成長することです。現場では、Databricks認定を取得して、自分自身を改善し、より良いあなたとより良い未来を目指してください。それにより、あなたはあなたの職業で認められます。 Databricks-Certified-Data-Engineer-Professional試験トレントは、より大企業に注意を向けさせる能力を証明できます。その後、より良い仕事を取得し、適切な職場に行くための選択肢があります。そして、Databricks-Certified-Data-Engineer-Professional試験問題は、98%以上の高い品質と高い合格率で有名です。 Databricks-Certified-Data-Engineer-Professional学習ガイドをお試しください。
Databricks Databricks-Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Data Transformation, Cleansing, and Quality | 10% | - Enforce data quality standards
- Apply data cleansing and validation rules
- Implement schema evolution and management
|
| Data Governance | 7% | - Use Unity Catalog for governance
- Enforce data policies and standards
- Manage data assets and metadata
|
| Data Ingestion & Acquisition | 7% | - Use Auto Loader and structured streaming
- Handle incremental and batch data loads
- Ingest data from diverse sources
|
| Debugging and Deploying | 10% | - Troubleshoot and debug pipelines
- Implement CI/CD and DevOps practices
- Deploy using Asset Bundles, CLI, and APIs
|
| Developing Code for Data Processing using Python and SQL | 22% | - Implement complex data processing logic
- Use Databricks-specific libraries and APIs
- Write efficient and maintainable code
|
| Data Sharing and Federation | 5% | - Manage cross-platform data access
- Implement Lakehouse Federation
- Use Delta Sharing for secure data sharing
|
| Cost & Performance Optimisation | 13% | - Optimize compute and storage resources
- Apply cost management best practices
- Improve query and pipeline performance
|
| Monitoring and Alerting | 10% | - Monitor pipeline performance and health
- Set up alerts and notifications
- Track data lineage and metrics
|
| Data Modelling | 6% | - Implement dimensional and relational models
- Design Medallion Architecture
- Optimize table design and partitioning
|
| Ensuring Data Security and Compliance | 10% | - Ensure data privacy and compliance
- Secure data at rest and in transit
- Implement access control and permissions
|
>> Databricks-Certified-Data-Engineer-Professional日本語受験教科書 <<
Databricks-Certified-Data-Engineer-Professional問題集、Databricks-Certified-Data-Engineer-Professional日本語独学書籍
24時間年中無休のサービスオンラインサポートサービスを提供しており、専門スタッフにリモートアシスタンスを提供しています。また、Databricks-Certified-Data-Engineer-Professional実践教材の請求書が必要な場合は、請求書情報を指定してメールをお送りください。オンラインカスタマーサービスとメールサービスが常にお客様をお待ちしています。また、購入前にDatabricks-Certified-Data-Engineer-Professionalトレーニングエンジンの試用版を無料でダウンロードできます。この種のサービスは、当社のDatabricks-Certified-Data-Engineer-Professional学習教材に関する自信と実際の強さを示しています。そして、最高のDatabricks-Certified-Data-Engineer-Professional学習ガイドで確実にDatabricks-Certified-Data-Engineer-Professional試験に合格します。
Databricks Certified Data Engineer Professional Exam 認定 Databricks-Certified-Data-Engineer-Professional 試験問題 (Q177-Q182):
質問 # 177
What statement is true regarding the retention of job run history?
- A. It is retained for 90 days or until the run-id is re-used through custom run configuration
- B. It is retained for 30 days, during which time you can deliver job run logs to DBFS or S3
- C. It is retained for 60 days, during which you can export notebook run results to HTML
- D. It is retained until you export or delete job run logs
- E. It is retained for 60 days, after which logs are archived
正解:C
解説:
https://docs.databricks.com/en/workflows/jobs/monitor-job-runs.html
質問 # 178
A data engineering team needs to create a SQL Alert that monitors data quality across multiple columns in their customer table. They want to trigger an alert when both the percentage of customers with missing email addresses exceeds 15% AND the percentage of customers with invalid phone number formats exceeds 10%. Which SQL query pattern is appropriate for implementing this multi-column alert condition?
- A. SELECT email, phone FROM customers WHERE email IS NULL AND phone NOT RLIKE ''[0-9-
+()\\s]+$' - B. SELECT CASE WHEN email_null_pct >15 AND phone_invalid_pct> 10 THEN 1 ELSE 0 END FROM (SELECT (COUNT (CASE WHEN email IS NULL THEN 1 END) * 100.0 / COUNT (*)) as phone_invalid_pct FROM customers) metrics
- C. SELECT COUNT (*) FROM customers WHERE email IS NULL OR phone_format_invalid = true
- D. SELECT email_null_pct, phone_invalid_pct FROM (SELECT (COUNT(CASE WHEN email IS NULL THEN 1 END) *
100.0/COUNT (*)) as email_null_pct, (COUNT(CASE WHEN phone NOT RLIKE ''[0-9-+()\\s]+$' THEN 1 END)*
100.0/COUNT (*)) as phone_invalid_pct FROM customers)
正解:D
解説:
This pattern computes independent percentage metrics for each data quality condition in a single aggregated query. By calculating the percentage of missing emails and invalid phone formats as separate columns, it enables the SQL Alert to evaluate a compound condition where both thresholds must be exceeded before triggering.
質問 # 179
A small company based in the United States has recently contracted a consulting firm in India to implement several new data engineering pipelines to power artificial intelligence applications. All the company's data is stored in regional cloud storage in the United States.
The workspace administrator at the company is uncertain about where the Databricks workspace used by the contractors should be deployed.
Assuming that all data governance considerations are accounted for, which statement accurately informs this decision?
- A. Databricks notebooks send all executable code from the user's browser to virtual machines over the open internet; whenever possible, choosing a workspace region near the end users is the most secure.
- B. Databricks runs HDFS on cloud volume storage; as such, cloud virtual machines must be deployed in the region where the data is stored.
- C. Cross-region reads and writes can incur significant costs and latency; whenever possible, compute should be deployed in the same region the data is stored.
- D. Databricks workspaces do not rely on any regional infrastructure; as such, the decision should be made based upon what is most convenient for the workspace administrator.
- E. Databricks leverages user workstations as the driver during interactive development; as such, users should always use a workspace deployed in a region they are physically near.
正解:C
解説:
This is the correct answer because it accurately informs this decision. The decision is about where the Databricks workspace used by the contractors should be deployed. The contractors are based in India, while all the company's data is stored in regional cloud storage in the United States. When choosing a region for deploying a Databricks workspace, one of the important factors to consider is the proximity to the data sources and sinks. Cross-region reads and writes can incur significant costs and latency due to network bandwidth and data transfer fees.
Therefore, whenever possible, compute should be deployed in the same region the data is stored to optimize performance and reduce costs.
質問 # 180
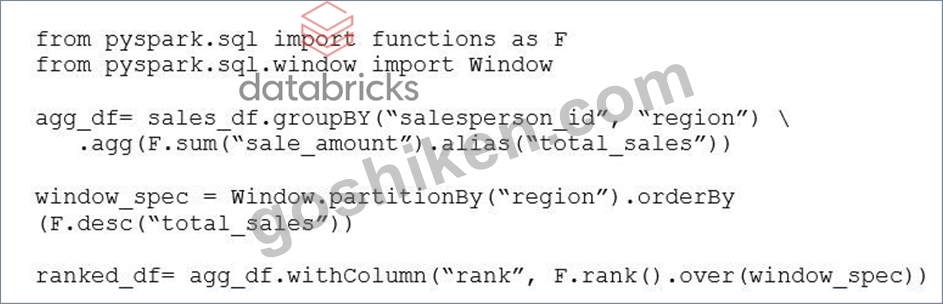
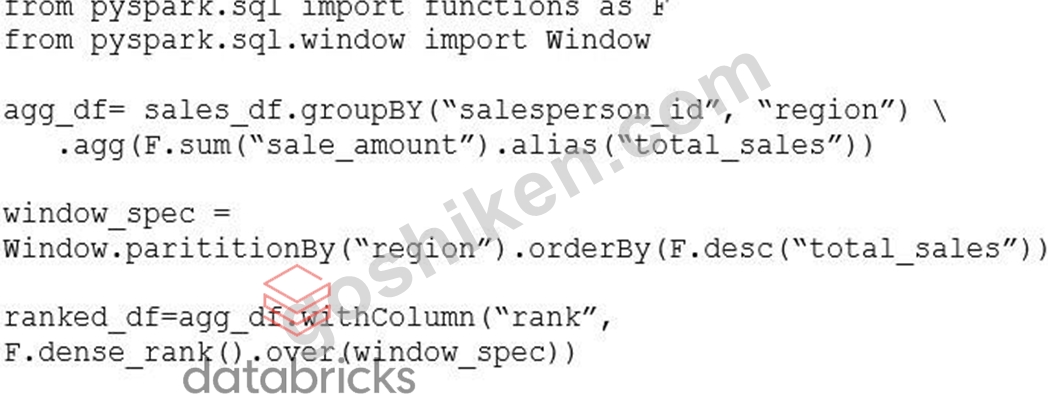
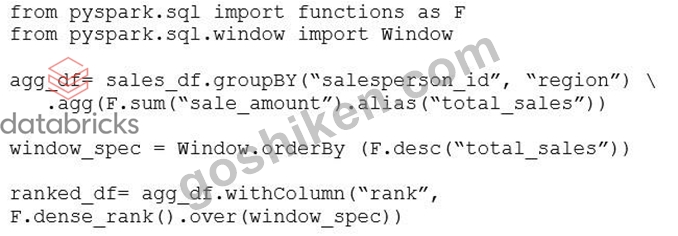
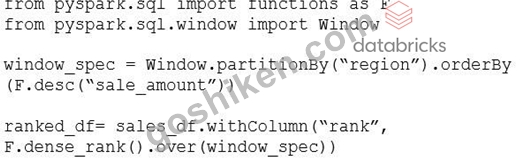
A data engineer is analyzing a large, partitioned retail dataset in Databricks, where each row represents a sale made by a salesperson. The dataset contains millions of records with the following schema:
sales_df: [salesperson_id: string, region: string, sale_amount: double, sale_date: date] The data engineer needs to generate a DataFrame that ranks salespeople within each region based on their total cumulative sales, with the highest seller ranked as 1. If multiple salespeople have the same total sales, they should share the same rank.
The data engineer wants to implement this logic using a PySpark window function and the dense_rank () function.
Which code snippet will perform this ranking?
正解:B
解説:
This approach first aggregates sales by salesperson and region to compute total cumulative sales. It then applies a window function partitioned by region and ordered by total sales in descending order, using dense_rank to assign ranks so that salespeople with equal totals share the same rank and the highest total receives rank 1.
質問 # 181
The data science team has requested assistance in accelerating queries on free form text from user reviews. The data is currently stored in Parquet with the below schema:
item_id INT, user_id INT, review_id INT, rating FLOAT, review STRING
The review column contains the full text of the review left by the user. Specifically, the data science team is looking to identify if any of 30 key words exist in this field.
A junior data engineer suggests converting this data to Delta Lake will improve query performance.
Which response to the junior data engineer's suggestion is correct?
- A. ZORDER ON review will need to be run to see performance gains.
- B. Delta Lake statistics are not optimized for free text fields with high cardinality.
- C. Delta Lake statistics are only collected on the first 4 columns in a table.
- D. The Delta log creates a term matrix for free text fields to support selective filtering.
- E. Text data cannot be stored with Delta Lake.
正解:B
解説:
Converting the data to Delta Lake may not improve query performance on free text fields with high cardinality, such as the review column. This is because Delta Lake collects statistics on the minimum and maximum values of each column, which are not very useful for filtering or skipping data on free text fields. Moreover, Delta Lake collects statistics on the first 32 columns by default, which may not include the review column if the table has more columns. Therefore, the junior data engineer's suggestion is not correct. A better approach would be to use a full-text search engine, such as Elasticsearch, to index and query the review column. Alternatively, you can use natural language processing techniques, such as tokenization, stemming, and lemmatization, to preprocess the review column and create a new column with normalized terms that can be used for filtering or skipping data.
質問 # 182
......
クライアントは、支払いが完了するとすぐに、当社の製品をダウンロードし、Databricks-Certified-Data-Engineer-Professional学習教材を使用できます。私たちのシステムは、支払いが成功してから5〜10分後にDatabricks-Certified-Data-Engineer-Professional学習準備をメール形式でクライアントに送信します。メールはリンクを提供します。クライアントのみがリンクをクリックすると、すぐにソフトウェアにログインしてDatabricks-Certified-Data-Engineer-Professionalガイド資料を学習できます。クライアントがDatabricks-Certified-Data-Engineer-Professionalトレーニングクイズを購入する限り、すぐにGoShiken製品を使用して時間を節約できます。
Databricks-Certified-Data-Engineer-Professional問題集: https://www.goshiken.com/Databricks/Databricks-Certified-Data-Engineer-Professional-mondaishu.html
- 便利なDatabricks-Certified-Data-Engineer-Professional日本語受験教科書 - 合格スムーズDatabricks-Certified-Data-Engineer-Professional問題集 | 便利なDatabricks-Certified-Data-Engineer-Professional日本語独学書籍 🐋 検索するだけで▶ jp.fast2test.com ◀から[ Databricks-Certified-Data-Engineer-Professional ]を無料でダウンロードDatabricks-Certified-Data-Engineer-Professional資格準備
- 便利なDatabricks-Certified-Data-Engineer-Professional日本語受験教科書 - 合格スムーズDatabricks-Certified-Data-Engineer-Professional問題集 | 便利なDatabricks-Certified-Data-Engineer-Professional日本語独学書籍 🍗 ウェブサイト⇛ www.goshiken.com ⇚から➡ Databricks-Certified-Data-Engineer-Professional ️⬅️を開いて検索し、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional資格取得
- 素敵なDatabricks-Certified-Data-Engineer-Professional日本語受験教科書 - 合格スムーズDatabricks-Certified-Data-Engineer-Professional問題集 | 効率的なDatabricks-Certified-Data-Engineer-Professional日本語独学書籍 📽 ➽ www.passtest.jp 🢪サイトにて最新{ Databricks-Certified-Data-Engineer-Professional }問題集をダウンロードDatabricks-Certified-Data-Engineer-Professional日本語講座
- 便利なDatabricks-Certified-Data-Engineer-Professional日本語受験教科書 - 合格スムーズDatabricks-Certified-Data-Engineer-Professional問題集 | 便利なDatabricks-Certified-Data-Engineer-Professional日本語独学書籍 🧴 ▛ www.goshiken.com ▟で使える無料オンライン版✔ Databricks-Certified-Data-Engineer-Professional ️✔️ の試験問題Databricks-Certified-Data-Engineer-Professional科目対策
- Databricks-Certified-Data-Engineer-Professional日本語関連対策 ➡️ Databricks-Certified-Data-Engineer-Professional対応内容 🔄 Databricks-Certified-Data-Engineer-Professional問題集 🌻 ✔ jp.fast2test.com ️✔️を開き、{ Databricks-Certified-Data-Engineer-Professional }を入力して、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional模擬対策
- Databricks-Certified-Data-Engineer-Professional日本語関連対策 🥄 Databricks-Certified-Data-Engineer-Professional最新対策問題 🎶 Databricks-Certified-Data-Engineer-Professional模擬対策 🚡 “ www.goshiken.com ”を開いて「 Databricks-Certified-Data-Engineer-Professional 」を検索し、試験資料を無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional問題集
- Databricks-Certified-Data-Engineer-Professional対応内容 🧱 Databricks-Certified-Data-Engineer-Professional資格準備 🐷 Databricks-Certified-Data-Engineer-Professional参考資料 🧭 サイト「 www.xhs1991.com 」で☀ Databricks-Certified-Data-Engineer-Professional ️☀️問題集をダウンロードDatabricks-Certified-Data-Engineer-Professional模擬資料
- 権威のあるDatabricks-Certified-Data-Engineer-Professional日本語受験教科書 - 合格スムーズDatabricks-Certified-Data-Engineer-Professional問題集 | 高品質なDatabricks-Certified-Data-Engineer-Professional日本語独学書籍 🍼 ➠ www.goshiken.com 🠰で使える無料オンライン版✔ Databricks-Certified-Data-Engineer-Professional ️✔️ の試験問題Databricks-Certified-Data-Engineer-Professional科目対策
- 試験の準備方法-有難いDatabricks-Certified-Data-Engineer-Professional日本語受験教科書試験-更新するDatabricks-Certified-Data-Engineer-Professional問題集 🍶 ▷ www.xhs1991.com ◁で使える無料オンライン版➡ Databricks-Certified-Data-Engineer-Professional ️⬅️ の試験問題Databricks-Certified-Data-Engineer-Professional日本語版試験解答
- 素敵なDatabricks-Certified-Data-Engineer-Professional日本語受験教科書 - 合格スムーズDatabricks-Certified-Data-Engineer-Professional問題集 | 効率的なDatabricks-Certified-Data-Engineer-Professional日本語独学書籍 🥋 ⮆ Databricks-Certified-Data-Engineer-Professional ⮄を無料でダウンロード【 www.goshiken.com 】ウェブサイトを入力するだけDatabricks-Certified-Data-Engineer-Professional認定試験
- 検証するDatabricks-Certified-Data-Engineer-Professional日本語受験教科書 - 合格スムーズDatabricks-Certified-Data-Engineer-Professional問題集 | 高品質なDatabricks-Certified-Data-Engineer-Professional日本語独学書籍 🐗 《 www.it-passports.com 》を開き、▶ Databricks-Certified-Data-Engineer-Professional ◀を入力して、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional日本語版試験解答
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, jacobscott67888.blogspot.com, experiment.com, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.flirtic.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
P.S.GoShikenがGoogle Driveで共有している無料の2026 Databricks Databricks-Certified-Data-Engineer-Professionalダンプ:https://drive.google.com/open?id=1jr3WOglFiylFTlyPZdqISvOkMkWe5mEq