Microsoft DP-750認定試験の難しさで近年にほとんどの受験生は資格認定試験に合格しなっかたと良く知られます。だから、我々社の有効な試験問題集は長年にわたりMicrosoft DP-750認定資格試験問題集作成に取り組んだIT専門家によって書いてます。実際の試験に表示される質問と正確な解答はあなたのMicrosoft DP-750認定資格試験合格を手伝ってあげます。
| Section | Weight | Objectives |
|---|---|---|
| Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
| Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Prepare and process data | 30-35% | - Ingest and transform data
|
JapancertはMicrosoftのDP-750認定試験にたいして短期で有効なウェブサイトでDP-750認定試験に合格するのを保証したり、Microsoft認証試験に合格しなければ全額で返金いたします。あなたはJapancertが提供したDP-750の認証試験の問題集を購入するの前にインターネットで無料な試用版をダウンロードしてください。
質問 # 95
You have an Azure Databricks workspace that contains an all-purpose cluster named Cluster! You need to configure Cluster1 to meet the following requirements;
* The cluster must scale up automatically when workloads increase.
* The cluster must scale down automatically when workloads decrease.
The solution must minimize costs.
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
正解:B、C
解説:
The correct answers are C and D. Together they deliver cost-efficient autoscaling:
D (Enable autoscaling) allows the cluster to grow when workloads increase and shrink when they ease off.
This satisfies both scale-up and scale-down requirements without manual intervention.
C (Auto-termination after 30 minutes of inactivity) ensures the cluster stops entirely when no work is running, eliminating the cost of an idle cluster. This is the cheapest possible state.
Option A (disable Photon) reduces compute acceleration - that's a performance regression with no meaningful cost benefit for autoscaling. Option B (compute policy that lets users manage settings) adds governance overhead and doesn't address scaling behaviour. Option E (fixed number of workers) is the opposite of autoscaling - a static worker count that either over-provisions during quiet periods or under- provisions during peaks.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/configure#autoscaling
質問 # 96
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to recommend a pipeline that ingests files from cloud storage, performs cleansing and enrichment transformations, and writes curated Delta tables for analytics. The solution must minimize development effort and provide built-in monitoring and automatic retries.
What should you include in the recommendation?
正解:B
解説:
The best choice is a Lakeflow Spark Declarative Pipelines (SDP) pipeline.
Low Development Effort: Lakeflow SDP (formerly known as Delta Live Tables or DLT) is a completely declarative ETL framework. You simply define the target schemas and data transformations using standard SQL or Python. Databricks automatically manages the underlying operational complexities, state maintenance, task orchestration, and DAG dependencies for you.
Built-in Quality & Monitoring: It offers out-of-the-box data monitoring capabilities via Expectations, which allow you to specify data cleansing policies (like drop, retain, or fail on bad rows) with zero custom validation code. It also captures complete, automatic end-to-end data lineage and operational stats straight into Unity Catalog.
Built-in Resilience: Infrastructure failure handling and automatic retries are natively managed by the Lakeflow runtime.
Native Storage Ingestion: Using read_files() (Auto Loader) within SDP allows effortless, incremental ingestion of files from cloud object storage directly into curated Delta tables.
Reference:
https://docs.databricks.com/aws/en/ldp/
質問 # 97
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You plan to create a job in Lakeflow Jobs named Job1 that:
* Ingests data from cloud storage
* Runs two independent transformation tasks
The transformation tasks must run only after the ingestion completes and must run in parallel.
You need to design the task logic for Job1.
What should you configure?
正解:B
解説:
Job1 should contain one ingestion task that acts as the common upstream dependency for two separate transformation tasks. Once ingestion succeeds, Lakeflow Jobs can start both downstream tasks concurrently because neither transformation depends on the other. This design represents the actual workflow, avoids duplicated ingestion, and reduces total execution time through parallelism. Creating two ingestion tasks would repeat the same source processing and could introduce inconsistent results or unnecessary costs. A single sequential task would prevent parallel transformation and make failures harder to isolate and retry. Defining three independent tasks without dependencies could allow transformations to start before ingestion has completed. An explicit directed task graph therefore provides the required execution order while preserving parallelism for independent downstream processing.
質問 # 98
You have an Azure Databricks workspace that uses Databricks SQL.
You have a table named sales_goals_source that contains the following columns:
* Salesperson
* Item
* 2019
* 2020
* 2021
You need to transform the year columns into rows and return the columns Salesperson, Item, Year, and Value.
How should you complete the SQL statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
SELECT Salesperson, Item, Year, Value
FROM sales_goals_source
UNPIVOT
(
Value FOR [first dropdown] IN [second dropdown]
);
正解:
解説: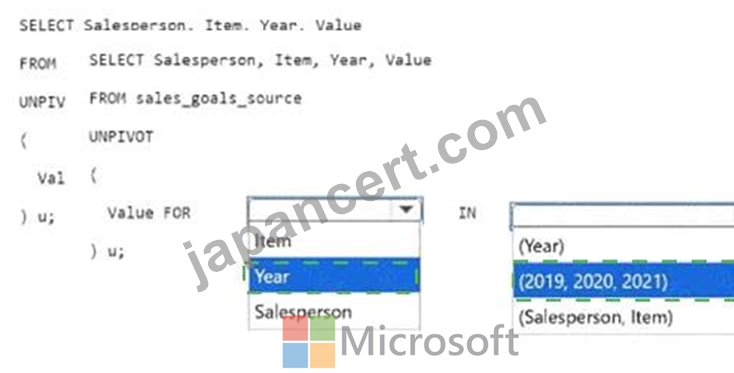
Explanation:
First dropdown: Year
Second dropdown: (2019, 2020, 2021)
The UNPIVOT operator converts the separate 2019, 2020, and 2021 columns into rows. Value becomes the output column containing the values previously stored in those year columns. Year becomes the output name column that identifies the original column from which each value came. Therefore, the expression must use Value FOR Year IN (2019, 2020, 2021). The Salesperson and Item columns are not included in the IN list because they remain identifier columns and are repeated for every resulting year row. A single source row consequently produces three output rows-one for each listed year. Selecting (Year) would reference an output name rather than the source columns that must be rotated.
質問 # 99
You have an Azure Databricks workspace that is enabled for Unity Catalog. You plan to run the following PySpark code.
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.
正解:
解説:
Explanation:
For HOTSPOT questions, each statement must be evaluated against the actual PySpark code shown in the answer area. Key evaluation principles:
DataFrames are immutable - every transformation returns a new DataFrame; the original is unchanged.
Transformations (filter, select, groupBy, join) are lazy and only execute when an action (show, count, write) is called.
Null handling: df.filter(col != None) is incorrect in PySpark due to SQL null semantics; use col.isNotNull() or dropna() instead. Schema changes: using mergeSchema=true or schema evolution handles new columns.
Write modes: ' overwrite ' replaces existing data; ' append ' adds to it.
Always check whether the code uses the correct Delta format (.format( ' delta ' )), Unity Catalog three-part naming, and whether write operations include a checkpointLocation for streaming queries. Evaluate each statement strictly on what the code does, not on what it might intend to do.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
質問 # 100
......
DP-750準備トレントは、タイムリーなアプリケーションを提供することにより、デジタル化された世界に対応できます。ソフトウェアとAPPのオンラインバージョンがあり、実際の試験環境をシミュレートできます。MicrosoftこのDP-750練習教材の特性を十分に活用すれば、DP-750の実際の試験に対処するときに緊張することはありません。さらに、それらはすべての電子デバイスにダウンロードできるため、かなりモダンな学習体験を手軽に楽しむことができます。 DP-750試験問題を試してみませんか?
DP-750日本語問題集: https://www.japancert.com/DP-750.html