Pass Guaranteed DP-600 - Newest Implementing Analytics Solutions Using Microsoft Fabric Certification Materials

What's more, part of that Getcertkey DP-600 dumps now are free: https://drive.google.com/open?id=1UPI1xDFf-g_wJbdtclEQgh6cNFbn7V2c
If you want to get DP-600 certification and get hired immediately, you’ve come to the right place. Getcertkey offers you the best exam dump for DP-600 certification. With the guidance of no less than seasoned DP-600 professionals, we have formulated updated actual questions for DP-600 Certified exams, over the years. To keep our questions up to date, we constantly review and revise them to be at par with the latest DP-600 syllabus for DP-600 certification.
Microsoft DP-600 Exam Overview:
| Certification Vendor: | Microsoft |
|---|
| Exam Name: | Implementing Analytics Solutions Using Microsoft Fabric |
|---|
| Exam Number: | DP-600 |
|---|
| Related Certifications: | Microsoft Certified: Fabric Analytics Engineer Associate |
|---|
| Exam Price: | $165 USD |
|---|
| Real Exam Qty: | 40-60 |
|---|
| Exam Format: | Case studies, Drag-and-drop, Multiple-choice |
|---|
| Exam Duration: | 120 minutes |
|---|
| Available Languages: | Korean, Chinese (Simplified), English, Japanese |
|---|
| Certificate Validity Period: | 1 year |
|---|
| Passing Score: | 700/1000 |
|---|
| Sample Questions: | Microsoft DP-600 Sample Questions |
|---|
| Exam Way: | Online proctored or in-person testing center |
|---|
| Pre Condition: | Candidates should have foundational knowledge of data concepts, experience with Microsoft Fabric, and proficiency in data transformation and modeling. Familiarity with Power BI is recommended but not required. |
|---|
| Official Syllabus URL: | https://learn.microsoft.com/en-us/certifications/exams/dp-600 |
|---|
>> DP-600 Certification Materials <<
Test Microsoft DP-600 Quiz & DP-600 Latest Dumps Book
Do you know why you feel pressured to work? That is because your own ability and experience are temporarily unable to adapt to current job requirements. Our DP-600 exam questions can upgrade your skills and experience to the current requirements in order to have the opportunity to make the next breakthrough. Don't doubt about our DP-600 Study Guide! Just look at the warm feedbacks from our loyal customers, they all have became more successful in their career with the help of our DP-600 practice engine.
| Topic | Details |
|---|
| Topic 1 | - Prepare data: This section of the exam measures the skills of engineers and covers essential data preparation tasks. It includes establishing data connections and discovering sources through tools like the OneLake data hub and the real-time hub. Candidates must demonstrate knowledge of selecting the appropriate storage type—lakehouse, warehouse, or eventhouse—depending on the use case. It also includes implementing OneLake integrations with Eventhouse and semantic models. The transformation part involves creating views, stored procedures, and functions, as well as enriching, merging, denormalizing, and aggregating data. Engineers are also expected to handle data quality issues like duplicates, missing values, and nulls, along with converting data types and filtering. Furthermore, querying and analyzing data using tools like SQL, KQL, and the Visual Query Editor is tested in this domain.
|
| Topic 2 | - Maintain a data analytics solution: This section of the exam measures the skills of administrators and covers tasks related to enforcing security and managing the Power BI environment. It involves setting up access controls at both workspace and item levels, ensuring appropriate permissions for users and groups. Row-level, column-level, object-level, and file-level access controls are also included, alongside the application of sensitivity labels to classify data securely. This section also tests the ability to endorse Power BI items for organizational use and oversee the complete development lifecycle of analytics assets by configuring version control, managing Power BI Desktop projects, setting up deployment pipelines, assessing downstream impacts from various data assets, and handling semantic model deployments using XMLA endpoint. Reusable asset management is also a part of this domain.
|
| Topic 3 | - Implement and manage semantic models: This section of the exam measures the skills of architects and focuses on designing and optimizing semantic models to support enterprise-scale analytics. It evaluates understanding of storage modes and implementing star schemas and complex relationships, such as bridge tables and many-to-many joins. Architects must write DAX-based calculations using variables, iterators, and filtering techniques. The use of calculation groups, dynamic format strings, and field parameters is included. The section also includes configuring large semantic models and designing composite models. For optimization, candidates are expected to improve report visual and DAX performance, configure Direct Lake behaviors, and implement incremental refresh strategies effectively.
|
Microsoft Implementing Analytics Solutions Using Microsoft Fabric Sample Questions (Q110-Q115):
NEW QUESTION # 110
Drag and Drop Question
You are creating a data flow in Fabric to ingest data from an Azure SQL database by using a T- SQL statement.
You need to ensure that any foldable Power Query transformation steps are processed by the Microsoft SQL Server engine.
How should you complete the code? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.

Answer:
Explanation:

Explanation:
https://learn.microsoft.com/en-us/power-query/native-query-folding
NEW QUESTION # 111
You have a Fabric eventhouse named Eventhousel that contains a table named Weatherdata. A sample of the data in Weatherdata is shown in the following table.

You plan to use a KQL queryset to manipulate the data in Eventhouse1. The result set must have the following columns.

You need to build the query.
Which four KQL statements should you use in sequence? To answer, move the appropriate statements from the list of statements to the answer area and arrange them in the correct order.

Answer:
Explanation:

Explanation:

Comprehensive Detailed Explanation
Step 1: Understanding the requirement
We need a KQL query that:
Reads data from Weatherdata.
Orders by Datetime.
Calculates Delta_temperature as the difference between the current row and the preceding row.
Returns the final columns: Datetime, Lat, Long, Temperature, Delta_temperature.
Step 2: Evaluate the provided statements
Weatherdata # Starts the query with the source table.
| sort by Datetime asc # Ensures chronological order, required for prev() to work correctly.
| extend Delta_temperature = Temperature - prev(Temperature) # Computes difference between the current row and the previous row's temperature.
| project Datetime, Lat, Long, Temperature, Delta_temperature # Selects the required output columns.
Step 3: Incorrect choices (to avoid)
next(Temperature,1) # Would calculate the difference with the next row, not the previous.
prev(Temperature,2) # Would skip one row, giving the difference with two rows back, which is not needed.
summarize ... by Datetime # Aggregates the data; not required here since we just need row-level differences.
Step 4: Final Correct Sequence
Weatherdata
| sort by Datetime asc
| extend Delta_temperature = Temperature - prev(Temperature)
| project Datetime, Lat, Long, Temperature, Delta_temperature
References
prev() function in KQL
extend operator in KQL
project operator in KQL
NEW QUESTION # 112
You have a Fabric tenant.
You plan to create a Fabric notebook that will use Spark DataFrames to generate Microsoft Power Bl visuals.
You run the following code.

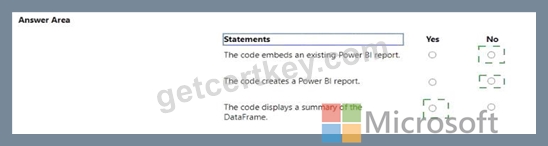
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.

Answer:
Explanation:
Explanation:
The code embeds an existing Power BI report. - No
The code creates a Power BI report. - Yes
The code displays a summary of the DataFrame. - Yes
The code provided seems to be a snippet from a SQL query or script which is neither creating nor embedding a Power BI report directly. It appears to be setting up a DataFrame for use within a larger context, potentially for visualization in Power BI, but the code itself does not perform the creation or embedding of a report.
Instead, it's likely part of a data processing step that summarizes data.
References =
Introduction to DataFrames - Spark SQL
Power BI and Azure Databricks
NEW QUESTION # 113
You have a Fabric tenant that contains the workspaces shown in the following table.

You have a deployment pipeline named Pipeline1 that deploys items from Workspace_DEV to Workspace_TEST. In Pipeline1, all items that have matching names are paired.
You deploy the contents of Workspace_DEV to Workspace_TEST by using Pipeline1.
What will the contents of Workspace_TEST be once the deployment is complete?
- A. Lakehouse2
Notebook2
SemanticModel1 - B. Lakehouse1
Lakehouse2
Notebook1
Notebook2
Pipeline1
SemanticModel1 - C. Lakehouse2
Notebook2
Pipeline1
SemanticModel1 - D. Lakehouse1
Notebook1
Pipeline1
SemanticModel1
Answer: C
NEW QUESTION # 114
You are implementing a medallion architecture in a single Fabric workspace.
You have a lakehouse that contains the 8ronze and Silver layers and a warehouse that contains the Gold layer.
You create the items required to populate the layers as shown in the following table.

You need to ensure that the layers are populated daily in sequential order such that Silver is populated only after Bronze is complete, and Gold is populated only after Silver is complete. The solution must minimize development effort and complexity.
What should you use to execute each set of items? To answer, drag the appropriate options to the correct items. Each option may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.

Answer:
Explanation:

Explanation:
To execute each set of items in sequential order with minimized development effort and complexity, you should use the following options:
* Orchestration pipeline: Use a pipeline with an Invoke pipeline activity. This allows for orchestrating and scheduling the execution of other pipelines, ensuring they run in the correct sequence.
* Bronze layer: Implement a pipeline Copy activity. This aligns with the table indicating that the Bronze layer uses pipelines with Copy activities for data integration.
* Silver layer: Implement a pipeline Dataflow activity. The table specifies that Dataflows are used for the Silver layer.
* Gold layer: Implement a pipeline Stored procedure activity. Stored procedures are specified for the Gold layer according to the table.
NEW QUESTION # 115
......
Test DP-600 Quiz: https://www.getcertkey.com/DP-600_braindumps.html
- Pass Guaranteed Microsoft - DP-600 - Unparalleled Implementing Analytics Solutions Using Microsoft Fabric Certification Materials 💫 The page for free download of ⇛ DP-600 ⇚ on 「 www.troytecdumps.com 」 will open immediately 🏯DP-600 Dumps PDF
- Exam DP-600 Quizzes 🎩 DP-600 Passed 🥞 Premium DP-600 Files 🔕 Open 【 www.pdfvce.com 】 enter ✔ DP-600 ️✔️ and obtain a free download 🐠Exam DP-600 Price
- Pass Guaranteed Microsoft - DP-600 - Unparalleled Implementing Analytics Solutions Using Microsoft Fabric Certification Materials 🔏 Search for ➥ DP-600 🡄 and download exam materials for free through ▷ www.prepawayexam.com ◁ 🕷DP-600 Exam Forum
- Top Features of Microsoft DP-600 PDF Dumps And Practice Test Software 😷 Enter ( www.pdfvce.com ) and search for ▛ DP-600 ▟ to download for free 🐅Exam DP-600 Certification Cost
- TOP DP-600 Certification Materials: Implementing Analytics Solutions Using Microsoft Fabric - High-quality Microsoft Test DP-600 Quiz 🙁 Search for ➥ DP-600 🡄 and download it for free immediately on ⇛ www.examcollectionpass.com ⇚ 🐁Best DP-600 Vce
- Exam DP-600 Quizzes 🚍 DP-600 Passed 🛬 DP-600 Dumps PDF 🔇 Simply search for ▷ DP-600 ◁ for free download on ▷ www.pdfvce.com ◁ 🎦Valid Test DP-600 Tips
- Free PDF Quiz Useful Microsoft - DP-600 Certification Materials 🙌 Easily obtain free download of 「 DP-600 」 by searching on ▶ www.troytecdumps.com ◀ 🏴Exam DP-600 Certification Cost
- Top Features of Microsoft DP-600 PDF Dumps And Practice Test Software 💑 Search for “ DP-600 ” and download it for free immediately on ▷ www.pdfvce.com ◁ 👈Premium DP-600 Files
- DP-600 Exam Forum 🦨 DP-600 Dumps PDF 🕘 DP-600 Exam Pass4sure 🎭 Search for “ DP-600 ” and obtain a free download on ➤ www.testkingpass.com ⮘ 👹Exam DP-600 Quizzes
- TOP DP-600 Certification Materials: Implementing Analytics Solutions Using Microsoft Fabric - High-quality Microsoft Test DP-600 Quiz 🍰 Simply search for ▷ DP-600 ◁ for free download on ▷ www.pdfvce.com ◁ 🙏Exam DP-600 Certification Cost
- DP-600 Exam Certification Materials- Unparalleled Test DP-600 Quiz Pass Success ⏰ Search on ▛ www.torrentvce.com ▟ for 《 DP-600 》 to obtain exam materials for free download 🧒Valid Dumps DP-600 Free
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, kaeuchi.jp, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, app.parler.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
P.S. Free & New DP-600 dumps are available on Google Drive shared by Getcertkey: https://drive.google.com/open?id=1UPI1xDFf-g_wJbdtclEQgh6cNFbn7V2c