그리고 PassTIP SPS-C01 시험 문제집의 전체 버전을 클라우드 저장소에서 다운로드할 수 있습니다: https://drive.google.com/open?id=1xhMDGwotUdqSXnvnmHe5Ef70XHVo0G_X
PassTIP 에서 출시한 제품 Snowflake인증SPS-C01시험덤프는 고득점으로 시험을 통과한 많은 분들이 검증한 완벽한 시험공부자료입니다. IT업계에 몇십년간 종사한 전문가들의 경험과 노하우로 제작된Snowflake인증SPS-C01덤프는 실제 시험문제에 대비하여 시험유형과 똑같은 유형의 문제가 포함되어있습니다.시험 불합격시 불합격성적표로 덤프비용환불신청을 약속드리기에 아무런 우려없이 덤프를 구매하여 공부하시면 됩니다.
| Section | Weight | Objectives |
|---|---|---|
| Data Transformations and DataFrame Operations | 35% | - Using built-in functions - Complex data pipelines - Persisting transformed data - Filtering, Aggregating, and Joining DataFrames - Window functions |
| Snowpark API for Python | 30% | - Establishing connections and session management - Working with Semi-structured data - User-Defined Functions (UDFs) and Stored Procedures - DataFrame creation and manipulation - Reading and writing data |
| Snowpark Concepts | 15% | - Snowpark architecture and core concepts - Client-side vs. Server-side execution - Transformations vs. Actions - Stored procedures and conditional logic - Snowpark Sessions and connection management - Snowpark DataFrames and query plans |
| Performance Optimization and Best Practices | 20% | - Caching strategies - Warehouse sizing for Snowpark - Query pushdown and optimization - Debugging and explain plans - Vectorized UDFs - Minimizing data transfer |
PassTIP의Snowflake SPS-C01 인증시험덤프는 자주 업데이트 되고, 오래 되고 더 이상 사용 하지 않는 문제들은 바로 삭제해버리며 새로운 최신 문제들을 추가 합니다. 이는 응시자가 확실하고도 빠르게Snowflake SPS-C01덤프를 마스터하고Snowflake SPS-C01시험을 패스할수 있도록 하는 또 하나의 보장입니다. 매력만점Snowflake SPS-C01덤프 강력 추천합니다.
질문 # 234
Consider the following Snowpark Python stored procedure: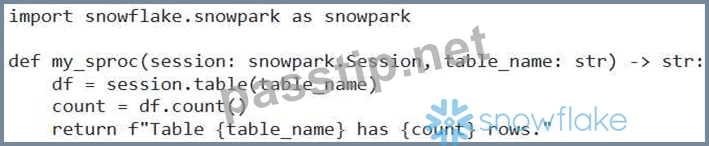
What steps are necessary to register this Python code as a stored procedure named 'GET ROW COUNT in Snowflake and allow users with the 'ANALYST' role to execute it, assuming the stored procedure will be created with the 'EXECUTE AS OWNER clause, and the table name parameter will be passed dynamically during invocation?
정답:D
설명:
Option A correctly outlines the process. First, the stored procedure is created with the correct syntax, including specifying the runtime version and handler, and using 'EXECUTE AS OWNER. Second, 'USAGE privilege is granted on the database and schema. Third, EXECUTE PROCEDURE' privilege must be explicitly granted to the 'ANALYST role. Option B attempts to embed the python code inline but doesn't include IMPORTS section if needed and its more common now to upload the Python code using create or replace procedure syntax. Option C is incorrect because you need to grant ' EXECUTE PROCEDURE privilege to the role in addition to Usage. Option D uses 'EXECUTE AS CALLER , which is not what the question specifies and requires granting 'SELECT privileges on the underlying tables, defeating the purpose of owner rights. 'EXECUTE' is not a valid privilege to grant on stored procedures in Snowflake (Option E), it has to be 'EXECUTE PROCEDURE.
질문 # 235
A Snowpark developer is using to create a Snowpark session. They want to ensure that the session uses a specific role and warehouse, but only if those parameters are not already defined in the Snowflake CLI configuration. Which of the following code snippets correctly implements this behavior?





정답:E
설명:
Option D offers a concise method where role and warehouse specified in the 'Session.builder' are only used if they aren't already defined in the environment or Snowflake CLI configurations. Snowflake gives precedence to the environment over the code when using the session builder. Options A does not take into account how Session.builder.configs would work in order to read the current CLI configurations. Option B overwrites even though the question state that if these parameters are already defined in Snowflake CLI configurations they should NOT be changed. Option C does not have complete Code. Option E is overly complicated.
질문 # 236
You have a Snowpark DataFrame with columns 'sale_date', 'product_id', and 'revenue'. You need to calculate the cumulative revenue for each product over time. Which of the following approaches will accomplish this in Snowpark using window functions?





정답:B,D
설명:
Options A and E both achieve the desired result of calculating cumulative revenue for each product. Option A utilizes 'rowsBetween' specifying that the window frame should include all rows from the beginning ('Window.unboundedPreceding') up to the current row ('Window.currentRow'). This calculates a running sum of revenue for each product over time. Option E uses 'rangeBetween' , which is equivalent to when the order-by expression is of a numeric or date type. Option B does not partition by product_id, so the cumulative revenue is calculated over the entire dataset. Option C does not include frame specification 'rowsBetween()' or 'rangeBetween(Y , therefore defaults to 'RANGE BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW, which is valid for this question. While it's functionally correct, it's implicit, so 'A' is preferrable if one option is to be selected. Option D partitions incorrectly by sale_date.
질문 # 237
You have a Snowpark application that performs machine learning inference on a large dataset of images stored in Snowflake. The inference logic is implemented within a Python UDF that utilizes a pre-trained deep learning model. You notice that the inference process is slow and consumes a significant amount of resources. Which of the following optimization techniques would be MOST effective in improving the performance and reducing the resource consumption of this application?
정답:A,C,E
설명:
Auto-scaling helps manage resources dynamically. Batch processing reduces UDF overhead by processing multiple images in one call. Storing the model in a stage requires repeated loading. Managing the model's lifecycle within the Snowpark Session prevents reloading the model. External functions require data transfer out of Snowflake.
질문 # 238
Consider the following Snowpark Python code snippet that retrieves data and calculates aggregate values, however, the application performance is slow when you are fetching dataframe, given the 'block' parameter controls the synchronous/asynchronous behavior of the 'collect()' method. Choose ALL the statements about "session.create_dataframe([rowl ,row2],schema)' that are correct:
정답:C
설명:
The method, when used with the default 'block=True' , operates synchronously, meaning it waits for the result to be fully available before proceeding to the next line of code. This can introduce latency and slow down the application, especially with larger datasets. Using 'block=False' makes the operation asynchronous, allowing the application to continue executing other tasks while the data is being retrieved in the background. Increasing warehouse size will have the same effect regardless, because of . The 'block' parameter is crucial for controlling synchronous versus asynchronous behaviour. The warehouse has no direct influence since the bottleneck is with 'collect()'. Converting to pandas does not fix the inherent blocking problem and makes the problem worse, given it increase network I/O to move data to client side.
질문 # 239
......
Snowflake인증SPS-C01시험을 패스함으로 취업에는 많은 도움이 됩니다. PassTIP는Snowflake인증SPS-C01시험패스로 꿈을 이루어주는 사이트입니다. 우리는Snowflake인증SPS-C01시험의 문제와 답은 아주 좋은 학습자료로도 충분한 문제집입니다. 여러분이 안전하게 간단하게Snowflake인증SPS-C01시험을 응시할 수 있는 자료입니다.
SPS-C01완벽한 시험기출자료: https://www.passtip.net/SPS-C01-pass-exam.html
PassTIP SPS-C01 최신 PDF 버전 시험 문제집을 무료로 Google Drive에서 다운로드하세요: https://drive.google.com/open?id=1xhMDGwotUdqSXnvnmHe5Ef70XHVo0G_X