Best practice indicates that people who have passed the DP-750 exam would not pass the exam without the help of the DP-750 study materials. So the study materials will be very important for all people. If you also want to pass the exam and get the related certification in a short, the good study materials are the best choice for you. Now we are going to make an introduction about the DP-750 Study Materials from our company for you. We sincerely hope that our study materials will help you achieve your dream.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Deploy and manage data pipelines and workloads | 30-35% | - Lakehouse architecture operations
|
| Topic 2: Configure and manage Azure Databricks environments | 15-20% | - Workspace and compute configuration
|
| Topic 3: Secure and govern data using Unity Catalog | 15-20% | - Access control and policies
|
| Topic 4: Prepare and process data | 30-35% | - Data transformation and modeling
|
Our DP-750 study materials are the best choice in terms of time and money. And all contents of DP-750 training prep are made by elites in this area. Furthermore, DP-750 Quiz Guide gives you 100 guaranteed success and free demos. To fit in this amazing and highly accepted DP-750 Exam, you must prepare for it with high-rank practice materials like our DP-750 study materials. We can ensure your success on the coming exam and you will pass the DP-750 exam just like the others.
NEW QUESTION # 38
You have an Azure Databricks workspace named Workspace1 that contains a lakehouse and is enabled for Unity Catalog.
You have a connection to a Microsoft SQL Server database named DB1.
You need to expose the schemas and tables of DB1 to meet the following requirements:
* The schemas and tables can be queried in Databricks.
* The schemas and tables appear alongside other Unity Catalog objects.
* The data is NOT copied into Databricks-managed storage.
Solution: You create a foreign catalog in Catalog Explorer.
Does this meet the goal?
Answer: A
Explanation:
The correct answer is A - Yes.
A foreign catalog created through Lakehouse Federation in Catalog Explorer is the correct solution for all three requirements. Here's why it works:
The schemas and tables of DB1 can be queried in Databricks - Lakehouse Federation pushes the query down to the external SQL Server and returns results, so analysts write normal SQL in Databricks.
They appear alongside other Unity Catalog objects - the foreign catalog sits in the same three-tier hierarchy as native catalogs, schemas, and tables, visible in Catalog Explorer alongside all other Unity Catalog assets.
The data is NOT copied into Databricks-managed storage - foreign catalogs query data in place at the source; nothing is replicated or materialised in Databricks storage.
This is exactly the scenario Lakehouse Federation was built for.
Reference: https://learn.microsoft.com/en-us/azure/databricks/query-federation/lakehouse-federation
NEW QUESTION # 39
You have an Azure Databricks workspace named Workspace1 that contains a Git folder linked to a remote Git repository. The Git folder contains a Databricks notebook named Notebook1.
From the main branch, you create a feature branch named Branch1 and commit changes to Notebook1.
Another user commits changes to Notebook1 in main.
When you attempt to merge Branch1 into main, a merge conflict occurs.
You need to ensure that Notebook1 in main includes the changes from both branches.
What should you do?
Answer: D
Explanation:
Branch1 must first incorporate the current changes from main. During that merge, the conflicting sections of Notebook1 can be reviewed and resolved so that the resulting feature-branch version contains the required work from both branches. After committing the resolution, Branch1 can be merged into main normally.
Cloning either branch into another Git folder creates another working copy but does not resolve the conflicting histories. Applying changes directly to main bypasses the controlled feature-branch workflow and risks omitting or overwriting one contributor's work. Resolving the conflict on Branch1 also allows the combined notebook to be tested before updating the shared main branch. Therefore, merging main into Branch1, resolving the conflict, and completing the final merge is the correct workflow.
NEW QUESTION # 40
Hotspot Question
You have an Azure Databricks job named Job1 that contains an ingestion task named Task1 and transformation task named Task2.
You need to ensure that if Task1 fails, the task retries automatically, and Task2 is prevented from running.
How should you configure Job1? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.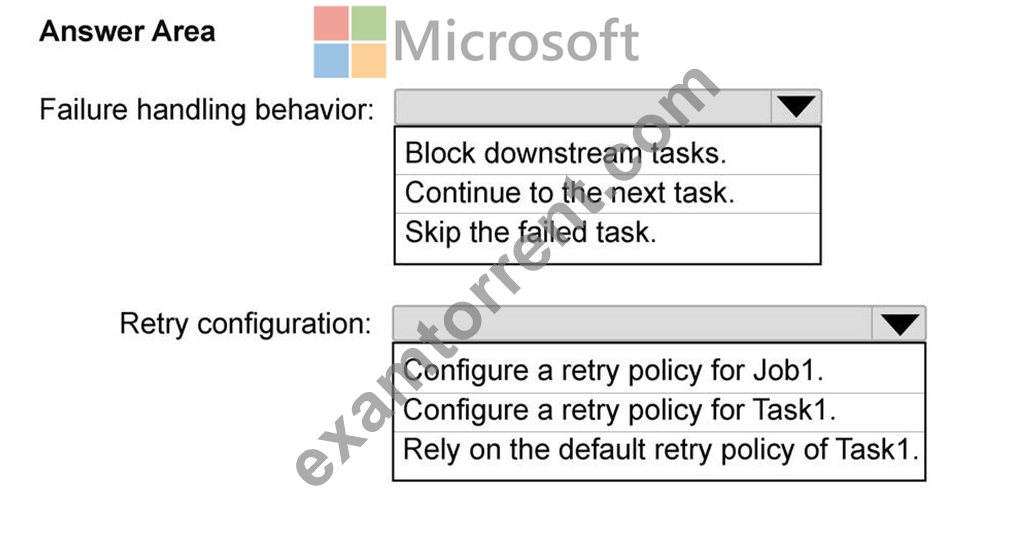
Answer:
Explanation: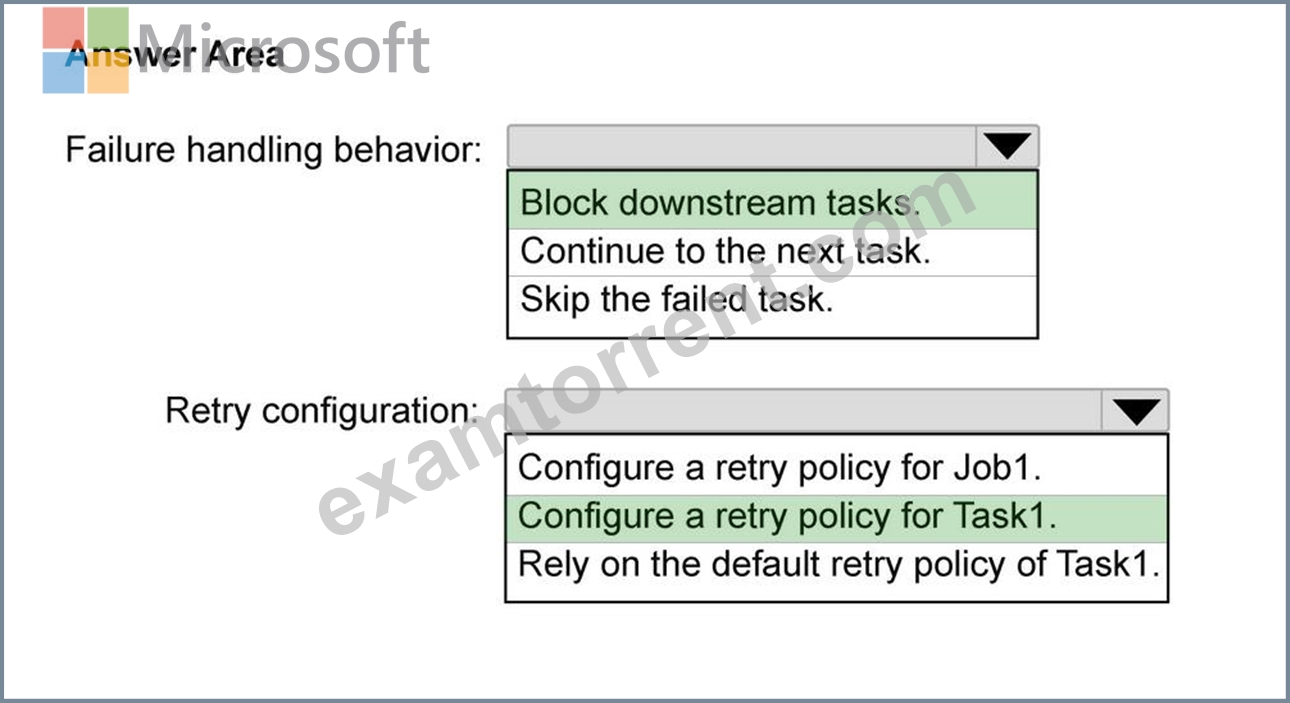
NEW QUESTION # 41
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Table1. Table1 stores customer data.
You need to implement a data retention solution that meets the following requirements:
Deleted data must be retained for 30 days to support audits.
Deleted data that is older than 30 days must be removed permanently.
The solution must minimize administrative effort.
Which two properties should you configure? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: A,D
Explanation:
The correct answers are B and D. Delta Lake's data retention behaviour is controlled by two distinct properties that work together:
delta.deletedFileRetentionDuration governs how long physically deleted data files are kept before VACUUM can remove them. Setting this to 30 days ensures deleted records remain on storage for the full audit window.
delta.logRetentionDuration controls how long the transaction log is retained. Time-travel queries (SELECT ...
VERSION AS OF or TIMESTAMP AS OF) rely on the log to reconstruct historical table states - without 30 days of log, you can't query 30-day-old snapshots even if the data files are still there.
Both properties need to be set to 30 days to fully honour the requirement. Option A (delta.timeUntilArchived) doesn't exist in Delta Lake. Option C (autoCompact) manages file sizing, not retention. Option E (enableDeletionVectors) speeds up deletes but has no bearing on how long data is kept.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/history#configure-data-retention
NEW QUESTION # 42
You have an Apache Spark DataFrame named salesDF that contains the following columns:
* Product
* Region
* Sales
* Date
You need to create a pivot table that shows the total sales by product for each region.
How should you complete the PySpark code segment? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.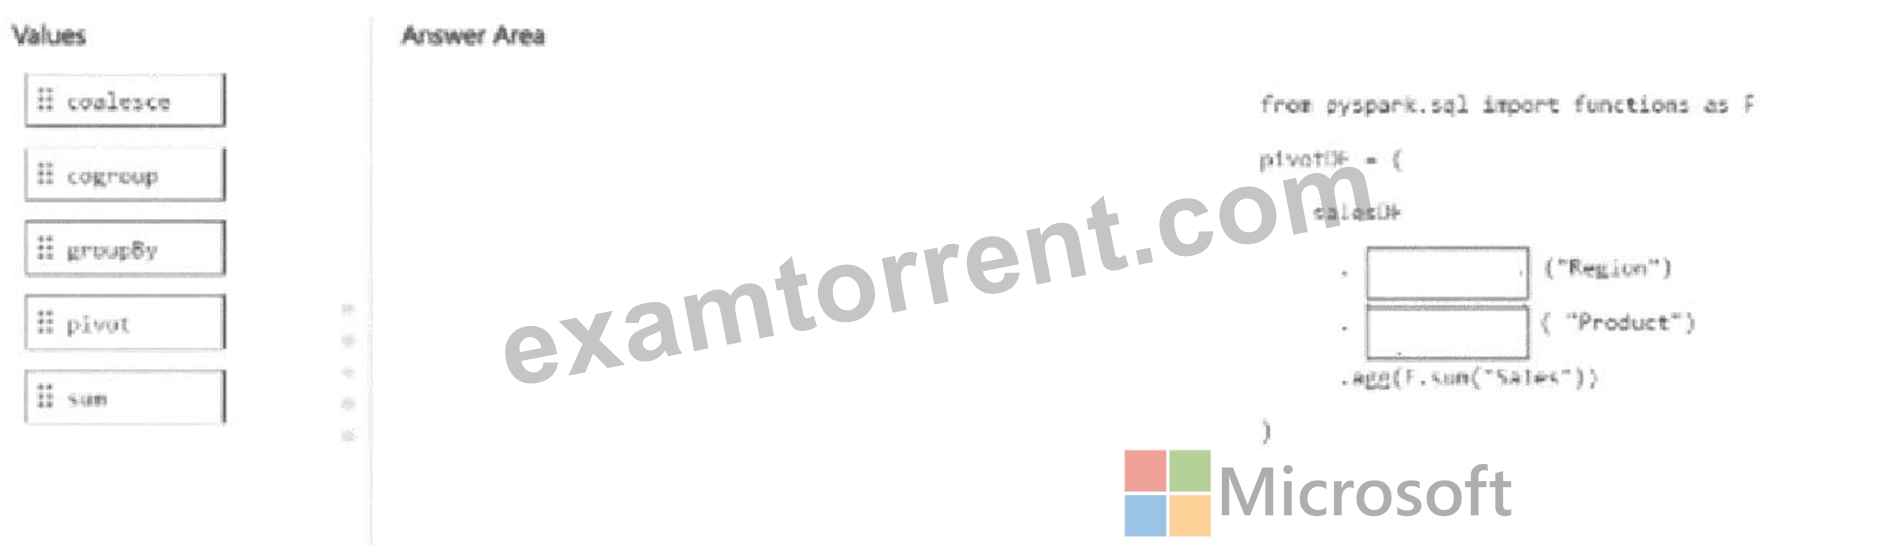
Answer:
Explanation: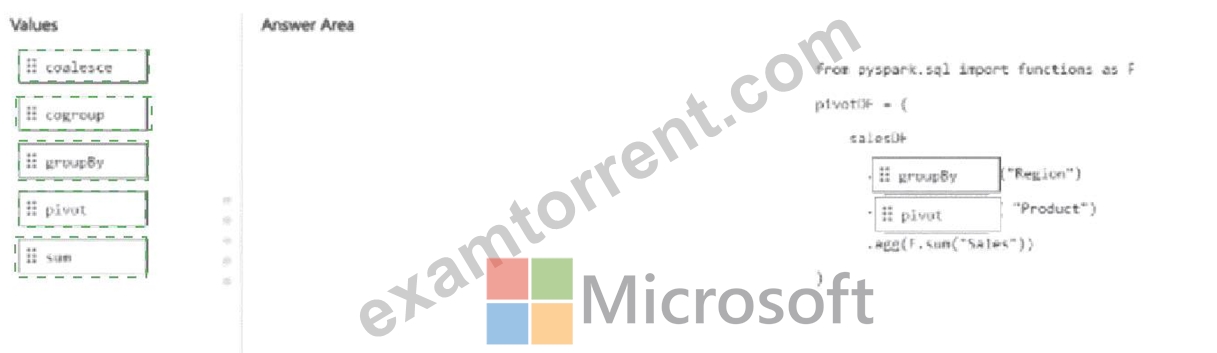
Explanation:
* groupBy
* pivot
The groupBy( " Region " ) operation establishes one aggregation group for each geographical region in the DataFrame. The subsequent pivot( " Product " ) operation converts every distinct Product value into a separate output column. Finally, agg(F.sum( " Sales " )) calculates the total sales for every product within each region. The resulting DataFrame contains one row per region and one column for each product, with the corresponding aggregated sales value. cogroup combines grouped datasets and is not used for creating a conventional pivot table. coalesce controls the number of DataFrame partitions or replaces null values, depending on its context. The sum function is already provided inside the aggregation expression and therefore is not required in either blank.
NEW QUESTION # 43
......
As we all know, it is difficult to prepare the DP-750 exam by ourselves. Excellent guidance is indispensable. If you urgently need help, come to buy our study materials. Our company has been regarded as the most excellent online retailers of the DP-750 exam question. So our assistance is the most professional and superior. You can totally rely on our study materials to pass the exam. In addition, all installed DP-750 study tool can be used normally. In a sense, our DP-750 Real Exam dumps equal a mobile learning device. We are not just thinking about making money. Your convenience and demands also deserve our deep consideration. At the same time, your property rights never expire once you have paid for money. So the DP-750 study tool can be reused after you have got the DP-750 certificate. You can donate it to your classmates or friends. They will thank you so much.
New DP-750 Exam Guide: https://www.examtorrent.com/DP-750-valid-vce-dumps.html